Testking Certified-Data-Engineer-Professional Exam Questions - Certified-Data-Engineer-Professional Test Engine Version

P.S. Free 2026 Databricks Certified-Data-Engineer-Professional dumps are available on Google Drive shared by SureTorrent: https://drive.google.com/open?id=1M3C0bD0a_mo3L4mWA8O_cbLrnSysZwBr
Three versions for Certified-Data-Engineer-Professional exam cram are available. Certified-Data-Engineer-Professional PDF version is printable and you can learn them anytime. Certified-Data-Engineer-Professional Online test engine is convenient and easy to learn, and supports all web browsers and if you want to practice offline, you can also realize by this. In addition, Certified-Data-Engineer-Professional Online soft test engine have testing history and performance review, you can have a general review of what you have learned before start practicing. We offer you free update for one year for Certified-Data-Engineer-Professional training materials, and the update version will be sent to your email automatically.
| Section | Objectives |
|---|
| Ensuring Data Security and Compliance | - Data Security
- 1. Use row filters and column masks for sensitive data
- 2. Apply anonymization and pseudonymization techniques
- 3. Use ACLs to secure workspace objects and enforce least privilege
- Compliance
- 1. Develop data purging solutions according to data retention policies
- 2. Implement pipelines that detect and mask personally identifiable information
|
| Data Sharing and Federation | - Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
- Delta Sharing
- 1. Share live Lakehouse data with external computing platforms
- 2. Configure Databricks-to-Databricks Sharing
- 3. Configure sharing with external platforms using the open sharing protocol
|
| Monitoring and Alerting | - Monitoring
- 1. Use system tables for resource, cost, audit, and workload monitoring
- 2. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 3. Use Query Profiler and Spark UI to monitor workloads
- 4. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- Alerting
- 1. Configure Lakeflow Jobs notifications for job status and performance issues
- 2. Use SQL Alerts for data quality monitoring
|
| Data Governance | - Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
- Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
|
| Data Transformation, Cleansing, and Quality | - Advanced Data Transformation
- 1. Apply window functions, joins, and aggregations to large datasets
- 2. Write efficient Spark SQL and PySpark transformations
- Data Quality
- 1. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- 2. Develop data quarantining processes for invalid data
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
- 2. Ingest data from message buses and cloud storage
- 3. Build append-only pipelines for batch and streaming data using Delta
|
| Data Modelling | - Dimensional Modelling
- 1. Design dimensional models for analytical workloads
- Scalable Data Models
- 1. Understand Liquid Clustering versus partitioning and Z-Ordering
- 2. Design and implement scalable data models using Delta Lake
- 3. Optimize data layout using Liquid Clustering
|
| Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- 2. Manage and troubleshoot third-party library installations and dependencies
- 3. Develop User-Defined Functions using Pandas/Python UDFs
- Building and Testing ETL Pipelines
- 1. Use APPLY CHANGES APIs for change data capture
- 2. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 3. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 4. Use control flow operators in pipeline components
- 5. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 6. Compare streaming tables and materialized views
- 7. Develop unit and integration tests for data processing code
- 8. Configure environments, dependencies, memory, and retry behavior
|
| Cost & Performance Optimisation | - Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
- Query Performance
- 1. Identify inefficient joins and excessive data shuffling
- 2. Use Query Profile to identify performance bottlenecks
- Delta Optimization
- 1. Use Change Data Feed to address streaming table limitations and improve latency
- 2. Apply data skipping and file pruning techniques
- 3. Understand deletion vectors and liquid clustering
|
| Debugging and Deploying | - Debugging and Troubleshooting
- 1. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 2. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- 3. Analyze errors and remediate failed job runs
- Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Integrate Git-based CI/CD workflows using Databricks Git Folders
|
>> Testking Certified-Data-Engineer-Professional Exam Questions <<
Perfect Testking Certified-Data-Engineer-Professional Exam Questions Help You to Get Acquainted with Real Certified-Data-Engineer-Professional Exam Simulation
You should prepare with SureTorrent Certified-Data-Engineer-Professional Questions that are in compliance with Certified-Data-Engineer-Professional exam content. More than 90,000 professionals worldwide have provided their feedback, helping create and launch Certified-Data-Engineer-Professional questions in the market. So, if you're determined to pass the Databricks exam and achieve Certified-Data-Engineer-Professional Certification to accelerate your career, it's time to build your knowledge and skills. You can try the demo version of Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) practice dumps before payment.
Databricks Certified Data Engineer Professional Sample Questions (Q240-Q245):
NEW QUESTION # 240
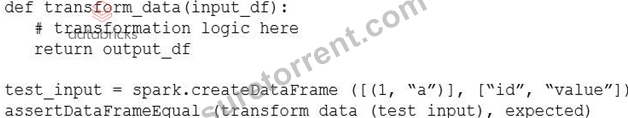
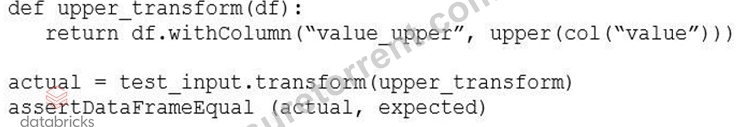
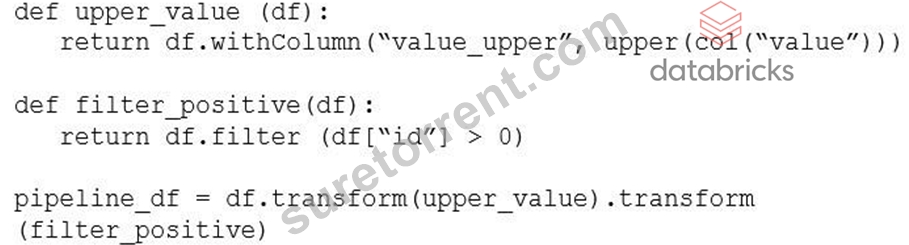
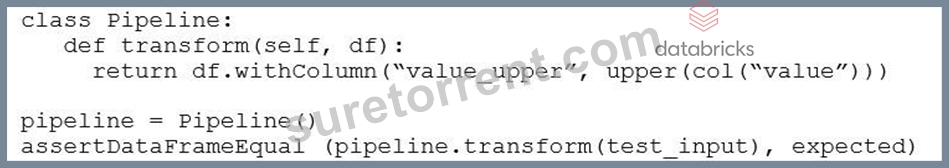
Which approach demonstrates a modular and testable way to use DataFrame transform for ETL code in PySpark?
Answer: B
Explanation:
Using DataFrame.transform with a pure transformation function promotes modular, reusable, and easily testable ETL logic. Each transformation is encapsulated as a standalone function, can be independently unit tested, and composed cleanly in a pipeline without coupling to orchestration or class state.
NEW QUESTION # 241
Spill occurs as a result of executing various wide transformations. However, diagnosing spill requires one to proactively look for key indicators.
Where in the Spark UI are two of the primary indicators that a partition is spilling to disk?
- A. Driver's and Executor's log files
- B. Stage's detail screen and Query's detail screen
- C. Executor's detail screen and Executor's log files
- D. Query's detail screen and Job's detail screen
- E. Stage's detail screen and Executor's log files
Answer: E
Explanation:
In the Spark UI, the Stage's detail screen provides key metrics about each stage of a job, including the amount of data that has been spilled to disk. If you see a high number in the "Spill (Memory)" or "Spill (Disk)" columns, it's an indication that a partition is spilling to disk.
The Executor's log files can also provide valuable information about spill. If a task is spilling a lot of data, you'll see messages in the logs like "Spilling UnsafeExternalSorter to disk" or "Task memory spill". These messages indicate that the task ran out of memory and had to spill data to disk.
NEW QUESTION # 242
A data engineer is tasked with building a nightly batch ETL pipeline that processes very large volumes of raw JSON logs from a data lake into Delta tables for reporting. The data arrives in bulk once per day, and the pipeline takes several hours to complete. Cost efficiency is important, but performance and reliability of completing the pipeline are the highest priorities. Which type of Databricks cluster should the data engineer configure?
- A. A lightweight single-node cluster with low worker node count to reduce costs.
- B. A high-concurrency cluster designed for interactive SQL workloads.
- C. An all-purpose cluster always kept running to ensure low-latency job startup times.
- D. A job cluster configured to autoscale across multiple workers during the pipeline run.
Answer: D
Explanation:
Job clusters are optimized for automated production workloads. They start when a job is triggered and terminate automatically once the task completes. This ensures cost control while maintaining performance and reliability for batch ETL. Autoscaling allows Databricks to add or remove workers dynamically based on workload size, ensuring large data volumes are processed efficiently.
All-purpose clusters are intended for development or ad-hoc workloads, not scheduled ETL.
NEW QUESTION # 243
A Delta Lake table was created with the below query:

Consider the following query:
DROP TABLE prod.sales_by_store
If this statement is executed by a workspace admin, which result will occur?
- A. The table will be removed from the catalog but the data will remain in storage.
- B. Nothing will occur until a COMMIT command is executed.
- C. The table will be removed from the catalog and the data will be deleted.
- D. Data will be marked as deleted but still recoverable with Time Travel.
- E. An error will occur because Delta Lake prevents the deletion of production data.
Answer: C
Explanation:
When a table is dropped in Delta Lake, the table is removed from the catalog and the data is deleted. This is because Delta Lake is a transactional storage layer that provides ACID guarantees. When a table is dropped, the transaction log is updated to reflect the deletion of the table and the data is deleted from the underlying storage.
NEW QUESTION # 244
The data engineering team maintains the following code:

Assuming that this code produces logically correct results and the data in the source tables has been de-duplicated and validated, which statement describes what will occur when this code is executed?
- A. An incremental job will leverage information in the state store to identify unjoined rows in the source tables and write these rows to the enriched_iteinized_orders_by_account table.
- B. A batch job will update the enriched_itemized_orders_by_account table, replacing only those rows that have different values than the current version of the table, using accountID as the primary key.
- C. An incremental job will detect if new rows have been written to any of the source tables; if new rows are detected, all results will be recalculated and used to overwrite the enriched_itemized_orders_by_account table.
- D. The enriched_itemized_orders_by_account table will be overwritten using the current valid version of data in each of the three tables referenced in the join logic.
- E. No computation will occur until enriched_itemized_orders_by_account is queried; upon query materialization, results will be calculated using the current valid version of data in each of the three tables referenced in the join logic.
Answer: D
Explanation:
This is the correct answer because it describes what will occur when this code is executed. The code uses three Delta Lake tables as input sources: accounts, orders, and order_items. These tables are joined together using SQL queries to create a view called new_enriched_itemized_orders_by_account, which contains information about each order item and its associated account details. Then, the code uses write.format("delta").mode("overwrite") to overwrite a target table called enriched_itemized_orders_by_account using the data from the view. This means that every time this code is executed, it will replace all existing data in the target table with new data based on the current valid version of data in each of the three input tables.
NEW QUESTION # 245
......
Our research materials will provide three different versions, the PDF version, the software version and the online version. Software version of the features are very practical, in order to meet the needs of some potential customers, we provide users with free experience, if you also choose the characteristics of practical, I think you can try to use our Certified-Data-Engineer-Professional test prep software version. I believe you have a different sensory experience for this version of the product. Because the software version of the product can simulate the real test environment, users can realize the effect of the atmosphere of the Certified-Data-Engineer-Professional Exam at home through the software version. Although this version can only run on the Windows operating system, our software version of the learning material is not limited to the number of computers installed and the number of users, the user can implement the software version on several computers. You will like the software version. Of course, you can also choose other learning mode of the Certified-Data-Engineer-Professional valid practice questions.
Certified-Data-Engineer-Professional Test Engine Version: https://www.suretorrent.com/Certified-Data-Engineer-Professional-exam-guide-torrent.html
- Pass Guaranteed 2026 Databricks Certified-Data-Engineer-Professional: Unparalleled Testking Databricks Certified Data Engineer Professional Exam Questions 👏 Easily obtain free download of ▶ Certified-Data-Engineer-Professional ◀ by searching on ➥ www.torrentvce.com 🡄 🥚New Certified-Data-Engineer-Professional Dumps Pdf
- Free PDF Quiz 2026 Certified-Data-Engineer-Professional: Perfect Testking Databricks Certified Data Engineer Professional Exam Questions 🥎 Easily obtain free download of ➡ Certified-Data-Engineer-Professional ️⬅️ by searching on ➽ www.pdfvce.com 🢪 👋Reliable Certified-Data-Engineer-Professional Dumps Book
- Pass Guaranteed 2026 Databricks Certified-Data-Engineer-Professional: Unparalleled Testking Databricks Certified Data Engineer Professional Exam Questions 👠 Simply search for ▶ Certified-Data-Engineer-Professional ◀ for free download on ▛ www.troytecdumps.com ▟ 👐Reliable Certified-Data-Engineer-Professional Dumps Book
- Free PDF Quiz 2026 Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Pass-Sure Testking Exam Questions 🦒 Copy URL ➠ www.pdfvce.com 🠰 open and search for [ Certified-Data-Engineer-Professional ] to download for free 🍁Certified-Data-Engineer-Professional New Exam Materials
- Free PDF Quiz 2026 Certified-Data-Engineer-Professional: Perfect Testking Databricks Certified Data Engineer Professional Exam Questions 📭 Copy URL ➡ www.practicevce.com ️⬅️ open and search for 【 Certified-Data-Engineer-Professional 】 to download for free 🔱Certified-Data-Engineer-Professional Test Score Report
- Pass Guaranteed 2026 Databricks Certified-Data-Engineer-Professional Updated Testking Exam Questions 🐴 Easily obtain free download of ✔ Certified-Data-Engineer-Professional ️✔️ by searching on ( www.pdfvce.com ) ➡️Certified-Data-Engineer-Professional Latest Test Simulator
- Pass Guaranteed 2026 Databricks Certified-Data-Engineer-Professional: Unparalleled Testking Databricks Certified Data Engineer Professional Exam Questions 🛴 Search for { Certified-Data-Engineer-Professional } and download it for free immediately on “ www.dumpsquestion.com ” ◀New Certified-Data-Engineer-Professional Dumps Pdf
- Pass Guaranteed 2026 Databricks Certified-Data-Engineer-Professional Updated Testking Exam Questions 🐌 Easily obtain free download of ✔ Certified-Data-Engineer-Professional ️✔️ by searching on ☀ www.pdfvce.com ️☀️ 🧖Certified-Data-Engineer-Professional Test Registration
- Pass Guaranteed Quiz 2026 Accurate Databricks Testking Certified-Data-Engineer-Professional Exam Questions 🦇 Open ➡ www.dumpsquestion.com ️⬅️ and search for 《 Certified-Data-Engineer-Professional 》 to download exam materials for free 🗺Certified-Data-Engineer-Professional Latest Braindumps Sheet
- Certified-Data-Engineer-Professional New Exam Materials 🌌 Certified-Data-Engineer-Professional Exam Engine 🌋 Certified-Data-Engineer-Professional Latest Braindumps Sheet 🧄 Search for ➠ Certified-Data-Engineer-Professional 🠰 and download it for free immediately on [ www.pdfvce.com ] 🦖Certified-Data-Engineer-Professional Exam Dumps Provider
- Testking Certified-Data-Engineer-Professional Exam Questions Free PDF | High Pass-Rate Certified-Data-Engineer-Professional Test Engine Version: Databricks Certified Data Engineer Professional 💝 Easily obtain free download of ▛ Certified-Data-Engineer-Professional ▟ by searching on ( www.troytecdumps.com ) 🎐Certified-Data-Engineer-Professional Exam Dumps Free
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, writeablog.net, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
DOWNLOAD the newest SureTorrent Certified-Data-Engineer-Professional PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1M3C0bD0a_mo3L4mWA8O_cbLrnSysZwBr