100%합격보장가능한Certified-Data-Engineer-Professional최신인증시험정보인증시험덤프

ITDumpsKR사이트에서 제공해드리는 Databricks Certified-Data-Engineer-Professional덤프는 실러버스의 갱신에 따라 업데이트되기에 고객님께서 구매한Databricks Certified-Data-Engineer-Professional덤프가 시중에서 가장 최신버전임을 장담해드립니다. Databricks Certified-Data-Engineer-Professional덤프의 문제와 답을 모두 기억하시면Databricks Certified-Data-Engineer-Professional시험에서 한방에 패스할수 있습니다.시험에서 불합격 받으시면 결제를 취소해드립니다.
Databricks Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Objectives |
|---|
| Topic 1: Data Transformation, Cleansing, and Quality | - Advanced Data Transformation
- 1. Apply window functions, joins, and aggregations to large datasets
- 2. Write efficient Spark SQL and PySpark transformations
- Data Quality
- 1. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- 2. Develop data quarantining processes for invalid data
|
| Topic 2: Data Governance | - Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
- Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
|
| Topic 3: Data Sharing and Federation | - Delta Sharing
- 1. Share live Lakehouse data with external computing platforms
- 2. Configure sharing with external platforms using the open sharing protocol
- 3. Configure Databricks-to-Databricks Sharing
- Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
|
| Topic 4: Ensuring Data Security and Compliance | - Compliance
- 1. Implement pipelines that detect and mask personally identifiable information
- 2. Develop data purging solutions according to data retention policies
- Data Security
- 1. Use row filters and column masks for sensitive data
- 2. Use ACLs to secure workspace objects and enforce least privilege
- 3. Apply anonymization and pseudonymization techniques
|
| Topic 5: Monitoring and Alerting | - Monitoring
- 1. Use Query Profiler and Spark UI to monitor workloads
- 2. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 3. Use system tables for resource, cost, audit, and workload monitoring
- 4. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- Alerting
- 1. Use SQL Alerts for data quality monitoring
- 2. Configure Lakeflow Jobs notifications for job status and performance issues
|
| Topic 6: Data Modelling | - Scalable Data Models
- 1. Design and implement scalable data models using Delta Lake
- 2. Optimize data layout using Liquid Clustering
- 3. Understand Liquid Clustering versus partitioning and Z-Ordering
- Dimensional Modelling
- 1. Design dimensional models for analytical workloads
|
| Topic 7: Developing Code for Data Processing using Python and SQL | - Building and Testing ETL Pipelines
- 1. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 2. Use control flow operators in pipeline components
- 3. Develop unit and integration tests for data processing code
- 4. Configure environments, dependencies, memory, and retry behavior
- 5. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 6. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 7. Compare streaming tables and materialized views
- 8. Use APPLY CHANGES APIs for change data capture
- Using Python and Tools for Development
- 1. Manage and troubleshoot third-party library installations and dependencies
- 2. Develop User-Defined Functions using Pandas/Python UDFs
- 3. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
|
| Topic 8: Debugging and Deploying | - Deploying CI/CD
- 1. Integrate Git-based CI/CD workflows using Databricks Git Folders
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
- Debugging and Troubleshooting
- 1. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- 2. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 3. Analyze errors and remediate failed job runs
|
| Topic 9: Cost & Performance Optimisation | - Query Performance
- 1. Identify inefficient joins and excessive data shuffling
- 2. Use Query Profile to identify performance bottlenecks
- Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
- Delta Optimization
- 1. Apply data skipping and file pruning techniques
- 2. Use Change Data Feed to address streaming table limitations and improve latency
- 3. Understand deletion vectors and liquid clustering
|
| Topic 10: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
- 2. Ingest data from message buses and cloud storage
- 3. Build append-only pipelines for batch and streaming data using Delta
|
>> Certified-Data-Engineer-Professional최신 인증시험정보 <<
Certified-Data-Engineer-Professional인기자격증 최신시험 덤프자료 & Certified-Data-Engineer-Professional최고패스자료
ITDumpsKR 에서 출시한Databricks인증Certified-Data-Engineer-Professional 덤프는Databricks인증Certified-Data-Engineer-Professional 실제시험의 출제범위와 출제유형을 대비하여 제작된 최신버전 덤프입니다. 시험문제가 바뀌면 제일 빠른 시일내에 덤프를 업데이트 하도록 최선을 다하고 있으며 1년 무료 업데이트서비스를 제공해드립니다. 1년 무료 업데이트서비스를 제공해드리기에 시험시간을 늦추어도 시험성적에 아무런 페를 끼치지 않습니다. ITDumpsKR에 믿음을 느낄수 있도록 구매사이트마다 무료샘플 다운가능기능을 설치하였습니다.무료샘플을 체험해보시고ITDumpsKR을 선택해주세요.
최신 Databricks Certification Certified-Data-Engineer-Professional 무료샘플문제 (Q229-Q234):
질문 # 229
The data engineering team maintains the following code:
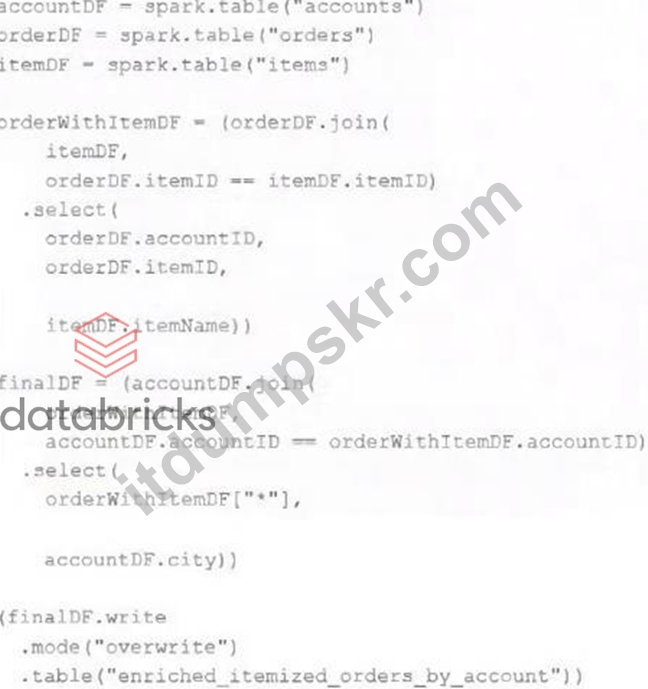
Assuming that this code produces logically correct results and the data in the source tables has been de-duplicated and validated, which statement describes what will occur when this code is executed?
- A. The enriched_itemized_orders_by_account table will be overwritten using the current valid version of data in each of the three tables referenced in the join logic.
- B. A batch job will update the enriched_itemized_orders_by_account table, replacing only those rows that have different values than the current version of the table, using accountID as the primary key.
- C. No computation will occur until enriched_itemized_orders_by_account is queried; upon query materialization, results will be calculated using the current valid version of data in each of the three tables referenced in the join logic.
- D. An incremental job will leverage information in the state store to identify unjoined rows in the source tables and write these rows to the enriched_iteinized_orders_by_account table.
- E. An incremental job will detect if new rows have been written to any of the source tables; if new rows are detected, all results will be recalculated and used to overwrite the enriched_itemized_orders_by_account table.
정답:A
설명:
This is the correct answer because it describes what will occur when this code is executed. The code uses three Delta Lake tables as input sources: accounts, orders, and order_items. These tables are joined together using SQL queries to create a view called new_enriched_itemized_orders_by_account, which contains information about each order item and its associated account details. Then, the code uses write.format("delta").mode("overwrite") to overwrite a target table called enriched_itemized_orders_by_account using the data from the view. This means that every time this code is executed, it will replace all existing data in the target table with new data based on the current valid version of data in each of the three input tables.
질문 # 230
A security team wants to enforce data protection for a customer table containing customer PII data. To comply with local policies, sales team members should only see customers from their region, while non-admin users should have email addresses masked. Which implementation approach should be used when using Unity Catalog row filters and column masks?
- A. Create a view with dynamic WHERE clauses for region filtering and use string replacement functions for email masking using ALTER COLUMN SET MASK command.
- B. Create SQL UDFs for row filtering based on user region and column masking based on group membership, then apply them using ALTER TABLE SET ROW FILTER and ALTER COLUMN SET MASK commands.
- C. Implement row filters with SQL UDFs based on user region only since column masks cannot be combined with row filters on the same table, then apply them be recreating the table with DROP TABLE and CREATE TABLE SET ROW FILTER commands.
- D. Use table ACLs to restrict access using tags with GRANT SELECT ON table_name WITH TAG command, and rely on application-level filtering for sensitive data based on user region.
정답:B
설명:
Unity Catalog enforces fine-grained access control by applying SQL UDF-based row filters and column masks directly at the table level. Row filter UDFs can restrict visible rows based on the user's region, while column mask UDFs can dynamically mask sensitive fields like email addresses for non-admin users. Applying them with ALTER TABLE SET ROW FILTER and ALTER COLUMN SET MASK ensures centralized, consistent enforcement of data protection policies across all access paths.
질문 # 231
A junior data engineer has manually configured a series of jobs using the Databricks Jobs UI.
Upon reviewing their work, the engineer realizes that they are listed as the "Owner" for each job.
They attempt to transfer "Owner" privileges to the "DevOps" group, but cannot successfully accomplish this task.
Which statement explains what is preventing this privilege transfer?
- A. Only workspace administrators can grant "Owner" privileges to a group.
- B. Other than the default "admins" group, only individual users can be granted privileges on jobs.
- C. The creator of a Databricks job will always have "Owner" privileges; this configuration cannot be changed.
- D. A user can only transfer job ownership to a group if they are also a member of that group.
- E. Databricks jobs must have exactly one owner; "Owner" privileges cannot be assigned to a group.
정답:E
설명:
A job cannot have more than one owner. A job cannot have a group as an owner.
질문 # 232
A data engineer deploys a multi-task Databricks job that orchestrates three notebooks. One task intermittently fails with Exit Code 1 but succeeds on retry. The engineer needs to collect detailed logs for the failing attempts, including stdout/stderr and cluster lifecycle context, and share them with the platform team. What steps the data engineer needs to follow using built-in tools?
- A. Download worker logs directly from the Spark UI and ignore driver logs, as worker logs contain stdout/stderr for all tasks and cluster events.
- B. Export the notebook run results to HTML; this bundle includes complete stdout, stderr, and cluster event history across all tasks.
- C. Use the notebook interactive debugger to re-run the entire multi-task job, and capture step- through traces for the failing task.
- D. From the job run details page, export the job's logs or configure log delivery; then retrieve the compute driver logs and event logs from the compute details page to correlate stdout/stderr with cluster events.
정답:D
설명:
The recommended way to troubleshoot and collect detailed job logs is through the Job Run Details page in Databricks. From there, engineers can export run logs or configure automatic log delivery to a storage destination. The driver and event logs available under compute details provide stdout, stderr, and cluster lifecycle context required for root-cause analysis.
질문 # 233
A data engineer is tasked with building a nightly batch ETL pipeline that processes very large volumes of raw JSON logs from a data lake into Delta tables for reporting. The data arrives in bulk once per day, and the pipeline takes several hours to complete. Cost efficiency is important, but performance and reliability of completing the pipeline are the highest priorities. Which type of Databricks cluster should the data engineer configure?
- A. A job cluster configured to autoscale across multiple workers during the pipeline run.
- B. A high-concurrency cluster designed for interactive SQL workloads.
- C. An all-purpose cluster always kept running to ensure low-latency job startup times.
- D. A lightweight single-node cluster with low worker node count to reduce costs.
정답:A
설명:
Job clusters are optimized for automated production workloads. They start when a job is triggered and terminate automatically once the task completes. This ensures cost control while maintaining performance and reliability for batch ETL. Autoscaling allows Databricks to add or remove workers dynamically based on workload size, ensuring large data volumes are processed efficiently.
All-purpose clusters are intended for development or ad-hoc workloads, not scheduled ETL.
질문 # 234
......
ITDumpsKR는 모든 IT관련 인증시험자료를 제공할 수 있는 사이트입니다. 우리ITDumpsKR는 여러분들한테 최고 최신의 자료를 제공합니다. ITDumpsKR을 선택함으로 여러분은 이미Databricks Certified-Data-Engineer-Professional시험을 패스하였습니다. 우리 자료로 여러분은 충분히Databricks Certified-Data-Engineer-Professional를 패스할 수 있습니다. 만약 시험에서 떨어지셨다면 우리는 백프로 환불은 약속합니다. 그리고 갱신이 된 최신자료를 보내드립니다. 하지만 이런사례는 거이 없었습니다.모두 한번에 패스하였기 때문이죠. ITDumpsKR는 여러분이Databricks Certified-Data-Engineer-Professional인증시험 패스와 추후사업에 모두 도움이 되겠습니다. Pass4Tes의 선택이야말로 여러분의 현명한 선택이라고 볼수 있습니다. Pass4Tes선택으로 여러분은 시간도 절약하고 돈도 절약하는 일석이조의 득을 얻을수 있습니다. 또한 구매후 일년무료 업데이트버전을 바을수 있는 기회를 얻을수 있습니다.
Certified-Data-Engineer-Professional인기자격증 최신시험 덤프자료: https://www.itdumpskr.com/Certified-Data-Engineer-Professional-exam.html
- Certified-Data-Engineer-Professional최신 인증시험정보 덤프로 Databricks Certified Data Engineer Professional시험 패스 🏓 ⇛ www.koreadumps.com ⇚에서 검색만 하면( Certified-Data-Engineer-Professional )를 무료로 다운로드할 수 있습니다Certified-Data-Engineer-Professional인증덤프데모문제
- Certified-Data-Engineer-Professional인증덤프데모문제 ☀ Certified-Data-Engineer-Professional인증덤프데모문제 ⛹ Certified-Data-Engineer-Professional높은 통과율 시험덤프자료 🕧 무료 다운로드를 위해 지금【 www.itdumpskr.com 】에서▶ Certified-Data-Engineer-Professional ◀검색Certified-Data-Engineer-Professional퍼펙트 덤프 최신문제
- 최신 Certified-Data-Engineer-Professional최신 인증시험정보 시험대비자료 🚣 ⏩ kr.fast2test.com ⏪웹사이트를 열고➤ Certified-Data-Engineer-Professional ⮘를 검색하여 무료 다운로드Certified-Data-Engineer-Professional시험패스 덤프공부자료
- 최신버전 Certified-Data-Engineer-Professional최신 인증시험정보 완벽한 시험 최신버전 덤프자료 다운 🐹 ➠ Certified-Data-Engineer-Professional 🠰를 무료로 다운로드하려면▛ www.itdumpskr.com ▟웹사이트를 입력하세요Certified-Data-Engineer-Professional유효한 인증덤프
- Certified-Data-Engineer-Professional시험패스 가능한 인증덤프 🧥 Certified-Data-Engineer-Professional최신 업데이트 덤프 🚠 Certified-Data-Engineer-Professional시험기출문제 🕯 지금⇛ www.dumptop.com ⇚을(를) 열고 무료 다운로드를 위해“ Certified-Data-Engineer-Professional ”를 검색하십시오Certified-Data-Engineer-Professional퍼펙트 덤프데모문제
- Certified-Data-Engineer-Professional최신 인증시험정보 덤프는 Databricks Certified Data Engineer Professional 100% 시험패스 보장 🍩 무료로 다운로드하려면⏩ www.itdumpskr.com ⏪로 이동하여《 Certified-Data-Engineer-Professional 》를 검색하십시오Certified-Data-Engineer-Professional유효한 시험자료
- 최신버전 Certified-Data-Engineer-Professional최신 인증시험정보 완벽한 시험 최신버전 덤프자료 다운 🚂 오픈 웹 사이트“ www.koreadumps.com ”검색{ Certified-Data-Engineer-Professional }무료 다운로드Certified-Data-Engineer-Professional시험패스 가능한 인증덤프
- Certified-Data-Engineer-Professional퍼펙트 덤프데모문제 🐏 Certified-Data-Engineer-Professional시험대비 덤프 최신 데모 📺 Certified-Data-Engineer-Professional인증덤프데모문제 🚕 ▛ www.itdumpskr.com ▟웹사이트를 열고“ Certified-Data-Engineer-Professional ”를 검색하여 무료 다운로드Certified-Data-Engineer-Professional인증덤프데모문제
- Certified-Data-Engineer-Professional최신 인증시험정보 덤프는 Databricks Certified Data Engineer Professional 100% 시험패스 보장 👧 ✔ www.pass4test.net ️✔️에서▛ Certified-Data-Engineer-Professional ▟를 검색하고 무료로 다운로드하세요Certified-Data-Engineer-Professional퍼펙트 덤프 최신문제
- Certified-Data-Engineer-Professional유효한 시험자료 🚴 Certified-Data-Engineer-Professional시험패스 가능한 공부 🐅 Certified-Data-Engineer-Professional시험기출문제 🔸 ➡ www.itdumpskr.com ️⬅️을 통해 쉽게➥ Certified-Data-Engineer-Professional 🡄무료 다운로드 받기Certified-Data-Engineer-Professional유효한 시험자료
- Certified-Data-Engineer-Professional최신 인증시험정보 덤프샘플문제 🐋 ➡ www.pass4test.net ️⬅️의 무료 다운로드《 Certified-Data-Engineer-Professional 》페이지가 지금 열립니다Certified-Data-Engineer-Professional인증시험
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes