BONUS!!! Download part of PassReview DP-100 dumps for free: https://drive.google.com/open?id=1uoEVOXbxILXA23fieG_AhhHFqL0JYE0w
Three versions for DP-100 training materials are available, and you can choose the most suitable one according to your own needs. DP-100 PDF version is printable, and you can print them into hard one and take them with you, you can also study anywhere and anyplace. DP-100 Soft test engine can install in more than 200 computers, and it has two modes for practice. DP-100 Soft test engine can also simulate the real exam environment, so that your confidence for the exam will be strengthened. DP-100 Online test engine is convenient and easy to learn. You can have a review of what you have learned through this version.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Deploy and retrain models | 10-15% | - Implement retraining pipelines
|
| Topic 2: Prepare a model for deployment | 20-25% | - Manage deployment assets
|
| Topic 3: Explore data and train models | 35-40% | - Prepare data for modeling
|
| Topic 4: Design and prepare a machine learning solution | 20-25% | - Design an Azure Machine Learning workspace
|
>> Reliable DP-100 Test Answers <<
As far as our DP-100 study guide is concerned, the PDF version brings you much convenience with regard to the following advantage. The PDF version of our DP-100 learning materials contain demo where a part of questions selected from the entire version of our DP-100 Exam Quiz is contained. In this way, you have a general understanding of our DP-100 actual prep exam, which must be beneficial for your choice of your suitable exam files.
NEW QUESTION # 84
You run a script as an experiment in Azure Machine Learning.
You have a Run object named run that references the experiment run. You must review the log files that were generated during the experiment run.
You need to download the log files to a local folder for review.
Which two code segments can you run to achieve this goal? Each correct answer presents a complete solution.
NOTE: Each correct selection is worth one point.
Answer: A,C
NEW QUESTION # 85
You use Azure Machine Learning Designer to load the following datasets into an experiment:
Data set 1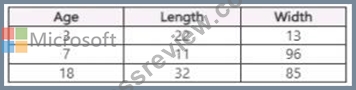
Dataset 2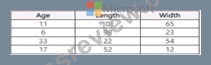
You need to create a dataset that has the same columns and header row as the input datasets and contains all rows from both input datasets.
Solution: Use the Apply Transformation component.
Does the solution meet the goal?
Answer: A
NEW QUESTION # 86
You use Azure Machine Learning Studio to build a machine learning experiment.
You need to divide data into two distinct datasets.
Which module should you use?
Answer: A
Explanation:
The Group Data into Bins module supports multiple options for binning data. You can customize how the bin edges are set and how values are apportioned into the bins.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/group-data-into-bins Perform Feature Engineering Testlet 1 Case study Overview You are a data scientist in a company that provides data science for professional sporting events. Models will use global and local market data to meet the following business goals:
* Understand sentiment of mobile device users at sporting events based on audio from crowd reactions.
* Assess a user's tendency to respond to an advertisement.
* Customize styles of ads served on mobile devices.
* Use video to detect penalty events
Current environment
* Media used for penalty event detection will be provided by consumer devices. Media may include images and videos captured during the sporting event and shared using social media. The images and videos will have varying sizes and formats.
* The data available for model building comprises of seven years of sporting event media. The sporting event media includes; recorded video transcripts or radio commentary, and logs from related social media feeds captured during the sporting events.
* Crowd sentiment will include audio recordings submitted by event attendees in both mono and stereo formats.
Penalty detection and sentiment
* Data scientists must build an intelligent solution by using multiple machine learning models for penalty event detection.
* Data scientists must build notebooks in a local environment using automatic feature engineering and model building in machine learning pipelines.
* Notebooks must be deployed to retrain by using Spark instances with dynamic worker allocation.
* Notebooks must execute with the same code on new Spark instances to recode only the source of the data.
* Global penalty detection models must be trained by using dynamic runtime graph computation during training.
* Local penalty detection models must be written by using BrainScript.
* Experiments for local crowd sentiment models must combine local penalty detection data.
* Crowd sentiment models must identify known sounds such as cheers and known catch phrases. Individual crowd sentiment models will detect similar sounds.
* All shared features for local models are continuous variables.
* Shared features must use double precision. Subsequent layers must have aggregate running mean and standard deviation metrics available.
Advertisements
During the initial weeks in production, the following was observed:
* Ad response rated declined.
* Drops were not consistent across ad styles.
* The distribution of features across training and production data are not consistent Analysis shows that, of the 100 numeric features on user location and behavior, the 47 features that come from location sources are being used as raw features. A suggested experiment to remedy the bias and variance issue is to engineer 10 linearly uncorrelated features.
* Initial data discovery shows a wide range of densities of target states in training data used for crowd sentiment models.
* All penalty detection models show inference phases using a Stochastic Gradient Descent (SGD) are running too slow.
* Audio samples show that the length of a catch phrase varies between 25%-47% depending on region
* The performance of the global penalty detection models shows lower variance but higher bias when comparing training and validation sets. Before implementing any feature changes, you must confirm the bias and variance using all training and validation cases.
* Ad response models must be trained at the beginning of each event and applied during the sporting event.
* Market segmentation models must optimize for similar ad response history.
* Sampling must guarantee mutual and collective exclusively between local and global segmentation models that share the same features.
* Local market segmentation models will be applied before determining a user's propensity to respond to an advertisement.
* Ad response models must support non-linear boundaries of features.
* The ad propensity model uses a cut threshold is 0.45 and retrains occur if weighted Kappa deviated from
0.1 +/- 5%.
* The ad propensity model uses cost factors shown in the following diagram: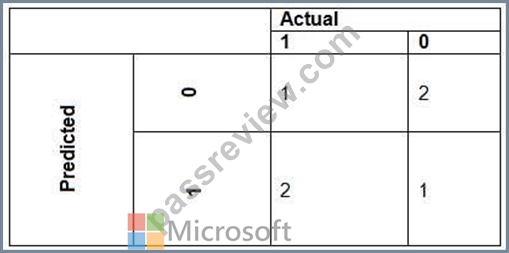
* The ad propensity model uses proposed cost factors shown in the following diagram: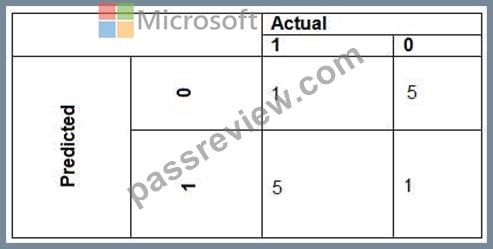
* Performance curves of current and proposed cost factor scenarios are shown in the following diagram: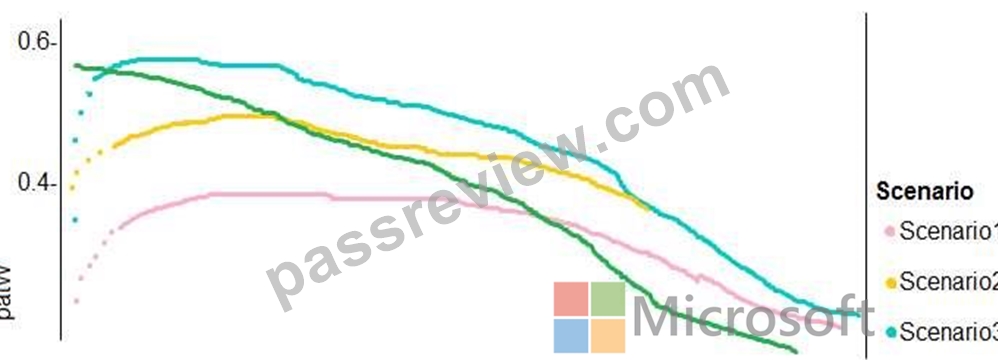
NEW QUESTION # 87
You create an Azure Data Lake Storage Gen2 stowage account named storage1 containing a file system named fsi and a folder named folder1.
The contents of folder1 must be accessible from jobs on compute targets in the Azure Machine Learning workspace.
You need to construct a URl to reference folder1.
How should you construct the URI? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.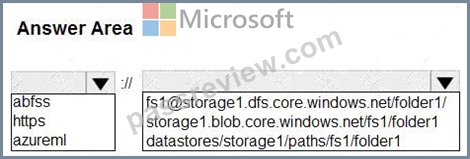
Answer:
Explanation: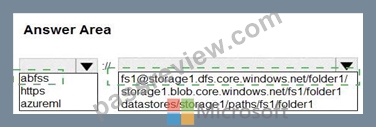
Explanation: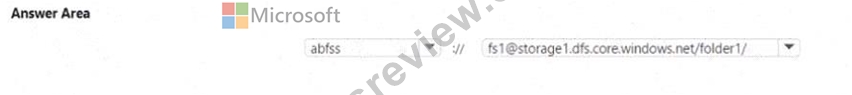
NEW QUESTION # 88
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You create an Azure Machine Learning service datastore in a workspace. The datastore contains the following files:
/data/2018/Q1.csv
/data/2018/Q2.csv
/data/2018/Q3.csv
/data/2018/Q4.csv
/data/2019/Q1.csv
All files store data in the following format:
id,f1,f2,I
1,1,2,0
2,1,1,1
3,2,1,0
4,2,2,1
You run the following code: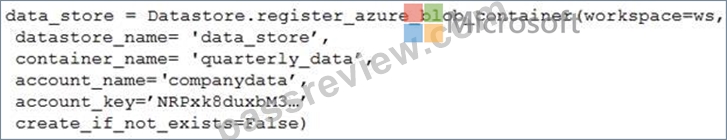
You need to create a dataset named training_data and load the data from all files into a single data frame by using the following code:
Solution: Run the following code:
Does the solution meet the goal?
Answer: A
Explanation:
Use two file paths.
Use Dataset.Tabular_from_delimeted, instead of Dataset.File.from_files as the data isn't cleansed.
Note:
A FileDataset references single or multiple files in your datastores or public URLs. If your data is already cleansed, and ready to use in training experiments, you can download or mount the files to your compute as a FileDataset object.
A TabularDataset represents data in a tabular format by parsing the provided file or list of files.
This provides you with the ability to materialize the data into a pandas or Spark DataFrame so you can work with familiar data preparation and training libraries without having to leave your notebook. You can create a TabularDataset object from .csv, .tsv, .parquet, .jsonl files, and from SQL query results.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-create-register-datasets
NEW QUESTION # 89
......
Most people define DP-100 study tool as regular books and imagine that the more you buy, the higher your grade may be. It is true this kind of view make sense to some extent. However, our DP-100 real questions are high efficient priced with reasonable amount, acceptable to exam candidates around the world. Our DP-100 practice materials comprise of a number of academic questions for your practice, which are interlinked and helpful for your exam. Unlike those untenable practice materials in the market, our DP-100 practice materials are highly utilitarian for their accuracy of the real exam because all content are compiled by proficient experts who engaged in this area more than ten years. It is our unswerving will to help you pass the exam by DP-100 study tool smoothly.
Practice DP-100 Test Engine: https://www.passreview.com/DP-100_exam-braindumps.html
P.S. Free 2026 Microsoft DP-100 dumps are available on Google Drive shared by PassReview: https://drive.google.com/open?id=1uoEVOXbxILXA23fieG_AhhHFqL0JYE0w