We understand you not only consider the quality of our Claude Certified Architect - Professional prepare torrents, but price and after-sales services and support, and other factors as well. So our Claude Certified Architect - Professional prepare torrents contain not only the high quality and high accuracy CCAR-P Test Braindumps but comprehensive services as well. By the free trial services you can get close realization with our CCAR-P quiz guides, and know how to choose the perfect versions before your purchase.
| Section | Objectives |
|---|---|
| Topic 1: Stakeholder Engagement and Solution Lifecycle | - Solution lifecycle, handoff, adoption, and operational enablement - Stakeholder discovery and architectural trade-off communication |
| Topic 2: Evaluation and Optimization | - Evaluation design and acceptance criteria - Model and architecture optimization |
| Topic 3: Solution Design | - Model, architecture, context, and deployment strategy selection - Claude platform and solution architecture |
| Topic 4: Governance, Safety, and Risk | - Security, compliance, risk management, and governance - Safety controls and fail-closed system design |
| Topic 5: Enterprise Integration and Production | - Cost, latency, reliability, and operational design - Enterprise integration architecture and production readiness |
>> Exam CCAR-P Questions Fee <<
As to this fateful exam that can help you or break you in some circumstances, our company made these CCAR-P practice materials with accountability. We understand you can have more chances being accepted by other places and getting higher salary or acceptance. Our CCAR-Ptraining materials are made by our responsible company which means you can gain many other benefits as well. We offer free demos for your reference, and send you the new updates if our experts make them freely.
NEW QUESTION # 113
You are evaluating model-selection claims used by a peer team.
For each statement, select yes if the statement is generally true. Otherwise, select no.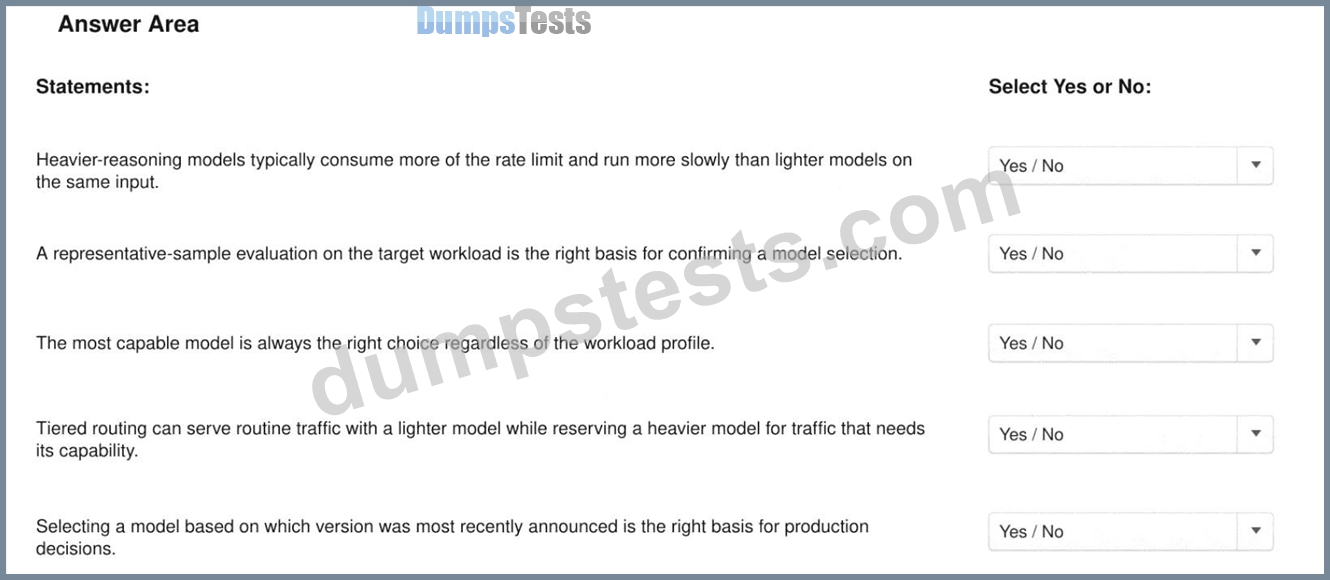
Answer:
Explanation: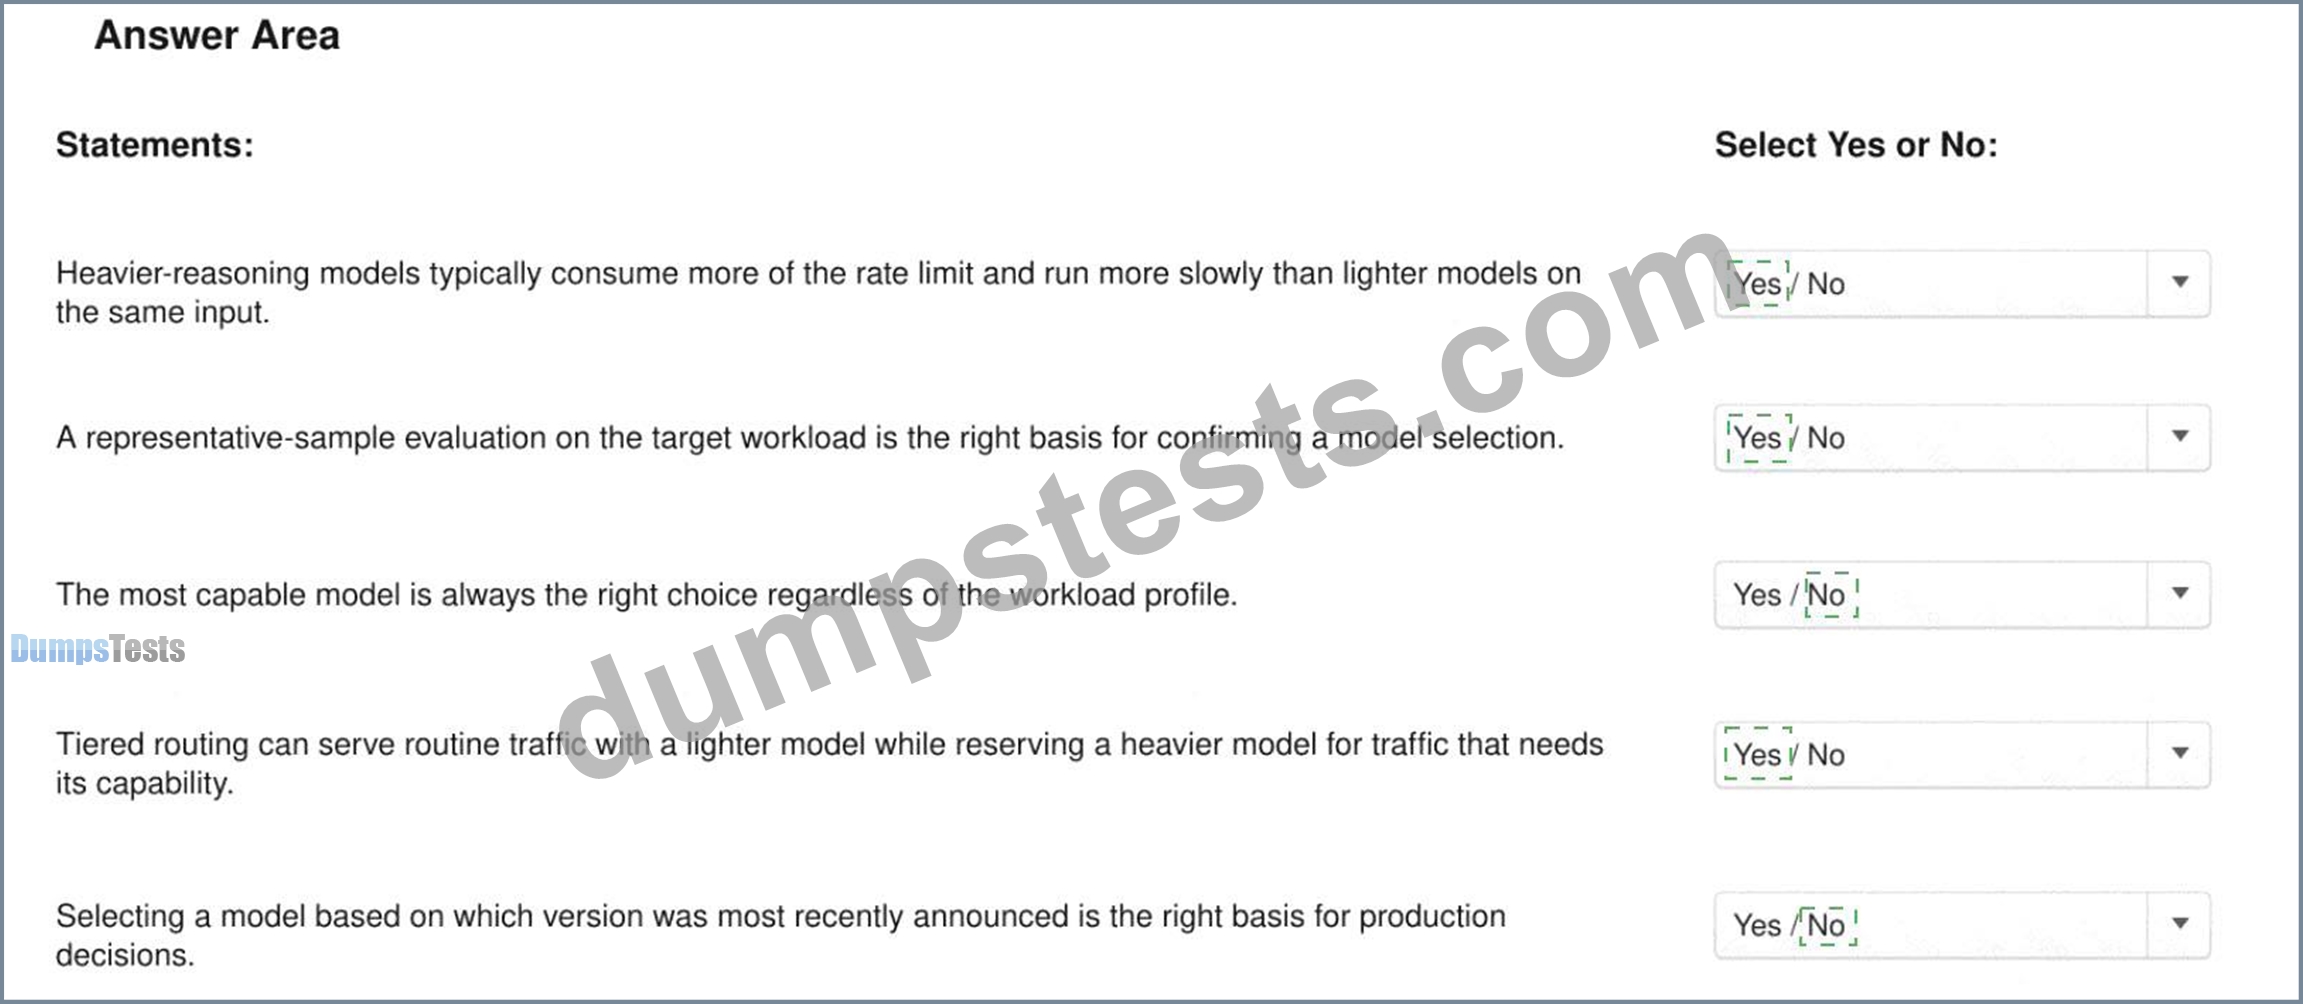
Explanation:
Yes, Yes, No, Yes, No
More capable reasoning configurations generally require greater computation, produce higher latency, and may consume larger token or rate-limit allocations than lighter alternatives. This makes the first statement generally accurate, although actual performance must be measured under the organization's specific provider and service tier.
Representative workload testing is essential because generic benchmark rankings do not establish performance on the organization's prompts, data, edge cases, tools, or required output format. Anthropic recommends benchmark tests specific to the use case, using actual prompts and data, followed by comparison of accuracy, quality, edge-case behavior, and cost. Choosing the Right Model The strongest model is not automatically the correct production choice. Model selection must balance capability, speed, cost, throughput, and operational constraints. Tiered routing implements this principle by serving predictable requests with an efficient model and escalating difficult cases to a more capable model.
Anthropic documents multi-model strategies in which lower-cost workers handle most traffic while harder decisions are escalated.
Recency is also not a valid selection criterion. A newly announced model must pass the workload's existing evaluation, security, latency, and cost gates before replacing a validated production model.
Study Guide references/topics: Model trade-offs; representative evaluations; tiered routing; escalation architectures; cost-capability optimization; model migration validation.
NEW QUESTION # 114
You are rolling out monitoring for a Claude-based deployment and must complete the specification steps before instrumenting the deployment.
Which two steps must be completed BEFORE instrumenting the deployment to emit metrics and traces?
(Select two.)
Each correct answer presents part of the solution.
Answer: A,D
Explanation:
Instrumentation must be driven by an explicit measurement specification. The team must first define the metrics and evaluation slices required to detect performance, cost, quality, safety, or reliability failures. Slices should include representative traffic, adversarial inputs, user segments, tools, and relevant content categories.
SLOs and error budgets must also be established before instrumentation because they determine required measurements, aggregation windows, and acceptable failure levels. Alert thresholds cannot be tuned until normal-state data has been collected. Dashboards and on-call documentation depend on the final metric definitions and observed operational behavior. Anthropic supports metrics, event, and trace export through OpenTelemetry, but telemetry is useful only when tied to measurable success and operating objectives.
Claude Code monitoring
NEW QUESTION # 115
You are listing characteristics of robust guardrail design for an enterprise deployment.
Which two characteristics belong on the list? (Select two.)
Each correct answer presents a complete solution.
Answer: C,E
Explanation:
Robust guardrails require both preventive enforcement and continuous empirical validation. Per-role tool allow-lists satisfy the preventive requirement by restricting each authenticated role to explicitly authorized tools. Enforcement must occur in the orchestration or permission layer before execution; relying on the model to decide whether a tool call is authorized is not an adequate security boundary. Anthropic recommends allow- list-based validation and provides permission rules and pre-tool-use controls capable of denying calls before they execute.
Adversarial evaluation with regression tracking supplies the validation component. The evaluation set should include prompt injections, indirect injections, encoded instructions, multi-turn escalation, role-confusion attempts, and requests designed to trigger unauthorized tool use. Guardrail performance must then be measured across releases so that changes to prompts, models, tools, or orchestration logic do not silently reduce protection.
Centralized logging and user feedback are useful detective and lifecycle controls, but neither prevents an unsafe action nor proves guardrail effectiveness. Periodically refreshing refusal wording is also insufficient unless the revised behavior is evaluated against defined safety criteria. The strongest design therefore combines deterministic authorization with adversarial regression testing.
Study Guide references/topics: Claude Code permissions and pre-tool enforcement ; tool allow-list guidance ; adversarial evaluations; regression testing; least-privilege orchestration.
NEW QUESTION # 116
A security audit uncovers two issues: (1) all end users share a single API key, and (2) tool calls are executed without logging the initiating user.
Which two mitigations directly address these specific findings? (Select two.)
Answer: D,E
Explanation:
Per-user, scope-restricted OAuth tokens directly eliminate the shared-credential weakness. Each token represents a distinct user or delegated identity, carries only the permissions required for that user's role, and can be revoked independently. This supports least privilege, limits the blast radius of credential compromise, and enables authorization decisions to be tied to a specific principal instead of an undifferentiated shared API key.
Actor attribution in tool-call logs directly resolves the second finding. Each audit event should record the authenticated user, delegated service identity, session or request identifier, tool name, authorization decision, relevant resource, timestamp, and outcome. This establishes accountability and permits incident investigators to reconstruct who initiated a consequential action.
Moving credentials into a server-side secret store is sound secret-management practice, but it does not by itself correct the shared-identity problem: a centrally stored key can still represent every user as the same principal. Schema validation protects downstream processing, while retrieval-layer RBAC protects information access; neither addresses the two specific audit findings.
These controls should be reinforced by short-lived tokens, server-side authorization enforcement, sensitive- field redaction, and tamper-resistant audit-log retention.
Study Guide references/topics: [Claude Code security](https://docs.anthropic.com/en/docs/claude-code
/security); [MCP authentication and OAuth] (https://docs.anthropic.com/en/docs/claude-code/mcp); least privilege; identity propagation; auditable tool execution.
NEW QUESTION # 117
A healthcare organization is evaluating two Claude-powered AI architectures for a clinical documentation assistant. Architecture X produces higher output quality scores but costs $0.18 per documentation session and averages 4.2 seconds per response. Architecture Y scores slightly lower on quality metrics but costs $0.09 per session and averages 2.1 seconds per response. The stated SLA requires responses under 3 seconds, and the annual volume is projected at 2 million documentation sessions.
Which evaluation approach correctly applies business value pillar analysis to this decision?
Answer: A
Explanation:
Architecture X fails a stated production gate: its 4.2-second average exceeds the required three-second response SLA. It should therefore not remain a qualifying architecture unless it is redesigned and retested before selection. A promise to optimize after deployment is not evidence of compliance.
Architecture Y meets the latency requirement at 2.1 seconds. Its annual inference cost is $180,000 at two million sessions, compared with $360,000 for Architecture X-a difference of $180,000 annually. However, cost alone does not establish suitability. The organization must determine whether Y's lower quality score causes material omissions, correction effort, clinician dissatisfaction, documentation risk, or reduced workflow productivity.
Option C correctly treats the SLA as a threshold and then analyzes the remaining architecture across cost, efficiency, quality, and productivity. Option A ignores clinical quality. Option B disregards an explicit SLA failure. Option D may eventually be viable, but it introduces routing complexity and leaves unanswered how complex cases are detected, whether X's latency becomes acceptable for them, and how both paths are evaluated.
The final choice should be gated by clinical-quality evaluation, human review requirements, safety metrics, operational latency, and total annual cost.
Study Guide references/topics: Business-value pillars; performance gates; solution cost; workflow efficiency; quality trade-offs; healthcare architecture evaluation.
NEW QUESTION # 118
......
DumpsTests is a website provide you with the best and valid CCAR-P exam questions that elaborately compiled and highly efficiently, studying with our CCAR-P study guide will cost you less time and energy, because we shouldn't waste our money on some unless things. The passing rate and the hit rate of our CCAR-P Training Material are also very high, there are thousands of candidates choose to trust our website and they have passed the CCAR-P exam. We provide with candidate so many guarantees that they can purchase our CCAR-P study materials no worries.
New CCAR-P Exam Duration: https://www.dumpstests.com/CCAR-P-latest-test-dumps.html