AI-300 考題寶典由 Testpdf 在世界各地的資深IT工程師組成的專業團隊製作完成,Microsoft 的 AI-300 考題寶典內包含最新的 AI-300 考試試題,並附有全部正確答案,保證一次輕鬆通過 AI-300 考試,完全無需購買其他額外的AI-300 複習資料。並且購買 AI-300 考題後,享有一年的免費更新服務。
| Section | Objectives |
|---|---|
| Optimize generative AI systems and model performance | - Optimize inference performance, caching, and throughput - Implement cost management and scaling strategies for GenAI workloads - Tune prompts, system messages, and grounding strategies - Fine-tune and distill models for specific use cases |
| Design and implement a GenAIOps infrastructure | - Manage API keys, rate limits, and responsible AI guardrails - Configure prompt orchestration, prompt flows, and agent frameworks - Implement RAG (Retrieval-Augmented Generation) pipelines and vector search - Set up Microsoft Foundry and Azure AI services for generative AI workloads |
| Design and implement an MLOps infrastructure | - Implement security, governance, and compliance for MLOps - Configure source control, CI/CD pipelines, and automation for ML workflows - Set up Azure Machine Learning workspace and compute targets - Manage environments, data stores, and model registries |
| Implement machine learning model lifecycle and operations | - Train, register, and version models using Azure Machine Learning - Deploy models to real-time and batch endpoints - Monitor model performance, data drift, and operational health - Retrain, update, and manage model versions in production |
| Implement generative AI quality assurance and observability | - Monitor latency, token usage, cost, and error rates - Conduct red teaming, adversarial testing, and content filtering - Evaluate generative AI outputs for quality, safety, and grounding - Implement logging, tracing, and telemetry for GenAI applications |
彰顯一個人在某一領域是否成功往往體現在他所獲得的資格證書上,在IT行業也不外如是。所以現在很多人都選擇參加AI-300資格認證考試來證明自己的實力。但是要想通過AI-300資格認證卻不是一件簡單的事。不過只要你找對了捷徑,通過考試也就變得容易許多了。這就不得不推薦Testpdf的考試考古題了,它可以讓你少走許多彎路,節省時間幫助你考試合格。
問題 #129
An organization maintains separate Azure Machine Learning workspaces for development and production.
Both environments must use the same validated assets without duplicating them.
Assets must be shared across workspaces while maintaining centralized governance and version control.
You need to enable reuse of assets across workspaces without copying them.
What should you do?
答案:C
解題說明:
Microsoft ' s Azure Machine Learning documentation on registries describes them as organization-level repositories that sit above individual workspaces. When you publish an asset such as a model, environment, or component to an Azure ML registry, it becomes accessible to any workspace in any subscription within the same Azure tenant, all without physical duplication. The registry maintains a single source of truth with full version history. Option A (Git integration) synchronizes code, not compiled ML artifacts. Option B (pipeline component) packages a reusable pipeline step but does not solve cross-workspace sharing. Option C (shared environment) addresses runtime dependencies, not the full range of ML assets. The registry is the purpose- built solution for centralized governance, version control, and cross-workspace asset sharing - the Microsoft- recommended pattern for mature MLOps organizations.
Microsoft Learn Reference Topic: Share assets across workspaces with Azure Machine Learning registries
問題 #130
You manage an Azure Machine Learning workspace. You have a folder that contains a CSV file.
The folder is registered as a folder data asset.
You plan to use the folder data asset for data wrangling during interactive development.
You need to access and load the folder data asset into a Pandas data frame.
Which method should you use to achieve this goal?
答案:C
解題說明:
Azure Machine Learning supports a Table type (mltable). This allows for the creation of a blueprint that defines how to load data files into memory as a Pandas or Spark data frame.
Authoring MLTable Files
To directly create the MLTable file, we recommend that you use the mltable Python SDK to author your MLTable files instead of a text editor.
Supported file types
You can create an MLTable using a range of different file types:
* Delimited Text
(for example, CSV files)
from_delimited_files(paths=[path])
Incorrect:
* Parquet
from_parquet_files(paths=[path])
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-mltable
問題 #131
A Retrieval-Augmented Generation (RAG) solution returns incomplete answers because relevant content is inconsistently retrieved from the knowledge source.
You need to improve RAG accuracy without changing the embedding model currently in use. You need to achieve this goal while minimizing operational costs.
Which two actions should you perform? Each correct answer presents part of the solution.
Choose two.
NOTE: Each correct selection is worth one point.
答案:B,D
解題說明:
To improve Retrieval-Augmented Generation (RAG) accuracy, address inconsistent retrieval, and eliminate incomplete answers without changing the embedding model or increasing costs significantly, you must move beyond naive fixed-length chunking and implement a two-stage retrieval process.
Here is the targeted, low-cost strategy:
1. Tune Chunk Size and Overlap to Match Content Structure
Inconsistent retrieval often occurs because important information is split across chunk boundaries (breaking context) or chunks are too large, diluting the semantic meaning.
2. Implement an Optimized Re-ranker
The initial vector search often returns "noise"-chunks that are semantically close but not actually relevant. A re-ranker acts as a second, smarter, but more "expensive" step that works on a smaller subset of data, making it low-cost overall.
Reference:
https://medium.com/@sthanikamsanthosh1994/how-to-improve-rag-retrieval-augmented- generation-performance-2a42303117f8
問題 #132
A real-time endpoint experiences sporadic latency spikes. Investigation reveals instances scale down to zero during inactivity. You need to reduce latency without significantly increasing cost.
What should you configure?
答案:B
問題 #133
You use Azure Machine Learning to train models across multiple experiments by using the same workspace.
You must record training runs in a centralized location to compare results from different jobs.
During training, performance values must be captured so they appear in the experiment run history.
You need to configure experiment tracking.
What should you configure for each requirement? To answer, select the appropriate options in the answer area
. NOTE: Each correct selection is worth one point.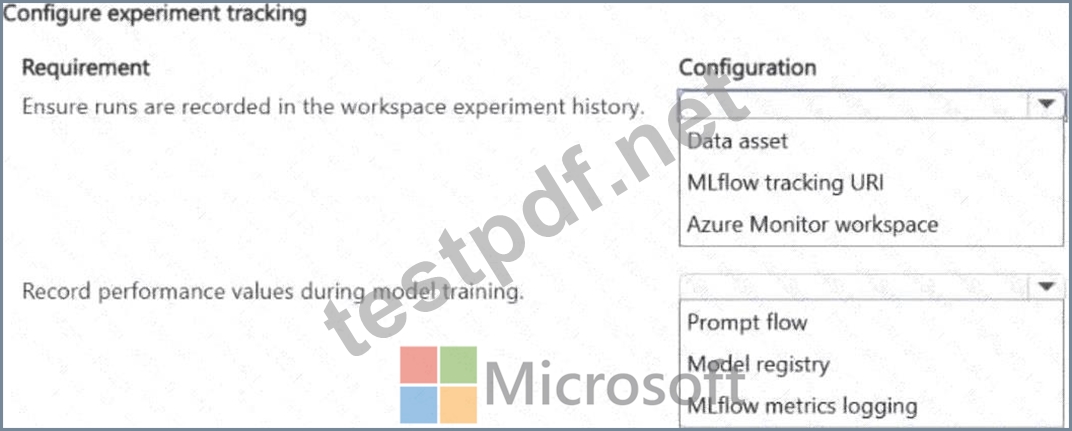
答案:
解題說明: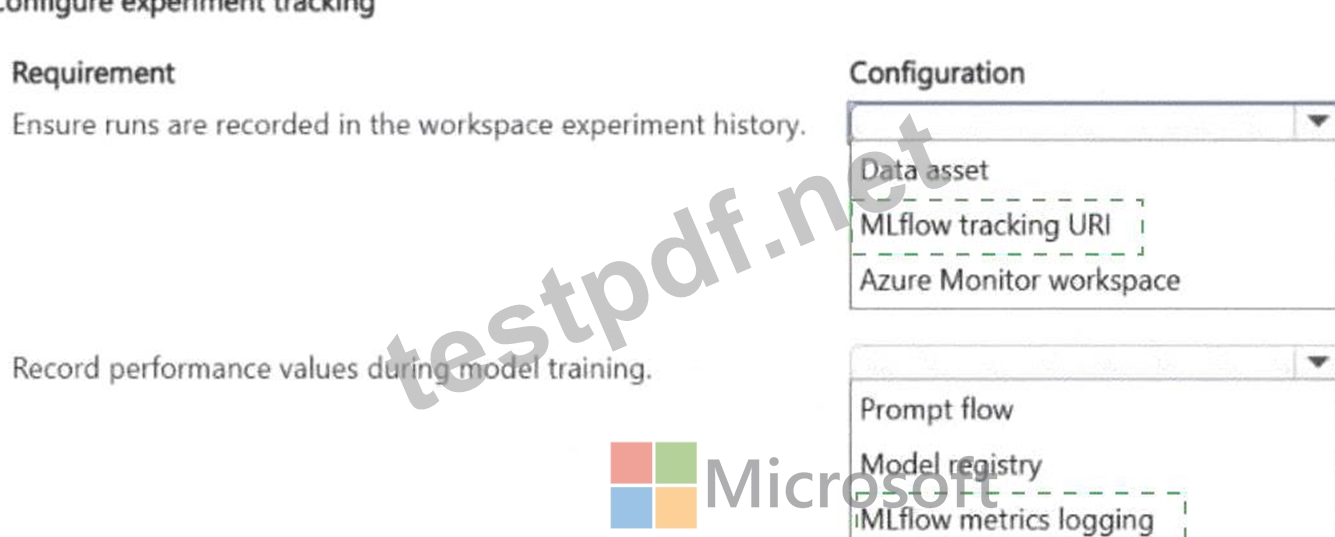
Explanation:
Azure Machine Learning ' s experiment tracking is built around two complementary concepts. First, experiments are named containers that group related runs. By calling mlflow.set_experiment with an experiment name at the start of your training code, all subsequent runs are grouped under that experiment name in the AML workspace, creating the centralized record required. Second, metrics are scalar values such as accuracy, loss, or AUC that represent model performance. Calling mlflow.log_metric with a metric name and value during training persists these values to the run ' s record in the experiment history. These values appear on the Azure ML Studio run detail page and can be compared across runs using the experiment comparison view. Without set_experiment, runs fall into a default experiment. Without log_metric, the run history has no performance data to display or compare.
Microsoft Learn Reference Topic: Track machine learning experiments with MLflow in Azure Machine Learning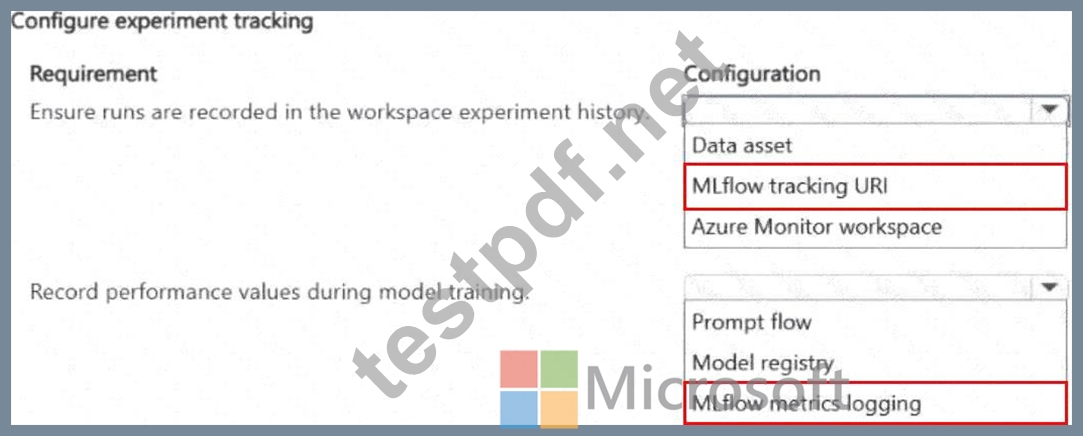
問題 #134
......
當你進入Testpdf網站,你看到每天進入Testpdf網站的人那麼多,不禁感到意外。其實這很正常的,我們Testpdf網站每天給不同的考生提供培訓資料數不勝數,他們都是利用了我們的培訓資料才順利通過考試的,說明我們的Microsoft的AI-300考試認證培訓資料真起到了作用,如果你也想購買,那就不要錯過我們Testpdf網站,你一定會非常滿意的。
AI-300考題寶典: https://www.testpdf.net/AI-300.html