What's more, part of that TestBraindump ACD-301 dumps now are free: https://drive.google.com/open?id=1Gc8qAhcx8qg34xngHrVrl2l07rM4JRFJ
If you still have questions with passing the exam, choose us, and we will help you pass the exam successfully. Our ACD-301 training materials contain the both the questions and answers. You can have a practice through different versions. If you prefer to practice on paper, then ACD-301 Pdf Version will satisfy you. If you want to have a good command of the ACD-301 exam dumps, you can buy all three versions, which can assist you for practice.
| Section | Objectives |
|---|---|
| Topic 1: Platform Management | - Troubleshoot and resolve issues at the environment level, involving Appian Support when necessary - Schedule, execute, and troubleshoot application deployments across environments - Describe basic platform enterprise architecture and how it's used - Implement administration console settings |
| Topic 2: Application Design and Development | - Implement best practices for multiple application development - Evaluate and design applications for consistency and reusability - Evaluate how Appian can meet user requirements - Design applications leveraging Appian functionality |
| Topic 3: Proactively Design for Scalability and Performance | - Build and maintain scalable applications - Monitor and troubleshoot issues at the application level - Design and implement performant Appian components - Plan and evaluate load testing |
| Topic 4: Project and Resource Management | - Manage and lead essential activities across an Agile team - Recommend the protocols and procedures involved in Appian governance - Interpret client requirements and recommend technical design options |
| Topic 5: Data Management | - Analyze and design secure data models - Implement advanced database features - Diagnose and troubleshoot data fabric complexities - Analyze, evaluate, and troubleshoot high-volume database structures - Plan, execute, and troubleshoot data migrations - Determine the best way to leverage data fabric, data types, and data migration |
| Topic 6: Extending Appian | - Evaluate and implement authentication using connected systems - Design and troubleshoot advanced integrations - Evaluate existing plug-ins and recognize when to develop custom plug-ins - Program advanced APIs that allow Appian to communicate with external systems - Evaluate advanced document generation options |
>> Latest ACD-301 Exam Dumps <<
The high quality and high efficiency of our ACD-301 exam materials has helped many people pass exams quickly. After they get a ACD-301 certificate, they now have more job opportunities. And you can just look at the feedbacks from our worthy customrs on the website thanking for our ACD-301 learning guide. The current situation is very serious. Selecting our ACD-301 training guide is your best decision.
NEW QUESTION # 36
You are deciding the appropriate process model data management strategy.
For each requirement. match the appropriate strategies to implement. Each strategy will be used once.
Note: To change your responses, you may deselect your response by clicking the blank space at the top of the selection list.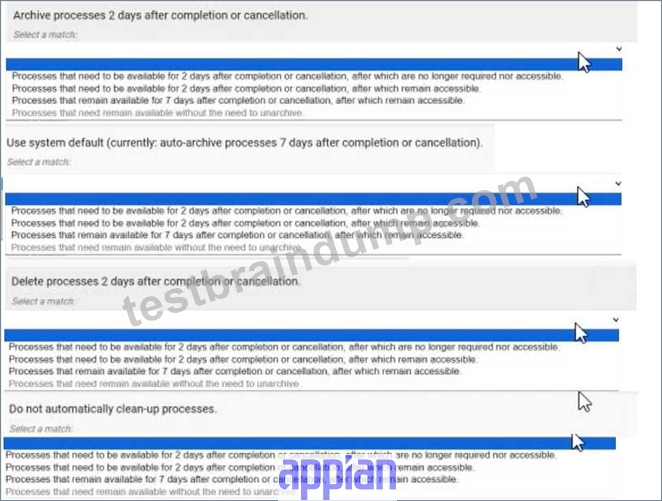
Answer:
Explanation: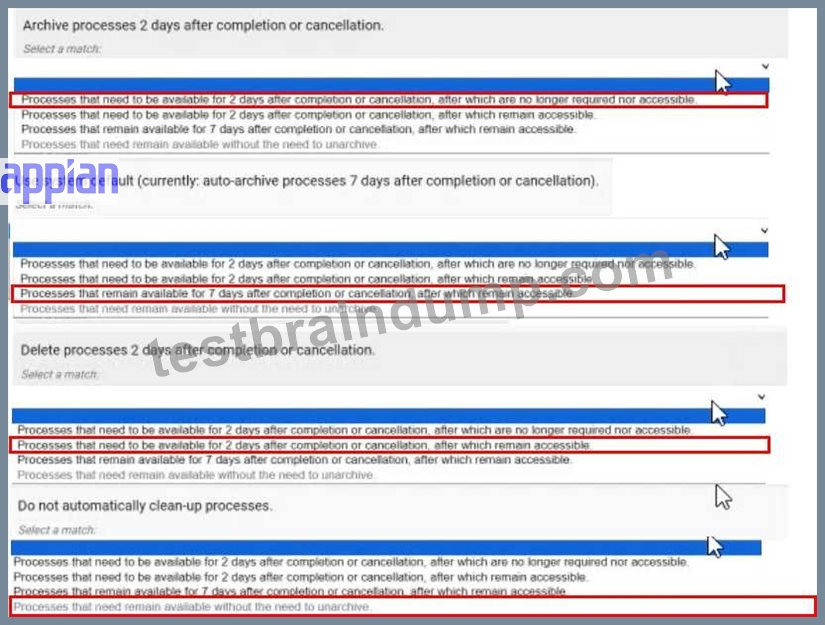
NEW QUESTION # 37
You are developing a case management application to manage support cases for a large set of sites. One of the tabs in this application s site Is a record grid of cases, along with Information about the site corresponding to that case. Users must be able to filter cases by priority level and status.
You decide to create a view as the source of your entity-backed record, which joins the separate case/site tables (as depicted in the following Image).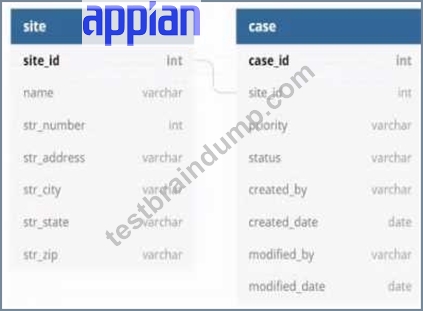
Which three column should be indexed?
Answer: A,D,F
Explanation:
Indexing columns can improve the performance of queries that use those columns in filters, joins, or order by clauses. In this case, the columns that should be indexed are site_id, status, and priority, because they are used for filtering or joining the tables. Site_id is used to join the case and site tables, so indexing it will speed up the join operation. Status and priority are used to filter the cases by the user's input, so indexing them will reduce the number of rows that need to be scanned. Name, modified_date, and case_id do not need to be indexed, because they are not used for filtering or joining. Name and modified_date are only used for displaying information in the record grid, and case_id is only used as a unique identifier for each record. Verified Appian Records Tutorial,Appian Best Practices As an Appian Lead Developer, optimizing a database view for an entity-backed record grid requires indexing columns frequently used in queries, particularly for filtering and joining. The scenario involves a record grid displaying cases with site information, filtered by "priority level" and "status," and joined via the site_id foreign key. The image shows two tables (site and case) with a relationship via site_id. Let's evaluate each column based on Appian's performance best practices and query patterns:
A . site_id:This is a primary key in the site table and a foreign key in the case table, used for joining the tables in the view. Indexing site_id in the case table (and ensuring it's indexed in site as a PK) optimizes JOIN operations, reducing query execution time for the record grid. Appian's documentation recommends indexing foreign keys in large datasets to improve query performance, especially for entity-backed records. This is critical for the join and must be included.
B . status:Users filter cases by "status" (a varchar column in the case table). Indexing status speeds up filtering queries (e.g., WHERE status = 'Open') in the record grid, particularly with large datasets. Appian emphasizes indexing columns used in WHERE clauses or filters to enhance performance, making this a key column for optimization. Since status is a common filter, it's essential.
C . name:This is a varchar column in the site table, likely used for display (e.g., site name in the grid). However, the scenario doesn't mention filtering or sorting by name, and it's not part of the join or required filters. Indexing name could improve searches if used, but it's not a priority given the focus on priority and status filters. Appian advises indexing only frequently queried or filtered columns to avoid unnecessary overhead, so this isn't necessary here.
D . modified_date:This is a date column in the case table, tracking when cases were last updated. While useful for sorting or historical queries, the scenario doesn't specify filtering or sorting by modified_date in the record grid. Indexing it could help if used, but it's not critical for the current requirements. Appian's performance guidelines prioritize indexing columns in active filters, making this lower priority than site_id, status, and priority.
E . priority:Users filter cases by "priority level" (a varchar column in the case table). Indexing priority optimizes filtering queries (e.g., WHERE priority = 'High') in the record grid, similar to status. Appian's documentation highlights indexing columns used in WHERE clauses for entity-backed records, especially with large datasets. Since priority is a specified filter, it's essential to include.
F . case_id:This is the primary key in the case table, already indexed by default (as PKs are automatically indexed in most databases). Indexing it again is redundant and unnecessary, as Appian's Data Store configuration relies on PKs for unique identification but doesn't require additional indexing for performance in this context. The focus is on join and filter columns, not the PK itself.
Conclusion: The three columns to index are A (site_id), B (status), and E (priority). These optimize the JOIN (site_id) and filter performance (status, priority) for the record grid, aligning with Appian's recommendations for entity-backed records and large datasets. Indexing these columns ensures efficient querying for user filters, critical for the application's performance.
Appian Documentation: "Performance Best Practices for Data Stores" (Indexing Strategies).
Appian Lead Developer Certification: Data Management Module (Optimizing Entity-Backed Records).
Appian Best Practices: "Working with Large Data Volumes" (Indexing for Query Performance).
NEW QUESTION # 38
You are planning a strategy around data volume testing for an Appian application that queries and writes to a MySQL database. You have administrator access to the Appian application and to the database. What are two key considerations when designing a data volume testing strategy?
Answer: B,C
Explanation:
Comprehensive and Detailed In-Depth Explanation:
Data volume testing ensures an Appian application performs efficiently under realistic data loads, especially when interacting with external databases like MySQL. As an Appian Lead Developer with administrative access, the focus is on scalability, performance, and iterative validation. The two key considerations are:
Option C (The amount of data that needs to be populated should be determined by the project sponsor and the stakeholders based on their estimation):
Determining the appropriate data volume is critical to simulate real-world usage. Appian's Performance Testing Best Practices recommend collaborating with stakeholders (e.g., project sponsors, business analysts) to define expected data sizes based on production scenarios. This ensures the test reflects actual requirements-like peak transaction volumes or record counts-rather than arbitrary guesses. For example, if the application will handle 1 million records in production, stakeholders must specify this to guide test data preparation.
Option D (Testing with the correct amount of data should be in the definition of done as part of each sprint):
Appian's Agile Development Guide emphasizes incorporating performance testing (including data volume) into the Definition of Done (DoD) for each sprint. This ensures that features are validated under realistic conditions iteratively, preventing late-stage performance issues. With admin access, you can query/write to MySQL and assess query performance or write latency with the specified data volume, aligning with Appian's recommendation to "test early and often." Option A (Data from previous tests needs to remain in the testing environment prior to loading prepopulated data): This is impractical and risky. Retaining old test data can skew results, introduce inconsistencies, or violate data integrity (e.g., duplicate keys in MySQL). Best practices advocate for a clean, controlled environment with fresh, prepopulated data per test cycle.
Option B (Large datasets must be loaded via Appian processes): While Appian processes can load data, this is not a requirement. With database admin access, you can use SQL scripts or tools like MySQL Workbench for faster, more efficient data population, bypassing Appian process overhead. Appian documentation notes this as a preferred method for large datasets.
Option E (Data model changes must wait until towards the end of the project): Delaying data model changes contradicts Agile principles and Appian's iterative design approach. Changes should occur as needed throughout development to adapt to testing insights, not be deferred.
NEW QUESTION # 39
You are taking your package from the source environment and importing it into the target environment.
Review the errors encountered during inspection:
What is the first action you should take to Investigate the issue?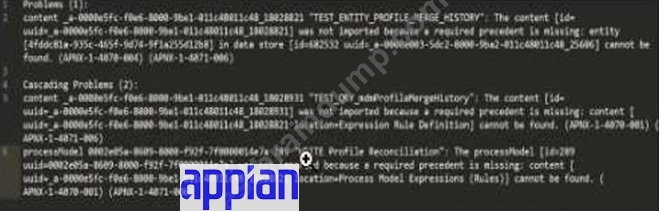
Answer: C
Explanation:
The error log provided indicates issues during the package import into the target environment, with multiple objects failing to import due to missing precedents. The key error messages highlight specific UUIDs associated with objects that cannot be resolved. The first error listed states:
"'TEST_ENTITY_PROFILE_MERGE_HISTORY': The content [id=uuid-a-0000m5fc-f0e6-8000-9b01-011c48011c48, 18028821] was not imported because a required precedent is missing: entity [uuid=a-0000m5fc-f0e6-8000-9b01-011c48011c48, 18028821] cannot be found..." According to Appian's Package Deployment Best Practices, when importing a package, the first step in troubleshooting is to identify the root cause of the failure. The initial error in the log points to an entity object with a UUID ending in 18028821, which failed to import due to a missing precedent. This suggests that the object itself or one of its dependencies (e.g., a data store or related entity) is either missing from the package or not present in the target environment.
Option A (Check whether the object (UUID ending in 18028821) is included in this package): This is the correct first action. Since the first error references this UUID, verifying its inclusion in the package is the logical starting point. If it's missing, the package export from the source environment was incomplete. If it's included but still fails, the precedent issue (e.g., a missing data store) needs further investigation.
Option B (Check whether the object (UUID ending in 7t00000i4e7a) is included in this package): This appears to be a typo or corrupted UUID (likely intended as something like "7t000014e7a" or similar), and it's not referenced in the primary error. It's mentioned later in the log but is not the first issue to address.
Option C (Check whether the object (UUID ending in 25606) is included in this package): This UUID is associated with a data store error later in the log, but it's not the first reported issue.
Option D (Check whether the object (UUID ending in 18028931) is included in this package): This UUID is mentioned in a subsequent error related to a process model or expression rule, but it's not the initial failure point.
Appian recommends addressing errors in the order they appear in the log to systematically resolve dependencies. Thus, starting with the object ending in 18028821 is the priority.
NEW QUESTION # 40
You have 5 applications on your Appian platform in Production. Users are now beginning to use multiple applications across the platform, and the client wants to ensure a consistent user experience across all applications.
You notice that some applications use rich text, some use section layouts, and others use box layouts. The result is that each application has a different color and size for the header.
What would you recommend to ensure consistency across the platform?
Answer: D
Explanation:
Comprehensive and Detailed In-Depth Explanation:
As an Appian Lead Developer, ensuring a consistent user experience across multiple applications on the Appian platform involves centralizing reusable components and adhering to Appian's design governance principles. The client's concern about inconsistent headers (e.g., different colors, sizes, layouts) across applications using rich text, section layouts, and box layouts requires a scalable, maintainable solution. Let's evaluate each option:
A . Create constants for text size and color, and update each section to reference these values:
Using constants (e.g., cons!TEXT_SIZE and cons!HEADER_COLOR) is a good practice for managing values, but it doesn't address layout consistency (e.g., rich text vs. section layouts vs. box layouts). Constants alone can't enforce uniform header design across applications, as they don't encapsulate layout logic (e.g., a!sectionLayout() vs. a!richTextDisplayField()). This approach would require manual updates to each application's components, increasing maintenance overhead and still risking inconsistency. Appian's documentation recommends using rules for reusable UI components, not just constants, making this insufficient.
B . In the common application, create a rule that can be used across the platform for section headers, and update each application to reference this new rule:
This is the best recommendation. Appian supports a "common application" (often called a shared or utility application) to store reusable objects like expression rules, which can define consistent header designs (e.g., rule!CommonHeader(size: "LARGE", color: "PRIMARY")). By creating a single rule for headers and referencing it across all 5 applications, you ensure uniformity in layout, color, and size (e.g., using a!sectionLayout() or a!boxLayout() consistently). Appian's design best practices emphasize centralizing UI components in a common application to reduce duplication, enforce standards, and simplify maintenance-perfect for achieving a consistent user experience.
C . In the common application, create one rule for each application, and update each application to reference its respective rule:
This approach creates separate header rules for each application (e.g., rule!App1Header, rule!App2Header), which contradicts the goal of consistency. While housed in the common application, it introduces variability (e.g., different colors or sizes per rule), defeating the purpose. Appian's governance guidelines advocate for a single, shared rule to maintain uniformity, making this less efficient and unnecessary.
D . In each individual application, create a rule that can be used for section headers, and update each application to reference its respective rule:
Creating separate rules in each application (e.g., rule!App1Header in App 1, rule!App2Header in App 2) leads to duplication and inconsistency, as each rule could differ in design. This approach increases maintenance effort and risks diverging styles, violating the client's requirement for a "consistent user experience." Appian's best practices discourage duplicating UI logic, favoring centralized rules in a common application instead.
Conclusion: Creating a rule in the common application for section headers and referencing it across the platform (B) ensures consistency in header design (color, size, layout) while minimizing duplication and maintenance. This leverages Appian's application architecture for shared objects, aligning with Lead Developer standards for UI governance.
Appian Documentation: "Designing for Consistency Across Applications" (Common Application Best Practices).
Appian Lead Developer Certification: UI Design Module (Reusable Components and Rules).
Appian Best Practices: "Maintaining User Experience Consistency" (Centralized UI Rules).
The best way to ensure consistency across the platform is to create a rule that can be used across the platform for section headers. This rule can be created in the common application, and then each application can be updated to reference this rule. This will ensure that all of the applications use the same color and size for the header, which will provide a consistent user experience.
The other options are not as effective. Option A, creating constants for text size and color, and updating each section to reference these values, would require updating each section in each application. This would be a lot of work, and it would be easy to make mistakes. Option C, creating one rule for each application, would also require updating each application. This would be less work than option A, but it would still be a lot of work, and it would be easy to make mistakes. Option D, creating a rule in each individual application, would not ensure consistency across the platform. Each application would have its own rule, and the rules could be different. This would not provide a consistent user experience.
Best Practices:
When designing a platform, it is important to consider the user experience. A consistent user experience will make it easier for users to learn and use the platform.
When creating rules, it is important to use them consistently across the platform. This will ensure that the platform has a consistent look and feel.
When updating the platform, it is important to test the changes to ensure that they do not break the user experience.
NEW QUESTION # 41
......
As is known to us, there are best sale and after-sale service of the ACD-301 study materials all over the world in our company. Our company has employed a lot of excellent experts and professors in the field in the past years, in order to design the best and most suitable ACD-301 study materials for all customers. More importantly, it is evident to all that the ACD-301 study materials from our company have a high quality, and we can make sure that the quality of our products will be higher than other study materials in the market. If you want to pass the ACD-301 Exam and get the related certification in the shortest time, choosing the ACD-301 study materials from our company will be in the best interests of all people. We can make sure that it will be very easy for you to pass your exam and get the related certification in the shortest time that beyond your imagination.
ACD-301 Test Torrent: https://www.testbraindump.com/ACD-301-exam-prep.html
2026 Latest TestBraindump ACD-301 PDF Dumps and ACD-301 Exam Engine Free Share: https://drive.google.com/open?id=1Gc8qAhcx8qg34xngHrVrl2l07rM4JRFJ