P.S. Free 2026 Amazon Data-Engineer-Associate dumps are available on Google Drive shared by Prep4away: https://drive.google.com/open?id=1GcFrKMxNYg_CpxUZ1e2ediOZA_iCb_K5
Compared with the other Data-Engineer-Associate exam questions providers' three months or five months on their free update service, we give all our customers promise that we will give one year free update on the Data-Engineer-Associate study quiz after payment. In this way, we can help our customers to pass their exams with more available opportunities with the updated Data-Engineer-Associate Preparation materials. You can feel how considerate our service is as well!
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Security and Governance | 18% | - Enforce compliance and data governance
- Encrypt data at rest and in transit |
| Topic 2: Data Ingestion and Transformation | 34% | - Implement data quality and validation - Transform and enrich data
|
| Topic 3: Data Store Management | 26% | - Manage data lifecycle and storage tiers - Design and implement data storage solutions
|
| Topic 4: Data Operations and Support | 22% | - Monitor and troubleshoot data pipelines
- Ensure reliability and scalability - Automate operational tasks |
>> Latest Data-Engineer-Associate Test Testking <<
For any candidate, choosing the Data-Engineer-Associate question torrent material is the key to passing the exam. Our study materials can fully meet all your needs: Avoid wasting your time and improve your learning efficiency. Spending little hours per day within one week, you can pass the exam easily. You will don't take any risks and losses if you purchase and learn our Data-Engineer-Associate Latest Exam Dumps, do you?
NEW QUESTION # 216
A company is developing an application that runs on Amazon EC2 instances. Currently, the data that the application generates is temporary. However, the company needs to persist the data, even if the EC2 instances are terminated.
A data engineer must launch new EC2 instances from an Amazon Machine Image (AMI) and configure the instances to preserve the data.
Which solution will meet this requirement?
Answer: B
Explanation:
Amazon EC2 instances can use two types of storage volumes: instance store volumes and Amazon EBS volumes. Instance store volumes are ephemeral, meaning they are only attached to the instance for the duration of its life cycle. If the instance is stopped, terminated, or fails, the data on the instance store volume is lost. Amazon EBS volumes are persistent, meaning they can be detached from the instance and attached to another instance, and the data on the volume is preserved. To meet the requirement of persisting the data even if the EC2 instances are terminated, the data engineer must use Amazon EBS volumes to store the application data. The solution is to launch new EC2 instances by using an AMI that is backed by an EC2 instance store volume, which is the default option for most AMIs. Then, the data engineer must attach an Amazon EBS volume to each instance and configure the application to write the data to the EBS volume. This way, the data will be saved on the EBS volume and can be accessed by another instance if needed. The data engineer can apply the default settings to the EC2 instances, as there is no need to modify the instance type, security group, or IAM role for this solution. The other options are either not feasible or not optimal. Launching new EC2 instances by using an AMI that is backed by an EC2 instance store volume that contains the application data (option A) or by using an AMI that is backed by a root Amazon EBS volume that contains the application data (option B) would not work, as the data on the AMI would be outdated and overwritten by the new instances. Attaching an additional EC2 instance store volume to contain the application data (option D) would not work, as the data on the instance store volume would be lost if the instance is terminated. References:
* Amazon EC2 Instance Store
* Amazon EBS Volumes
* AWS Certified Data Engineer - Associate DEA-C01 Complete Study Guide, Chapter 2: Data Store Management, Section 2.1: Amazon EC2
NEW QUESTION # 217
A company stores server logs in an Amazon 53 bucket. The company needs to keep the logs for 1 year. The logs are not required after 1 year.
A data engineer needs a solution to automatically delete logs that are older than 1 year.
Which solution will meet these requirements with the LEAST operational overhead?
Answer: D
Explanation:
Problem Analysis:
The company uses AWS Glue for ETL pipelines and requires automatic data quality checks during pipeline execution.
The solution must integrate with existing AWS Glue pipelines and evaluate data quality rules based on predefined thresholds.
Key Considerations:
Ensure minimal implementation effort by leveraging built-in AWS Glue features.
Use a standardized approach for defining and evaluating data quality rules.
Avoid custom libraries or external frameworks unless absolutely necessary.
Solution Analysis:
Option A: SQL Transform
Adding SQL transforms to define and evaluate data quality rules is possible but requires writing complex queries for each rule.
Increases operational overhead and deviates from Glue's declarative approach.
Option B: Evaluate Data Quality Transform with DQDL
AWS Glue provides a built-in Evaluate Data Quality transform.
Allows defining rules in Data Quality Definition Language (DQDL), a concise and declarative way to define quality checks.
Fully integrated with Glue Studio, making it the least effort solution.
Option C: Custom Transform with PyDeequ
PyDeequ is a powerful library for data quality checks but requires custom code and integration.
Increases implementation effort compared to Glue's native capabilities.
Option D: Custom Transform with Great Expectations
Great Expectations is another powerful library for data quality but adds complexity and external dependencies.
Final Recommendation:
Use Evaluate Data Quality transform in AWS Glue.
Define rules in DQDL for checking thresholds, null values, or other quality criteria.
This approach minimizes development effort and ensures seamless integration with AWS Glue.
Reference:
AWS Glue Data Quality Overview
DQDL Syntax and Examples
Glue Studio Transformations
NEW QUESTION # 218
A company needs to set up a data catalog and metadata management for data sources that run in the AWS Cloud. The company will use the data catalog to maintain the metadata of all the objects that are in a set of data stores. The data stores include structured sources such as Amazon RDS and Amazon Redshift. The data stores also include semistructured sources such as JSON files and .xml files that are stored in Amazon S3.
The company needs a solution that will update the data catalog on a regular basis. The solution also must detect changes to the source metadata.
Which solution will meet these requirements with the LEAST operational overhead?
Answer: C
Explanation:
This solution will meet the requirements with the least operational overhead because it uses the AWS Glue Data Catalog as the central metadata repository for data sources that run in the AWS Cloud. The AWS Glue Data Catalog is a fully managed service that provides a unified view of your data assets across AWS and on-premises data sources. It stores the metadata of your data in tables, partitions, and columns, and enables you to access and query your data using various AWS services, such as Amazon Athena, Amazon EMR, and Amazon Redshift Spectrum. You can use AWS Glue crawlers to connect to multiple data stores, such as Amazon RDS, Amazon Redshift, and Amazon S3, and to update the Data Catalog with metadata changes.
AWS Glue crawlers can automatically discover the schema and partition structure of your data, and create or update the corresponding tables in the Data Catalog. You can schedule the crawlers to run periodically to update the metadata catalog, and configure them to detect changes to the source metadata, such as new columns, tables, or partitions12.
The other options are not optimal for the following reasons:
A: Use Amazon Aurora as the data catalog. Create AWS Lambda functions that will connect to the data catalog. Configure the Lambda functions to gather the metadata information from multiple sources and to update the Aurora data catalog. Schedule the Lambda functions to run periodically. This option is not recommended, as it would require more operational overhead to create and manage an Amazon Aurora database as the data catalog, and to write and maintain AWS Lambda functions to gather and update the metadata information from multiple sources. Moreover, this option would not leverage the benefits of the AWS Glue Data Catalog, such as data cataloging, data transformation, and data governance.
C: Use Amazon DynamoDB as the data catalog. Create AWS Lambda functions that will connect to the data catalog. Configure the Lambda functions to gather the metadata information from multiple sources and to update the DynamoDB data catalog. Schedule the Lambda functions to run periodically. This option is also not recommended, as it would require more operational overhead to create and manage an Amazon DynamoDB table as the data catalog, and to write and maintain AWS Lambda functions to gather and update the metadata information from multiple sources. Moreover, this option would not leverage the benefits of the AWS Glue Data Catalog, such as data cataloging, data transformation, and data governance.
D: Use the AWS Glue Data Catalog as the central metadata repository. Extract the schema for Amazon RDS and Amazon Redshift sources, and build the Data Catalog. Use AWS Glue crawlers for data that is in Amazon S3 to infer the schema and to automatically update the Data Catalog. This option is not optimal, as it would require more manual effort to extract the schema for Amazon RDS and Amazon Redshift sources, and to build the Data Catalog. This option would not take advantage of the AWS Glue crawlers' ability to automatically discover the schema and partition structure of your data from various data sources, and to create or update the corresponding tables in the Data Catalog.
References:
1: AWS Glue Data Catalog
2: AWS Glue Crawlers
3: Amazon Aurora
4: AWS Lambda
5: Amazon DynamoDB
NEW QUESTION # 219
A data engineer maintains a materialized view that is based on an Amazon Redshift database. The view has a column named load_date that stores the date when each row was loaded.
The data engineer needs to reclaim database storage space by deleting all the rows from the materialized view.
Which command will reclaim the MOST database storage space?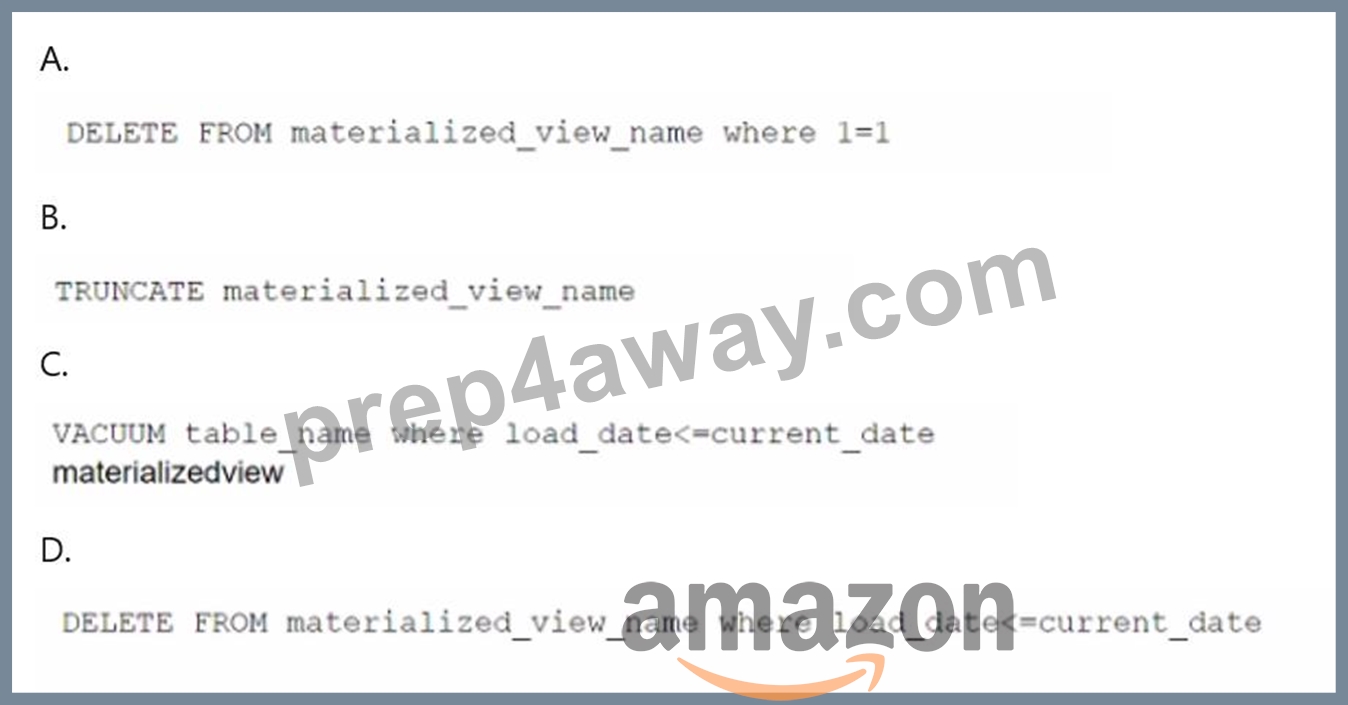
Answer: B
Explanation:
To reclaim the most storage space from a materialized view in Amazon Redshift, you should use a DELETE operation that removes all rows from the view. The most efficient way to remove all rows is to use a condition that always evaluates to true, such as 1=1. This will delete all rows without needing to evaluate each row individually based on specific column values like load_date.
Option A: DELETE FROM materialized_view_name WHERE 1=1;
This statement will delete all rows in the materialized view and free up the space. Since materialized views in Redshift store precomputed data, performing a DELETE operation will remove all stored rows.
Other options either involve inappropriate SQL statements (e.g., VACUUM in option C is used for reclaiming storage space in tables, not materialized views), or they don't remove data effectively in the context of a materialized view (e.g., TRUNCATE cannot be used directly on a materialized view).
Reference:
Amazon Redshift Materialized Views Documentation
Deleting Data from Redshift
NEW QUESTION # 220
A company is developing a product recommendation system that uses Amazon OpenSearch Service. The system needs to perform k-nearest neighbors (k-NN) vector searches on 10 million product embeddings with
768-dimensional vectors. The system must maintain high recall accuracy and support incremental updates without reindexing as new products are added each day. The system must also accommodate complex filtering based on product categories and inventory status.
Which vector index type will meet these requirements?
Answer: C
Explanation:
The correct answer is B because the scenario requires scalable approximate vector search, high recall, incremental updates, and complex filtering. Amazon OpenSearch Service supports k-NN vector search for recommendation use cases, and OpenSearch supports k-NN vector fields for high-dimensional vector search. The Lucene HNSW option is strongest here because OpenSearch documentation specifically states that Lucene supports k-NN searches using HNSW graphs and supports Lucene filters for k-NN searches. That directly matches the need for category and inventory filtering. Exact k-NN with Painless script scoring is accurate but too slow for 10 million vectors. IVF can be efficient but is less ideal for frequent incremental updates and complex filtering. Binary quantization reduces memory but sacrifices accuracy.
NEW QUESTION # 221
......
It would take a lot of serious effort to pass the AWS Certified Data Engineer - Associate (DEA-C01) (Data-Engineer-Associate) exam, therefore it wouldn't be simple. So, you have to prepare yourself for this. But since we are here to assist you, you need not worry about how you will study for the AWS Certified Data Engineer - Associate (DEA-C01) (Data-Engineer-Associate) exam dumps. You can get help from us on how to get ready for the AWS Certified Data Engineer - Associate (DEA-C01) (Data-Engineer-Associate) exam questions. We will accomplish this objective by giving you access to some excellent Data-Engineer-Associate practice test material that will enable you to get ready for the AWS Certified Data Engineer - Associate (DEA-C01) (Data-Engineer-Associate) exam dumps.
Data-Engineer-Associate Examcollection Dumps Torrent: https://www.prep4away.com/Amazon-certification/braindumps.Data-Engineer-Associate.ete.file.html
What's more, part of that Prep4away Data-Engineer-Associate dumps now are free: https://drive.google.com/open?id=1GcFrKMxNYg_CpxUZ1e2ediOZA_iCb_K5