P.S. Free & New MLA-C01 dumps are available on Google Drive shared by Prep4King: https://drive.google.com/open?id=1B-XHMGh1OoinhTaGGJaQJ9fhYDcZZusN
Prep4King allows all visitors to try a free demo of MLA-C01 pdf questions and practice tests to assess the quality of our MLA-C01 study material. Your money is 100% secure as we will ensure that you crack the Amazon MLA-C01 test on the first attempt. You will also enjoy 24/7 efficient support from our customer support team before and after the purchase of Amazon MLA-C01 Exam Dumps. If you face any issues while using our MLA-C01 PDF dumps or MLA-C01 practice exam software (desktop and web-based), contact Prep4King customer service for guidance.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
>> MLA-C01 Flexible Testing Engine <<
Improve Your Profession With MLA-C01 Questions. AWS Certified Machine Learning Engineer - Associate Questions – Best Strategy for Instant Preparation. To achieve these career objectives, you must pass the AWS Certified Machine Learning Engineer - Associate examination. Are you ready to prepare for the challenging MLA-C01test? Are you looking for the best Amazon Exam practice material? If your answer is yes, then you should rely on Prep4King and get MLA-C01 Real Exam Questions. Download these actual MLA-C01 Exam Dumps and start your journey.
NEW QUESTION # 87
A hospital wants to predict patient outcomes for the coming year An ML engineer must improve several existing ML models that currently perform poorly.
Select the correct regularization method from the following list to improve each model Select each regularization method one time, more than one time, or not at all. (Select THREE.)
* L1 regularization
* L2 regularization
* Early stopping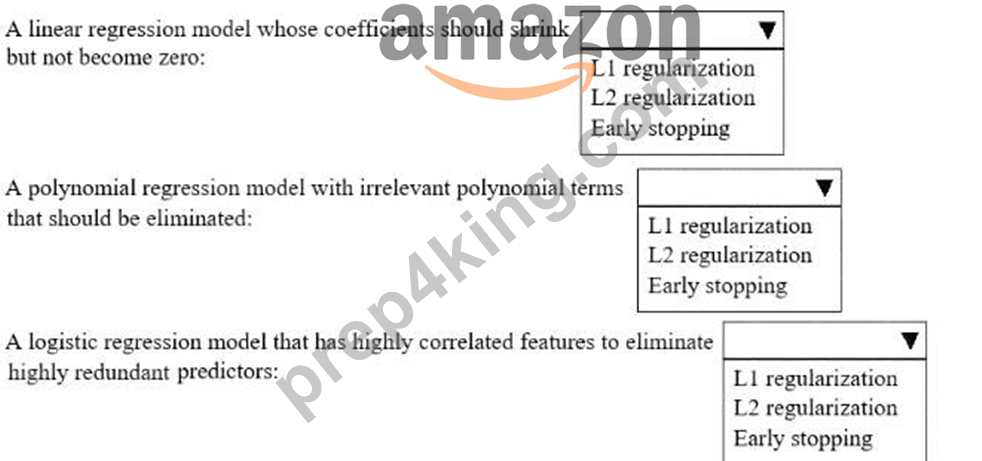
Answer:
Explanation: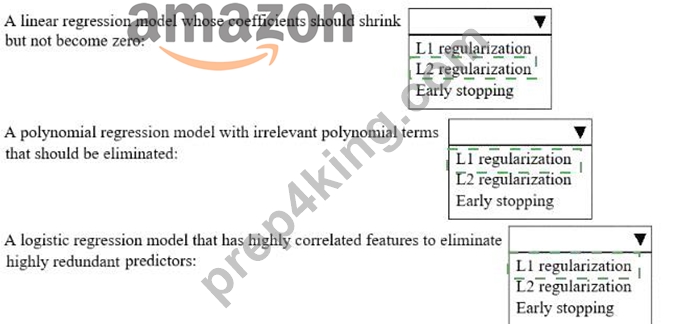
Explanation:
Linear regression model whose coefficients should shrink but not become zero answer: L2 regularization AWS says L2 produces smaller overall weight values and is the right fit when coefficients should be reduced without being forced to zero.
Polynomial regression model with irrelevant polynomial terms that should be eliminated answer: L1 regularization AWS says L1 reduces the number of features used by pushing small weights to zero , which matches elimination of irrelevant terms.
Logistic regression model that has highly correlated features to eliminate highly redundant predictors L1 regularization This is the nuanced one. AWS says L2 stabilizes weights when there is high correlation between features , but because the question explicitly says eliminate highly redundant predictors , L1 is the better match since it creates sparsity and removes predictors by zeroing coefficients.
NEW QUESTION # 88
A company wants to reduce the cost of its containerized ML applications. The applications use ML models that run on Amazon EC2 instances, AWS Lambda functions, and an Amazon Elastic Container Service (Amazon ECS) cluster. The EC2 workloads and ECS workloads use Amazon Elastic Block Store (Amazon EBS) volumes to save predictions and artifacts.
An ML engineer must identify resources that are being used inefficiently. The ML engineer also must generate recommendations to reduce the cost of these resources.
Which solution will meet these requirements with the LEAST development effort?
Answer: D
Explanation:
AWS Compute Optimizer analyzes the resource usage of Amazon EC2 instances, ECS services, Lambda functions, and Amazon EBS volumes. It provides actionable recommendations to optimize resource utilization and reduce costs, such as resizing instances, moving workloads to Spot Instances, or changing volume types. This solution requires the least development effort because Compute Optimizer is a managed service that automatically generates insights and recommendations based on historical usage data.
NEW QUESTION # 89
An ML engineer is working on an ML model to predict the prices of similarly sized homes. The model will base predictions on several features The ML engineer will use the following feature engineering techniques to estimate the prices of the homes:
* Feature splitting
* Logarithmic transformation
* One-hot encoding
* Standardized distribution
Select the correct feature engineering techniques for the following list of features. Each feature engineering technique should be selected one time or not at all (Select three.)
Answer:
Explanation: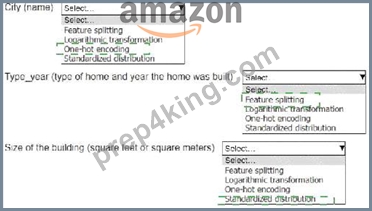
Explanation:
* City (name):One-hot encoding
* Type_year (type of home and year the home was built):Feature splitting
* Size of the building (square feet or square meters):Standardized distribution
* City (name): One-hot encoding
* Why?The "City" is a categorical feature (non-numeric), so one-hot encoding is used to transform it into a numeric format. This encoding creates binary columns for eachunique category (e.g., cities like "New York" or "Los Angeles"), which the model can interpret.
* Type_year (type of home and year the home was built): Feature splitting
* Why?"Type_year" combines two pieces of information into one column, which could confuse the model. Feature splitting separates this column into two distinct features: "Type of home" and
"Year built," enabling the model to process each feature independently.
* Size of the building (square feet or square meters): Standardized distribution
* Why?Size is a continuous numerical variable, and standardization (scaling the feature to have a mean of 0 and a standard deviation of 1) ensures that the model treats it fairly compared to other features, avoiding bias from differences in feature scale.
By applying these feature engineering techniques, the ML engineer can ensure that the input data is correctly formatted and optimized for the model to make accurate predictions.
NEW QUESTION # 90
A company collects customer data daily and stores it as compressed files in an Amazon S3 bucket partitioned by date. Each month, analysts process the data, check data quality, and upload results to Amazon QuickSight dashboards.
An ML engineer needs to automatically check data quality before the data is sent to QuickSight, with the LEAST operational overhead.
Which solution will meet these requirements?
Answer: C
Explanation:
AWS Glue Data Quality provides managed, declarative data quality checks with minimal configuration.
Combined with Glue crawlers, it enables automatic schema discovery and quality validation without custom code.
Option A uses native AWS services designed for this exact purpose, minimizing operational overhead.
Options B and C require custom code and maintenance. Option D is not designed for data validation.
AWS documentation explicitly recommends Glue Data Quality rules for scalable, automated data quality checks in analytics pipelines.
Therefore, Option A is the correct and AWS-aligned solution.
NEW QUESTION # 91
A company is training a deep learning model to detect abnormalities in images. The company has limited GPU resources and a large hyperparameter space to explore. The company needs to test different configurations and avoid wasting computation time on poorly performing models that show weak validation accuracy in early epochs.
Which hyperparameter optimization strategy should the company use?
Answer: D
Explanation:
When GPU resources are limited and the hyperparameter search space is large, AWS documentation strongly recommends Bayesian optimization combined with early stopping. Bayesian optimization uses past evaluation results to intelligently select the next set of hyperparameters to test, focusing exploration on promising regions of the search space rather than testing all combinations.
In Amazon SageMaker, Bayesian optimization is the default and recommended strategy for hyperparameter tuning jobs. It significantly reduces the number of training runs required compared to grid or random search, making it highly cost-efficient for deep learning workloads.
Early stopping further improves efficiency by terminating training jobs that show poor validation performance in early epochs. This prevents wasted GPU time on configurations that are unlikely to perform well. AWS explicitly documents early stopping as a key feature for controlling training cost and duration.
Grid search and exhaustive search are computationally expensive and impractical for large hyperparameter spaces. Manual tuning is slow, error-prone, and does not scale.
By combining Bayesian optimization with early stopping, the company can rapidly converge on high- performing hyperparameter configurations while minimizing resource usage.
Therefore, Option B is the correct and AWS-aligned solution.
NEW QUESTION # 92
......
Both practice tests simulate the Amazon MLA-C01 real exam environment and produce results of your attempts on the spot. In this way, you will be able to not only evaluate your progress but also overcome mistakes before the MLA-C01 actual examination. Windows computers support the AWS Certified Machine Learning Engineer - Associate MLA-C01 desktop practice exam software. The AWS Certified Machine Learning Engineer - Associate MLA-C01 web-based practice test needs an active internet connection.
MLA-C01 Reliable Exam Syllabus: https://www.prep4king.com/MLA-C01-exam-prep-material.html
BONUS!!! Download part of Prep4King MLA-C01 dumps for free: https://drive.google.com/open?id=1B-XHMGh1OoinhTaGGJaQJ9fhYDcZZusN