The clients at home and abroad can both purchase our DP-750 study materials online. Our brand enjoys world-wide fame and influences so many clients at home and abroad choose to buy our DP-750 study materials. Our company provides convenient service to the clients all around the world so that the clients all around the world can use our DP-750 Study Materials efficiently. Our company boosts an entire sale system which provides the links to the clients all around the world so that the clients can receive our products timely.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Deploy and maintain data pipelines and workloads | 30–35% | - Build and orchestrate pipelines
|
| Topic 2: Secure and govern Unity Catalog objects | 15–20% | - Implement data governance and security
|
| Topic 3: Prepare and process data | 30–35% | - Optimize and manage data storage
|
| Topic 4: Set up and configure an Azure Databricks environment | 15–20% | - Integrate with Azure services
|
In the Desktop DP-750 practice exam software version of Microsoft DP-750 practice test is updated and real. The software is useable on Windows-based computers and laptops. There is a demo of the DP-750 practice exam which is totally free. DP-750 practice test is very customizable and you can adjust its time and number of questions. Desktop DP-750 Practice Exam software also keeps track of the earlier attempted DP-750 practice test so you can know mistakes and overcome them at each and every step.
NEW QUESTION # 50
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that writes records to a Delta table named Table1 by using a data quality rule named rule1 You need to meet the following requirements:
* Records that violate rule! must NOT be written to Table1. but the pipeline must continue processing valid records.
* Data engineers must be able to review expectation metrics by using minimal development effort.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.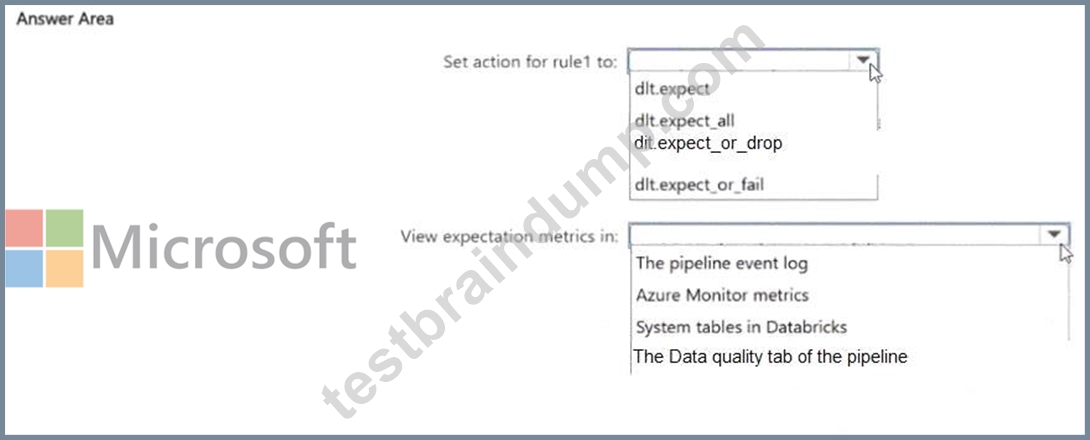
Answer:
Explanation: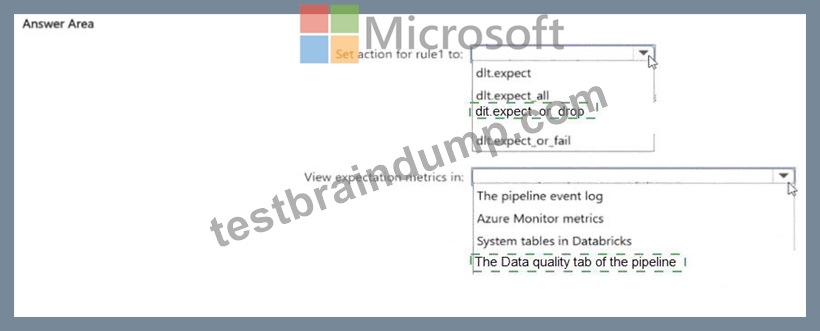
Explanation:
Two things are needed here:
For the rule enforcement: use @dlt.expect_or_drop. This drops any record that violates rule1 before it reaches Table1, while the pipeline continues processing all valid records. The table only ever receives clean data.
For reviewing metrics: the Lakeflow SDP Pipeline UI is the right tool - zero development effort required.
The pipeline graph shows expectation pass/fail counts directly on each table node, and the event log provides a detailed per-batch breakdown of how many records were dropped and why. Data engineers can inspect this at any time without writing additional monitoring queries or connecting external dashboards.
This combination is one of the strongest arguments for SDP over hand-coded Structured Streaming:
expectation observability is built in, not bolted on.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/expectations
NEW QUESTION # 51
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have 500 GB of sales data stored as multiple CSV files in cloud storage.
You plan to load the data into a Delta table.
You need to ingest the bulk data by using a solution that meets the following requirements:
* Minimize how long it takes to implement the solution.
* Minimize the amount of custom code required.
What should you use?
Answer: A
Explanation:
COPY INTO provides a concise SQL-based mechanism for loading files from cloud storage directly into a Delta table. It requires substantially less custom code than constructing a Spark ingestion application and is suitable for a straightforward bulk load of multiple CSV files. COPY INTO is also retryable and idempotent:
it tracks files already loaded into the target table and skips them during later executions, helping prevent accidental duplication. Auto Loader is optimized primarily for incremental and continuously arriving files and normally requires a streaming or triggered pipeline. Apache Spark read APIs require additional code for reading, transforming, tracking, and writing the files. Manually uploading 500 GB would be inefficient and operationally unsuitable. Therefore, COPY INTO best satisfies both implementation-speed and minimal-code requirements. Microsoft Learn
NEW QUESTION # 52
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that writes numerical data to a table named Table1 by using a data quality validation rule named rule1.
You need to modify rule1 to meet the following requirements:
* Ensure that amount is always greater than 0.
* Fail the pipeline update for Table1 when data that violates rule1 is detected.
Which statement should you execute?
Answer: C
Explanation:
The expect_or_fail decorator validates every incoming record against the expression amount > 0 and stops the table update when a violation occurs. This exactly meets the requirement that invalid data cause the pipeline update to fail. Option A applies multiple expectations and drops violating records instead of failing the update. Option B also discards invalid records while allowing valid records to continue processing. Option D records expectation metrics but retains invalid records and allows the update to continue. These alternative behaviors are useful when invalid data can be tolerated, quarantined, or monitored, but they do not satisfy strict enforcement. The fail action provides transactional protection because the affected update does not successfully publish data that violates the stated quality rule.
NEW QUESTION # 53
You have an Azure Databricks workspace named Workspace1 that is attached to a Unity Catalog metastore named metastore1 You need to register an Azure Storage account named account1 that has a hierarchical namespace enabled as an external location The external location must use a managed identity to authenticate to account1 and the solution must follow the principle of least privilege.
Which three actions should you perform in sequence' To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.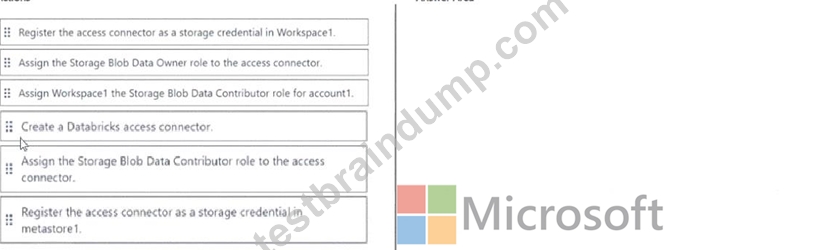
Answer:
Explanation: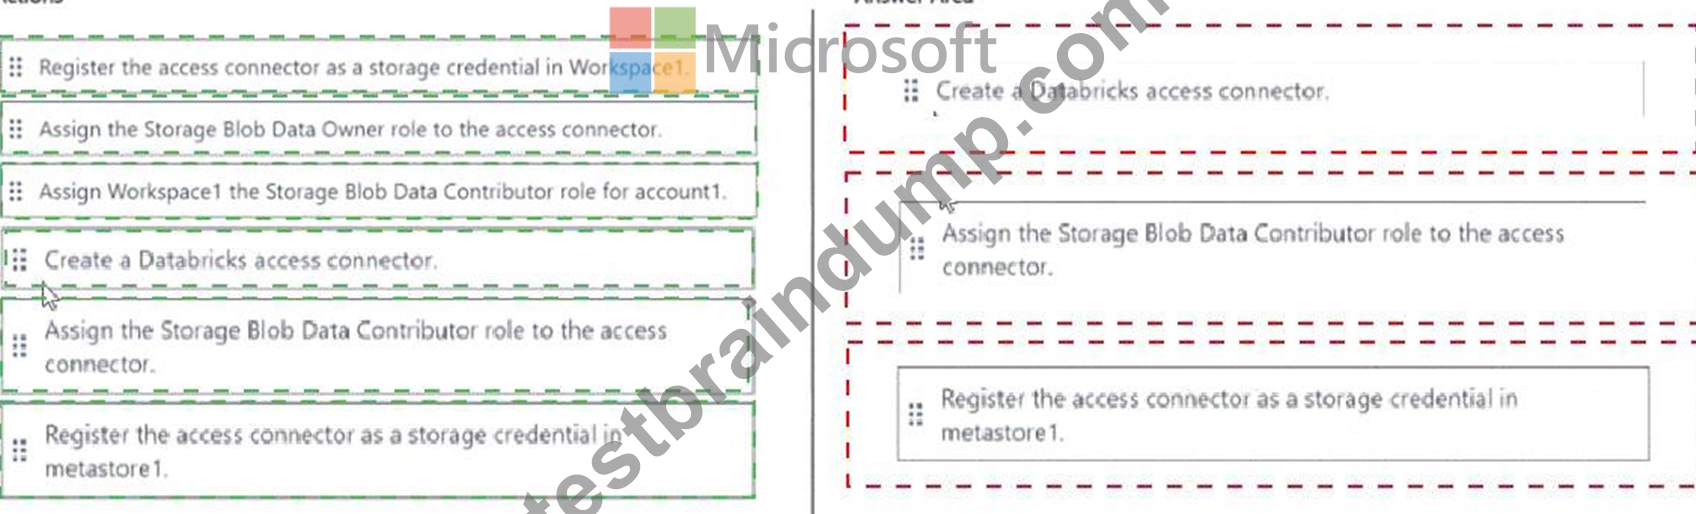
Explanation:
Registering an ADLS Gen2 account as an external location in Unity Catalog requires three steps in a specific order:
Step 1: Create a Databricks Access Connector. This Azure resource wraps a system-assigned or user-assigned managed identity. It is the credential-less authentication bridge between Databricks and Azure Storage - no SAS tokens or access keys are stored anywhere in the workspace.
Step 2: Create a Storage Credential in Unity Catalog that references the Access Connector. This object tells Unity Catalog 'use this identity when accessing storage.' The Storage Credential is the reusable authentication object.
Step 3: Create an External Location that maps a Unity Catalog path to the specific ADLS Gen2 container using the Storage Credential. This is the object that grants Databricks users access to files under that path, and it respects the principle of least privilege by scoping access to a specific container.
Reference: https://learn.microsoft.com/en-us/azure/databricks/connect/unity-catalog/storage-credentials
NEW QUESTION # 54
You have an Azure Databricks workspace named Workspace1 that contains a takehouse and is enabled for Unity Catalog.
You have a connection to a Microsoft SQL Server database named DB1.
You need to expose the schemas and tables of DB1 to meet the following requirements:
* The schemas and tables can be queried in Databricks.
* The schemas and tables appear alongside other Unity Catalog objects.
* The data is NOT copied into Databricks-managed storage.
Solution: You create a new native catalog in Unity Catalog. Does this meet the goal?
Answer: A
Explanation:
The correct answer is B - No.
A native catalog in Unity Catalog is a standard Databricks-managed catalog. Creating one provisions a metadata namespace inside Unity Catalog, but it has no connection whatsoever to DB1 or any external SQL Server database. There is no mechanism to point a native catalog at an external database - it simply doesn't serve that purpose.
The requirement is to expose an external SQL Server's schemas and tables inside Unity Catalog without copying the data. That requires a foreign catalog, which is created through Lakehouse Federation using a registered connection to the external database. A foreign catalog acts as a read-only, virtual mirror of the external database - queries run against the live external data in place.
Creating a native catalog and then trying to manually recreate DB1's structure inside it would involve copying all the data, violating the 'data is NOT copied' requirement.
Reference: https://learn.microsoft.com/en-us/azure/databricks/query-federation/lakehouse-federation
NEW QUESTION # 55
......
The experts in our company have been focusing on the DP-750 examination for a long time and they never overlook any new knowledge. The content of our DP-750 study materials has always been kept up to date. Don't worry if any new information comes out after your purchase of our DP-750 Study Guide. We will inform you by E-mail when we have a new version. We can ensure you a pass rate as high as 99%. If you don't pass the DP-750 exam, you will get a refund. Why not study and practice for just 20 to 30 hours and then pass the examination?
DP-750 Top Questions: https://www.testbraindump.com/DP-750-exam-prep.html