P.S. Free & New Data-Engineer-Associate dumps are available on Google Drive shared by ExamDiscuss: https://drive.google.com/open?id=1dt1-vGEsuLZlEmtD-3cmJL6Xtqc38g1c
The Amazon Data-Engineer-Associate certification exam is not only validate your skills but also prove your expertise. It can prove to your boss that he did not hire you in vain. The current IT industry needs a reliable source of Amazon Data-Engineer-Associate Certification Exam, ExamDiscuss is a good choice. Select ExamDiscuss Data-Engineer-Associate exam material, so that you do not need yo waste your money and effort. And it will also allow you to have a better future.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Ingestion and Transformation | 34% | - Ingest and transform data using AWS services - Build and manage data pipelines |
| Topic 2: Data Store Management | 26% | - Optimize storage performance and cost - Select appropriate data storage solutions |
| Topic 3: Data Operations and Support | 22% | - Monitor and maintain data pipelines - Troubleshoot data workflow issues |
| Topic 4: Data Security and Governance | 18% | - Apply governance and compliance best practices - Implement data security controls |
>> Real Data-Engineer-Associate Testing Environment <<
Up to now, we have business connection with tens of thousands of exam candidates who adore the quality of our Data-Engineer-Associate exam questions. Besides, we try to keep our services brief, specific and courteous with reasonable prices of Data-Engineer-Associate Study Guide. All your questions will be treated and answered fully and promptly. So as long as you contact us to ask for the questions on the Data-Engineer-Associate learning guide, you will get the guidance immediately.
NEW QUESTION # 167
A gaming company uses Amazon Kinesis Data Streams to collect clickstream data. The company uses Amazon Kinesis Data Firehose delivery streams to store the data in JSON format in Amazon S3. Data scientists at the company use Amazon Athena to query the most recent data to obtain business insights.
The company wants to reduce Athena costs but does not want to recreate the data pipeline.
Which solution will meet these requirements with the LEAST management effort?
Answer: C
Explanation:
Step 1: Understanding the Problem
The company collectsclickstream datavia Amazon Kinesis Data Streams and stores it inJSON formatin Amazon S3 using Kinesis Data Firehose. They useAmazon Athenato query the data, but they want toreduce Athena costswhile maintaining the same data pipeline.
Since Athena charges based on the amount of data scanned during queries, reducing the data size (by converting JSON to a more efficient format likeApache Parquet) is a key solution to lowering costs.
Step 2: Why Option A is Correct
* Option Aprovides a straightforward way to reduce costs withminimal management overhead:
* Changing the Firehose output format to Parquet: Parquet is a columnar data format, which is more compact and efficient than JSON for Athena queries. It significantly reduces the amount of data scanned, which in turn reduces Athena query costs.
* Custom S3 Object Prefix (YYYYMMDD): Adding a date-based prefix helps in partitioning the data, which further improves query efficiency in Athena by limiting the data scanned to only relevant partitions.
* AWS Glue ETL Job for Existing Data: To handle existing data stored in JSON format, a one- time AWS Glue ETL job can combine small JSON files, convert them to Parquet, and apply the YYYYMMDD prefix. This ensures consistency in the S3 bucket structure and allows Athena to efficiently query historical data.
* ALTER TABLE ADD PARTITION: This command updates Athena's table metadata to reflect the new partitions, ensuring that future queries target only the required data.
Step 3: Why Other Options Are Not Ideal
* Option B (Apache Spark on EMR)introduces higher management effort by requiring the setup of Apache Spark jobsand anAmazon EMR cluster. While it achieves the goal of converting JSON to Parquet, it involves running and maintaining an EMR cluster, which adds operational complexity.
* Option C (Kinesis and Apache Flink)is a more complex solution involvingApache Flink, which adds a real-time streaming layer to aggregate data. Although Flink is a powerful tool for stream processing, it adds unnecessary overhead in this scenario since the company already uses Kinesis Data Firehose for batch delivery to S3.
* Option D (AWS Lambda with Firehose)suggests usingAWS Lambdato convert records in real time.
While Lambda can work in some cases, it's generally not the best tool for handling large-scale data transformations like JSON-to-Parquet conversion due to potential scaling and invocation limitations.
Additionally, running parallel Glue jobs further complicates the setup.
Step 4: How Option A Minimizes Costs
* By usingApache Parquet, Athena queries become more efficient, as Athena will scan significantly less data, directly reducing query costs.
* Firehosenatively supports Parquet as an output format, so enabling this conversion in Firehose requires minimal effort. Once set, new data will automatically be stored in Parquet format in S3, without requiring any custom coding or ongoing management.
* TheAWS Glue ETL jobfor historical data ensures that existing JSON files are also converted to Parquet format, ensuring consistency across the data stored in S3.
Conclusion:
Option A meets the requirement toreduce Athena costswithout recreating the data pipeline, using Firehose's native support forApache Parquetand a simple one-timeAWS Glue ETL jobfor existing data. This approach involvesminimal management effortcompared to the other solutions.
NEW QUESTION # 168
A data engineer needs to create an Amazon Athena table based on a subset of data from an existing Athena table named cities_world. The cities_world table contains cities that are located around the world. The data engineer must create a new table named cities_us to contain only the cities from cities_world that are located in the US.
Which SQL statement should the data engineer use to meet this requirement?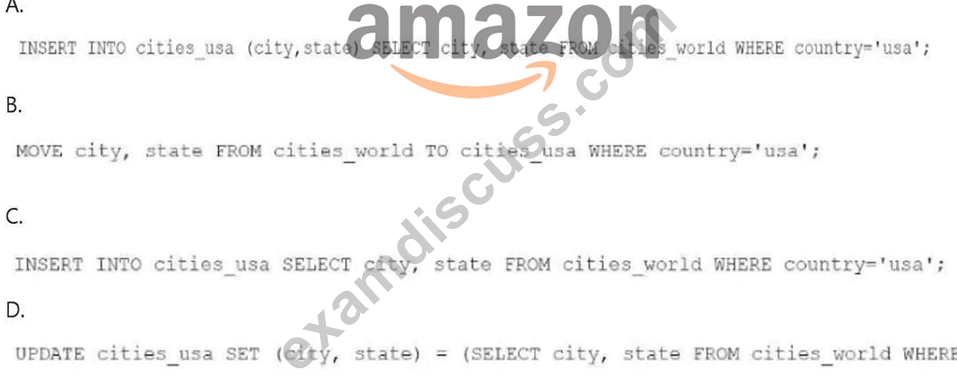
Answer: C
Explanation:
To create a new table named cities_usa in Amazon Athena based on a subset of data from the existing cities_world table, you should use an INSERT INTO statement combined with a SELECT statement to filter only the records where the country is 'usa'. The correct SQL syntax would be:
Option A: INSERT INTO cities_usa (city, state) SELECT city, state FROM cities_world WHERE country='usa';This statement inserts only the cities and states where the country column has a value of 'usa' from the cities_world table into the cities_usa table. This is a correct approach to create a new table with data filtered from an existing table in Athena.
Options B, C, and D are incorrect due to syntax errors or incorrect SQL usage (e.g., the MOVE command or the use of UPDATE in a non-relevant context).
References:
Amazon Athena SQL Reference
Creating Tables in Athena
NEW QUESTION # 169
A company uses a variety of AWS and third-party data stores. The company wants to consolidate all the data into a central data warehouse to perform analytics. Users need fast response times for analytics queries.
The company uses Amazon QuickSight in direct query mode to visualize the data. Users normally run queries during a few hours each day with unpredictable spikes.
Which solution will meet these requirements with the LEAST operational overhead?
Answer: C
Explanation:
Problem Analysis:
The company requires a centralized data warehouse for consolidating data from various sources.
They use Amazon QuickSight in direct query mode, necessitating fast response times for analytical queries.
Users query the data intermittently, with unpredictable spikes during the day.
Operational overhead should be minimal.
Key Considerations:
The solution must support fast, SQL-based analytics.
It must handle unpredictable spikes efficiently.
Must integrate seamlessly with QuickSight for direct querying.
Minimize operational complexity and scaling concerns.
Solution Analysis:
Option A: Amazon Redshift Serverless
Redshift Serverless eliminates the need for provisioning and managing clusters.
Automatically scales compute capacity up or down based on query demand.
Reduces operational overhead by handling performance optimization.
Fully integrates with Amazon QuickSight, ensuring low-latency analytics.
Reduces costs as it charges only for usage, making it ideal for workloads with intermittent spikes.
Option B: Amazon Athena with S3 (Apache Parquet)
Athena supports querying data directly from S3 in Parquet format.
While it's cost-effective, performance depends on the size and complexity of the data.
It is not optimized for high-speed analytics needed by QuickSight in direct query mode.
Option C: Amazon Redshift Provisioned Clusters
Requires manual cluster provisioning, scaling, and maintenance.
Higher operational overhead compared to Redshift Serverless.
Option D: Amazon Aurora PostgreSQL
Aurora is optimized for transactional databases, not data warehousing or analytics.
Does not meet the requirement for fast analytics queries.
Final Recommendation:
Amazon Redshift Serverless is the best choice for this use case because it provides fast analytics, integrates natively with QuickSight, and minimizes operational complexity while efficiently handling unpredictable spikes.
Amazon Redshift Serverless Overview
Amazon QuickSight and Redshift Integration
Athena vs. Redshift
NEW QUESTION # 170
A manufacturing company uses AWS Glue jobs to process IoT sensor data to generate predictive maintenance models. A data engineer needs to implement automated data quality checks to identify temperature readings that are outside the expected range of -50°C to 150°C. The data quality checks must also identify records that are missing timestamp values.
The data engineer needs a solution that requires minimal coding and can automatically flag the specified issues.
Which solution will meet these requirements?
Answer: C
Explanation:
AWS Glue DataBrew provides a no-code data preparation and validation interface. It allows you to set data profiling, completeness checks, and numeric range validations directly through its UI-ideal for IoT validation use cases.
"AWS Glue DataBrew enables users to define validation rules such as completeness and value range checks without writing code."
- Ace the AWS Certified Data Engineer - Associate Certification - version 2 - apple.pdf This fulfills the requirement for minimal coding and automatic data quality flagging.
NEW QUESTION # 171
A company is migrating its database servers from Amazon EC2 instances that run Microsoft SQL Server to Amazon RDS for Microsoft SQL Server DB instances. The company's analytics team must export large data elements every day until the migration is complete. The data elements are the result of SQL joins across multiple tables. The data must be in Apache Parquet format. The analytics team must store the data in Amazon S3.
Which solution will meet these requirements in the MOST operationally efficient way?
Answer: D
Explanation:
Option A is the most operationally efficient way to meet the requirements because it minimizes the number of steps and services involved in the data export process. AWS Glue is a fully managed service that can extract, transform, and load (ETL) data from various sources to various destinations, including Amazon S3. AWS Glue can also convert data to different formats, such as Parquet, which is a columnar storage format that is optimized for analytics. By creating a view in the SQL Server databases that contains the required data elements, the AWS Glue job can select the data directly from the view without having to perform any joins or transformations on the source data. The AWS Glue job can then transfer the data in Parquet format to an S3 bucket and run on a daily schedule.
Option B is not operationally efficient because it involves multiple steps and services to export the data. SQL Server Agent is a tool that can run scheduled tasks on SQL Server databases, such as executing SQL queries. However, SQL Server Agent cannot directly export data to S3, so the query output must be saved as .csv objects on the EC2 instance. Then, an S3 event must be configured to trigger an AWS Lambda function that can transform the .csv objects to Parquet format and upload them to S3. This option adds complexity and latency to the data export process and requires additional resources and configuration.
Option C is not operationally efficient because it introduces an unnecessary step of running an AWS Glue crawler to read the view. An AWS Glue crawler is a service that can scan data sources and create metadata tables in the AWS Glue Data Catalog. The Data Catalog is a central repository that stores information about the data sources, such as schema, format, and location. However, in this scenario, the schema and format of the data elements are already known and fixed, so there is no need to run a crawler to discover them. The AWS Glue job can directly select the data from the view without using the Data Catalog. Running a crawler adds extra time and cost to the data export process.
Option D is not operationally efficient because it requires custom code and configuration to query the databases and transform the data. An AWS Lambda function is a service that can run code in response to events or triggers, such as Amazon EventBridge. Amazon EventBridge is a service that can connect applications and services with event sources, such as schedules, and route them to targets, such as Lambda functions. However, in this scenario, using a Lambda function to query the databases and transform the data is not the best option because it requires writing and maintaining code that uses JDBC to connect to the SQL Server databases, retrieve the required data, convert the data to Parquet format, and transfer the data to S3. This option also has limitations on the execution time, memory, and concurrency of the Lambda function, which may affect the performance and reliability of the data export process.
Reference:
AWS Certified Data Engineer - Associate DEA-C01 Complete Study Guide
AWS Glue Documentation
Working with Views in AWS Glue
Converting to Columnar Formats
NEW QUESTION # 172
......
With the complete collection of Amazon practice questions and answers, our website offers you the most reliable Data-Engineer-Associate vce files for your exam preparation. In the Data-Engineer-Associate actual test we have compiled real questions and answers so that you can prepare and pas exam in your first attempt. You can also check the demo of Data-Engineer-Associate Dumps PDF before you decide to buy it.
Latest Data-Engineer-Associate Learning Materials: https://www.examdiscuss.com/Amazon/exam/Data-Engineer-Associate/
BTW, DOWNLOAD part of ExamDiscuss Data-Engineer-Associate dumps from Cloud Storage: https://drive.google.com/open?id=1dt1-vGEsuLZlEmtD-3cmJL6Xtqc38g1c