You can use this Microsoft AI-200 version on any operating system, and this software is accessible through any browser like Opera, Safari, Chrome, Firefox, and IE. You can easily assess yourself with the help of our AI-200 practice software, as it records all your previous results for future use.
| Section | Objectives |
|---|---|
| Secure, monitor, troubleshoot Azure solutions | - Operate AI cloud solutions
|
| Connect to and consume Azure services | - Integrate Azure services
|
| Develop containerized solutions on Azure | - Implement containerized applications
|
| Develop AI solutions by using Azure data management services | - Work with Azure data platforms for AI workloads
|
Our website are specialized in offering customers with reliable Microsoft braindumps and study guide, which written by a team of IT experts and certified trainers who enjoy great reputation in the IT field. All AI-200 Test Questions are created based on the real test and followed by valid test answers and explanations. We guarantee you get high passing score with our AI-200 exam prep.
NEW QUESTION # 41
You are implementing the expiration requirement for AI-generated summaries in the Redis cache.
You need to purge the AI summaries five minutes after creation, regardless of how often they are accessed.
What should you do?
Answer: A
Explanation:
Configure a fixed expiration timeout on each Redis key when the summary is created , such as a five- minute TTL. Azure Managed Redis automatically removes a key when its configured timeout expires.
Critically, ordinary read operations do not extend that expiration period, so a summary created at time T will expire approximately five minutes later regardless of how frequently clients retrieve it.
This is the required absolute-expiration behavior. In Redis, applications can establish expiration when writing the value or by using expiration commands after creation. The important design property is that the expiration deadline is not refreshed whenever the key is read.
An allkeys-lru eviction policy addresses memory pressure , not deterministic five-minute expiration. It may evict less recently used keys when memory is constrained, but it does not guarantee removal exactly five minutes after creation. The PERSIST command is directly incorrect because it removes an existing timeout , potentially causing the summary to remain indefinitely. Sliding expiration is also unsuitable because it renews or resets the expiration window based on activity, allowing frequently accessed summaries to remain longer than five minutes.
Therefore, a per-key absolute five-minute expiration is the correct configuration.
Study Guide references: Azure Managed Redis # key expiration; TTL behavior; cache expiration versus eviction; fixed versus sliding expiration.
NEW QUESTION # 42
Case Study 2 - Proseware Inc.
Background
Proseware Inc. develops AI-powered knowledge management solutions for enterprise customers.
The company is modernizing its platform to support semantic search, intelligent document retrieval, and real-time partner integrations.
The engineering team uses Python and Azure SDKs. The architecture is being redesigned to support containerized microservices, vector search workloads, and serverless backend processing.
Planned Application Architecture
Microservices are containerized by using Docker.
Code for containerized microservices and Azure Function apps is developed locally but stored in a GitHub repository.
Custom images for containerized microservices are stored in Azure Container Registry (ACR).
Base images are stored in Docker Hub. Custom images must be rebuilt automatically whenever their base images are updated.
Azure Cosmos DB for NoSQL stores documents, metadata, and vector embeddings.
Azure Functions generate vector embeddings of Azure Cosmos DB for NoSQL-hosted documents and send messages to Service Bus to trigger search index updates.
Azure Container Apps (ACA) apps host backend API services that provide semantic search across Azure Cosmos DB for NoSQL documents. API services process Service Bus messages and update search indexes.
Azure Kubernetes Service (AKS) processes batch vector embedding regeneration for existing Azure Cosmos DB for NoSQL documents (whenever the embedding model is changed).
An extranet-facing containerized webhook allows business partners to submit documents to be processed by internal AI workflows for semantic search and retrieval.
Monitoring
Telemetry generated by Azure resources is sent to Azure Monitor.
A Log Analytics workspace is used to collect ACA apps logs, AKS container logs, and Azure Functions apps logs.
Monitoring of Azure Functions is currently implemented by using Azure Application Insights SDK instrumentation.
Business Requirements
Embeddings for new or updated Azure Cosmos DB for NoSQL-hosted documents must be automatically generated.
Backend API services must scale automatically during business hours.
Cold start delay of backend APIs must be minimized.
Secrets must be stored outside of container images.
Developers must be able to correlate telemetry across Azure Functions hosts and apps.
All tracing must be implemented by using OpenTelemetry SDK instrumentation.
Development efforts must be minimized.
Technical Requirements
Container images must be built automatically and validated before code updates are merged into the main branch.
Image build automation must run inside the Azure Container Registry, eliminating dependency on local developer machines and external build services.
Dependency of image builds on local developer machines must be eliminated.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Azure Cosmos DB for NoSQL RU consumption must be minimized.
Vector similarity search must use embeddings stored in Azure Cosmos DB for NoSQL.
The partner-facing containerized webhook service must run on Azure App Service.
Secrets must NOT be stored in container images, source control, or application configuration directly. They must be accessed securely at runtime.
All secrets must be stored centrally in Azure Key Vault and accessed at runtime through a managed identity.
Azure App Service must supply secrets at runtime without relying on external services.
Resources and workloads must be deployed by using Bicep templates through an automated, version-controlled pipeline. Local and command-line deployments must be eliminated to ensure repeatable, auditable deployments.
Known Issues
RU consumption spikes during vector similarity queries.
Hotspot Question
You need to configure image build automation based on the technical requirements.
Which settings should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.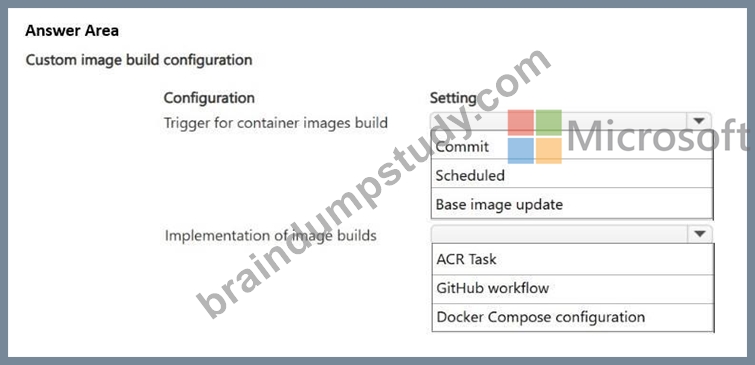
Answer:
Explanation: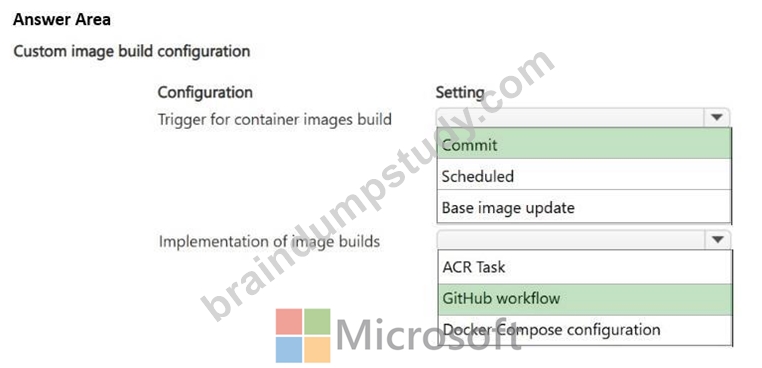
Explanation:
Scenario, Technical Requirements
Container images must be built automatically and validated before code updates are merged into the main branch.
Image build automation must run inside the Azure Container Registry, eliminating dependency on local developer machines and external build services.
Dependency of image builds on local developer machines must be eliminated.
Box 1: Commit
Use a Commit trigger for this configuration
Immediate Validation: Builds continuous integration (CI) pipelines automatically when a developer submits a pull request or pushes code.
Gatekeeper Function: Prevents unvalidated code or broken container images from merging into your main branch.
Workflow Alignment: Supports microservices development by isolating tests to the specific code updates being introduced.
Box 2: GitHub workflow
To implement automatic image builds and validation before code updates are merged into the main branch, you should use a GitHub workflow.
Branch gating: GitHub Actions can trigger specifically on pull_request events targeting the main branch, allowing you to validate code and builds before merging.
Automation control: It orchestrates the entire continuous integration (CI) pipeline, including linting, running unit tests, building Docker images, and scanning them for vulnerabilities.
Integration capacity: It can seamlessly hand off the successfully validated image to Azure Container Registry (ACR) or utilize ACR Tasks under the hood as part of the pipeline steps.
Reference:
https://docs.github.com/en/actions/tutorials/publish-packages/publish-docker-images
NEW QUESTION # 43
You deploy multiple instances of a change feed processor to handle a high ingestion rate within Azure Cosmos DB for NoSQL.
Each processor instance must process a different subset of partitions.
You need to ensure the workload is load-balanced across all processor instances.
What should you configure?
Answer: A
Explanation:
The lease container is the Azure Cosmos DB component that coordinates change feed processing across multiple processor instances. Microsoft defines the lease container as the state store used by the change feed processor to track progress and coordinate ownership of partition ranges among workers. Each lease corresponds to a portion of the change feed workload, and at any given time a lease is owned by one processor instance.
When several change feed processor instances use the same lease container and the same processor name while maintaining unique instance names, the processor distributes leases across the active instances by using an equal-distribution algorithm. If instances are added or removed, the processor dynamically redistributes leases, which provides automatic workload balancing and parallelism. This is exactly what is required when ingestion volume is high and each instance must process a distinct subset of partition ranges.
Indexing precision affects query indexing behavior, not change feed coordination. Strong consistency controls read consistency semantics and does not assign partitions to processors. Autoscale throughput can increase database RU/s capacity, but it does not coordinate which processor instance owns which change feed partition range.
Study Guide references: Azure Cosmos DB for NoSQL # Change Feed Processor; lease container; parallel processing; dynamic scaling and load balancing.
NEW QUESTION # 44
You need to implement the semantic retrieval workflow for the recommendation engine to meet the technical and performance requirements of Fabrikam Inc.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.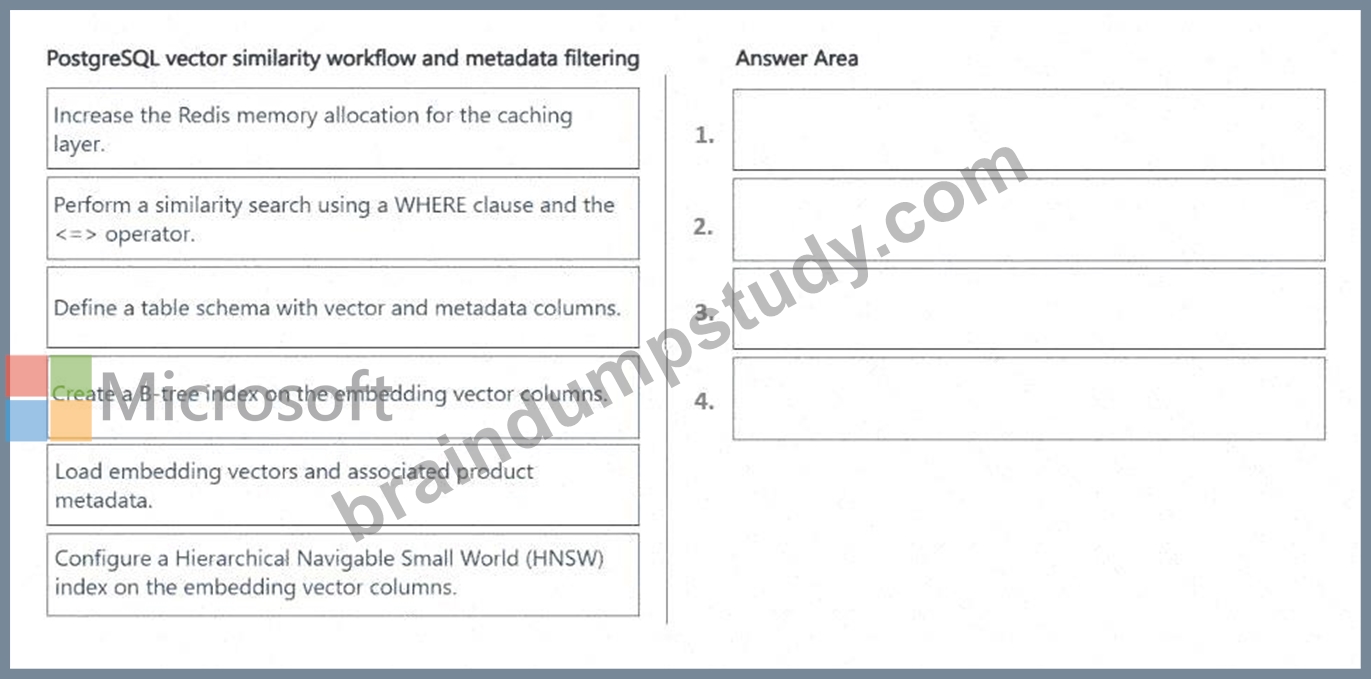
Answer:
Explanation: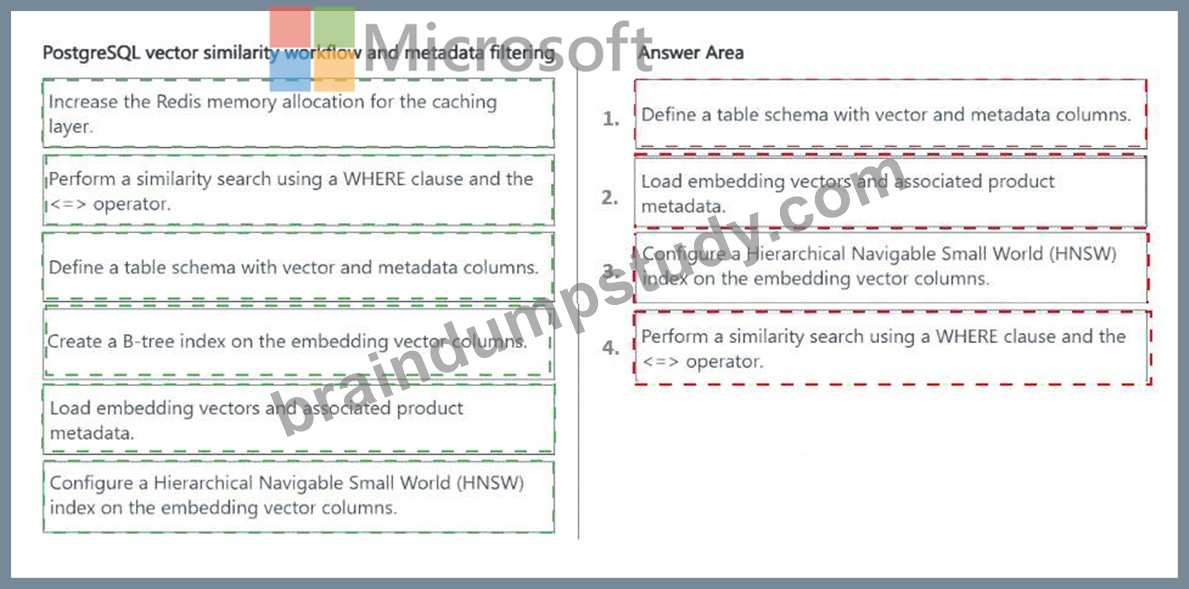
Explanation:
* Define a table schema with vector and metadata columns.
* Load embedding vectors and associated product metadata.
* Configure a Hierarchical Navigable Small World (HNSW) index on the embedding vector columns.
* Perform a similarity search using a WHERE clause and the < = > operator.
The workflow must first establish a PostgreSQL schema containing both the pgvector embedding column and the product metadata required for filtering. The embeddings and their associated metadata are then bulk- loaded. This ordering is important because Microsoft recommends loading data before creating vector indexes ; creating the index afterward provides faster ingestion and a more optimal index layout.
After loading, configure an HNSW index on the embedding column. HNSW is an approximate-nearest- neighbor index supported by pgvector and provides a strong speed/recall tradeoff for low-latency vector retrieval. Microsoft specifically documents HNSW for efficient cosine-distance searches in Azure Database for PostgreSQL.
Finally, execute the retrieval query so that mandatory product metadata constraints are applied through a WHERE clause , while vector similarity is evaluated with the < = > cosine-distance operator . This satisfies Fabrikam ' s requirement to calculate similarity only for eligible products.
A B-tree index is not an ANN vector index, and increasing Redis memory does not implement PostgreSQL semantic retrieval.
Study Guide references: Azure Database for PostgreSQL # pgvector, HNSW indexing, bulk-load optimization, vector similarity operators, metadata-filtered retrieval.
NEW QUESTION # 45
You are creating an Azure Functions app project in your local development environment by using Azure Functions Core Tools.
You must create the project in either Python or C# without using a template.
You need to specify the command and its parameter required to create the Azure Functions app project.
Which command and parameter should you specify? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.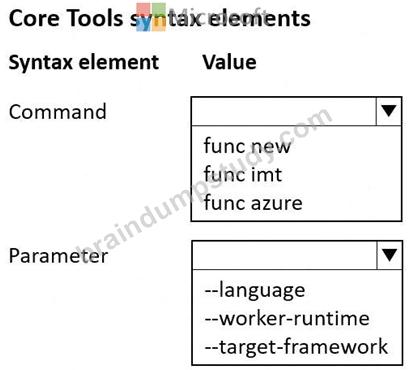
Answer:
Explanation: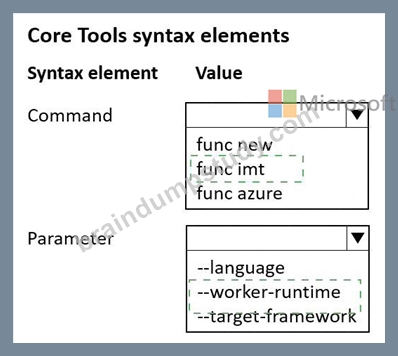
Explanation:
* Command: func init
* Parameter: --worker-runtime
Use func init to initialize a new Azure Functions project. Microsoft documents func init as the Azure Functions Core Tools command that creates the project structure in either the current directory or a specified project folder. The command is specifically intended for creating a new Functions application project, whereas func new creates an individual function from a template inside an already initialized project.
The --worker-runtime parameter specifies the language/runtime model for the Functions project. For example, Microsoft documents func init --worker-runtime python for Python projects and func init --worker- runtime dotnet-isolated for modern C#/.NET isolated-worker projects.
--language is not the primary parameter used to establish the Functions worker runtime in this scenario. It can be relevant to certain runtime combinations, such as Node.js, but the Core Tools project initialization examples for Python and C# rely on --worker-runtime. --target-framework is used to select a specific .NET target framework after the worker/runtime model is determined; it does not identify whether the project should be Python or C#.
Therefore, the correct combination is func init + --worker-runtime .
Study Guide references: Azure Functions Core Tools # func init; local Functions project creation; --worker- runtime; Python and .NET isolated worker projects.
NEW QUESTION # 46
......
Maybe on other web sites or books, you can also see the related training materials. But as long as you compare BraindumpStudy's product with theirs, you will find that our product has a broader coverage of the certification exam's outline. You can free download part of exam practice questions and answers about Microsoft certification AI-200 exam from BraindumpStudy website as a try to detect the quality of our products. Why BraindumpStudy can provide the comprehensive and high-quality information uniquely? Because we have a professional team of IT experts. They continue to use their IT knowledge and rich experience to study the previous years exams of Microsoft AI-200 and have developed practice questions and answers about Microsoft AI-200 exam certification exam. So BraindumpStudy's newest exam practice questions and answers about Microsoft certification AI-200 exam are so popular among the candidates participating in the Microsoft certification AI-200 exam.
AI-200 Pdf Format: https://www.braindumpstudy.com/AI-200_braindumps.html