
BTW, DOWNLOAD part of VCE4Dumps MLA-C01 dumps from Cloud Storage: https://drive.google.com/open?id=11K-njCGK-EKb2D8A5oRm_o09zKRrRJkj
You do not require an active internet connection after installation of the Amazon MLA-C01 practice exam software. Repetitive attempts of Amazon MLA-C01 exam dumps boosts confidence and provide familiarity with the MLA-C01 Actual Exam format. A free demo version is also available for satisfaction. This MLA-C01 software provides a real AWS Certified Machine Learning Engineer - Associate (MLA-C01) exam environment to help ease exam anxiety.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
>> MLA-C01 Valid Test Online <<
With passing rate more than 98 percent from exam candidates who chose our Amazon MLA-C01 Study Guide, we have full confidence that your MLA-C01 actual test will be a piece of cake by them. Our AWS Certified Machine Learning Engineer - Associate exam questions provide with the software which has a variety of self-study and self-assessment functions to detect learning results.
NEW QUESTION # 94
A company receives daily .csv files about customer interactions with its ML model. The company stores the files in Amazon S3 and uses the files to retrain the model. An ML engineer needs to implement a solution to mask credit card numbers in the files before the model is retrained.
Which solution will meet this requirement with the LEAST development effort?
Answer: D
NEW QUESTION # 95
An ML engineer needs to use Amazon SageMaker Feature Store to create and manage features to train a model.
Select and order the steps from the following list to create and use the features in Feature Store. Each step should be selected one time. (Select and order three.)
* Access the store to build datasets for training.
* Create a feature group.
* Ingest the records.
Answer:
Explanation: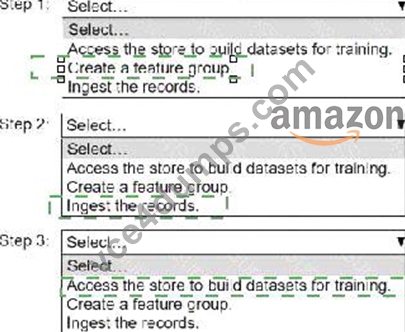
Explanation: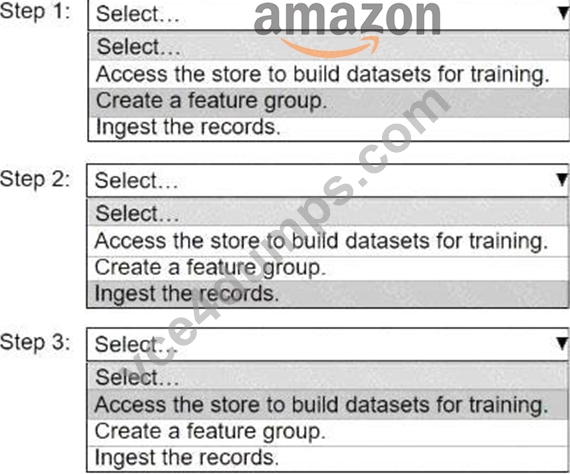
Step 1: Create a feature group.Step 2: Ingest the records.Step 3: Access the store to build datasets for training.
* Step 1: Create a Feature Group
* Why?A feature group is the foundational unit in SageMaker Feature Store, where features are defined, stored, and organized. Creating a feature group specifies the schema (name, data type) for the features and the primary keys for data identification.
* How?Use the SageMaker Python SDK or AWS CLI to define the feature group by specifying its name, schema, and S3 storage location for offline access.
* Step 2: Ingest the Records
* Why?After creating the feature group, the raw data must be ingested into the Feature Store. This step populates the feature group with data, making it available for both real-time and offline use.
* How?Use the SageMaker SDK or AWS CLI to batch-ingest historical data or stream new records into the feature group. Ensure the records conform to the feature group schema.
* Step 3: Access the Store to Build Datasets for Training
* Why?Once the features are stored, they can be accessed to create training datasets. These datasets combine relevant features into a single format for machine learning model training.
* How?Use the SageMaker Python SDK to query the offline store or retrieve real-time features using the online store API. The offline store is typically used for batch training, while the online store is used for inference.
Order Summary:
* Create a feature group.
* Ingest the records.
* Access the store to build datasets for training.
This process ensures the features are properly managed, ingested, and accessible for model training using Amazon SageMaker Feature Store.
NEW QUESTION # 96
An ML engineer is training a simple neural network model. The ML engineer tracks the performance of the model over time on a validation dataset. The model's performance improves substantially at first and then degrades after a specific number of epochs.
Which solutions will mitigate this problem? (Choose two.)
Answer: A,D
Explanation:
Early stopping halts training once the performance on the validation dataset stops improving. This prevents the model from overfitting, which is likely the cause of performance degradation after a certain number of epochs.
Dropout is a regularization technique that randomly deactivates neurons during training, reducing overfitting by forcing the model to generalize better. Increasing dropout can help mitigate the problem of performance degradation due to overfitting.
NEW QUESTION # 97
An ML engineer needs to use an ML model to predict the price of apartments in a specific location.
Which metric should the ML engineer use to evaluate the model's performance?
Answer: D
Explanation:
Predicting apartment prices is a regression problem, where the target variable is continuous. AWS documentation states that classification metrics such as accuracy, AUC, and F1 score are not appropriate for regression tasks.
Mean Absolute Error (MAE) measures the average absolute difference between predicted values and actual values. MAE is easy to interpret because it is expressed in the same units as the target variable (for example, dollars), making it especially useful for business-facing problems like price prediction.
AWS best practices recommend MAE for evaluating regression models when understanding average prediction error magnitude is important and when robustness to outliers is desired.
Therefore, Option D is the correct and AWS-aligned answer.
NEW QUESTION # 98
A company is developing ML models by using PyTorch and TensorFlow estimators with Amazon SageMaker AI. An ML engineer configures the SageMaker AI estimator and now needs to initiate a training job that uses a training dataset.
Which SageMaker AI SDK method can initiate the training job?
Answer: A
Explanation:
In the Amazon SageMaker Python SDK, the fit() method is used to start a training job after an estimator has been configured. AWS documentation explicitly states that once an estimator (such as PyTorch or TensorFlow) is defined with parameters like instance type, framework version, and hyperparameters, the fit() method is responsible for launching the training process.
The fit() method accepts the training data location (commonly an Amazon S3 URI) and initiates the managed training job on SageMaker infrastructure. SageMaker then provisions the required compute resources, stages the data, executes the training script, and stores model artifacts in Amazon S3.
The create_model() method is used after training to create a SageMaker model object from trained artifacts.
The deploy() method deploys a trained model to an endpoint for inference. The predict() method is used only after deployment to request predictions from an endpoint.
AWS documentation clearly separates these lifecycle steps and identifies fit() as the correct method to initiate training.
Therefore, Option A is the correct and AWS-verified answer.
NEW QUESTION # 99
......
To get respected jobs in tech companies around the globe, hundreds of people take the Amazon certification exam every year. Once they clear Amazon MLA-C01 Exam, they easily get jobs and promotions. Hundreds of applicants who appear in the Amazon MLA-C01 Exam don't get a passing score. The major reason behind their failure in the Amazon MLA-C01 Exam is studying the material which is not the latest. So, to save your resources, you must prepare with Amazon MLA-C01 Dumps which has real and updated exam material.
Exam MLA-C01 Pattern: https://www.vce4dumps.com/MLA-C01-valid-torrent.html
What's more, part of that VCE4Dumps MLA-C01 dumps now are free: https://drive.google.com/open?id=11K-njCGK-EKb2D8A5oRm_o09zKRrRJkj