Microsoft AI-901덤프최신문제 & AI-901완벽한시험덤프공부

ExamPassdump에서 판매하고 있는 Microsoft AI-901인증시험자료는 시중에서 가장 최신버전으로서 시험적중율이 100%에 가깝습니다. Microsoft AI-901덤프자료를 항상 최신버전으로 보장해드리기 위해Microsoft AI-901시험문제가 변경되면 덤프자료를 업데이트하도록 최선을 다하고 있습니다. ExamPassdump는 여러분이 자격증을 취득하는 길에서 없어서는 안되는 동반자로 되어드릴것을 약속해드립니다.
Microsoft AI-901 Exam Overview:
| Certification Vendor: | Microsoft |
|---|
| Exam Name: | Microsoft Azure AI Fundamentals (AI-900) Exam |
|---|
| Exam Number: | AI-900 |
|---|
| Certificate Validity Period: | Does not expire (Fundamentals certification) |
|---|
| Related Certifications: | Microsoft Azure Data Fundamentals (DP-900)
Microsoft Azure Fundamentals (AZ-900) |
|---|
| Passing Score: | 700 (out of 1000) |
|---|
| Exam Format: | Multiple choice, Drag and drop, Multiple response, Case study (limited) |
|---|
| Available Languages: | Chinese (Simplified), Spanish, Portuguese (Brazil), Chinese (Traditional), Japanese, German, English, French, Korean |
|---|
| Exam Duration: | 60 minutes |
|---|
| Real Exam Qty: | 40-60 |
|---|
| Exam Price: | Approx. 99 USD (varies by region) |
|---|
| Recommended Training: | Microsoft Learn - AI-900 Learning Path
Azure AI Fundamentals Course |
|---|
| Exam Registration: | Schedule exam via Pearson VUE
Microsoft Certification Portal |
|---|
| Sample Questions: | Microsoft AI-901 Sample Questions |
|---|
| Exam Way: | Online proctored exam or in-person test center |
|---|
| Pre Condition: | No formal prerequisites required. Basic understanding of cloud computing and AI concepts is recommended. |
|---|
| Official Syllabus URL: | https://learn.microsoft.com/en-us/credentials/certifications/azure-ai-fundamentals/ |
|---|
>> Microsoft AI-901덤프최신문제 <<
최신 AI-901덤프최신문제 시험대비 공부자료
국제공인자격증을 취득하여 IT업계에서 자신만의 자리를 잡고 싶으신가요? 자격증이 수없이 많은데Microsoft AI-901 시험패스부터 시작해보실가요? 100%합격가능한 Microsoft AI-901덤프는Microsoft AI-901시험문제의 기출문제와 예상문제로 되어있는 퍼펙트한 모음문제집으로서 시험패스율이 100%에 가깝습니다.
Microsoft AI-901 시험요강:
| 주제 | 소개 |
|---|
| 주제 1 | - Identify AI concepts and capabilities: This domain covers the foundational knowledge of AI from ethical principles and responsible design to understanding how AI models work and what kinds of tasks they can perform. It also explores the full range of AI workloads including generative AI, computer vision, speech, and information extraction.
|
| 주제 2 | - Implement AI solutions by using Microsoft Foundry: This domain is hands-on and focuses on building and deploying AI solutions using the Microsoft Foundry platform and its associated tools. It spans generative AI apps, text and speech processing, computer vision, and document intelligence all implemented through the Foundry portal and SDK.
|
최신 Microsoft Certified: Azure AI Fundamentals AI-901 무료샘플문제 (Q74-Q79):
질문 # 74
You have a Microsoft Foundry project that contains a vision-enabled model deployment.
You use the Azure OpenAI Responses API to send a prompt to the model.
You need to provide an image for analysis.
Which content item should you include in the request?
- A. input_image
- B. image_base64
- C. image_generation
- D. output_image
정답:A
설명:
When sending an image for analysis using the Azure OpenAI Responses API within a Microsoft Foundry project, you must include a content item object with the type input_image in the message payload.
Required Content Object Structure
Unlike the standard Chat Completions API (which uses type: "image_url"), the Responses API explicitly structures a multimodal image input as a separate block with the following properties:
type: Must be explicitly set to "input_image".
image_url: A dictionary or a direct parameter containing the target location of the image.
Reference:
https://learn.microsoft.com/en-us/azure/foundry/openai/how-to/responses
질문 # 75
Hotspot Question
Select the answer that correctly completes the sentence.
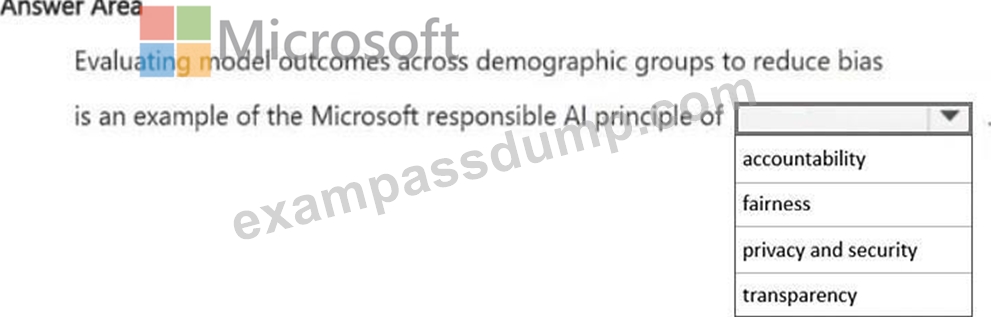
정답:
설명:

질문 # 76
Hotspot Question
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.

정답:
설명:

Explanation:
Box 1: Yes
Yes, a multimodal generative AI model is required to process prompts that contain images. These models can understand and combine different types of data, such as text and visual inputs, at the same time.
Box 2: Yes
Yes, you can use both methods to provide an image in the portal.
In the Microsoft Foundry chat playground, when interacting with vision-enabled models (like gpt-
4o or gpt-4o-mini), the interface allows you to upload local image files directly or paste a publicly accessible URL endpoint.
Box 3: Yes
A multimodal model can interpret multiple images in a single prompt. Most modern vision- language models accept several image inputs at once for tasks like comparison or sequential analysis.
Reference:
https://learn.microsoft.com/en-us/azure/foundry/openai/how-to/gpt-with-vision
질문 # 77
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.

정답:
설명:

질문 # 78
You have a Microsoft Foundry project that contains a vision-enabled model deployment.
You need to develop an application that sends a message containing text and an image URL.
The solution must ensure the quickest response time.
Which message structure should you include in the request?
- A. a user message that includes both a text item and an image item in the content array
- B. a system message that includes both a text item and an image item in the content array
- C. a system message that includes only a text item and sends an image item in a separate request
- D. a user message that includes only a text item and sends an image item in a separate request
정답:A
설명:
For a vision-enabled model, Microsoft documentation shows that multimodal prompts can include both text and image content in the same user message content array. Azure OpenAI vision models accept multimodal image-and-text input and return natural language responses.
The correct request structure is a user message with a content array containing both items, for example:
{
"role": "user",
"content": [
{"type": "input_text", "text": "What is in this image?"}, {"type": "input_image", "image_url":
image_url}
]
}
This avoids sending separate requests and is therefore the best choice for quickest response time.
A and C are incorrect because they send the text and image separately. B is incorrect because the image/question should be sent as a user message, while system messages are used for instructions and behavior.
질문 # 79
......
AI-901완벽한 시험덤프공부: https://www.exampassdump.com/AI-901_valid-braindumps.html
- AI-901최신 시험 예상문제모음 💰 AI-901시험대비 인증공부 📂 AI-901최신 기출문제 👸 시험 자료를 무료로 다운로드하려면➥ www.itdumpskr.com 🡄을 통해☀ AI-901 ️☀️를 검색하십시오AI-901최신버전 시험덤프문제
- AI-901퍼펙트 덤프데모문제 🚬 AI-901퍼펙트 덤프데모문제 👙 AI-901덤프문제모음 🍟 무료로 쉽게 다운로드하려면➥ www.itdumpskr.com 🡄에서➽ AI-901 🢪를 검색하세요AI-901퍼펙트 최신버전 덤프자료
- AI-901덤프최신문제 덤프 최신버전 자료 🍫 「 www.passtip.net 」을 통해 쉽게▷ AI-901 ◁무료 다운로드 받기AI-901퍼펙트 최신 덤프문제
- 실제 AI-901 시험덤프, AI-901 기출문제, 유효한 AI-901 덤프자료 ⏺ 검색만 하면➡ www.itdumpskr.com ️⬅️에서⇛ AI-901 ⇚무료 다운로드AI-901퍼펙트 최신버전 덤프자료
- 실제 AI-901 시험덤프, AI-901 기출문제, 유효한 AI-901 덤프자료 🏳 ➽ www.koreadumps.com 🢪을(를) 열고▶ AI-901 ◀를 입력하고 무료 다운로드를 받으십시오AI-901퍼펙트 공부자료
- AI-901덤프최신문제 인증시험패스하여 자격증 취득하기 🎫 ⇛ www.itdumpskr.com ⇚을(를) 열고➤ AI-901 ⮘를 입력하고 무료 다운로드를 받으십시오AI-901응시자료
- AI-901퍼펙트 공부자료 😎 AI-901퍼펙트 덤프데모문제 🧟 AI-901퍼펙트 공부자료 👋 ➠ www.dumptop.com 🠰웹사이트를 열고▶ AI-901 ◀를 검색하여 무료 다운로드AI-901 Dumps
- AI-901덤프최신문제 최신 인증시험은 덤프로 고고싱 🏛 오픈 웹 사이트☀ www.itdumpskr.com ️☀️검색( AI-901 )무료 다운로드AI-901최신 인증시험정보
- 실제 AI-901 시험덤프, AI-901 기출문제, 유효한 AI-901 덤프자료 🦄 시험 자료를 무료로 다운로드하려면➤ www.exampassdump.com ⮘을 통해「 AI-901 」를 검색하십시오AI-901퍼펙트 공부자료
- 최신 AI-901덤프최신문제 덤프문제 🚦 오픈 웹 사이트➽ www.itdumpskr.com 🢪검색⏩ AI-901 ⏪무료 다운로드AI-901최신 인증시험자료
- 시험패스에 유효한 AI-901덤프최신문제 최신버전 자료 🧶 지금➠ www.dumptop.com 🠰을(를) 열고 무료 다운로드를 위해➥ AI-901 🡄를 검색하십시오AI-901최신 인증시험정보
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.impactio.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes