P.S. Free & New Professional-Data-Engineer dumps are available on Google Drive shared by Pass4Leader: https://drive.google.com/open?id=1JNC20mMRB4-JJvM_aKuu5ztEvbZ-PSbC
In order to provide the most effective Professional-Data-Engineer exam materials which cover all of the current events for our customers, a group of experts in our company always keep an close eye on the changes of the Professional-Data-Engineer exam even the smallest one, and then will compile all of the new key points as well as the latest types of exam questions into the new version of our Professional-Data-Engineer Practice Test, and you can get the latest version of our study materials for free during the whole year. Do not lose the wonderful chance to advance with times.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Ensuring solution quality | 28% | - Security and governance
|
| Topic 2: Building and operationalizing data processing systems | 24% | - Data ingestion and integration
|
| Topic 3: Designing data processing systems | 22% | - Data architecture and storage design
|
| Topic 4: Operationalizing machine learning models | 26% | - ML pipeline integration
|
>> Professional-Data-Engineer Valid Test Answers <<
Almost everyone is trying to get the Google Certified Professional Data Engineer Exam (Professional-Data-Engineer) certification to update their CV or get the desired job. Every student faces just one problem and that is not finding updated study material. Applicants are always confused about where to buy real Google Professional-Data-Engineer Dumps Questions and prepare for the Google Certified Professional Data Engineer Exam (Professional-Data-Engineer) exam in less time. Nowadays everyone is interested in getting the Google Certified Professional Data Engineer Exam (Professional-Data-Engineer) certificate because it has multiple benefits for Google career.
NEW QUESTION # 325
You are deploying a new storage system for your mobile application, which is a media streaming service.
You decide the best fit is Google Cloud Datastore. You have entities with multiple properties, some of which can take on multiple values. For example, in the entity 'Movie'the property 'actors'and the property 'tags' have multiple values but the property 'date released' does not. A typical query would ask for all movies with actor=<actorname>ordered by date_releasedor all movies with tag=Comedyordered by date_released. How should you avoid a combinatorial explosion in the number of indexes?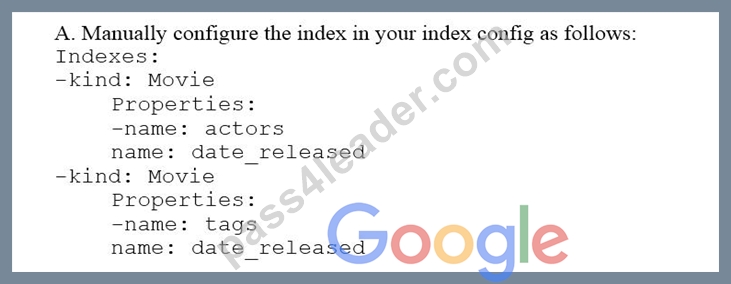
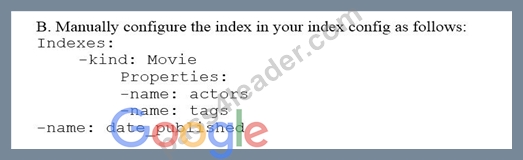
C: Set the following in your entity options: exclude_from_indexes = 'actors, tags' D: Set the following in your entity options: exclude_from_indexes = 'date_published'
Answer: A
NEW QUESTION # 326
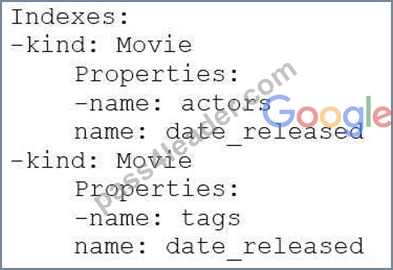
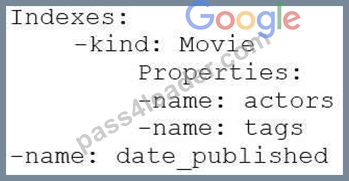
You are deploying a new storage system for your mobile application, which is a media streaming service. You decide the best fit is Google Cloud Datastore. You have entities with multiple properties, some of which can take on multiple values. For example, in the entity 'Movie'the property 'actors'and the property 'tags' have multiple values but the property 'date released' does not. A typical query would ask for all movies with actor=<actorname>ordered by date_releasedor all movies with tag=Comedyordered by date_released. How should you avoid a combinatorial explosion in the number of indexes?
Answer: A
NEW QUESTION # 327
Case Study 1 - Flowlogistic
Company Overview
Flowlogistic is a leading logistics and supply chain provider. They help businesses throughout the world manage their resources and transport them to their final destination. The company has grown rapidly, expanding their offerings to include rail, truck, aircraft, and oceanic shipping.
Company Background
The company started as a regional trucking company, and then expanded into other logistics market.
Because they have not updated their infrastructure, managing and tracking orders and shipments has become a bottleneck. To improve operations, Flowlogistic developed proprietary technology for tracking shipments in real time at the parcel level. However, they are unable to deploy it because their technology stack, based on Apache Kafka, cannot support the processing volume. In addition, Flowlogistic wants to further analyze their orders and shipments to determine how best to deploy their resources.
Solution Concept
Flowlogistic wants to implement two concepts using the cloud:
* Use their proprietary technology in a real-time inventory-tracking system that indicates the location of their loads
* Perform analytics on all their orders and shipment logs, which contain both structured and unstructured data, to determine how best to deploy resources, which markets to expand info. They also want to use predictive analytics to learn earlier when a shipment will be delayed.
Existing Technical Environment
Flowlogistic architecture resides in a single data center:
* Databases
8 physical servers in 2 clusters
- SQL Server - user data, inventory, static data
3 physical servers
- Cassandra - metadata, tracking messages
10 Kafka servers - tracking message aggregation and batch insert
* Application servers - customer front end, middleware for order/customs
60 virtual machines across 20 physical servers
- Tomcat - Java services
- Nginx - static content
- Batch servers
* Storage appliances
- iSCSI for virtual machine (VM) hosts
- Fibre Channel storage area network (FC SAN) - SQL server storage
- Network-attached storage (NAS) image storage, logs, backups
* 10 Apache Hadoop /Spark servers
- Core Data Lake
- Data analysis workloads
* 20 miscellaneous servers
- Jenkins, monitoring, bastion hosts,
Business Requirements
* Build a reliable and reproducible environment with scaled panty of production.
* Aggregate data in a centralized Data Lake for analysis
* Use historical data to perform predictive analytics on future shipments
* Accurately track every shipment worldwide using proprietary technology
* Improve business agility and speed of innovation through rapid provisioning of new resources
* Analyze and optimize architecture for performance in the cloud
* Migrate fully to the cloud if all other requirements are met
Technical Requirements
* Handle both streaming and batch data
* Migrate existing Hadoop workloads
* Ensure architecture is scalable and elastic to meet the changing demands of the company.
* Use managed services whenever possible
* Encrypt data flight and at rest
* Connect a VPN between the production data center and cloud environment SEO Statement We have grown so quickly that our inability to upgrade our infrastructure is really hampering further growth and efficiency. We are efficient at moving shipments around the world, but we are inefficient at moving data around.
We need to organize our information so we can more easily understand where our customers are and what they are shipping.
CTO Statement
IT has never been a priority for us, so as our data has grown, we have not invested enough in our technology. I have a good staff to manage IT, but they are so busy managing our infrastructure that I cannot get them to do the things that really matter, such as organizing our data, building the analytics, and figuring out how to implement the CFO' s tracking technology.
CFO Statement
Part of our competitive advantage is that we penalize ourselves for late shipments and deliveries. Knowing where out shipments are at all times has a direct correlation to our bottom line and profitability. Additionally, I don't want to commit capital to building out a server environment.
Flowlogistic's management has determined that the current Apache Kafka servers cannot handle the data volume for their real-time inventory tracking system. You need to build a new system on Google Cloud Platform (GCP) that will feed the proprietary tracking software. The system must be able to ingest data from a variety of global sources, process and query in real-time, and store the data reliably. Which combination of GCP products should you choose?
Answer: A
Explanation:
Pub/Sub -> Dataflow for real time processing requirements.
https://codelabs.developers.google.com/codelabs/cpb104-pubsub/#0
NEW QUESTION # 328
You are deploying MariaDB SQL databases on GCE VM Instances and need to configure monitoring and alerting. You want to collect metrics including network connections, disk IO and replication status from MariaDB with minimal development effort and use StackDriver for dashboards and alerts.
What should you do?
Answer: B
Explanation:
The GitHub repository named google-fluentd-catch-all-config which includes the configuration files for the Logging agent for ingesting the logs from various third-party software packages.
NEW QUESTION # 329
You use a dataset in BigQuery for analysis. You want to provide third-party companies with access to the same dataset. You need to keep the costs of data sharing low and ensure that the data is current. Which solution should you choose?
Answer: C
Explanation:
Explanation
NEW QUESTION # 330
......
When it comes to Professional-Data-Engineer exam, many candidates are lack of confidence to pass it. But we all know self-confidence is the spiritual pillar of a person as well as the inherent power, which is of great importance and value to a person who want to pass the Professional-Data-Engineer exam. Our material include free Demo, you can go for free it of the Professional-Data-Engineer Materials and make sure that the quality of our questions and answers serve you the best. You are not required to pay any amount or getting registered with us for downloading free Professional-Data-Engineer materials. You can improve your confidence in the exam by learning about real exams through our free demo.
Official Professional-Data-Engineer Study Guide: https://www.pass4leader.com/Google/Professional-Data-Engineer-exam.html
BONUS!!! Download part of Pass4Leader Professional-Data-Engineer dumps for free: https://drive.google.com/open?id=1JNC20mMRB4-JJvM_aKuu5ztEvbZ-PSbC