Certified-Data-Engineer-Professional Reliable Exam Tutorial - Certified-Data-Engineer-Professional Exam Questions

Based on a return visit to students who purchased our Certified-Data-Engineer-Professional actual exam, we found that over 99% of the customers who purchased our Certified-Data-Engineer-Professional learning materials successfully passed the exam. Advertisements can be faked, but the scores of the students cannot be falsified. Certified-Data-Engineer-Professional Study Guide’s good results are derived from the intensive research and efforts of our experts. And we have become a popular brand in this field.
| Section | Objectives |
|---|
| Data Governance | - Govern enterprise data
- 1. Create and add descriptions and metadata to enterprise data to improve discoverability
- 2. Demonstrate understanding of the Unity Catalog permission inheritance model
|
| Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
- 2. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
|
| Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 2. Apply Change Data Feed to address streaming table limitations and improve latency
- 3. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 4. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 5. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
|
| Data Modeling | - Design and optimize data models
- 1. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 2. Design dimensional models for analytical workloads with efficient querying and aggregation
- 3. Design and implement scalable data models using Delta Lake to manage large datasets
- 4. Simplify data layout decisions and optimize query performance using liquid clustering
|
| Developing Code for Data Processing using Python and SQL | - Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 2. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 3. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 4. Create pipeline components using control flow operators such as if/else and foreach
- 5. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 6. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 7. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 8. Explain the advantages and disadvantages of streaming tables compared to materialized views
- Using Python and Tools for Development
- 1. Develop User-Defined Functions using Pandas/Python UDF
- 2. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 3. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
|
| Debugging and Deploying | - Debugging and Troubleshooting
- 1. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- 2. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 3. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- Deploying CI/CD
- 1. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
|
| Ensuring Data Security and Compliance | - Applying Data Security Mechanisms
- 1. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 2. Use row filters and column masks to protect sensitive table data
- 3. Use ACLs to secure workspace objects and enforce the principle of least privilege
- Ensuring Compliance
- 1. Implement compliant batch and streaming pipelines that detect and mask PII
- 2. Develop data purging solutions that comply with data retention policies
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
- 2. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
|
| Monitoring and Alerting | - Alerting
- 1. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- 2. Use SQL Alerts to monitor data quality
- Monitoring
- 1. Use Query Profile and Spark UI to monitor workloads
- 2. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 3. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 4. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
|
| Data Sharing and Federation | - Share and federate data
- 1. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 2. Configure Lakehouse Federation with appropriate governance across supported source systems
- 3. Use Delta Sharing to share live data from the Lakehouse with any computing platform
|
>> Certified-Data-Engineer-Professional Reliable Exam Tutorial <<
Databricks Certified-Data-Engineer-Professional Exam Questions - Certified-Data-Engineer-Professional Latest Mock Test
Although the passing rate of our Certified-Data-Engineer-Professional simulating exam is nearly 100%, we can refund money in full if you are still worried that you may not pass. You don't need to worry about the complexity of the refund process at all, we've made it quite simple. As long as you provide us with proof that you failed the exam after using our Certified-Data-Engineer-Professional, we can refund immediately. If you encounter any problems during the refund process, you can also contact our customer service staff at any time. They will help you solve the problem as quickly as possible. That is to say, our Certified-Data-Engineer-Professional Exam Questions almost guarantee that you pass the exam. Even if you don't pass, you don't have to pay any price for our Certified-Data-Engineer-Professional simulating exam. I hope we have enough sincerity to impress you.
Databricks Certified Data Engineer Professional Sample Questions (Q240-Q245):
NEW QUESTION # 240
A data engineer is reviewing the PySpark code to copy a part of the production dataset to the sandbox environment, and needs to be sure that no PII(Personally Identifiable Information) data is being copied. After checking the sales table, the data engineer notices that it has user emails as the only PII data included as well as being the only column to identify the user.
from pyspark.sql import functions as F
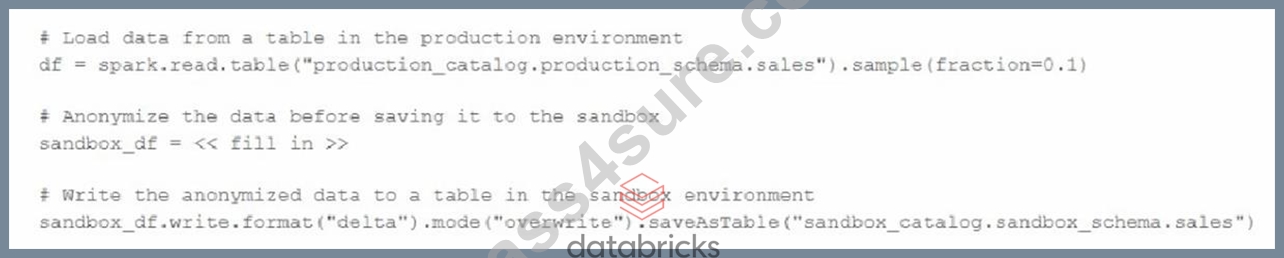
Which anonymised code should be used to achieve the required outcome?
- A. df.withColumn ("hashed_email", sha2 ("user_email"))
- B. df.withColumn ("user_emai", F.expr("uuid()"))
- C. df.withColumn ("user_email", F.sha2 ("user_email"))
- D. df.withColumn ("user_email", F.regexp_replace ("user_eamail", "@*", "@anonymized.com"))
Answer: C
Explanation:
Hashing the email column replaces the original PII with a deterministic, irreversible value while preserving its role as a unique identifier. This ensures no actual email addresses are copied to the sandbox environment, while still allowing consistent joins or user-level analysis if needed.
NEW QUESTION # 241
A data engineer deploys a multi-task Databricks job that orchestrates three notebooks. One task intermittently fails with Exit Code 1 but succeeds on retry. The engineer needs to collect detailed logs for the failing attempts, including stdout/stderr and cluster lifecycle context, and share them with the platform team. What steps the data engineer needs to follow using built-in tools?
- A. Use the notebook interactive debugger to re-run the entire multi-task job, and capture step- through traces for the failing task.
- B. Export the notebook run results to HTML; this bundle includes complete stdout, stderr, and cluster event history across all tasks.
- C. From the job run details page, export the job's logs or configure log delivery; then retrieve the compute driver logs and event logs from the compute details page to correlate stdout/stderr with cluster events.
- D. Download worker logs directly from the Spark UI and ignore driver logs, as worker logs contain stdout/stderr for all tasks and cluster events.
Answer: C
Explanation:
The recommended way to troubleshoot and collect detailed job logs is through the Job Run Details page in Databricks. From there, engineers can export run logs or configure automatic log delivery to a storage destination. The driver and event logs available under compute details provide stdout, stderr, and cluster lifecycle context required for root-cause analysis.
NEW QUESTION # 242
A data engineer is building a customer data pipeline in Lakeflow Spark Declarative Pipelines. The source is a cloud-based event stream with limited retention containing inserts, updates, and deletes for customer records. These changes are being applied using the AUTO CDC INTO syntax to maintain an SCD Type 1 table as the target table, customer_dim. How should the data engineer build a downstream job that streams from the customer_dim table to only act on updates and delete events, processing data incrementally?
- A. When stored as SCD 1, the target of AUTO CDC INTO includes updates and deletes. Streaming from customer_dim can fail due to these operations. Instead, build another stream from the original source.
- B. Use ignoreChanges flag while streaming from customer_dim to avoid breaking the pipeline during updates and deletes.
- C. Streaming from customer_dim table would only be possible in the case of SCD 2 retention.
- D. Read change data feed from customer_dim table and apply filters to incrementally act on the change events.
Answer: D
Explanation:
Reading the change data feed from the customer_dim table enables downstream processing to react specifically to update and delete events while operating incrementally. Change data feed exposes row-level change types and versions, making it the correct mechanism for streaming only the relevant changes from an SCD Type 1 table maintained with AUTO CDC INTO.
NEW QUESTION # 243
An analytics team wants to run a short-term experiment in Databricks SQL on the customer transactions Delta table (about 20 billion records) created by the data engineering team. Which strategy should the data engineering team use to ensure minimal downtime and no impact on the ongoing ETL processes?
- A. Deep clone the table for the analytics team.
- B. Shallow clone the table for the analytics team.
- C. Give the analytics team direct access to the production table.
- D. Create a new table for the analytics team using a CTAS statement.
Answer: B
Explanation:
A shallow clone of the production Delta table creates an instantaneous snapshot that references the same data files, so it introduces virtually no downtime or storage overhead and avoids interfering with the ongoing ETL. A deep clone would copy all data (very expensive and slow for
20B rows). CTAS rewrites data and is unnecessary; direct access to prod risks contention and accidental changes.
NEW QUESTION # 244
A data engineer, while designing a Pandas UDF to process financial time-series data with complex calculations that require maintaining state across rows within each stock symbol group, must ensure the function is efficient and scalable. Which approach will solve the problem with minimum overhead while preserving data integrity?
- A. Use a grouped_agg Pandas UDF that processes each stock symbol group independently, maintaining state through intermediate aggregation results that get passed between successive UDF calls via broadcast variables.
- B. Use a SCALAR Pandas UDF that processes the entire dataset at once, implementing custom partitioning logic within the UDF to group by stock symbol and maintain state using global variables shared across all executor processes.
- C. Use a SCALAR_ITER Pandas UDF with iterator-based processing, implementing state management through persistent storage (Delta tables) that gets updated after each batch to maintain continuity across iterator chunks.
- D. Use applyInPandas() on a Spark DataFrame that receives all rows for each stock symbol as a Pandas DataFrame, allowing processing within each group while maintaining state variables local to each group's processing function.
Answer: D
Explanation:
The Databricks documentation recommends applyInPandas() for complex per-group operations where maintaining internal state within each group is necessary. When using applyInPandas(), Spark provides all records for each grouping key as a Pandas DataFrame to the function, allowing efficient vectorized operations with local state management. This approach ensures high performance and scalability while maintaining logical isolation between groups. In contrast, SCALAR and SCALAR_ITER UDFs operate on individual rows or batches and cannot maintain inter-row state effectively. grouped_agg UDFs are limited to computing aggregates and do not support complex multi-row transformations. Therefore, applyInPandas() is the correct and Databricks-recommended solution for stateful per-group time-series computations.
NEW QUESTION # 245
......
In modern society, everything is changing so fast with the development of technology. If you do no renew your knowledge and skills, you will be wiped out by others. Our Certified-Data-Engineer-Professional study materials also keep up with the society. After all, new technology has been applied in many fields. It is time to strengthen your skills. Our Certified-Data-Engineer-Professional Study Materials will help you master the most popular skills in the job market. Then you will have a greater chance to find a desirable job. Also, it doesn’t matter whether have basic knowledge about the Certified-Data-Engineer-Professional study materials.
Certified-Data-Engineer-Professional Exam Questions: https://www.2pass4sure.com/Databricks-Certification/Certified-Data-Engineer-Professional-actual-exam-braindumps.html
- Braindumps Certified-Data-Engineer-Professional Torrent 👦 Certified-Data-Engineer-Professional Positive Feedback 💍 Free Certified-Data-Engineer-Professional Exam 🚤 Go to website ➤ www.prepawaypdf.com ⮘ open and search for 《 Certified-Data-Engineer-Professional 》 to download for free 😷Certified-Data-Engineer-Professional Valid Exam Braindumps
- Pass Guaranteed Quiz Databricks - High Hit-Rate Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional Reliable Exam Tutorial 🥙 Immediately open ⮆ www.pdfvce.com ⮄ and search for “ Certified-Data-Engineer-Professional ” to obtain a free download 💕New Certified-Data-Engineer-Professional Braindumps Pdf
- 100% Pass Quiz 2026 High Pass-Rate Databricks Certified-Data-Engineer-Professional Reliable Exam Tutorial 🧰 Open ▛ www.verifieddumps.com ▟ enter ⇛ Certified-Data-Engineer-Professional ⇚ and obtain a free download 🔹Reliable Certified-Data-Engineer-Professional Exam Topics
- Braindumps Certified-Data-Engineer-Professional Torrent 🧮 Certified-Data-Engineer-Professional Positive Feedback 📇 Certified-Data-Engineer-Professional Valid Exam Braindumps ☃ Search for ☀ Certified-Data-Engineer-Professional ️☀️ on ▛ www.pdfvce.com ▟ immediately to obtain a free download 😸Free Certified-Data-Engineer-Professional Exam
- Certified-Data-Engineer-Professional Exam Passing Score 🛂 Certified-Data-Engineer-Professional Valid Test Question 🍍 New Certified-Data-Engineer-Professional Braindumps Pdf 🚥 Open 《 www.prepawayete.com 》 and search for ➤ Certified-Data-Engineer-Professional ⮘ to download exam materials for free 💜Reliable Certified-Data-Engineer-Professional Exam Topics
- Features of Databricks Certified-Data-Engineer-Professional PDF Dumps Formate 🌸 Immediately open 《 www.pdfvce.com 》 and search for 《 Certified-Data-Engineer-Professional 》 to obtain a free download 😘Certified-Data-Engineer-Professional Exam Simulator Fee
- 100% Pass Quiz 2026 Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Pass-Sure Reliable Exam Tutorial 🪀 Search for 《 Certified-Data-Engineer-Professional 》 and download it for free on ▛ www.prep4away.com ▟ website ✴Exam Certified-Data-Engineer-Professional Preview
- Braindumps Certified-Data-Engineer-Professional Torrent 🥞 Certified-Data-Engineer-Professional Exam Passing Score 😰 Certification Certified-Data-Engineer-Professional Test Answers 🍱 Search for ➡ Certified-Data-Engineer-Professional ️⬅️ and download exam materials for free through [ www.pdfvce.com ] 📕Reliable Certified-Data-Engineer-Professional Exam Topics
- Certified-Data-Engineer-Professional Valid Exam Braindumps 🙀 Certified-Data-Engineer-Professional Latest Test Cost 🌕 Certified-Data-Engineer-Professional Test Dumps 🎳 Easily obtain free download of ⏩ Certified-Data-Engineer-Professional ⏪ by searching on 【 www.pass4test.com 】 🐟New Certified-Data-Engineer-Professional Braindumps Pdf
- 100% Pass Quiz 2026 High Pass-Rate Databricks Certified-Data-Engineer-Professional Reliable Exam Tutorial 🥈 Open ➽ www.pdfvce.com 🢪 and search for [ Certified-Data-Engineer-Professional ] to download exam materials for free 🔺Free Certified-Data-Engineer-Professional Exam
- Pass Guaranteed Quiz Databricks - High Hit-Rate Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional Reliable Exam Tutorial ⏪ Copy URL 「 www.prepawayete.com 」 open and search for ➠ Certified-Data-Engineer-Professional 🠰 to download for free 👞Reliable Certified-Data-Engineer-Professional Test Tutorial
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, anoj.in.net, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes