DOWNLOAD the newest DumpsTorrent DP-100 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=14DZ_kcXrIN8neJKOcWqG3FiezErciyww
All-in-One Exam Guide Practice To your DP-100 Exam. To meet this objective DumpsTorrent is offering valid, updated, and real DP-100 exam practice test questions in their formats.. Download DP-100 study guide pdf, pass Designing and Implementing a Data Science Solution on Azure exam with full refund guarantee! Success Microsoft exam with DP-100 Exam Questions which has high pass rate. Use free DP-100 certification questions to gain a good test result.
| Section | Objectives |
|---|---|
| Deploy and consume models | - Deploy models to endpoints - Monitor deployed models and endpoints |
| Optimize and manage models | - Track experiments and manage model lifecycle - Improve model performance |
| Explore and analyze data | - Ingest and prepare data for modeling - Perform exploratory data analysis |
| Design and prepare a machine learning solution | - Manage compute and data assets - Plan and configure Azure Machine Learning workspace - Select appropriate Azure services for machine learning workloads |
| Train machine learning models | - Tune hyperparameters and evaluate models - Train models using Azure Machine Learning |
>> Free DP-100 Practice Exams <<
Free demo is available for DP-100 training materials, so that you can have a deeper understanding of what you are going to buy. We also recommend you to have a try. In addition, DP-100 training materials are compiled by experienced experts, and they are quite familiar with the exam center, and if you choose us, you can know the latest information for the DP-100 Exam Dumps. We offer you free update for one year after buying DP-100 exam materials from us, and our system will send the latest version to your email automatically. So you just need to check your email, and change the your learning ways in accordance with new changes.
NEW QUESTION # 121
You have a Python data frame named salesData in the following format: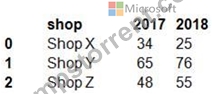
The data frame must be unpivoted to a long data format as follows: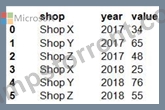
You need to use the pandas.melt() function in Python to perform the transformation.
How should you complete the code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.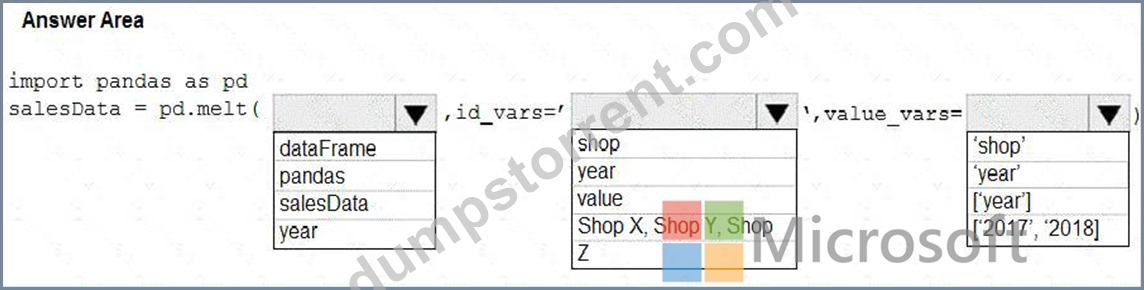
Answer:
Explanation: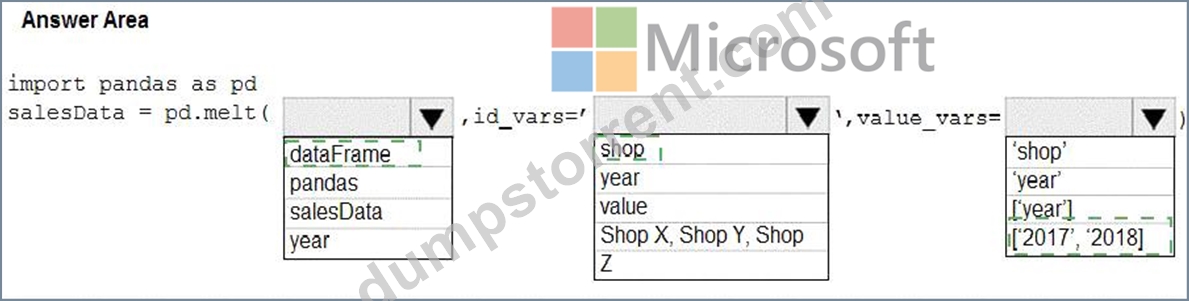
Explanation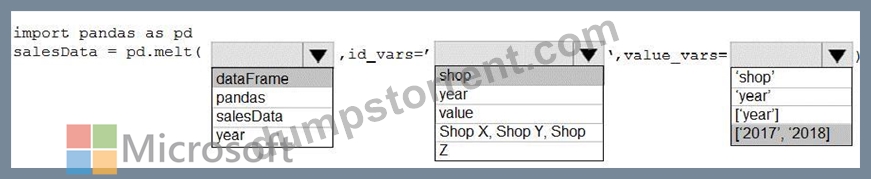
Box 1: dataFrame
Syntax: pandas.melt(frame, id_vars=None, value_vars=None, var_name=None, value_name='value', col_level=None)[source] Where frame is a DataFrame Box 2: shop Paramter id_vars id_vars : tuple, list, or ndarray, optional Column(s) to use as identifier variables.
Box 3: ['2017','2018']
value_vars : tuple, list, or ndarray, optional
Column(s) to unpivot. If not specified, uses all columns that are not set as id_vars.
Example:
df = pd.DataFrame({'A': {0: 'a', 1: 'b', 2: 'c'},
'B': {0: 1, 1: 3, 2: 5},
'C': {0: 2, 1: 4, 2: 6}})
pd.melt(df, id_vars=['A'], value_vars=['B', 'C'])
A variable value
0 a B 1
1 b B 3
2 c B 5
3 a C 2
4 b C 4
5 c C 6
References:
https://pandas.pydata.org/pandas-docs/stable/reference/api/pandas.melt.html
NEW QUESTION # 122
You create a multi-class image classification deep learning model that uses the PyTorch deep learning framework.
You must configure Azure Machine Learning Hyperdrive to optimize the hyperparameters for the classification model.
You need to define a primary metric to determine the hyperparameter values that result in the model with the best accuracy score.
Which three actions must you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: B,C,D
Explanation:
AD:
primary_metric_name="accuracy",
primary_metric_goal=PrimaryMetricGoal.MAXIMIZE
Optimize the runs to maximize "accuracy". Make sure to log this value in your training script.
Note:
primary_metric_name: The name of the primary metric to optimize. The name of the primary metric needs to exactly match the name of the metric logged by the training script.
primary_metric_goal: It can be either PrimaryMetricGoal.MAXIMIZE or
PrimaryMetricGoal.MINIMIZE and determines whether the primary metric will be maximized or minimized when evaluating the runs.
F: The training script calculates the val_accuracy and logs it as "accuracy", which is used as the primary metric.
NEW QUESTION # 123
You train a machine learning model by using Aunt Machine Learning.
You use the following training script m Python to log an accuracy value.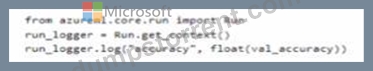
You must use a Python script to define a sweep job.
You need to provide the primary metric and goal you want hyper parameter tuning to optimize.
How should you complete the Python script? To answer select the appropriate options in the answer area NOTE: Each correct selection is worth one point.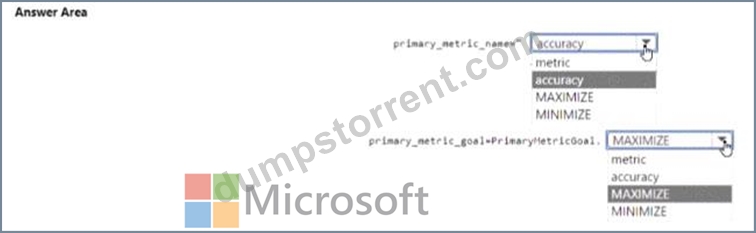
Answer:
Explanation: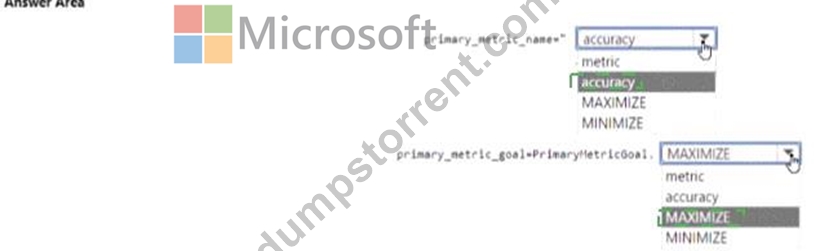
Explanation: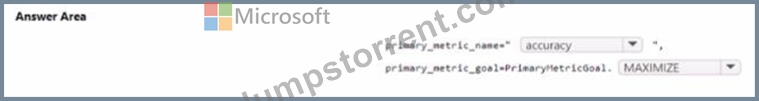
NEW QUESTION # 124
You create an experiment in Azure Machine Learning Studio. You add a training dataset that contains 10,000 rows. The first 9,000 rows represent class 0 (90 percent).
The remaining 1,000 rows represent class 1 (10 percent).
The training set is imbalances between two classes. You must increase the number of training examples for class 1 to 4,000 by using 5 data rows. You add the Synthetic Minority Oversampling Technique (SMOTE) module to the experiment.
You need to configure the module.
Which values should you use? To answer, select the appropriate options in the dialog box in the answer area.
NOTE: Each correct selection is worth one point.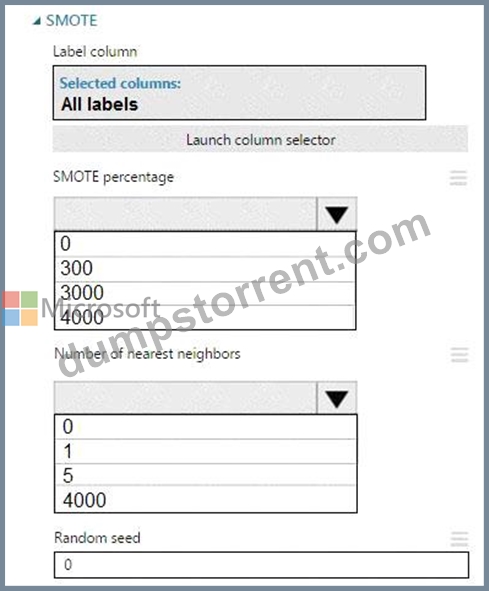
Answer:
Explanation: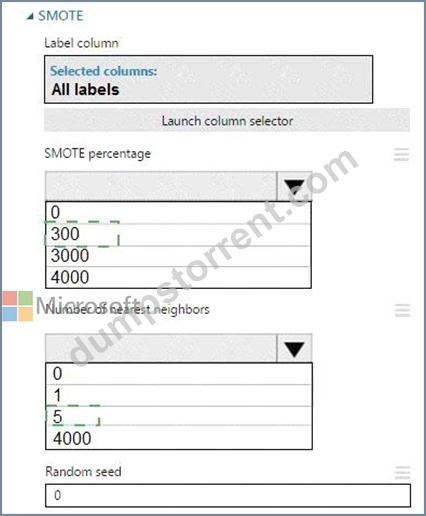
Explanation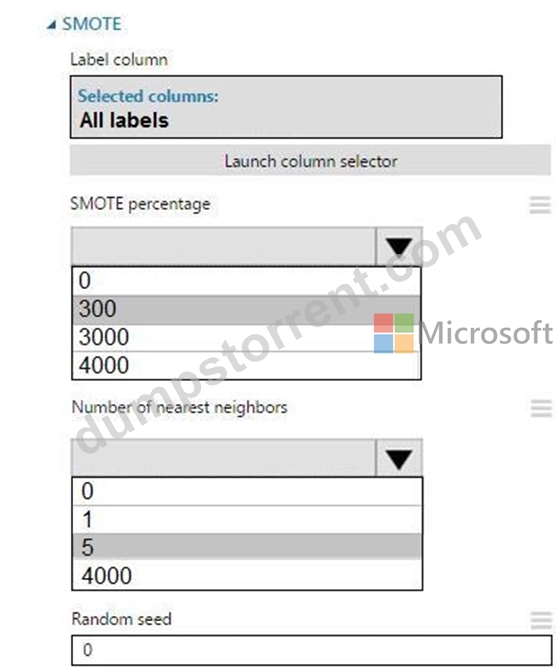
Box 1: 300
You type 300 (%), the module triples the percentage of minority cases (3000) compared to the original dataset (1000).
Box 2: 5
We should use 5 data rows.
Use the Number of nearest neighbors option to determine the size of the feature space that the SMOTE algorithm uses when in building new cases. A nearest neighbor is a row of data (a case) that is very similar to some target case. The distance between any two cases is measured by combining the weighted vectors of all features.
By increasing the number of nearest neighbors, you get features from more cases.
By keeping the number of nearest neighbors low, you use features that are more like those in the original sample.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/smote
NEW QUESTION # 125
You create an Azure Machine Learning workspace and a new Azure DevOps organization. You register a model in the workspace and deploy the model to the target environment.
All new versions of the model registered in the workspace must automatically be deployed to the target environment.
You need to configure Azure Pipelines to deploy the model.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.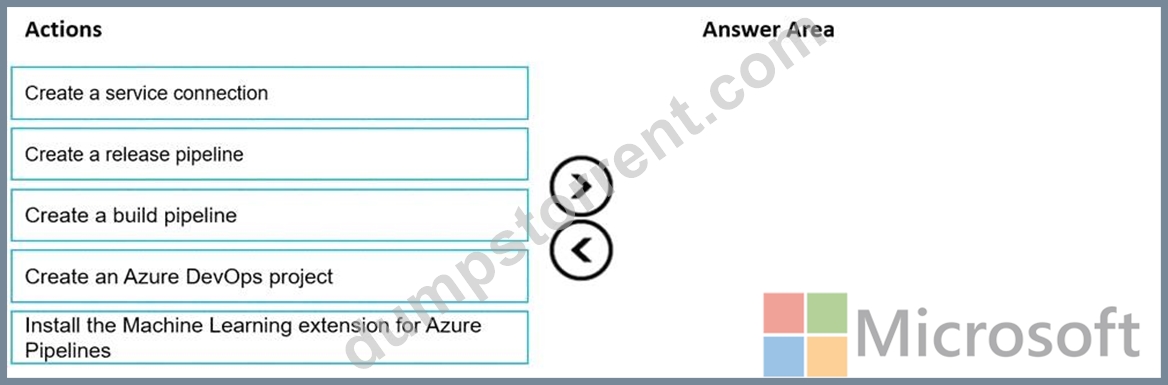
Answer:
Explanation: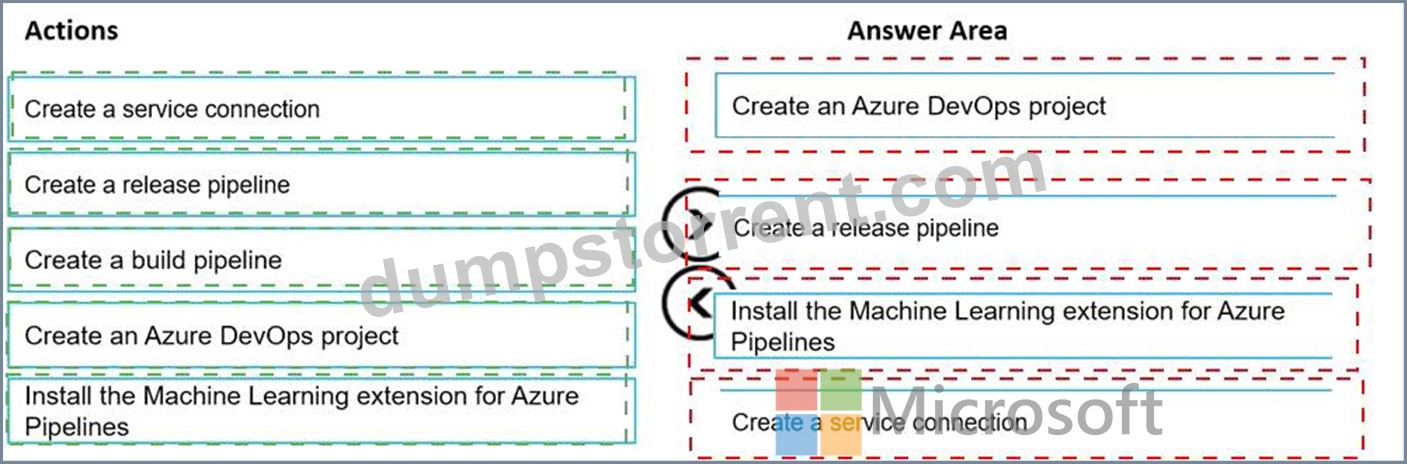
Explanation
Graphical user interface, text, application, email Description automatically generated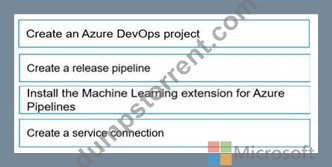
Step 1: Create an Azure DevOps project
Step 2: Create a release pipeline
Sign in to your Azure DevOps organization and navigate to your project.
Go to Pipelines, and then select New pipeline.
Step 3: Install the Machine Learning extension for Azure Pipelines
You must install and configure the Azure CLI and ML extension.
Step 4: Create a service connection
How to set up your service connection
Graphical user interface, text, application, email Description automatically generated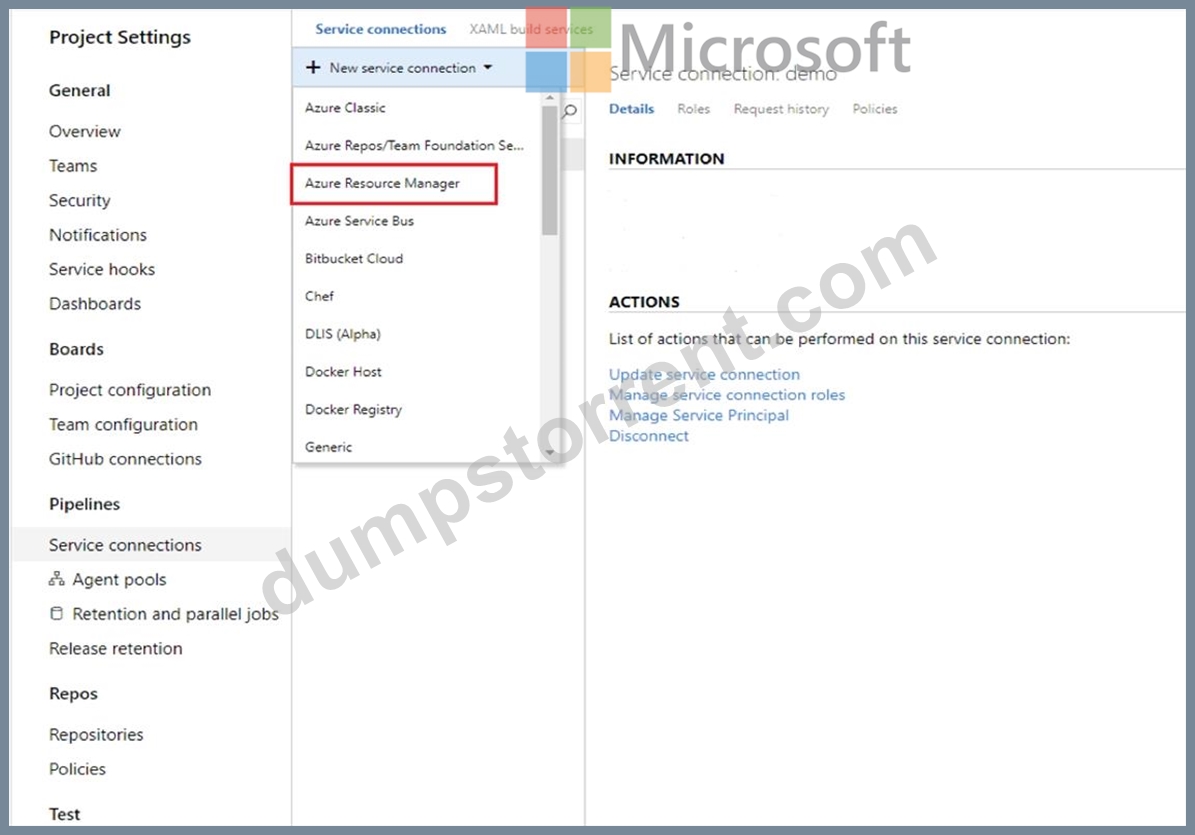
Select AzureMLWorkspace for the scope level, then fill in the following subsequent parameters.
Graphical user interface, text, application Description automatically generated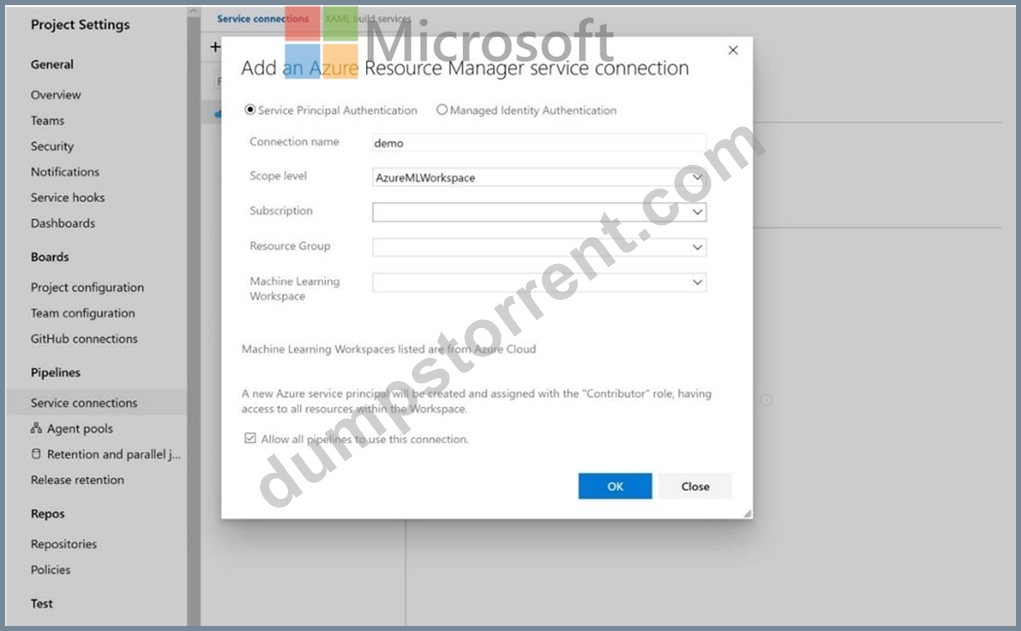
Note: How to enable model triggering in a release pipeline
Go to your release pipeline and add a new artifact. Click on AzureML Model artifact then select the appropriate AzureML service connection and select from the available models in your workspace.
Enable the deployment trigger on your model artifact as shown here. Every time a new version of that model is registered, a release pipeline will be triggered.
Reference:
https://marketplace.visualstudio.com/items?itemName=ms-air-aiagility.vss-services-azureml
https://docs.microsoft.com/en-us/azure/devops/pipelines/targets/azure-machine-learning
NEW QUESTION # 126
......
DumpsTorrent Designing and Implementing a Data Science Solution on Azure (DP-100) practice test software is the answer if you want to score higher in the Designing and Implementing a Data Science Solution on Azure (DP-100) exam and achieve your academic goals. Don't let the DP-100 certification exam stress you out! Prepare with our DP-100 exam dumps and boost your confidence in the Designing and Implementing a Data Science Solution on Azure (DP-100) exam. We guarantee your road toward success by helping you prepare for the Designing and Implementing a Data Science Solution on Azure (DP-100) certification exam. Use the best DumpsTorrent Microsoft DP-100 practice questions to pass your Designing and Implementing a Data Science Solution on Azure (DP-100) exam with flying colors!
Review DP-100 Guide: https://www.dumpstorrent.com/DP-100-exam-dumps-torrent.html
BONUS!!! Download part of DumpsTorrent DP-100 dumps for free: https://drive.google.com/open?id=14DZ_kcXrIN8neJKOcWqG3FiezErciyww