BTW, DOWNLOAD part of Exams4Collection AB-100 dumps from Cloud Storage: https://drive.google.com/open?id=1Q5RgQBTM_8R6H7k613gXqqjxn_ItcRJJ
Three versions are available for AB-100 study materials, and you can choose the most suitable one according to your own needs. AB-100 PDF version is printable, and you can print them and take some notes on them if you want. AB-100 Soft test engine can be used in more than 200 personal computers, and they support MS operating system. AB-100 Online Test engine is convenient and easy to learn, and it supports all web browsers. You can have a general review of what you have learned. Just have a try, and there is always a version for you.
| Section | Weight | Objectives |
|---|---|---|
| Design AI-powered business solutions | 30% | - Agent and solution design
|
| Plan AI-powered business solutions | 25% | - AI solution design strategy
|
| Deploy AI-powered business solutions | 45% | - Monitoring and optimization
|
>> Valid AB-100 Test Discount <<
You will go through Microsoft AB-100 Exams and will see for yourself the difference in your preparation. The Microsoft AB-100 practice test software is very user-friendly and simple to use. It is accessible on all browsers. It will save your progress and give a report of your mistakes which will surely be beneficial for your overall exam preparation.
NEW QUESTION # 59
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
A company has a Microsoft Dynamics 365 Sales environment that has Microsoft Copilot enabled.
You need to customize Copilot by tailoring how opportunity summaries are generated or how they are presented to users.
Solution: You build Microsoft Power Automate flows to trigger customized Copilot summaries.
Does this meet the goal?
Answer: B
Explanation:
Correct:
* You add fields to the opportunity summary.
Incorrect:
* You build Microsoft Power Automate flows to trigger customized Copilot summaries.
* You configure AI Builder lead scoring models to influence opportunity summaries.
Note:
To customize Microsoft Copilot opportunity summaries and incorporate AI Builder lead scoring data, you must configure the specific fields Copilot uses to ground its generative AI outputs.
By default, Copilot for Sales generates summaries using a set of predefined fields. To "influence" these summaries with scoring data, you need to add the predictive score and grade fields to the Opportunity summary configuration.
Step-by-Step Configuration
Switch Area: In the Sales Hub app, select the Change area menu in the bottom-left corner and choose App Settings.
Navigate to Copilot: Under General Settings, select Copilot.
Select Entity: Choose the Opportunities tab.
Add Fields:
Click Add fields.
Select the checkboxes for the fields you want to include.
You can select out-of-the-box, custom, and related table fields.
Save: Click Add and then Save your changes to update the summary configuration.
Reference:
https://learn.microsoft.com/en-us/dynamics365/sales/copilot-configure-summary-fields
NEW QUESTION # 60
You need to design a multi-agent solution that will include a custom agent. The solution must meet the following requirements:
* Define the ruin and constraints that the agent mutt follow.
* Automate a backend process that involves data movement between services and runs independently of the agent s reasoning steps.
What should you include in the design for each requirement ' To answer, select the appropriate options in the answer area NOTE: Each correct selection is worth one point.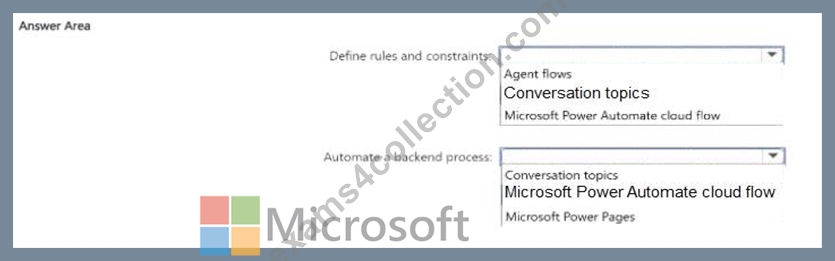
Answer:
Explanation: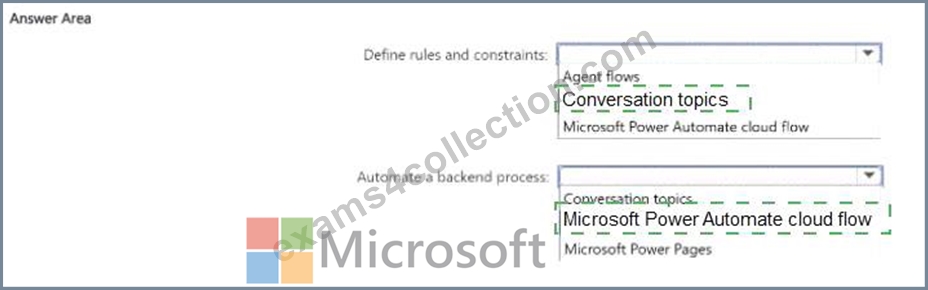
Explanation: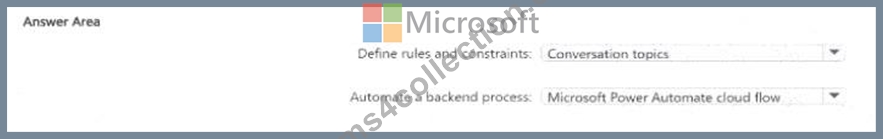
In Microsoft Copilot Studio, conversation topics define controlled conversational paths for an agent. A topic consists of nodes that determine how the interaction proceeds, including conditions, questions, messages, branching, and other deterministic logic. Microsoft specifically describes a topic as defining how an agent conversation progresses , making it the appropriate choice among the available options when specific rules or constrained behavior must be enforced.
A Microsoft Power Automate cloud flow is appropriate for the second requirement because the process involves backend automation and movement of data between services and must execute independently of the agent ' s reasoning. Power Automate cloud flows provide workflow automation using connectors, triggers, and actions and can operate independently rather than being selected dynamically as part of the agent ' s orchestration. Microsoft also distinguishes cloud flows that run independently from agent flows that can be attached to an agent as tools.
NEW QUESTION # 61
You are designing a testing solution for Microsoft Copilot Studio agents.
You need to validate prompt engineering best practices to ensure that the agents generate accurate and contextually relevant responses. Which prompt validation techniques and metrics should you include in the solution? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.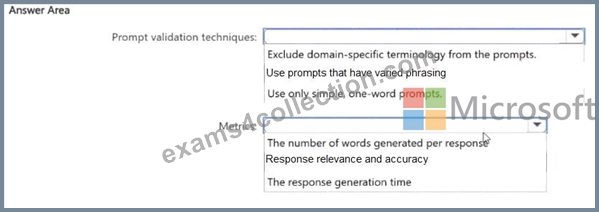
Answer:
Explanation: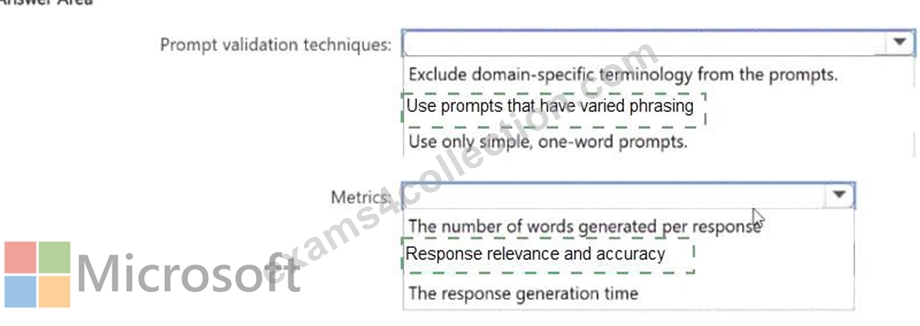
Explanation: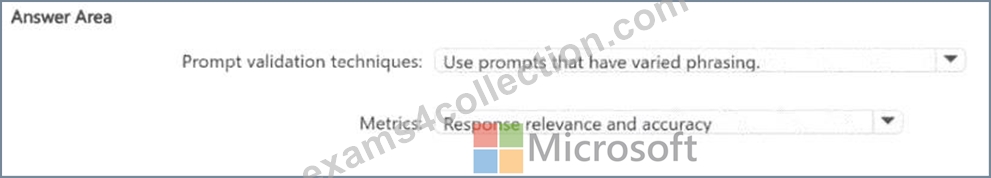
To validate prompt engineering for Microsoft Copilot Studio agents, the goal is to confirm that the agent responds correctly even when users ask the same thing in different ways, and to measure whether the responses are actually useful and correct.
For the prompt validation technique, the correct choice is Use prompts that have varied phrasing. This is a core best practice because real users do not ask questions in one fixed form. They may use different wording, sentence structure, synonyms, or levels of detail. Testing with varied phrasing checks whether the prompt design is robust and whether the agent can still produce the right response across natural language variation.
For the metric, the correct choice is Response relevance and accuracy. Since the requirement is to ensure responses are accurate and contextually relevant, this is the most appropriate measure. It directly evaluates whether the output answers the user's need correctly and in the right context.
Why the other options are not correct:
Exclude domain-specific terminology from the prompts is not a best practice in business AI solutions. In many enterprise scenarios, domain-specific terms are essential for accuracy.
Use only simple, one-word prompts does not reflect real-world usage and would weaken testing coverage.
The number of words generated per response does not tell you whether the response is correct or contextually appropriate.
The response generation time is a performance metric, not the best metric for validating prompt quality.
NEW QUESTION # 62
You are designing a testing solution for a Microsoft Copilot Studio agent that integrates with Microsoft Dynamics 365 Customer Service and Dynamics 365 Sales.
You need to design end-to-end scenarios to test the agent ' s ability to perform the following actions:
Coordinate tasks and data interactions across both Dynamics 365 apps.
Interpret user input and provide contextually relevant outputs.
Which test scenario and metric should you include in the design? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.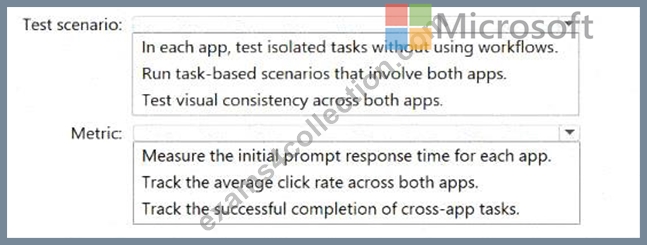
Answer:
Explanation: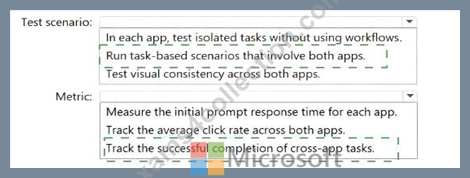
Explanation:
Test scenario # Run task-based scenarios that involve both apps; Metric # Track the successful completion of cross-app tasks Comprehensive and Detailed Explanation From Agentic AI Business Solutions Topics:
The correct answer is D:
Test scenario # Run task-based scenarios that involve both apps
Metric # Track the successful completion of cross-app tasks
Why this test scenario is correct
The question explicitly asks for an end-to-end testing design for a Copilot Studio agent that integrates with both:
Dynamics 365 Customer Service
Dynamics 365 Sales
The required capabilities are:
coordinating tasks and data interactions across both apps
interpreting user input and returning contextually relevant outputs
That means the testing approach cannot be isolated to one app at a time. It must validate the agent's behavior across the full multi-application business workflow.
That is why the correct test scenario is:
Run task-based scenarios that involve both apps
This kind of test validates whether the agent can successfully move through realistic business processes such as:
reading customer context from one app
updating or retrieving related sales information in the other
maintaining context through the workflow
responding appropriately based on user intent across systems
From an agentic AI business solutions perspective, this is the right design because true enterprise agent validation must focus on workflow execution, not just component-level checks.
Why this metric is correct
The best metric is:
Track the successful completion of cross-app tasks
This is the most direct way to measure whether the agent is actually achieving the intended business outcome across both Dynamics 365 applications.
Why this matters:
The requirement is about coordination across apps
The test is end-to-end
The goal is not just speed or UI consistency
The agent must complete business tasks successfully across systems
A cross-app completion metric shows whether the agent can:
understand the user's request
maintain context
retrieve or update the right information
finish the workflow correctly across app boundaries
This is much more meaningful than measuring clicks or simple response time.
Why the other options are incorrect
A). In each app, test isolated tasks without using workflows / Measure initial prompt response time This fails the end-to-end requirement. Isolated tasks do not validate cross-app orchestration, and response time does not prove successful workflow execution.
B). Run task-based scenarios that involve both apps / Track average click rate across both apps The scenario part is good, but average click rate is not the right success metric for Copilot task orchestration.
Clicks do not reliably measure whether the business process was completed correctly.
C). Test visual consistency across both apps / Track successful completion of cross-app tasks The metric is good, but the test scenario is wrong. Visual consistency is a UI concern, not an end-to-end functional validation of cross-app agent behavior.
Expert reasoning
For exam questions like this:
If the requirement says end-to-end across multiple apps, choose task-based scenarios involving both apps If the goal is business workflow success, choose a metric tied to task completion, not visual design, click rate, or raw response speed
NEW QUESTION # 63
Scenario: Your organization wants to empower different teams with custom AI agents using Microsoft Copilot Studio. Some teams only need simple, personal productivity agents based on SharePoint content, while others need enterprise-grade agents that integrate with back-end systems and require full lifecycle governance. Leadership asks you to identify the scenarios where each Copilot Studio experience-Lite or Full-would be the correct choice.
Which three of the following scenarios align with Microsoft's recommended use cases for choosing either the Lite or Full Copilot Studio experience? (Choose three)
Answer: A,B,E
Explanation:
A manager wants to quickly build a personal agent that answers questions using their team's internal SharePoint files-without needing complex workflows is correct because This scenario perfectly describes a use case for Copilot Studio Lite. Lite is designed for individual users or small teams to quickly create simple, personal productivity copilots, often leveraging Microsoft 365 content (like SharePoint) without requiring deep technical skills or complex integrations.
A department needs an agent that uses multi-step workflows and connects to a custom CRM via APIs for large-scale deployment across the organization is correct because This scenario aligns with the capabilities and target audience of the Full Copilot Studio experience. Building multi-step workflows, connecting to custom APIs (like a CRM), and preparing for large-scale organizational deployment are advanced features that require the comprehensive environment and governance capabilities of the Full Studio.
An enterprise wants to deploy an agent to thousands of external customers and requires controlled release management and secure integration with line-of-business systems is correct because This is a prime example of a scenario demanding the Full Copilot Studio experience.
Deploying to external customers at scale, requiring controlled release processes, and ensuring secure integration with core business systems (which often involves complex connectors and security configurations) are all advanced requirements best met by the robust features of Full Copilot Studio.
References:
https://learn.microsoft.com/en-us/microsoft-copilot-studio/publication-add-bot-to-microsoft-teams
https://www.microsoft.com/insidetrack/blog/how-our-employees-are-extending-enterprise-ai-with- custom-retrieval-agents/
https://learn.microsoft.com/en-us/microsoft-365-copilot/extensibility/copilot-studio-experience
NEW QUESTION # 64
......
You will be able to assess your shortcomings and improve gradually without having anything to lose in the actual Agentic AI Business Solutions Architect exam. You will sit through mock exams and solve actual Microsoft AB-100 dumps. In the end, you will get results that'll improve each time you progress and grasp the concepts of your syllabus. The desktop-based Microsoft AB-100 Practice Exam software is only compatible with Windows.
AB-100 Valid Test Braindumps: https://www.exams4collection.com/AB-100-latest-braindumps.html
What's more, part of that Exams4Collection AB-100 dumps now are free: https://drive.google.com/open?id=1Q5RgQBTM_8R6H7k613gXqqjxn_ItcRJJ