DOWNLOAD the newest ITPassLeader DP-800 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1t4-G-201fCtPjM6LYGp2klvWUp2l-0vj
If you buy our DP-800 training quiz, you will find three different versions are available on our test platform. According to your need, you can choose the suitable version for you. The three different versions of our DP-800 study materials include the PDF version, the software version and the online version. We can promise that the three different versions are equipment with the high quality. If you purchase our DP-800 Preparation questions, it will be very easy for you to easily and efficiently find the exam focus and pass the DP-800 exam.
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Developing AI-Enabled Database Solutions |
| Exam Number: | DP-800 |
| Exam Price: | $165 USD |
| Passing Score: | 700 |
| Exam Duration: | 100 minutes |
| Certificate Validity Period: | 1 year |
| Related Certifications: | Microsoft Certified: SQL AI Developer Associate |
| Available Languages: | Italian, French, Portuguese (Brazil), Chinese (Simplified), Korean, Spanish, Chinese (Traditional), Arabic (Saudi Arabia), German, English, Indonesian (Indonesia), Japanese |
| Real Exam Qty: | 40-60 |
| Exam Format: | Drag and drop, Multiple select, Case studies, Multiple choice, Build list |
| Sample Questions: | Microsoft DP-800 Sample Questions |
| Exam Way: | Online proctored or in-person at a testing center |
| Pre Condition: | No specific prerequisites, but candidates should have experience with SQL and a basic understanding of Azure services. Familiarity with AI or machine learning concepts is recommended. |
| Official Syllabus URL: | https://learn.microsoft.com/en-us/credentials/certifications/exams/dp-800/ |
We are quite confident that all these Microsoft DP-800 exam dumps feature you will not find anywhere. Just download the Microsoft DP-800 and start this journey right now. For the well and Microsoft DP-800 Exam Dumps preparation, you can get help from Microsoft DP-800 which will provide you with everything that you need to learn, prepare and pass the Developing AI-Enabled Database Solutions (DP-800) certification exam.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
NEW QUESTION # 31
You have an Azure SQL database that supports a customer-facing API. The API calls a stored procedure named dbo.GetCustomerOrders thousands of times per hour.
After a deployment that updated indexes and statistics, users report that the API endpoint backed by dbo.
Getcustomerorders is slower. In Query Store, the same query now has two persisted execution plans. During the last hour, the newer plan had a significantly higher average duration and CPU time than the older plan.
You need to restore the previous performance quickly, without changing the API code.
Which Transact-SQL command should you run?
Answer: A
Explanation:
The scenario says Query Store already shows two persisted execution plans for the same query, and the older plan performed much better than the newer one during the last hour. Microsoft documents that sp_query_store_force_plan is used to force a particular plan for a particular query in Query Store. That makes it the fastest way to restore the previously good plan without changing application code, which is exactly what the question requires.
Why the other options are not the best fit:
sp_query_store_set_hints is for adding or updating Query Store hints to influence compilation behavior, but when you already know the exact older good plan, Microsoft points to plan forcing as the direct remedy.
DBCC FREEPROCCACHE clears cached plans broadly and is disruptive; it does not guarantee a return to the known good plan.
ALTER DATABASE is too general and does not directly restore the prior execution plan.
So the right Transact-SQL command is:
EXEC sp_query_store_force_plan
using the relevant @query_id and @plan_id from Query Store for the older, better-performing plan.
Microsoft also notes that when a plan is forced, SQL Server tries to use that plan whenever it encounters the query again.
NEW QUESTION # 32
You have a SQL database in Microsoft Fabric named Sales BD that contains a table named dbo.Products. You need to modify SalesBD to meet the following requirements:
* Create a vector index on the appropriate column.
* Use a supplied natural language query vector.
How should you complete the Transact-SQL code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
The first correct selection is embedding because a vector index must be created on the vector column , not on a scalar distance column or a text column such as product_name. Microsoft's CREATE VECTOR INDEX documentation shows that the index is created directly on the vector-valued column, for example ON product_embeddings(embedding).
The second correct selection is VECTOR_SEARCH because the requirement is to use a supplied natural language query vector and search against the indexed embeddings. Microsoft documents that VECTOR_SEARCH is the Transact-SQL function for approximate nearest neighbor vector retrieval and that it applies to SQL database in Microsoft Fabric as well as other supported SQL platforms.
This also matches the shown code pattern:
* declare a vector variable such as @query_vector VECTOR(1536),
* create a vector index on dbo.Products(embedding),
* query with VECTOR_SEARCH(... SIMILAR_TO = @query_vector, METRIC = ' cosine ' , TOP_N =
10).
NEW QUESTION # 33
Hotspot Question
You have an SDK-style SQL database project named MyDatabaseProject.sqlprojstored in a private GitHub repository. The repository contains the following GitHub Actions workflow.
The repository contains the AZURE_SQL_CONNECTION_STRING secrets.
The target is an Azure SQL database that allows access to Azure services and is configured to support mixed authentication.
The workflow runs successfully.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
NEW QUESTION # 34
Case Study 1 - Contoso
Existing Environment
Azure Environment
Contoso has an Azure subscription in North Europe that contains the corporate infrastructure.
The current infrastructure contains a Microsoft SQL Server 2017 database. The database contains the following tables.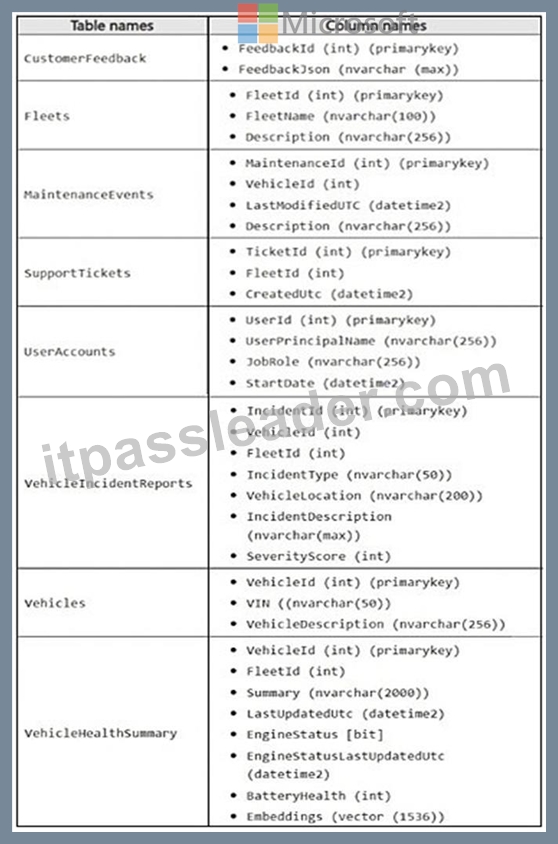
The FeedbackJsoncolumn has a full-text index and stores JSON documents in the following format.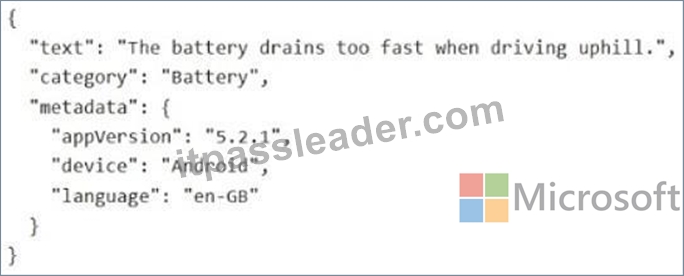
The support staff at Contoso never has the UNMASKpermission.
Problem Statements
Contoso is deploying a new Azure SQL database that will become the authoritative data store for the following:
* AI workloads
* Vector search
* Modernized API access
* Retrieval Augmented Generation (RAG) pipelines
Sometimes the ingestion pipeline fails due to malformed JSON and duplicate payloads.
The engineers at Contoso report that the following dashboard query runs slowly.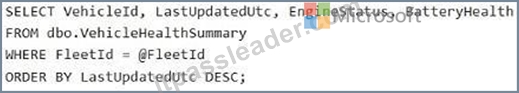
You review the execution plan and discover that the plan shows a clustered index scan.
VehicleIncidentReportsoften contains details about the weather, traffic conditions, and location. Analysts report that it is difficult to find similar incidents based on these details.
Requirements
Planned Changes
Contoso wants to modernize Fleet Intelligence Platform to support AI-powered semantic search over incident reports.
Security Requirements
Contoso identifies the following security requirements:
* Restrict the support staff from viewing Personally Identifiable Information (PII) data, which is full email addresses and phone numbers.
* Enforce row-level filtering so that analysts see only incidents for the fleets to which they are assigned. The analysts can be assigned to multiple fleets.
Database Performance and Requirements
Contoso identifies the following telemetry requirements:
* Telemetry data must be stored in a partitioned table.
* Telemetry data must provide predictable performance for ingestion and retention operations.
* latitude, longitude, and accuracyJSON properties must be filtered by using an index seek.
Contoso identifies the following maintenance data requirements:
* Ensure that any changes to a row in the MaintenanceEventstable updates the corresponding value in the LastModifiedUtccolumn to the time of the change.
* Avoid recursive updates.
AI Search, Embeddings, and Vector Indexing
Contoso plans to implement semantic search over incident data to meet the following requirements:
* Embeddings must be stored in dedicated Azure SQL Database tables.
* Embeddings must be generated from rich natural language fields.
* Chunking must preserve semantic coherence.
* Hybrid search must combine the following:
- Vector similarity
- Keyword filtering or boosting
Development Requirements
The development team at Contoso will use Microsoft Visual Studio Code and GitHub Copilot and will retrieve live metadata from the databases.
Contoso identifies the following requirements for querying data in the FeedbackJsoncolumn of the CustomerFeedbacktable:
* Extract the customer feedback text from the JSON document.
* Filter rows where the JSON text contains a keyword.
* Calculate a fuzzy similarity score between the feedback text and a known issue description.
* Order the results by similarity score, with the highest score first.
Hotspot Question
You need to create a table in the database to store the telemetry data.
You have the following Transact-SQL code.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
NEW QUESTION # 35
You have an Azure SQL database That contains a table named dbo.Products, dbo.Products contains three columns named Embedding Category, and Price. The Embedding column is defined as VECTOR(1536).
You use Ai_GENERME_EMBEDOINGS and VECTOR_SEARCH to support semantic search and apply additional filters on two columns named Category and Price.
You plan to change the embedding model from text-embedding-ada-002 to text-embedding-3-smalL Existing rows already contain embeddings in the Embedding column.
You need to implement the model change. Applications must be able to use VECTOR_SEARCH without runtime errors.
What should you do first?
Answer: A
Explanation:
When you change embedding models, the stored vectors should be treated as belonging to a different embedding space unless you intentionally keep the entire corpus consistent. Microsoft's vector guidance notes that when most or all embeddings are replaced with fresh embeddings from a new model, the recommended practice is to reload the new embeddings and, for large-scale replacement scenarios, consider dropping and recreating the vector index afterward so search quality remains predictable.
This question also says applications must continue to use VECTOR_SEARCH without runtime errors .
VECTOR_SEARCH requires compatible vector dimensions, and the vector column already exists. Azure OpenAI documentation shows that text-embedding-ada-002 is fixed at 1536 dimensions and text- embedding-3-small supports up to 1536 dimensions . That means the migration can remain compatible with a VECTOR(1536) column, but the right implementation step is still to re-embed the existing rows so the table does not contain a mixed corpus produced by different models.
The other options are not appropriate:
* B normalization does not solve a model migration problem.
* C converting the vector column to nvarchar(max) would break vector-native search design.
* D a vector index improves performance, but it does not migrate old embeddings to the new model.
NEW QUESTION # 36
......
DP-800 Valid Examcollection: https://www.itpassleader.com/Microsoft/DP-800-dumps-pass-exam.html
DOWNLOAD the newest ITPassLeader DP-800 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1t4-G-201fCtPjM6LYGp2klvWUp2l-0vj