ちなみに、ShikenPASS DP-100の一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=1mJPuAFgj7M66jQDeCCXDky-ScI4_IGaF
すべての働く人は、DP-100がこの分野で支配的な人物であり、また彼らのキャリアに役立つことを知っています。 DP-100信頼性の高い試験ブートキャンプが試験に合格し、資格証明書を取得するのに役立つ場合、より良いキャリア、より良い人生を得ることができます。 私たちの研究DP-100ガイド資料は、最新のDP-100テストの質問と回答のほとんどを網羅しています。 確かにこの分野で何か違うことをしようと決心しているなら、役に立つ認定はあなたのキャリアの足がかりになるでしょう。
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Designing and Implementing a Data Science Solution on Azure |
| Exam Number: | DP-100 |
| Real Exam Qty: | 40-60 |
| Passing Score: | 700/1000 |
| Available Languages: | Spanish, Chinese (Simplified), English, German, Portuguese, Korean, Japanese, French |
| Exam Format: | Multiple Choice, Lab, Case Study, Drag and Drop, Interactive Tasks |
| Certificate Validity Period: | 1 year |
| Exam Duration: | 100 minutes |
| Related Certifications: | Microsoft Certified: Azure Data Scientist Associate |
| Exam Price: | $165 USD |
| Sample Questions: | Microsoft DP-100 Sample Questions |
| Exam Way: | Online proctored exam or test center delivery through Pearson VUE. |
| Pre Condition: | Candidates should have experience with Azure services, Python programming, and machine learning frameworks such as Scikit-Learn, PyTorch, or TensorFlow. |
| Official Syllabus URL: | https://learn.microsoft.com/en-us/credentials/certifications/exams/dp-100/ |
ここ数年、DP-100復習教材は、無数の受験者がDP-100試験に合格するのに役立ちました。DP-100認定資格証明書を取得した後、仕事機会が増え、偉大な企業家になり、専門家になった人もいました。DP-100復習教材は多くのいい評価をもらいました。良い評判で、DP-100復習教材を選択する人がますます増えています。
Microsoft DP-100の認定を取得することで、雇用主や顧客にデータサイエンスソリューションをAzure上で設計・実装するスキルと知識を持っていることを示します。また、最新の技術やベストプラクティスについての継続的な学習と最新の技術に追いつく意欲を持っていることも示します。
Microsoft DP-100試験は、Microsoft Azureを使用してデータソリューションを設計および実装するデータプロフェッショナルがスキルを開発するための必須認定資格です。この認定資格は、データ探索、データ準備、データモデリング、機械学習、およびデータ可視化を含むデータサイエンスのさまざまな側面に関する候補者の知識を検証します。DP-100の認定資格は、グローバルに認められており、候補者がより良い就職機会とキャリア成長を実現するのに役立ちます。
質問 # 354
You create an Azure Machine Learning workspace. You use the Azure Machine Learning SDK for Python.
You must create a dataset from remote paths. The dataset must be reusable within the workspace.
You need to create the dataset.
How should you complete the following code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.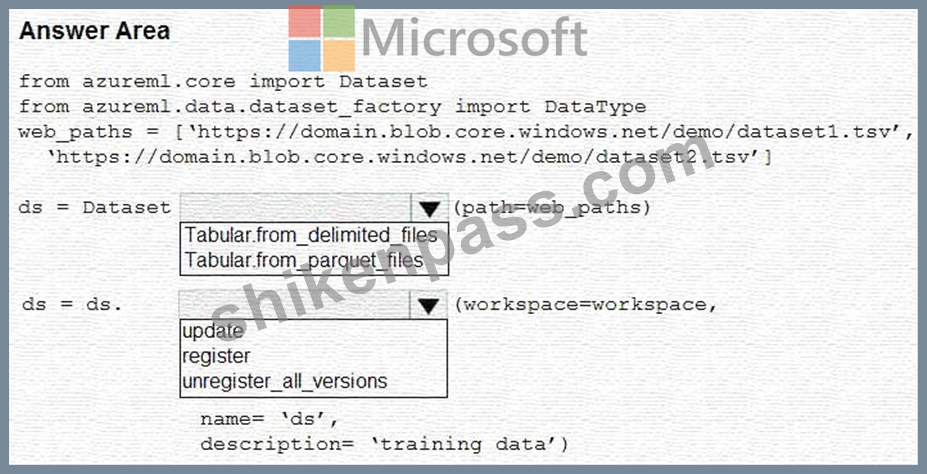
正解:
解説:
Explanation: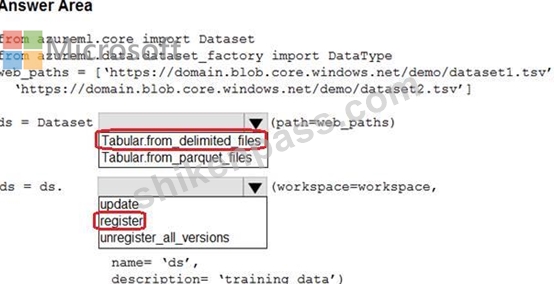
質問 # 355
You need to select an environment that will meet the business and data requirements.
Which environment should you use?
正解:C
解説:
Topic 1, Case Study 1
Overview
You are a data scientist in a company that provides data science for professional sporting events. Models will be global and local market data to meet the following business goals:
*Understand sentiment of mobile device users at sporting events based on audio from crowd reactions.
*Access a user's tendency to respond to an advertisement.
*Customize styles of ads served on mobile devices.
*Use video to detect penalty events.
Current environment
Requirements
* Media used for penalty event detection will be provided by consumer devices. Media may include images and videos captured during the sporting event and snared using social media. The images and videos will have varying sizes and formats.
* The data available for model building comprises of seven years of sporting event media. The sporting event media includes: recorded videos, transcripts of radio commentary, and logs from related social media feeds feeds captured during the sporting events.
*Crowd sentiment will include audio recordings submitted by event attendees in both mono and stereo Formats.
Advertisements
* Ad response models must be trained at the beginning of each event and applied during the sporting event.
* Market segmentation nxxlels must optimize for similar ad resporr.r history.
* Sampling must guarantee mutual and collective exclusivity local and global segmentation models that share the same features.
* Local market segmentation models will be applied before determining a user's propensity to respond to an advertisement.
* Data scientists must be able to detect model degradation and decay.
* Ad response models must support non linear boundaries features.
* The ad propensity model uses a cut threshold is 0.45 and retrains occur if weighted Kappa deviates from 0.1
+/-5%.
* The ad propensity model uses cost factors shown in the following diagram: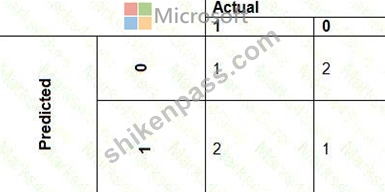
The ad propensity model uses proposed cost factors shown in the following diagram: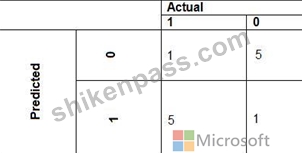
Performance curves of current and proposed cost factor scenarios are shown in the following diagram: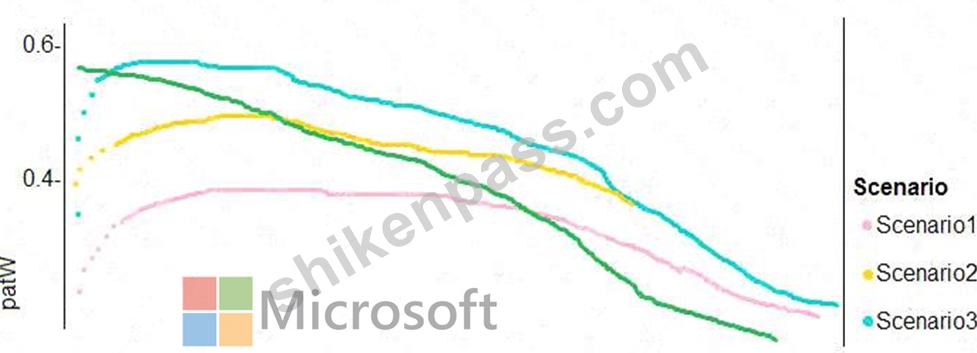
Penalty detection and sentiment
Findings
*Data scientists must build an intelligent solution by using multiple machine learning models for penalty event detection.
*Data scientists must build notebooks in a local environment using automatic feature engineering and model building in machine learning pipelines.
*Notebooks must be deployed to retrain by using Spark instances with dynamic worker allocation
*Notebooks must execute with the same code on new Spark instances to recode only the source of the data.
*Global penalty detection models must be trained by using dynamic runtime graph computation during training.
*Local penalty detection models must be written by using BrainScript.
* Experiments for local crowd sentiment models must combine local penalty detection data.
* Crowd sentiment models must identify known sounds such as cheers and known catch phrases. Individual crowd sentiment models will detect similar sounds.
* All shared features for local models are continuous variables.
* Shared features must use double precision. Subsequent layers must have aggregate running mean and standard deviation metrics Available.
segments
During the initial weeks in production, the following was observed:
*Ad response rates declined.
*Drops were not consistent across ad styles.
*The distribution of features across training and production data are not consistent.
Analysis shows that of the 100 numeric features on user location and behavior, the 47 features that come from location sources are being used as raw features. A suggested experiment to remedy the bias and variance issue is to engineer 10 linearly uncorrected features.
Penalty detection and sentiment
*Initial data discovery shows a wide range of densities of target states in training data used for crowd sentiment models.
*All penalty detection models show inference phases using a Stochastic Gradient Descent (SGD) are running too stow.
*Audio samples show that the length of a catch phrase varies between 25%-47%, depending on region.
*The performance of the global penalty detection models show lower variance but higher bias when comparing training and validation sets. Before implementing any feature changes, you must confirm the bias and variance using all training and validation cases.
質問 # 356
You create an Azure Machine Learning workspace and a new Azure DevOps organization. You register a model in the workspace and deploy the model to the target environment.
All new versions of the model registered in the workspace must automatically be deployed to the target environment.
You need to configure Azure Pipelines to deploy the model.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.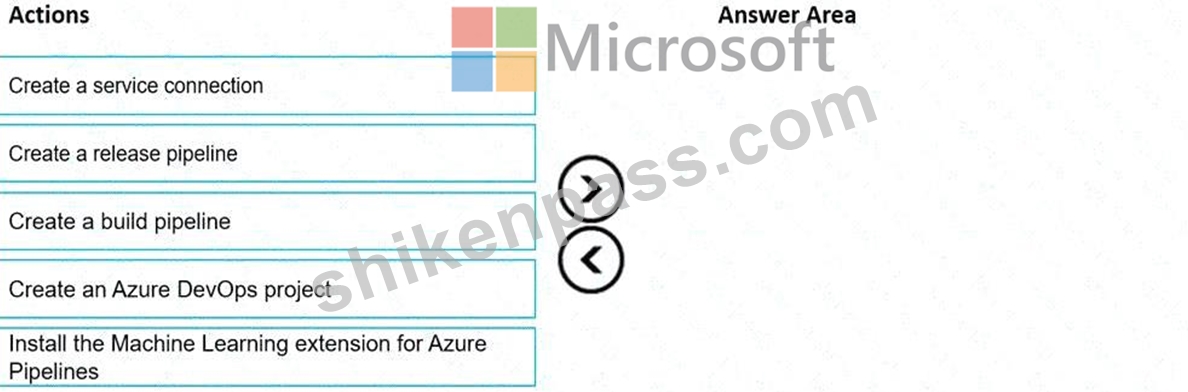
正解:
解説: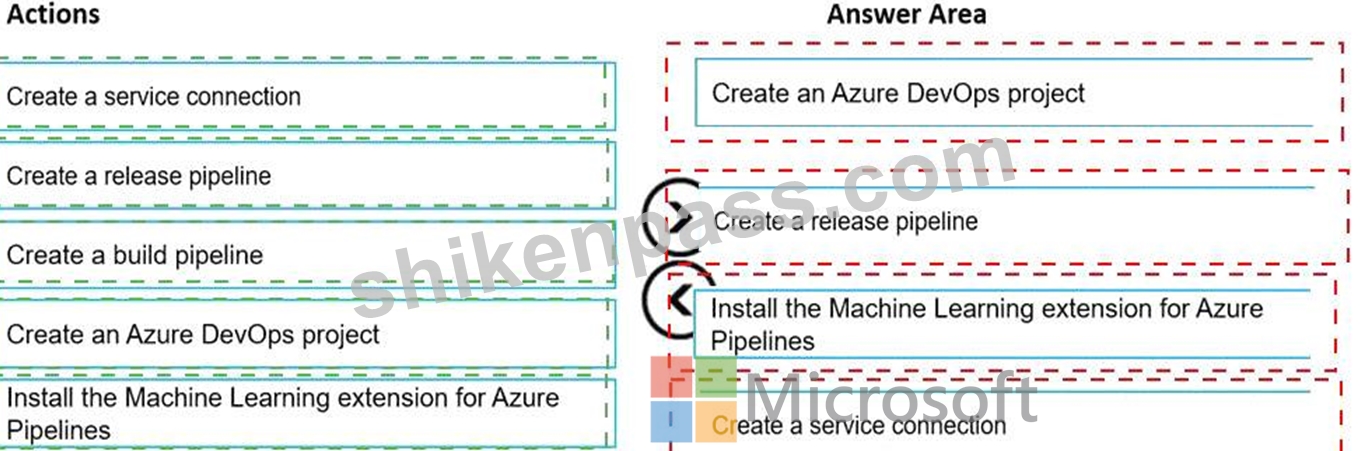
Explanation: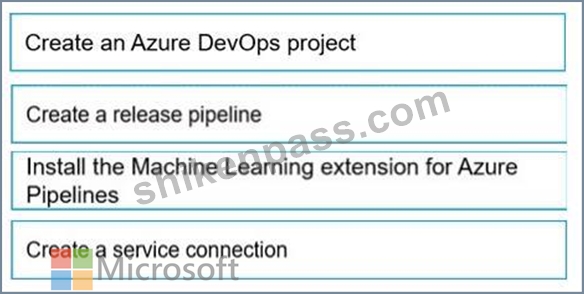
Step 1: Create an Azure DevOps project
Step 2: Create a release pipeline
Sign in to your Azure DevOps organization and navigate to your project.
Go to Pipelines, and then select New pipeline.
Step 3: Install the Machine Learning extension for Azure Pipelines
You must install and configure the Azure CLI and ML extension.
Step 4: Create a service connection
How to set up your service connection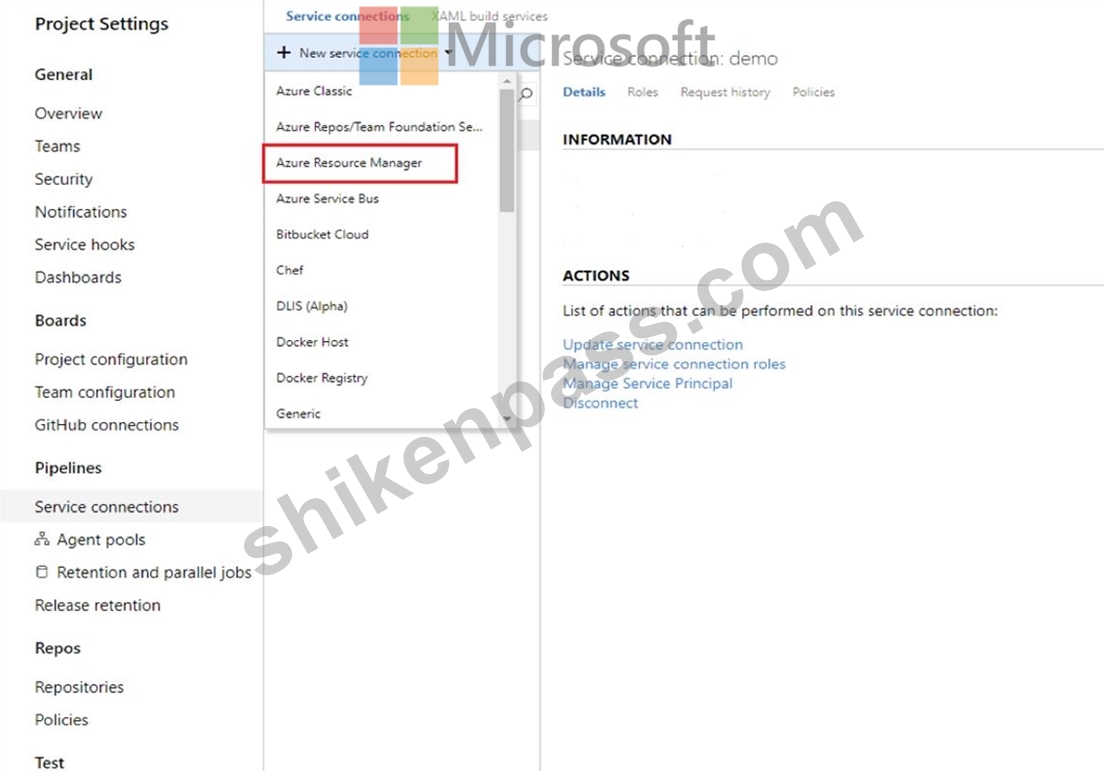
Select AzureMLWorkspace for the scope level, then fill in the following subsequent parameters.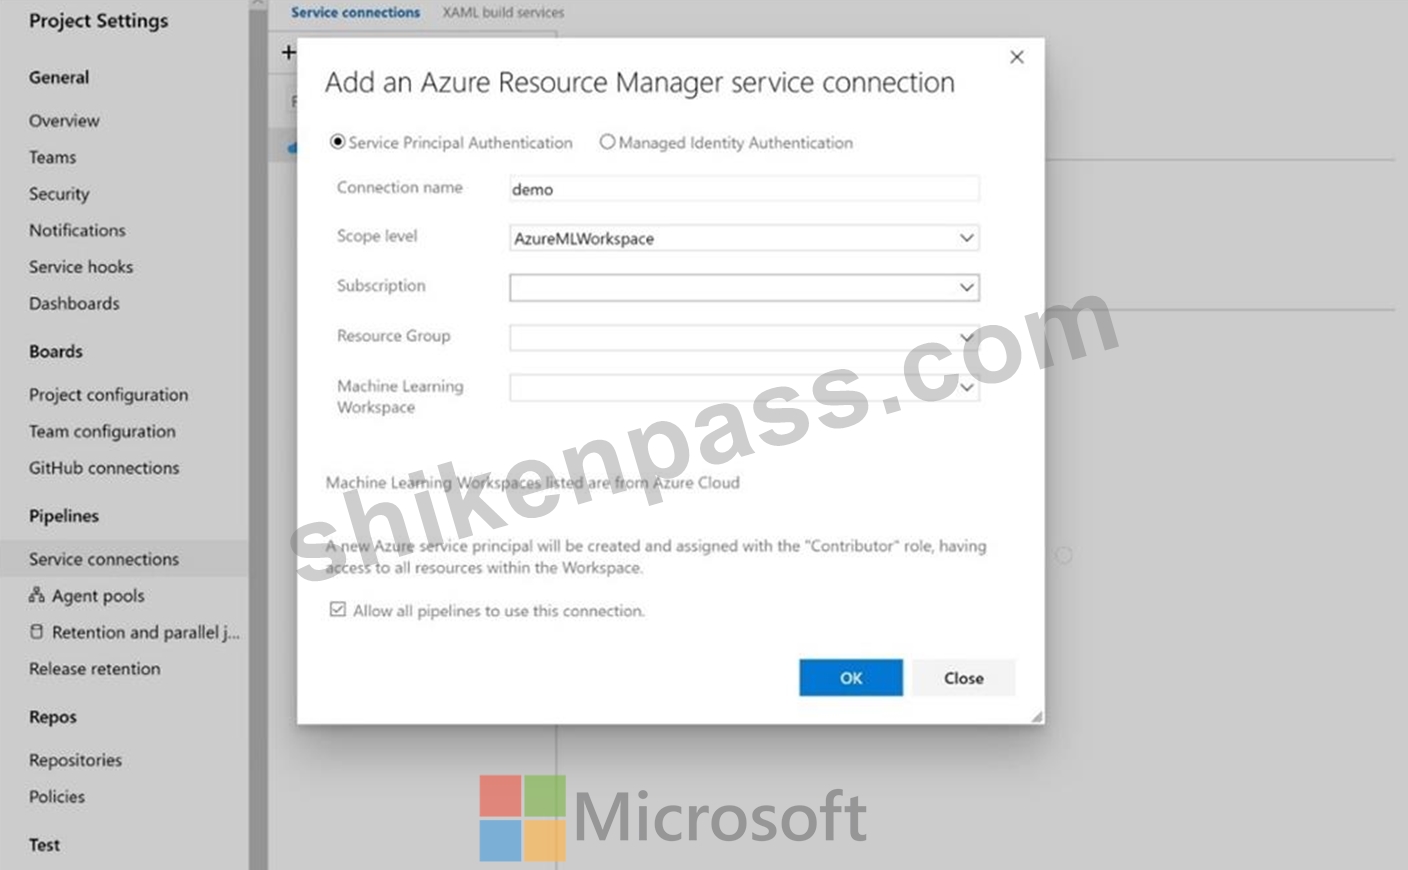
Note: How to enable model triggering in a release pipeline
Go to your release pipeline and add a new artifact. Click on AzureML Model artifact then select the appropriate AzureML service connection and select from the available models in your workspace.
Enable the deployment trigger on your model artifact as shown here. Every time a new version of that model is registered, a release pipeline will be triggered.
Reference:
https://marketplace.visualstudio.com/items?itemName=ms-air-aiagility.vss-services-azureml
https://docs.microsoft.com/en-us/azure/devops/pipelines/targets/azure-machine-learning
質問 # 357 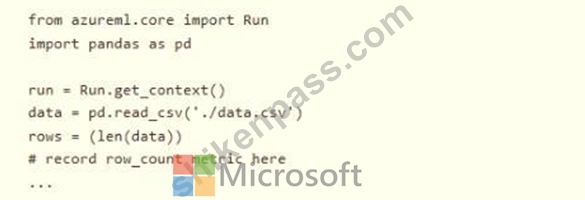
You need to record the row count as a metric named row_count that can be returned using the get_metrics method of the Run object after the experiment run completes. Which code should you use?
正解:D
解説:
Log a numerical or string value to the run with the given name using log(name, value, description=''). Logging a metric to a run causes that metric to be stored in the run record in the experiment. You can log the same metric multiple times within a run, the result being considered a vector of that metric.
Example: run.log("accuracy", 0.95)
Reference:
https://docs.microsoft.com/en-us/python/api/azureml-core/azureml.core.run
質問 # 358
You are building a recurrent neural network to perform a binary classification. You review the training loss, validation loss, training accuracy, and validation accuracy for each training epoch.
You need to analyze model performance.
Which observation indicates that the classification model is over fitted?
正解:C
質問 # 359
......
DP-100受験料: https://www.shikenpass.com/DP-100-shiken.html
無料でクラウドストレージから最新のShikenPASS DP-100 PDFダンプをダウンロードする:https://drive.google.com/open?id=1mJPuAFgj7M66jQDeCCXDky-ScI4_IGaF