Test Databricks-Certified-Data-Engineer-Professional Guide Online | Study Databricks-Certified-Data-Engineer-Professional Test

The software version is one of the different versions that is provided by our company, and the software version of the Databricks-Certified-Data-Engineer-Professional study materials is designed by all experts and professors who employed by our company. We can promise that the superiority of the software version is very obvious for all people. It is very possible to help all customers pass the Databricks-Certified-Data-Engineer-Professional Exam and get the related certification successfully.
| Section | Weight | Objectives |
|---|
| Topic 1: Monitoring and Troubleshooting | 16% | - Monitoring
- Troubleshooting
- Performance Optimization
|
| Topic 2: Data Quality and Governance | 12% | - Data Quality
- Governance
- Data Lineage
|
| Topic 3: Data Processing | 28% | - Structured Streaming
- Data Transformation
- Spark SQL
- ETL Pipelines
|
| Topic 4: Databricks Lakehouse Platform | 24% | - Delta Lake
- Unity Catalog
- Lakehouse Architecture
- Data Management
|
| Topic 5: Data Modeling and Storage | 20% | - File Formats
- Storage Optimization
- Data Modeling
|
>> Test Databricks-Certified-Data-Engineer-Professional Guide Online <<
Real Databricks Databricks-Certified-Data-Engineer-Professional Questions Download Databricks-Certified-Data-Engineer-Professional Exam Demo Free
After seeing you struggle, CertkingdomPDF has come up with an idea to provide you with the actual and updated Databricks Databricks-Certified-Data-Engineer-Professional practice questions so you can pass the Databricks-Certified-Data-Engineer-Professional certification test on the first try and your hard work doesn't go to waste. Updated Databricks-Certified-Data-Engineer-Professional Exam Dumps are essential to pass the Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) certification exam so you can advance your career in the technology industry and get a job in a good company that pays you well.
Databricks Certified Data Engineer Professional Exam Sample Questions (Q215-Q220):
NEW QUESTION # 215
The data science team has requested assistance in accelerating queries on free form text from user reviews. The data is currently stored in Parquet with the below schema:
item_id INT, user_id INT, review_id INT, rating FLOAT, review STRING
The review column contains the full text of the review left by the user. Specifically, the data science team is looking to identify if any of 30 key words exist in this field.
A junior data engineer suggests converting this data to Delta Lake will improve query performance.
Which response to the junior data engineer's suggestion is correct?
- A. Text data cannot be stored with Delta Lake.
- B. ZORDER ON review will need to be run to see performance gains.
- C. Delta Lake statistics are only collected on the first 4 columns in a table.
- D. Delta Lake statistics are not optimized for free text fields with high cardinality.
- E. The Delta log creates a term matrix for free text fields to support selective filtering.
Answer: D
Explanation:
Converting the data to Delta Lake may not improve query performance on free text fields with high cardinality, such as the review column. This is because Delta Lake collects statistics on the minimum and maximum values of each column, which are not very useful for filtering or skipping data on free text fields. Moreover, Delta Lake collects statistics on the first 32 columns by default, which may not include the review column if the table has more columns. Therefore, the junior data engineer's suggestion is not correct. A better approach would be to use a full-text search engine, such as Elasticsearch, to index and query the review column. Alternatively, you can use natural language processing techniques, such as tokenization, stemming, and lemmatization, to preprocess the review column and create a new column with normalized terms that can be used for filtering or skipping data.
NEW QUESTION # 216
A query is taking too long to run. After investigating the Spark UI, the data engineer discovered a significant amount of disk spill. The compute instance being used has a core-to-memory ratio of
1:2. What are the two steps the data engineer should take to minimize spillage? (Choose two.)
- A. Increase spark.sql.files.maxPartitionBytes.
- B. Choose a compute instance with more network bandwidth.
- C. Choose a compute instance with a higher core-to-memory ratio.
- D. Choose a compute instance with more disk space.
- E. Reduce spark.sql.files.maxPartitionBytes.
Answer: C,E
Explanation:
Databricks recommends addressing disk spilling--which occurs when Spark tasks run out of memory--by increasing memory per core and controlling partition size. Selecting an instance type with a higher memory-to-core ratio (A) provides each task with more available RAM, directly reducing the chance of spilling to disk. Additionally, reducing spark.sql.files.maxPartitionBytes (D) creates smaller partitions, preventing any single task from holding too much data in memory.
Increasing partition size (C) or disk capacity (B) does not solve memory bottlenecks, and bandwidth (E) affects network I/O, not spill behavior. Therefore, the correct actions are A and D.
NEW QUESTION # 217
An external object storage container has been mounted to the location /mnt/finance_eda_bucket.
The following logic was executed to create a database for the finance team:
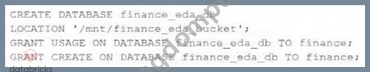
After the database was successfully created and permissions configured, a member of the finance team runs the following code:
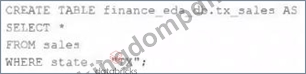
If all users on the finance team are members of the finance group, which statement describes how the tx_sales table will be created?
- A. An managed table will be created in the storage container mounted to /mnt/finance_eda_bucket.
- B. An external table will be created in the storage container mounted to /mnt/finance eda bucket.
- C. A logical table will persist the query plan to the Hive Metastore in the Databricks control plane.
- D. A managed table will be created in the DBFS root storage container.
- E. A logical table will persist the physical plan to the Hive Metastore in the Databricks control plane.
Answer: A
Explanation:
https://docs.databricks.com/en/data-governance/unity-catalog/create-schemas.html#language- SQL
NEW QUESTION # 218
A data pipeline uses Structured Streaming to ingest data from kafka to Delta Lake. Data is being stored in a bronze table, and includes the Kafka_generated timesamp, key, and value. Three months after the pipeline is deployed the data engineering team has noticed some latency issued during certain times of the day.
A senior data engineer updates the Delta Table's schema and ingestion logic to include the current timestamp (as recoded by Apache Spark) as well the Kafka topic and partition. The team plans to use the additional metadata fields to diagnose the transient processing delays.
Which limitation will the team face while diagnosing this problem?
- A. New fields cannot be added to a production Delta table.
- B. New fields will not be computed for historic records.
- C. Spark cannot capture the topic partition fields from the kafka source.
- D. Updating the table schema will invalidate the Delta transaction log metadata.
- E. Updating the table schema requires a default value provided for each file added.
Answer: B
Explanation:
When adding new fields to a Delta table's schema, these fields will not be retrospectively applied to historical records that were ingested before the schema change. Consequently, while the team can use the new metadata fields to investigate transient processing delays moving forward, they will be unable to apply this diagnostic approach to past data that lacks these fields.
NEW QUESTION # 219
A data engineering team is implementing an append-only data pipeline using Delta Lake, and wants to ensure that data is never modified or deleted once written. Which Delta Lake feature should the data engineer enable to prevent modifications to existing data?
- A. Delta VACUUM
- B. Delta Time Travel
- C. Delta OPTIMIZE
- D. Delta APPEND_ONLY
Answer: D
Explanation:
Enabling the append-only table property enforces that data can only be inserted into the Delta table. Updates and deletes are blocked, ensuring that once data is written it is never modified or removed, which is essential for strict append-only pipeline guarantees.
NEW QUESTION # 220
......
We know how expensive it is to take Databricks-Certified-Data-Engineer-Professional exam. It costs both time and money. However, with the most reliable exam dumps material from CertkingdomPDF, we guarantee that you will pass the Databricks-Certified-Data-Engineer-Professional exam on your first try! You’ve heard it right. We are so confident about our Databricks-Certified-Data-Engineer-Professional Exam Dumps for Databricks Databricks-Certified-Data-Engineer-Professional exam that we are offering a money back guarantee, if you fail. Yes you read it right, if our Databricks-Certified-Data-Engineer-Professional exam braindumps didn’t help you pass, we will issue a refund - no other questions asked.
Study Databricks-Certified-Data-Engineer-Professional Test: https://www.certkingdompdf.com/Databricks-Certified-Data-Engineer-Professional-latest-certkingdom-dumps.html
- Databricks-Certified-Data-Engineer-Professional Real Brain Dumps 🔰 High Databricks-Certified-Data-Engineer-Professional Quality 🔝 Databricks-Certified-Data-Engineer-Professional Practice Exam Questions 👤 Simply search for 《 Databricks-Certified-Data-Engineer-Professional 》 for free download on ▶ www.exam4labs.com ◀ 🦲Practice Databricks-Certified-Data-Engineer-Professional Test Online
- Reliable Databricks-Certified-Data-Engineer-Professional Actual Test Dumps PDF has 100% pass rate - Pdfvce 🦆 Search for ( Databricks-Certified-Data-Engineer-Professional ) and obtain a free download on ⏩ www.pdfvce.com ⏪ 🥑Databricks-Certified-Data-Engineer-Professional Books PDF
- New Databricks-Certified-Data-Engineer-Professional Test Practice 🤿 VCE Databricks-Certified-Data-Engineer-Professional Dumps 🧲 Relevant Databricks-Certified-Data-Engineer-Professional Exam Dumps 🏟 The page for free download of ✔ Databricks-Certified-Data-Engineer-Professional ️✔️ on 【 www.prep4away.com 】 will open immediately 🧶VCE Databricks-Certified-Data-Engineer-Professional Dumps
- High-quality Test Databricks-Certified-Data-Engineer-Professional Guide Online, Study Databricks-Certified-Data-Engineer-Professional Test 🌄 Search for 「 Databricks-Certified-Data-Engineer-Professional 」 and download exam materials for free through ▷ www.pdfvce.com ◁ 🕵Databricks-Certified-Data-Engineer-Professional Books PDF
- Databricks-Certified-Data-Engineer-Professional Test Free 🦜 Databricks-Certified-Data-Engineer-Professional Practice Exam Questions 👔 Databricks-Certified-Data-Engineer-Professional Practice Exam Questions 🚨 Easily obtain ⏩ Databricks-Certified-Data-Engineer-Professional ⏪ for free download through ⏩ www.testkingpass.com ⏪ 🌸Databricks-Certified-Data-Engineer-Professional Books PDF
- 2026 Test Databricks-Certified-Data-Engineer-Professional Guide Online 100% Pass | Latest Study Databricks-Certified-Data-Engineer-Professional Test: Databricks Certified Data Engineer Professional Exam 🕚 ( www.pdfvce.com ) is best website to obtain ▶ Databricks-Certified-Data-Engineer-Professional ◀ for free download 🐇Exam Databricks-Certified-Data-Engineer-Professional Quick Prep
- Databricks-Certified-Data-Engineer-Professional Latest Dumps: Databricks Certified Data Engineer Professional Exam - Databricks Certified Data Engineer Professional Exam Exam Cram 🏬 Search for ▷ Databricks-Certified-Data-Engineer-Professional ◁ and download exam materials for free through { www.troytecdumps.com } 🚼Databricks-Certified-Data-Engineer-Professional Download Free Dumps
- Certificate Databricks-Certified-Data-Engineer-Professional Exam 👧 Databricks-Certified-Data-Engineer-Professional Test Free 🍇 Databricks-Certified-Data-Engineer-Professional Practice Exam Questions ✅ Search for ➠ Databricks-Certified-Data-Engineer-Professional 🠰 and obtain a free download on [ www.pdfvce.com ] 👮Databricks-Certified-Data-Engineer-Professional Practice Exam Questions
- Free PDF Databricks - Databricks-Certified-Data-Engineer-Professional - Reliable Test Databricks Certified Data Engineer Professional Exam Guide Online 🐎 Search on ▷ www.examcollectionpass.com ◁ for ➥ Databricks-Certified-Data-Engineer-Professional 🡄 to obtain exam materials for free download 🚪Databricks-Certified-Data-Engineer-Professional Books PDF
- Valid Databricks-Certified-Data-Engineer-Professional Exam Topics 💕 Exam Databricks-Certified-Data-Engineer-Professional PDF 🥏 Databricks-Certified-Data-Engineer-Professional Download Free Dumps 🔔 Search for ➽ Databricks-Certified-Data-Engineer-Professional 🢪 and easily obtain a free download on [ www.pdfvce.com ] ⭐Relevant Databricks-Certified-Data-Engineer-Professional Exam Dumps
- Free PDF 2026 Databricks Authoritative Test Databricks-Certified-Data-Engineer-Professional Guide Online 📻 The page for free download of ☀ Databricks-Certified-Data-Engineer-Professional ️☀️ on ☀ www.exam4labs.com ️☀️ will open immediately 🦍Relevant Databricks-Certified-Data-Engineer-Professional Exam Dumps
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes