Nowadays, everyone lives so busy every day, and we believe that you are no exception. If you want to save your time, it will be the best choice for you to buy our Databricks-Certified-Professional-Data-Engineer study torrent. Because the greatest advantage of our study materials is the high effectiveness. If you buy our Databricks-Certified-Professional-Data-Engineer guide torrent and take it seriously consideration, you will find you can take your exam after twenty to thirty hours' practice. So come to buy our Databricks-Certified-Professional-Data-Engineer Test Torrent, it will help you pass your Databricks-Certified-Professional-Data-Engineer exam and get the certification in a short time that you long to own.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Ensuring Data Security and Compliance | 10% | - Access control and permissions - Compliance standards implementation - Data encryption and masking |
| Topic 2: Data Sharing and Federation | 5% | - Cross-workspace and cross-cloud access - Unity Catalog data sharing |
| Topic 3: Cost & Performance Optimisation | 13% | - Storage optimization (partitioning, Z-order, indexing) - Query optimization and caching - Cluster configuration and scaling |
| Topic 4: Data Modelling | 6% | - Medallion Architecture implementation - Schema design and management - Delta Lake table design |
| Topic 5: Developing Code for Data Processing using Python and SQL | 22% | - Batch and incremental processing logic - Data transformation and aggregation - Integration with Databricks APIs and tools |
| Topic 6: Data Governance | 7% | - Policy enforcement - Unity Catalog management - Data lineage and metadata tracking |
| Topic 7: Data Transformation, Cleansing, and Quality | 10% | - Standardization and normalization - Data validation and quality checks - Handling missing or inconsistent data |
| Topic 8: Monitoring and Alerting | 10% | - Setting up alerts and notifications - Performance and health monitoring - Pipeline observability and logging |
| Topic 9: Data Ingestion & Acquisition | 7% | - Auto Loader and streaming ingestion - Schema inference and evolution - Connecting to diverse data sources |
| Topic 10: Debugging and Deploying | 10% | - Troubleshooting pipelines and errors - Deployment using bundles, CLI, and APIs - CI/CD and DevOps practices |
>> Databricks-Certified-Professional-Data-Engineer New Question <<
I believe that people want to have good prospects of career whatever industry they work in. Of course, there is no exception in the competitive IT industry. IT Professionals working in the IT area also want to have good opportunities for promotion of job and salary. A lot of IT professional know that Databricks Certification Databricks-Certified-Professional-Data-Engineer Exam can help you meet these aspirations. BootcampPDF is a website which help you successfully pass Databricks Databricks-Certified-Professional-Data-Engineer.
NEW QUESTION # 122
A data engineer wants to create a cluster using the Databricks CLI for a big ETL pipeline. The cluster should have five workers, one driver of type i3.xlarge, and should use the '14.3.x-scala2.12' runtime.
Which command should the data engineer use?
Answer: C
Explanation:
The Databricks CLI allows users to manage clusters using command-line commands. The correct command for creating a cluster follows a specific format.
Key Components in the Command:
* Command Type: databricks compute create is the correct syntax for creating a new compute resource (cluster).
* Runtime Version: '14.3.x-scala2.12' specifies the Databricks runtime to use.
* Workers: --num-workers 5 sets the number of worker nodes to 5.
* Node Type: --node-type-id i3.xlarge defines the hardware configuration.
* Cluster Name: --cluster-name DataEngineer_cluster assigns a recognizable name to the cluster.
Evaluation of Options:
* Option A (databricks clusters create ...)
* Incorrect: databricks clusters create is not a valid command in the Databricks CLI v0.205.
* The correct CLI command for cluster creation is databricks compute create.
* Option B (databricks clusters add ...)
* Incorrect: databricks clusters add is not a valid CLI command.
* Option C (databricks compute add ...)
* Incorrect: databricks compute add is not a valid CLI command.
* Option D (databricks compute create ...)
* Correct: databricks compute create is the correct command for creating a cluster.
Conclusion:
The correct command to create a cluster with five workers, an i3.xlarge node type, and Databricks runtime
14.3.x-scala2.12 is:
databricks compute create 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster-name Data Engineer_cluster Thus, the correct answer is D.
References:
Databricks CLI Documentation
NEW QUESTION # 123
Which statement describes integration testing?
Answer: D
Explanation:
This is the correct answer because it describes integration testing. Integration testing is a type of testing that validates interactions between subsystems of your application, such as modules, components, or services.
Integration testing ensures that the subsystems work together as expected and produce the correct outputs or results. Integration testing can be done at different levels of granularity, such as component integration testing, system integration testing, or end-to-end testing. Integration testing can help detect errors or bugs that may not be found by unit testing, which only validates behavior of individual elements of your application. Verified References: [Databricks Certified Data Engineer Professional], under "Testing" section; Databricks Documentation, under "Integration testing" section.
NEW QUESTION # 124
When scheduling Structured Streaming jobs for production, which configuration automatically recovers from query failures and keeps costs low?
Answer: D
Explanation:
The configuration that automatically recovers from query failures and keeps costs low is to use a new job cluster, set retries to unlimited, and set maximum concurrent runs to 1. This configuration has the following advantages:
* A new job cluster is a cluster that is created and terminated for each job run. This means that the cluster resources are only used when the job is running, and no idle costs are incurred. This also ensures that the cluster is always in a clean state and has the latest configuration and libraries for the job1.
* Setting retries to unlimited means that the job will automatically restart the query in case of any failure, such as network issues, node failures, or transient errors. This improves the reliability and availability of the streaming job, and avoids data loss or inconsistency2.
* Setting maximum concurrent runs to 1 means that only one instance of the job can run at a time. This prevents multiple queries from competing for the same resources or writing to the same output location, which can cause performance degradation or data corruption3.
Therefore, this configuration is the best practice for scheduling Structured Streaming jobs for production, as it ensures that the job is resilient, efficient, and consistent.
References: Job clusters, Job retries, Maximum concurrent runs
NEW QUESTION # 125
Which of the following describes how Databricks Repos can help facilitate CI/CD workflows on the Databricks Lakehouse Platform?
Answer: D
Explanation:
Explanation
Answer is Databricks Repos can commit or push code changes to trigger a CI/CD process See below diagram to understand the role Databricks Repos and Git provider plays when building a CI/CD workdlow.
All the steps highlighted in yellow can be done Databricks Repo, all the steps highlighted in Gray are done in a git provider like Github or Azure Devops.
Diagram Description automatically generated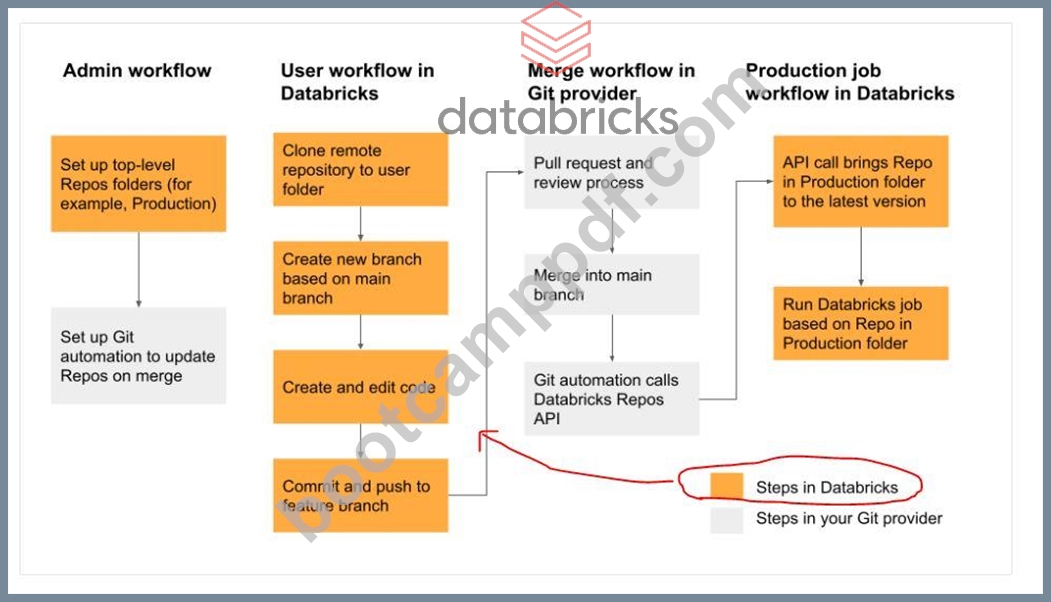
NEW QUESTION # 126
A data engineer is designing a Lakeflow Declarative Pipeline to process streaming order data. The pipeline uses Auto Loader to ingest data and must enforce data quality by ensuring customer_id and amount are greater than zero. Invalid records should be dropped.
Which Lakeflow Declarative Pipelines configurations implement this requirement using Python?
Answer: A
Explanation:
Lakeflow Declarative Pipelines (LDP), formerly Delta Live Tables (DLT), supports enforcing data quality using expectations . Expectations can either:
* Track violations (expect) # records that do not meet conditions are flagged but still included in the pipeline.
* Drop violations (expect_or_drop) # records that do not meet conditions are excluded from downstream tables.
* Fail pipeline on violations (expect_or_fail) # records that fail conditions stop the pipeline.
In this scenario, the requirement explicitly states that invalid records (where customer_id is null or amount #
0) must be dropped . According to the official documentation, the correct method is .expect_or_drop( " expectation_name " , " SQL_predicate " ) applied on the streaming input.
* Option A is correct: It uses .expect_or_drop directly within the transformation chain for both rules, ensuring records that fail are removed before writing to the silver table.
* Option B incorrectly uses @dlt.expect decorators, which only track violations but do not drop invalid rows.
* Option C uses .expect, which also only flags rows, not drop them.
* Option D uses @dlt.expect_or_drop decorator syntax, which is not supported in Python API; expect_or_drop must be applied as a method on the DataFrame, not as a decorator.
Therefore, the correct solution is Option A , which ensures compliance by enforcing data quality and dropping invalid rows programmatically during ingestion.
Reference: Databricks Lakeflow Declarative Pipelines Documentation - Expectations (expect, expect_or_drop, expect_or_fail)
NEW QUESTION # 127
......
A second format is a Databricks-Certified-Professional-Data-Engineer web-based practice exam that can take for self-assessment. However, it differs from desktop-based Databricks-Certified-Professional-Data-Engineer practice exam software as it can be taken via any browser, including Chrome, Firefox, Safari, and Opera. This Databricks Databricks-Certified-Professional-Data-Engineer web-based practice exam does not require any other plugins. You can take this Databricks-Certified-Professional-Data-Engineer self-assessment test on Windows, iOS, Linux, Mac, and Android. It also includes all of the functionalities of desktop Databricks-Certified-Professional-Data-Engineer software and will assist you in passing the Databricks-Certified-Professional-Data-Engineer certification test.
Databricks-Certified-Professional-Data-Engineer Valid Braindumps: https://www.bootcamppdf.com/Databricks-Certified-Professional-Data-Engineer_exam-dumps.html