無料でクラウドストレージから最新のJapancert Data-Engineer-Associate PDFダンプをダウンロードする:https://drive.google.com/open?id=1jZpX8BW2NFgXrFsJg2nghz7F9EQXRPHH
テストData-Engineer-Associate認定の取得は、学習プロセスの目標を達成するために必要であり、労働者のために働いており、開発のためのより広いスペースを提供できるより多くの資格を持っています。 Data-Engineer-Associateの実際の試験ガイドは、効率的で便利な学習プラットフォームを提供するため、できるだけ早く認定を取得できます。高い学位は能力の表れかもしれません。テストData-Engineer-Associate認定を取得することも良い選択です。 Data-Engineer-Associate証明書を取得すると、より良い未来を創造するための選択肢が増えます。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Store Management | 26% | - Choose a data store
|
| Topic 2: Data Security and Governance | 18% | - Implement data quality checks
|
| Topic 3: Data Ingestion and Transformation | 34% | - Transform and process data
|
| Topic 4: Data Operations and Support | 22% | - Manage and troubleshoot data processes
|
>> Data-Engineer-Associate日本語認定 <<
Japancertにあるソフトウェアバージョンは、Data-Engineer-Associate実際の試験の3つのバージョンの1つであり、当社の専門家によって設計されています。 ソフトウェアバージョンの機能は非常に特殊です。 たとえば、ソフトウェアバージョンは実際の試験環境をシミュレートできます。 Data-Engineer-Associate試験問題を購入すると、同様の実際の試験環境を楽しむことができます。 また、教材のソフトウェアバージョンは、コンピューターの数に限定されません。 Data-Engineer-Associate準備試験をためらわずに購入してください。多くのメリットが得られ、Data-Engineer-Associate試験に確実に合格します。
質問 # 154
A data engineer needs to create an Amazon Athena table based on a subset of data from an existing Athena table named cities_world. The cities_world table contains cities that are located around the world. The data engineer must create a new table named cities_us to contain only the cities from cities_world that are located in the US.
Which SQL statement should the data engineer use to meet this requirement?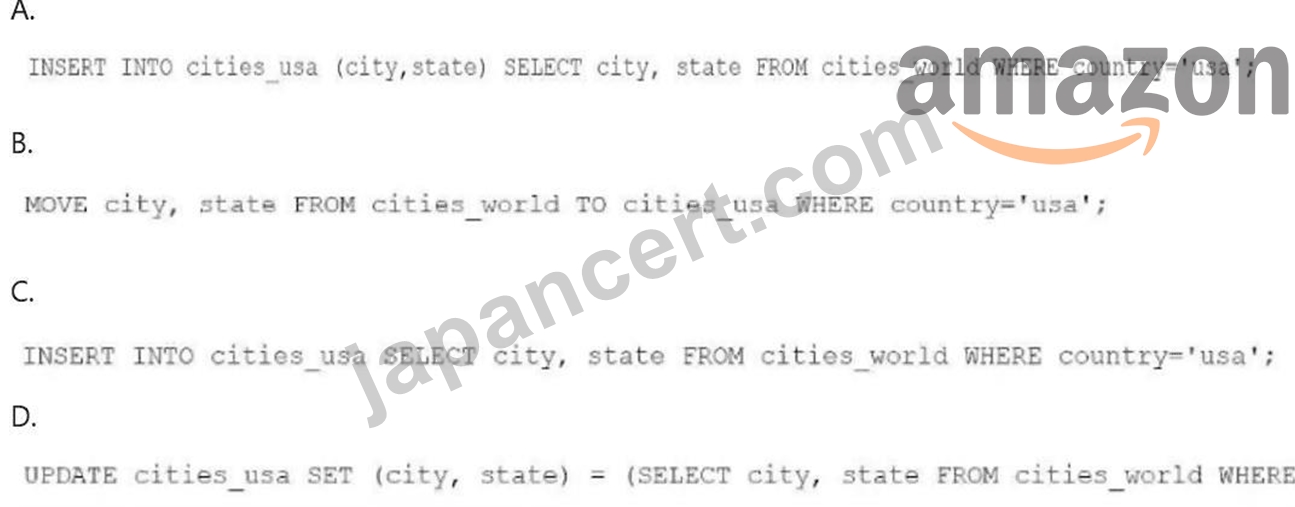
正解:B
解説:
To create a new table named cities_usa in Amazon Athena based on a subset of data from the existing cities_world table, you should use an INSERT INTO statement combined with a SELECT statement to filter only the records where the country is ' usa ' . The correct SQL syntax would be:
Option A: INSERT INTO cities_usa (city, state) SELECT city, state FROM cities_world WHERE country= ' usa ' ;This statement inserts only the cities and states where the country column has a value of ' usa ' from the cities_world table into the cities_usa table. This is a correct approach to create a new table with data filtered from an existing table in Athena.
Options B, C, and D are incorrect due to syntax errors or incorrect SQL usage (e.g., the MOVE command or the use of UPDATE in a non-relevant context).
References:
Amazon Athena SQL Reference
Creating Tables in Athena
質問 # 155
A telecommunications company collects network usage data throughout each day at a rate of several thousand data points each second. The company runs an application to process the usage data in real time. The company aggregates and stores the data in an Amazon Aurora DB instance.
Sudden drops in network usage usually indicate a network outage. The company must be able to identify sudden drops in network usage so the company can take immediate remedial actions.
Which solution will meet this requirement with the LEAST latency?
正解:B
解説:
The telecommunications company needs a low-latency solution to detect sudden drops in network usage from real-time data collected throughout the day.
* Option B: Modify the processing application to publish the data to an Amazon Kinesis data stream. Create an Amazon Managed Service for Apache Flink (Amazon Kinesis Data Analytics) application to detect drops in network usage.Using Amazon Kinesis with Managed Service for Apache Flink (formerly Kinesis Data Analytics) is ideal for real-time stream processing with minimal latency. Flink can analyze the incoming data stream in real-time and detect anomalies, such as sudden drops in usage, which makes it the best fit for this scenario.
Other options (A, C, and D) either introduce unnecessary delays (e.g., querying databases) or do not provide the same real-time, low-latency processing that is critical for this use case.
References:
* Amazon Kinesis Data Analytics for Apache Flink
* Amazon Kinesis Documentation
質問 # 156
A company uses AWS Glue Data Catalog to index data that is uploaded to an Amazon S3 bucket every day.
The company uses a daily batch processes in an extract, transform, and load (ETL) pipeline to upload data from external sources into the S3 bucket.
The company runs a daily report on the S3 data. Some days, the company runs the report before all the daily data has been uploaded to the S3 bucket. A data engineer must be able to send a message that identifies any incomplete data to an existing Amazon Simple Notification Service (Amazon SNS) topic.
Which solution will meet this requirement with the LEAST operational overhead?
正解:C
解説:
AWS Glue workflows are designed to orchestrate the ETL pipeline, and you can createdata quality checksto ensure the uploaded datasets are complete before running reports. If there is an issue with the data, AWS Glue workflows can trigger anAmazon EventBridge eventthat sends a message to anSNS topic.
* AWS Glue Workflows:
* AWS Glue workflows allow users to automate and monitor complex ETL processes. You can includedata quality actionsto check for null values, data types, and other consistency checks.
* In the event of incomplete data, anEventBridgeevent can be generated to notify via SNS.
Reference:AWS Glue Workflows
Alternatives Considered:
A (Airflow cluster): Managed Airflow introduces more operational overhead and complexity compared to Glue workflows.
B (EMR cluster): Setting up an EMR cluster is also more complex compared to the Glue-centric solution.
D (Lambda functions): While Lambda functions can work, using Glue workflows offers a more integrated and lower operational overhead solution.
References:
AWS Glue Workflow Documentation
質問 # 157
A company stores data from an application in an Amazon DynamoDB table that operates in provisioned capacity mode. The workloads of the application have predictable throughput load on a regular schedule.
Every Monday, there is an immediate increase in activity early in the morning. The application has very low usage during weekends.
The company must ensure that the application performs consistently during peak usage times.
Which solution will meet these requirements in the MOST cost-effective way?
正解:A
解説:
Amazon DynamoDB is a fully managed NoSQL database service that provides fast and predictable performance with seamless scalability. DynamoDB offers two capacity modes for throughput capacity:
provisioned and on-demand. In provisioned capacity mode, you specify the number of read and write capacity units per second that you expect your application to require. DynamoDB reserves the resources to meet your throughput needs with consistent performance. In on-demand capacity mode, you pay per request and DynamoDB scales the resources up and down automatically based on the actual workload. On-demand capacity mode is suitable for unpredictable workloads that can vary significantly over time1.
The solution that meets the requirements in the most cost-effective way is to use AWS Application Auto Scaling to schedule higher provisioned capacity for peak usage times and lower capacity during off-peak times. This solution has the following advantages:
It allows you to optimize the cost and performance of your DynamoDB table by adjusting the provisioned capacity according to your predictable workload patterns. You can use scheduled scaling to specify the date and time for the scaling actions, and the new minimum and maximum capacity limits. For example, you can schedule higher capacity for every Monday morning and lower capacity for weekends2.
It enables you to take advantage of the lower cost per unit of provisioned capacity mode compared to on- demand capacity mode. Provisioned capacity mode charges a flat hourly rate for the capacity you reserve, regardless of how much you use. On-demand capacity mode charges for each read and write request you consume, with no minimum capacity required. For predictable workloads, provisioned capacity mode can be more cost-effective than on-demand capacity mode1.
It ensures that your application performs consistently during peak usage times by having enough capacity to handle the increased load. You can also use auto scaling to automatically adjust the provisioned capacity based on the actual utilization of your table, and set a target utilization percentage for your table or global secondary index. This way, you can avoid under-provisioning or over-provisioning your table2.
Option A is incorrect because it suggests increasing the provisioned capacity to the maximum capacity that is currently present during peak load times. This solution has the following disadvantages:
It wastes money by paying for unused capacity during off-peak times. If you provision the same high capacity for all times, regardless of the actual workload, you are over-provisioning your table and paying for resources that you don't need1.
It does not account for possible changes in the workload patterns over time. If your peak load times increase or decrease in the future, you may need to manually adjust the provisioned capacity to match the new demand. This adds operational overhead and complexity to your application2.
Option B is incorrect because it suggests dividing the table into two tables and provisioning each table with half of the provisioned capacity of the original table. This solution has the following disadvantages:
It complicates the data model and the application logic by splitting the data into two separate tables. You need to ensure that the queries are evenly distributed across both tables, and that the data is consistent and synchronized between them. This adds extra development and maintenance effort to your application3.
It does not solve the problem of adjusting the provisioned capacity according to the workload patterns. You still need to manually or automatically scale the capacity of each table based on the actual utilization and demand. This may result in under-provisioning or over-provisioning your tables2.
Option D is incorrect because it suggests changing the capacity mode from provisioned to on-demand. This solution has the following disadvantages:
It may incur higher costs than provisioned capacity mode for predictable workloads. On-demand capacity mode charges for each read and write request you consume, with no minimum capacity required. For predictable workloads, provisioned capacity mode can be more cost-effective than on-demand capacity mode, as you can reserve the capacity you need at a lower rate1.
It may not provide consistent performance during peak usage times, as on-demand capacity mode may take some time to scale up the resources to meet the sudden increase in demand. On-demand capacity mode uses adaptive capacity to handle bursts of traffic, but it may not be able to handle very large spikes or sustained high throughput. In such cases, you may experience throttling or increased latency.
1: Choosing the right DynamoDB capacity mode - Amazon DynamoDB
2: Managing throughput capacity automatically with DynamoDB auto scaling - Amazon DynamoDB
3: Best practices for designing and using partition keys effectively - Amazon DynamoDB
[4]: On-demand mode guidelines - Amazon DynamoDB
[5]: How to optimize Amazon DynamoDB costs - AWS Database Blog
[6]: DynamoDB adaptive capacity: How it works and how it helps - AWS Database Blog
[7]: Amazon DynamoDB pricing - Amazon Web Services (AWS)
質問 # 158
A company receives test results from testing facilities that are located around the world. The company stores the test results in millions of 1 KB JSON files in an Amazon S3 bucket. A data engineer needs to process the files, convert them into Apache Parquet format, and load them into Amazon Redshift tables. The data engineer uses AWS Glue to process the files, AWS Step Functions to orchestrate the processes, and Amazon EventBridge to schedule jobs.
The company recently added more testing facilities. The time required to process files is increasing. The data engineer must reduce the data processing time.
Which solution will MOST reduce the data processing time?
正解:A
解説:
* Problem Analysis:
* Millions of 1 KB JSON files in S3 are being processed and converted to Apache Parquet format using AWS Glue.
* Processing time is increasing due to the additional testing facilities.
* The goal is toreduce processing timewhile using the existing AWS Glue framework.
* Key Considerations:
* AWS Glue offers thedynamic frame file-groupingfeature, which consolidates small files into larger, more efficient datasets during processing.
* Grouping smaller files reduces overhead and speeds up processing.
* Solution Analysis:
* Option A: Lambda for File Grouping
* Using Lambda to group files would add complexity and operational overhead. Glue already offers built-in grouping functionality.
* Option B: AWS Glue Dynamic Frame File-Grouping
* This option directly addresses the issue by grouping small files during Glue job execution.
* Minimizes data processing time with no extra overhead.
* Option C: Redshift COPY Command
* COPY directly loads raw files but is not designed for pre-processing (conversion to Parquet).
* Option D: Amazon EMR
* While EMR is powerful, replacing Glue with EMR increases operational complexity.
* Final Recommendation:
* UseAWS Glue dynamic frame file-groupingfor optimized data ingestion and processing.
:
AWS Glue Dynamic Frames
Optimizing Glue Performance
質問 # 159
......
ITテストと認定は当面の競争が激しい世界でこれまで以上に重要になりました。それは異なる世界の未来を意味しています。AmazonのData-Engineer-Associate「AWS Certified Data Engineer - Associate (DEA-C01)」の試験はあなたの職場生涯で重要な画期的な出来事になり、新しいチャンスを発見するかもしれません。ところが、AmazonのData-Engineer-Associateの試験にどうやって合格しますか。心配することはないですよ、ヘルプがあなたの手元にありますから。Japancertを利用したら恐いことはないです。JapancertのAmazonのData-Engineer-Associate「AWS Certified Data Engineer - Associate (DEA-C01)」の試験問題と解答は試験準備のパイオニアですから。
Data-Engineer-Associate過去問題: https://www.japancert.com/Data-Engineer-Associate.html
ちなみに、Japancert Data-Engineer-Associateの一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=1jZpX8BW2NFgXrFsJg2nghz7F9EQXRPHH