Databricks Databricks-Certified-Data-Engineer-Professional Exam | Databricks-Certified-Data-Engineer-Professionalミシュレーション問題 - 100%安全なショッピング体験

さらに、Japancert Databricks-Certified-Data-Engineer-Professionalダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1awmjRaisTzrXxZlSfyJCzT3LtrM11kFz
当代社会の競争が激しいとともに、自分の生きがいを探すために、できるだけ自分の能力を生かさなければならない。IT業界でのあなたは自分の能力を高めるために、Databricks-Certified-Data-Engineer-Professional試験を準備しているのでしょう。我々はDatabricks-Certified-Data-Engineer-Professional試験に参加するつもりのあなたに最高のサービスを提供します。我々の提供するDatabricks-Certified-Data-Engineer-Professional問題集を利用して、あなたは試験に合格することができると信じています。
Databricks Databricks-Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Data Modeling and Storage | 20% | - Storage Optimization
- Data Modeling
- File Formats
|
| Databricks Lakehouse Platform | 24% | - Delta Lake
- Unity Catalog
- Lakehouse Architecture
- Data Management
|
| Data Processing | 28% | - Data Transformation
- Structured Streaming
- Spark SQL
- ETL Pipelines
|
| Data Quality and Governance | 12% | - Data Quality
- Governance
- Data Lineage
|
| Monitoring and Troubleshooting | 16% | - Troubleshooting
- Performance Optimization
- Monitoring
|
>> Databricks-Certified-Data-Engineer-Professionalミシュレーション問題 <<
Databricks-Certified-Data-Engineer-Professional模擬モード & Databricks-Certified-Data-Engineer-Professional学習教材
Japancert DatabricksのDatabricks-Certified-Data-Engineer-Professional試験スタディガイドはあなたのキャリアの灯台になれます。Japancertは全ての受かるべきDatabricks-Certified-Data-Engineer-Professional試験を含めていますから、Japancertを利用したら、あなたは試験に合格することができるようになります。これは絶対に賢明な決断です。恐い研究の中から逸することができます。Japancertがあなたのヘルパーで、Japancertを手に入れたら、半分の労力でも二倍の効果を得ることができます。
Databricks Certified Data Engineer Professional Exam 認定 Databricks-Certified-Data-Engineer-Professional 試験問題 (Q47-Q52):
質問 # 47
A data engineer is using the AUTO CDC API in Lakeflow Spark Declarative Pipeline to propagate deletions from a source table (orders_source) to a target table (orders_target). The source has Change Data Feed (CDF) enabled, but some delete events arrive out of order due to upstream delays. How does the AUTO CDC API internally ensure deletions are applied correctly despite out-of-order events?
- A. It ignores deletions if they arrive after updates for the same key.
- B. It manually sorts incoming events by timestamp before applying changes.
- C. It uses sequence_by to order events and retains tombstones for deleted rows until older sequences are processed.
- D. It runs VACUUM on the target table to purge conflicting records.
正解:C
解説:
AUTO CDC uses the sequence_by column to deterministically order change events for each key.
Delete operations create tombstones that are retained until all earlier sequence values have been processed, ensuring that out-of-order delete events are still applied correctly and consistently in the target table.
質問 # 48
A data engineer is building a customer data pipeline in Lakeflow Spark Declarative Pipelines. The source is a cloud-based event stream with limited retention containing inserts, updates, and deletes for customer records. These changes are being applied using the AUTO CDC INTO syntax to maintain an SCD Type 1 table as the target table, customer_dim. How should the data engineer build a downstream job that streams from the customer_dim table to only act on updates and delete events, processing data incrementally?
- A. Use ignoreChanges flag while streaming from customer_dim to avoid breaking the pipeline during updates and deletes.
- B. Read change data feed from customer_dim table and apply filters to incrementally act on the change events.
- C. Streaming from customer_dim table would only be possible in the case of SCD 2 retention.
- D. When stored as SCD 1, the target of AUTO CDC INTO includes updates and deletes. Streaming from customer_dim can fail due to these operations. Instead, build another stream from the original source.
正解:B
解説:
Reading the change data feed from the customer_dim table enables downstream processing to react specifically to update and delete events while operating incrementally. Change data feed exposes row-level change types and versions, making it the correct mechanism for streaming only the relevant changes from an SCD Type 1 table maintained with AUTO CDC INTO.
質問 # 49
A table is registered with the following code:
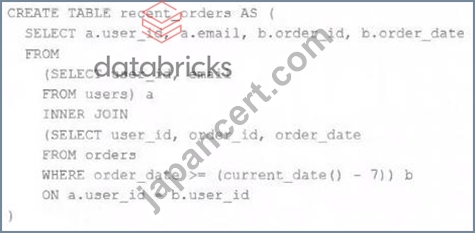
Both users and orders are Delta Lake tables. Which statement describes the results of querying recent_orders?
- A. Results will be computed and cached when the table is defined; these cached results will incrementally update as new records are inserted into source tables.
- B. All logic will execute when the table is defined and store the result of joining tables to the DBFS; this stored data will be returned when the table is queried.
- C. All logic will execute at query time and return the result of joining the valid versions of the source tables at the time the query began.
- D. The versions of each source table will be stored in the table transaction log; query results will be saved to DBFS with each query.
- E. All logic will execute at query time and return the result of joining the valid versions of the source tables at the time the query finishes.
正解:B
解説:
Table is created and data of join will be stored on DBFS and it will be returned on query time.
質問 # 50
All records from an Apache Kafka producer are being ingested into a single Delta Lake table with the following schema:
key BINARY, value BINARY, topic STRING, partition LONG, offset LONG, timestamp LONG There are 5 unique topics being ingested. Only the "registration" topic contains Personal Identifiable Information (PII). The company wishes to restrict access to PII. The company also wishes to only retain records containing PII in this table for 14 days after initial ingestion.
However, for non-PII information, it would like to retain these records indefinitely.
Which of the following solutions meets the requirements?
- A. Separate object storage containers should be specified based on the partition field, allowing isolation at the storage level.
- B. Because the value field is stored as binary data, this information is not considered PII and no special precautions should be taken.
- C. All data should be deleted biweekly; Delta Lake's time travel functionality should be leveraged to maintain a history of non-PII information.
- D. Data should be partitioned by the topic field, allowing ACLs and delete statements to leverage partition boundaries.
- E. Data should be partitioned by the registration field, allowing ACLs and delete statements to be set for the PII directory.
正解:D
解説:
By default partitionning by a column will create a separate folder for each subset data linked to the partition.
質問 # 51
An upstream source writes Parquet data as hourly batches to directories named with the current date. A nightly batch job runs the following code to ingest all data from the previous day as indicated by the date variable:
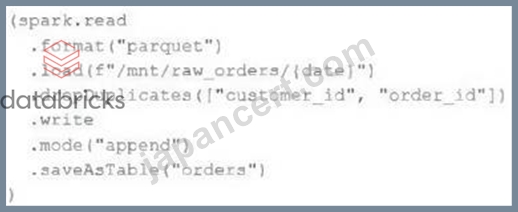
Assume that the fields customer_id and order_id serve as a composite key to uniquely identify each order.
If the upstream system is known to occasionally produce duplicate entries for a single order hours apart, which statement is correct?
- A. Each write to the orders table will only contain unique records, and only those records without duplicates in the target table will be written.
- B. Each write to the orders table will only contain unique records; if existing records with the same key are present in the target table, the operation will tail.
- C. Each write to the orders table will run deduplication over the union of new and existing records, ensuring no duplicate records are present.
- D. Each write to the orders table will only contain unique records; if existing records with the same key are present in the target table, these records will be overwritten.
- E. Each write to the orders table will only contain unique records, but newly written records may have duplicates already present in the target table.
正解:E
解説:
This is the correct answer because the code uses the dropDuplicates method to remove any duplicate records within each batch of data before writing to the orders table. However, this method does not check for duplicates across different batches or in the target table, so it is possible that newly written records may have duplicates already present in the target table. To avoid this, a better approach would be to use Delta Lake and perform an upsert operation using mergeInto.
質問 # 52
......
JapancertのDatabricksのDatabricks-Certified-Data-Engineer-Professional試験トレーニング資料は現在で一番人気があるダウンロードのフォーマットを提供します。PDFとソフトのフォーマットで、ダウンロードするのは易いです。Japancertが提供した製品がIT専門家は実際の経験を活かして作った最も良い製品で、あなたが自分の目標を達成するようにずっと一生懸命頑張っています。
Databricks-Certified-Data-Engineer-Professional模擬モード: https://www.japancert.com/Databricks-Certified-Data-Engineer-Professional.html
- Databricks-Certified-Data-Engineer-Professional資格問題集 🌤 Databricks-Certified-Data-Engineer-Professional的中合格問題集 🧤 Databricks-Certified-Data-Engineer-Professional技術試験 🧐 ➤ www.mogiexam.com ⮘を開き、《 Databricks-Certified-Data-Engineer-Professional 》を入力して、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional日本語版受験参考書
- Databricks-Certified-Data-Engineer-Professional試験の準備方法 | 有難いDatabricks-Certified-Data-Engineer-Professionalミシュレーション問題試験 | 実際的なDatabricks Certified Data Engineer Professional Exam模擬モード 📜 ▛ www.goshiken.com ▟で➥ Databricks-Certified-Data-Engineer-Professional 🡄を検索して、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional勉強方法
- 最高のDatabricks Databricks-Certified-Data-Engineer-Professionalミシュレーション問題 - 合格スムーズDatabricks-Certified-Data-Engineer-Professional模擬モード | 真実的なDatabricks-Certified-Data-Engineer-Professional学習教材 🕓 今すぐ➽ www.goshiken.com 🢪を開き、⏩ Databricks-Certified-Data-Engineer-Professional ⏪を検索して無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional的中合格問題集
- Databricks-Certified-Data-Engineer-Professional試験の準備方法 | 有難いDatabricks-Certified-Data-Engineer-Professionalミシュレーション問題試験 | 実際的なDatabricks Certified Data Engineer Professional Exam模擬モード 📳 ⏩ www.goshiken.com ⏪で➠ Databricks-Certified-Data-Engineer-Professional 🠰を検索し、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professionalサンプル問題集
- Databricks-Certified-Data-Engineer-Professional的中合格問題集 🍥 Databricks-Certified-Data-Engineer-Professional資格問題集 🕺 Databricks-Certified-Data-Engineer-Professionalキャリアパス 🍬 ➤ www.japancert.com ⮘で⏩ Databricks-Certified-Data-Engineer-Professional ⏪を検索し、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional資格問題集
- Databricks-Certified-Data-Engineer-Professional模擬モード 📉 Databricks-Certified-Data-Engineer-Professional受験方法 🎐 Databricks-Certified-Data-Engineer-Professional的中合格問題集 🚑 ➡ www.goshiken.com ️⬅️を入力して☀ Databricks-Certified-Data-Engineer-Professional ️☀️を検索し、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional最新受験攻略
- Databricks-Certified-Data-Engineer-Professional試験の準備方法|権威のあるDatabricks-Certified-Data-Engineer-Professionalミシュレーション問題試験|便利なDatabricks Certified Data Engineer Professional Exam模擬モード 🍅 ✔ Databricks-Certified-Data-Engineer-Professional ️✔️の試験問題は“ www.it-passports.com ”で無料配信中Databricks-Certified-Data-Engineer-Professional日本語版受験参考書
- Databricks-Certified-Data-Engineer-Professional試験の準備方法 | 真実的なDatabricks-Certified-Data-Engineer-Professionalミシュレーション問題試験 | 認定するDatabricks Certified Data Engineer Professional Exam模擬モード 💛 時間限定無料で使える➡ Databricks-Certified-Data-Engineer-Professional ️⬅️の試験問題は[ www.goshiken.com ]サイトで検索Databricks-Certified-Data-Engineer-Professional絶対合格
- Databricks-Certified-Data-Engineer-Professional試験の準備方法 | 真実的なDatabricks-Certified-Data-Engineer-Professionalミシュレーション問題試験 | 認定するDatabricks Certified Data Engineer Professional Exam模擬モード 🐕 ➡ Databricks-Certified-Data-Engineer-Professional ️⬅️の試験問題は➡ jp.fast2test.com ️⬅️で無料配信中Databricks-Certified-Data-Engineer-Professional認定テキスト
- Databricks-Certified-Data-Engineer-Professional資格問題集 🕋 Databricks-Certified-Data-Engineer-Professional模擬モード 🐇 Databricks-Certified-Data-Engineer-Professional勉強方法 🍿 検索するだけで➡ www.goshiken.com ️⬅️から【 Databricks-Certified-Data-Engineer-Professional 】を無料でダウンロードDatabricks-Certified-Data-Engineer-Professional受験方法
- Databricks-Certified-Data-Engineer-Professional勉強方法 ❎ Databricks-Certified-Data-Engineer-Professional絶対合格 🍸 Databricks-Certified-Data-Engineer-Professional日本語参考 🆒 ➥ www.passtest.jp 🡄を開いて《 Databricks-Certified-Data-Engineer-Professional 》を検索し、試験資料を無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional日本語参考
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, aprenderfotografia.online, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, users.playground.ru, www.stes.tyc.edu.tw, www.competize.com, Disposable vapes
2026年Japancertの最新Databricks-Certified-Data-Engineer-Professional PDFダンプおよびDatabricks-Certified-Data-Engineer-Professional試験エンジンの無料共有:https://drive.google.com/open?id=1awmjRaisTzrXxZlSfyJCzT3LtrM11kFz