Databricks Databricks-Certified-Professional-Data-Engineer資格取得講座 & Databricks-Certified-Professional-Data-Engineer日本語版参考資料

ちなみに、Xhs1991 Databricks-Certified-Professional-Data-Engineerの一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=1A1SzvTowtV-qb98mZwmGqtHA6-bT6Hg7
すべての人が当社Xhs1991のDatabricks-Certified-Professional-Data-Engineer学習教材を使用することは非常に便利です。私たちの学習教材は、多くの人々が私たちの製品を購入した場合、多くの問題を解決するのに役立ちます。当社のDatabricks-Certified-Professional-Data-Engineer学習教材のオンライン版は機器に限定されません。つまり、学習教材を電話、コンピューターなどを含むすべての電子機器に適用できます。そのため、当社のオンライン版Databricks-Certified-Professional-Data-Engineer学習教材は、試験の準備に非常に役立ちます。私たちは、Databricks-Certified-Professional-Data-Engineer学習教材が良い選択になると信じています。
Databricks Databricks-Certified-Professional-Data-Engineer Exam Syllabus Topics:
| Section | Objectives |
|---|
| Security, Governance, Monitoring, and Optimization | - Monitor and optimize Spark workloads
- Implement Unity Catalog governance and access control
- Cost optimization and performance tuning
|
| Data Modeling and Storage | - Schema evolution and data partitioning strategies
- Design scalable data lakehouse architectures
- Delta Lake table design and optimization
|
| Production Pipelines and Orchestration | - Pipeline reliability and fault tolerance
- Build and manage workflows using Databricks Jobs
- Automate ETL pipelines and scheduling
|
| Data Ingestion and Transformation | - Handle batch and streaming data pipelines
- Ingest data using Apache Spark and Databricks
- Transform and clean datasets using Spark SQL and DataFrame APIs
|
>> Databricks Databricks-Certified-Professional-Data-Engineer資格取得講座 <<
世界基準の Databricks-Certified-Professional-Data-Engineer 問題集
当社は、お客様に信頼できる学習プラットフォームを提供できることを嬉しく思います。 Databricks-Certified-Professional-Data-Engineerクイズトレントは、急速な発展の世界のさまざまな分野の多くの専門家や教授によって設計されました。同時に、Databricks-Certified-Professional-Data-Engineer試験問題集に質問がある場合は、プロの個人が短時間であなたの質問に答えることができます。つまり、Databricks-Certified-Professional-Data-Engineerクイズ準備を購入することを選択した場合、当社が提供する権威ある学習プラットフォームを楽しむことができます。最新のDatabricks-Certified-Professional-Data-Engineer試験トレントが最適な選択になると確信しています。さらに重要なことは、最新のDatabricks-Certified-Professional-Data-Engineer試験トレントのデモを無料で入手できることです。
Databricks Certified Professional Data Engineer Exam 認定 Databricks-Certified-Professional-Data-Engineer 試験問題 (Q31-Q36):
質問 # 31
A data engineer is testing a collection of mathematical functions, one of which calculates the area under a curve as described by another function.
Which kind of the test does the above line exemplify?
- A. Integration
- B. Unit
- C. functional
- D. Manual
正解:B
解説:
A unit test is designed to verify the correctness of a small, isolated piece of code, typically a single function.
Testing a mathematical function that calculates the area under a curve is an example of a unit test because it is testing a specific, individual function to ensure it operates as expected.
References:
* Software Testing Fundamentals: Unit Testing
質問 # 32
A data engineer wants to reflector the following DLT code, which includes multiple definition with very similar code:
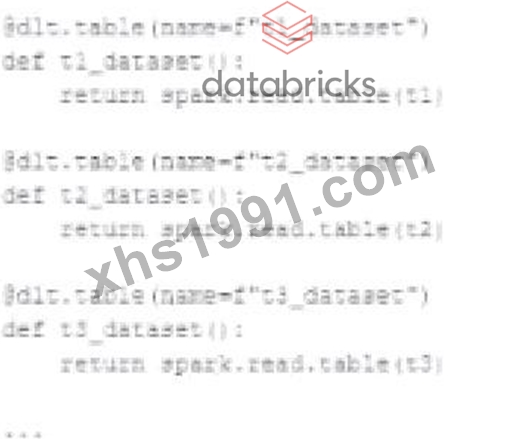
In an attempt to programmatically create these tables using a parameterized table definition, the data engineer writes the following code.
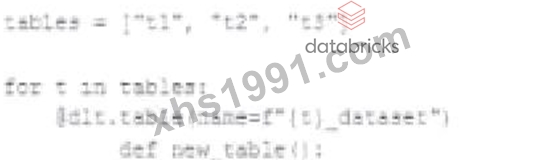
The pipeline runs an update with this refactored code, but generates a different DAG showing incorrect configuration values for tables.
How can the data engineer fix this?
- A. Convert the list of configuration values to a dictionary of table settings, using different input the for loop.
- B. Load the configuration values for these tables from a separate file, located at a path provided by a pipeline parameter.
- C. Wrap the loop inside another table definition, using generalized names and properties to replace with those from the inner table
- D. Convert the list of configuration values to a dictionary of table settings, using table names as keys.
正解:D
解説:
The issue with the refactored code is that it tries to use string interpolation to dynamically create table names within thedlc.tabledecorator, which will not correctly interpret the table names. Instead, by using a dictionary with table names as keys and their configurations as values, the data engineer can iterate over the dictionary items and use the keys (table names) to properly configure the table settings. This way, the decorator can correctly recognize each table name, and the corresponding configuration settings can be applied appropriately.
質問 # 33
The DevOps team has configured a production workload as a collection of notebooks scheduled to run daily using the Jobs Ul. A new data engineering hire is onboarding to the team and has requested access to one of these notebooks to review the production logic.
What are the maximum notebook permissions that can be granted to the user without allowing accidental changes to production code or data?
- A. Can manage
- B. Can Read
- C. Can edit
- D. Can run
正解:B
解説:
Granting a user 'Can Read' permissions on a notebook within Databricks allows them to view the notebook's content without the ability to execute or edit it. This level of permission ensures that the new team member can review the production logic for learning or auditing purposes without the risk of altering the notebook's code or affecting production data and workflows. This approach aligns with best practices for maintaining security and integrity in production environments, where strict access controls are essential to prevent unintended modifications.References: Databricks documentation on access control and permissions for notebooks within the workspace (https://docs.databricks.com/security/access-control/workspace-acl.html).
質問 # 34
A table named user_ltv is being used to create a view that will be used by data analysts on various teams.
Users in the workspace are configured into groups, which are used for setting up data access using ACLs.
The user_ltv table has the following schema:
email STRING, age INT, ltv INT
The following view definition is executed:
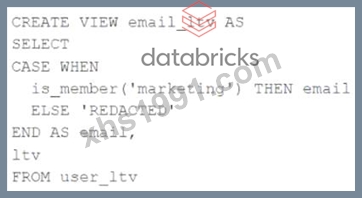
An analyst who is not a member of the marketing group executes the following query:
SELECT * FROM email_ltv
Which statement describes the results returned by this query?
- A. Three columns will be returned, but one column will be named "redacted" and contain only null values.
- B. Only the email and ltv columns will be returned; the email column will contain the string
"REDACTED" in each row. - C. The email and ltv columns will be returned with the values in user itv.
- D. The email, age. and ltv columns will be returned with the values in user ltv.
- E. Only the email and itv columns will be returned; the email column will contain all null values.
正解:B
解説:
The code creates a view called email_ltv that selects the email and ltv columns from a table called user_ltv, which has the following schema: email STRING, age INT, ltv INT. The code also uses the CASE WHEN expression to replace the email values with the string "REDACTED" if the user is not a member of the marketing group. The user who executes the query is not a member of the marketing group, so they will only see the email and ltv columns, and the email column will contain the string "REDACTED" in each row.
Verified References: [Databricks Certified Data Engineer Professional], under "Lakehouse" section; Databricks Documentation, under "CASE expression" section.
質問 # 35
A data engineer needs to capture pipeline settings from an existing in the workspace, and use them to create and version a JSON file to create a new pipeline.
Which command should the data engineer enter in a web terminal configured with the Databricks CLI?
- A. Use the alone command to create a copy of an existing pipeline; use the get JSON command to get the pipeline definition; save this to git
- B. Use list pipelines to get the specs for all pipelines; get the pipeline spec from the return results parse and use this to create a pipeline
- C. Stop the existing pipeline; use the returned settings in a reset command
- D. Use the get command to capture the settings for the existing pipeline; remove the pipeline_id and rename the pipeline; use this in a create command
正解:D
解説:
The Databricks CLI provides a way to automate interactions with Databricks services. When dealing with pipelines, you can use thedatabricks pipelines get --pipeline-idcommand to capture the settings of an existing pipeline in JSON format. This JSON can then be modified by removing thepipeline_idto prevent conflicts and renaming the pipeline to create a new pipeline. The modified JSON file can then be used with the databricks pipelines createcommand to create a new pipeline with those settings.
References:
* Databricks Documentation on CLI for Pipelines: Databricks CLI - Pipelines
質問 # 36
......
私たちのDatabricks-Certified-Professional-Data-Engineer試験材料とサービスはあなたのDatabricks-Certified-Professional-Data-Engineer試験に合格することに役に立ちます。私たちはあなたの時間と精力を節約してタイムスケジュールを設定します。 私たちのDatabricks-Certified-Professional-Data-Engineer試験資料は確かに有効かつ全面的であるので、Databricks-Certified-Professional-Data-Engineer試験の合格率が高いです。私たちのDatabricks-Certified-Professional-Data-Engineer試験資料のような書籍が少ないので、早く買いましょう!
Databricks-Certified-Professional-Data-Engineer日本語版参考資料: https://www.xhs1991.com/Databricks-Certified-Professional-Data-Engineer.html
- 100%合格率Databricks-Certified-Professional-Data-Engineer|一番優秀なDatabricks-Certified-Professional-Data-Engineer資格取得講座試験|試験の準備方法Databricks Certified Professional Data Engineer Exam日本語版参考資料 🌀 ➤ Databricks-Certified-Professional-Data-Engineer ⮘を無料でダウンロード▶ www.jpexam.com ◀で検索するだけDatabricks-Certified-Professional-Data-Engineer日本語版対応参考書
- Databricks-Certified-Professional-Data-Engineer問題集、受験者たちの認可を得ているDatabricks Databricks-Certified-Professional-Data-Engineer模擬試験 💓 ➥ www.goshiken.com 🡄を入力して( Databricks-Certified-Professional-Data-Engineer )を検索し、無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer資格難易度
- 実用的なDatabricks-Certified-Professional-Data-Engineer資格取得講座試験-試験の準備方法-真実的なDatabricks-Certified-Professional-Data-Engineer日本語版参考資料 🤸 ✔ Databricks-Certified-Professional-Data-Engineer ️✔️の試験問題は⇛ www.xhs1991.com ⇚で無料配信中Databricks-Certified-Professional-Data-Engineer復習時間
- Databricks-Certified-Professional-Data-Engineer日本語練習問題 😴 Databricks-Certified-Professional-Data-Engineer過去問題 🎠 Databricks-Certified-Professional-Data-Engineer資格難易度 🍀 ➥ www.goshiken.com 🡄から簡単に{ Databricks-Certified-Professional-Data-Engineer }を無料でダウンロードできますDatabricks-Certified-Professional-Data-Engineer受験資料更新版
- Databricks-Certified-Professional-Data-Engineer復習時間 🦖 Databricks-Certified-Professional-Data-Engineer復習時間 🦠 Databricks-Certified-Professional-Data-Engineer資料勉強 🍟 { www.jptestking.com }で{ Databricks-Certified-Professional-Data-Engineer }を検索して、無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer資格取得
- Databricks-Certified-Professional-Data-Engineer対応資料 🥥 Databricks-Certified-Professional-Data-Engineer試験資料 👎 Databricks-Certified-Professional-Data-Engineer試験関連赤本 💄 ⮆ www.goshiken.com ⮄の無料ダウンロード▛ Databricks-Certified-Professional-Data-Engineer ▟ページが開きますDatabricks-Certified-Professional-Data-Engineer試験資料
- Databricks-Certified-Professional-Data-Engineer問題集、受験者たちの認可を得ているDatabricks Databricks-Certified-Professional-Data-Engineer模擬試験 🐚 ⏩ www.passtest.jp ⏪サイトにて最新《 Databricks-Certified-Professional-Data-Engineer 》問題集をダウンロードDatabricks-Certified-Professional-Data-Engineer資格取得
- 実用的なDatabricks-Certified-Professional-Data-Engineer資格取得講座試験-試験の準備方法-真実的なDatabricks-Certified-Professional-Data-Engineer日本語版参考資料 🐋 【 www.goshiken.com 】の無料ダウンロード( Databricks-Certified-Professional-Data-Engineer )ページが開きますDatabricks-Certified-Professional-Data-Engineer対応資料
- 100%合格率Databricks-Certified-Professional-Data-Engineer|一番優秀なDatabricks-Certified-Professional-Data-Engineer資格取得講座試験|試験の準備方法Databricks Certified Professional Data Engineer Exam日本語版参考資料 🧭 サイト( www.mogiexam.com )で⇛ Databricks-Certified-Professional-Data-Engineer ⇚問題集をダウンロードDatabricks-Certified-Professional-Data-Engineer日本語版
- 信頼的Databricks-Certified-Professional-Data-Engineer|高品質なDatabricks-Certified-Professional-Data-Engineer資格取得講座試験|試験の準備方法Databricks Certified Professional Data Engineer Exam日本語版参考資料 🍂 ➡ Databricks-Certified-Professional-Data-Engineer ️⬅️を無料でダウンロード➥ www.goshiken.com 🡄ウェブサイトを入力するだけDatabricks-Certified-Professional-Data-Engineer日本語版
- Databricks-Certified-Professional-Data-Engineer受験対策 🎦 Databricks-Certified-Professional-Data-Engineer資格難易度 🚴 Databricks-Certified-Professional-Data-Engineer受験資料更新版 🥣 ➤ www.xhs1991.com ⮘で➠ Databricks-Certified-Professional-Data-Engineer 🠰を検索し、無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer試験資料
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes
無料でクラウドストレージから最新のXhs1991 Databricks-Certified-Professional-Data-Engineer PDFダンプをダウンロードする:https://drive.google.com/open?id=1A1SzvTowtV-qb98mZwmGqtHA6-bT6Hg7