DOWNLOAD the newest Pass4Leader AI-300 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1dZYo3zqmuStGUQSUH1JGTgrMobJaKT8m
The users can instantly access the product after purchasing it from Pass4Leader AI-300, so they don't have to wait to prepare for the Microsoft AI-300 Exams. The 24/7 support system is available for the customers, so they can contact the support whenever they face any issue, and it will provide them with the solution. Furthermore, Pass4Leader offers up to 1 year of free updates and free demos of the product.
| Section | Objectives |
|---|---|
| Topic 1: Design and implement a GenAIOps infrastructure | - Set up Microsoft Foundry and Azure AI services for generative AI workloads - Implement RAG (Retrieval-Augmented Generation) pipelines and vector search - Configure prompt orchestration, prompt flows, and agent frameworks - Manage API keys, rate limits, and responsible AI guardrails |
| Topic 2: Optimize generative AI systems and model performance | - Fine-tune and distill models for specific use cases - Tune prompts, system messages, and grounding strategies - Implement cost management and scaling strategies for GenAI workloads - Optimize inference performance, caching, and throughput |
| Topic 3: Implement generative AI quality assurance and observability | - Conduct red teaming, adversarial testing, and content filtering - Monitor latency, token usage, cost, and error rates - Evaluate generative AI outputs for quality, safety, and grounding - Implement logging, tracing, and telemetry for GenAI applications |
| Topic 4: Design and implement an MLOps infrastructure | - Implement security, governance, and compliance for MLOps - Manage environments, data stores, and model registries - Set up Azure Machine Learning workspace and compute targets - Configure source control, CI/CD pipelines, and automation for ML workflows |
| Topic 5: Implement machine learning model lifecycle and operations | - Monitor model performance, data drift, and operational health - Deploy models to real-time and batch endpoints - Retrain, update, and manage model versions in production - Train, register, and version models using Azure Machine Learning |
Our AI-300 study materials boost the self-learning and self-evaluation functions so as to let the clients understand their learning results and learning process , then find the weak links to improve them. Through the self-learning function the learners can choose the learning methods by themselves and choose the contents which they think are important. Through the self-evaluation function the learners can evaluate their mastery degree of our AI-300 Study Materials and their learning process. The two functions can help the learners adjust their learning arrangements and schedules to efficiently prepare the exam.
NEW QUESTION # 144
Hotspot Question
A team deploys a generative AI application built by using Microsoft Foundry to production and receives variable traffic throughout the day.
The team requires uninterrupted insight into the application s health and model behavior to detect issues without relying on manual inspection.
You need to select the monitoring capabilities that provide real-time operational visibility into the application.
Which monitoring capability should you use for each requirement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.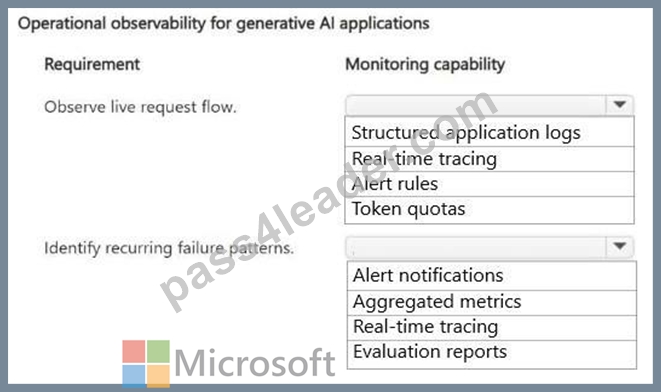
Answer:
Explanation: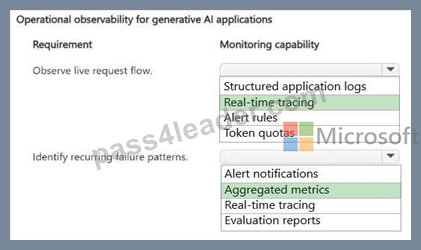
Explanation:
Box 1: Real-time tracing
Observe live request flow.
To best observe the live request flow in your generative AI application, you should use Real-time tracing.
Real-time tracing maps the end-to-end journey of a request as it flows through various microservices, APIs, and AI model endpoints. It provides the exact visibility needed to pinpoint bottlenecks, latencies, and failures in the live request path immediately.
Box 2: Aggregated metrics
Identify recurring failure patterns.
To best identify recurring failure patterns in a generative AI application with variable traffic, you should use aggregated metrics.
Aggregated metrics groups data points over specified time intervals to reveal long-term trends, error rates, and system anomalies. It allows you to track patterns (like a spike in 5xx errors or model timeouts during peak traffic) over hours or days without manually inspecting individual logs.
Reference:
https://docs.azure.cn/en-us/ai-services/metrics-advisor/glossary
NEW QUESTION # 145
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a mid-sized healthcare analytics company that provides population health dashboards and predictive insights to regional hospital systems across the United States.
Fabrikam Inc. customers rely on near real time analytics to monitor patient flow, staffing needs, and readmission risks. They use multiple traditional forecasting machine learning models for predictions.
Fabrikam Inc. has an established Microsoft Azure footprint. The company uses Jupyter Notebooks that run on a local server as the primary development environment. The data science team is experiencing scalability, asset management and code management issues with the current development platform. Fabrikam Inc. plans to migrate to a cloud-based development environment to mitigate the issues.
Additionally, the company plans to implement a Retrieval-Augmented Generation (RAG)-based chat application for client support. Leadership requires the application to be developed and deployed with a low operational risk.
Current Environment
Fabrikam Inc. operates a single Azure subscription that has the following components:
* Azure Data Lake Storage Gen2 that contains de-identified clinical and operational datasets
* Azure AI Search indexing curated analytical documents and reference materials
* A small set of Python-based training scripts maintained by data scientists
* Azure OpenAI Service with deployed foundational models
* A Microsoft Foundry resource for building a RAG-based solution
Evaluation data has manually defined expected responses.
The current challenges faced by the data science team include the following:
* Model training jobs are run manually from notebooks.
* Experiment tracking is inconsistent
* Model versions are registered without standardized metadata.
* Deployment is performed manually by data scientists, with limited rollback capability.
* The team has no standardized evaluation process for generative AI outputs.
The environment currently allows public network access. Authentication relies on user accounts rather than managed identities. Compute targets are manually created and shared across experiments. This has led to resource contention during peak usage.
Business Requirements
Fabrikam Inc. has the following business requirements for the modernization initiative:
* Provide a conversational interface that answers analytics questions by using internal documents and datasets.
* Ensure that sensitive healthcare-related data is not exposed outside the Fabrikam Inc. Azure tenant.
* Enable repeatable and auditable model training and deployment processes.
* Support experimentation to compare prompt strategies and fine-tuned models.
* Align the model with the ranked preferences and optimize behavior for the long term.
* Minimize disruption to existing analytics workloads during rollout.
Technical Requirements
To support the business goals, Fabrikam Inc. identifies these technical requirements:
* Use Azure Machine Learning workspaces to centrally manage data assets, models, and environments.
* Implement experiment tracking and model versioning for all training jobs.
* Orchestrate training and evaluation by using pipelines rather than manually running notebooks.
* Deploy traditional machine learning models with support for staged rollout and rollback.
* Improve RAG-based solution output quality.
* Use the existing evaluation datasets that are based on real data with input-output pairs.
* Apply advanced fine-tuning techniques only when prompt engineering is insufficient Issues and Constraints Fabrikam Inc. must comply with internal security policies that require the company to restrict network access and avoid long-lived secrets. The data science team has limited Azure DevOps experience, so solutions must favor managed services and automation over custom infrastructure.
Cost predictability is important. Leadership prefers serverless or managed compute options where possible but is willing to approve dedicated compute for stable production workloads.
Problem Statement
Fabrikam Inc. must design and implement an Azure-based AI operations solution that enables reliable training, evaluation, deployment, and iteration of generative AI models. The solution must support experimentation and gradual rollout while ensuring governance, security, and operational stability. The data science and platform teams must collaborate to deliver this solution by using Azure Machine Learning and Microsoft Foundry capabilities.
You need to refine a GPT-5 model so that its performance and behavior align with the technical and business requirements of Fabrikam Inc.
Which two Foundry strategies should you apply? Each correct answer presents a complete solution. Choose two.
NOTE: Each correct selection is worth one point.
Answer: A,C
Explanation:
Scenario, Technical Requirements:
Improve RAG-based solution output quality.
Apply advanced fine-tuning techniques only when prompt engineering is insufficient Business Requirements:
Provide a conversational interface that answers analytics questions by using internal documents and datasets.
The two Foundry strategies that would be most useful in this scenario are Evaluations and Supervised fine-tuning.
Evaluations: This strategy is critical for improving RAG-based solution output quality. It provides systemic measurement to test how changes to your data, prompts, or retrieval chunks impact the accuracy, relevance, and groundedness of the model's answers before moving to more complex methods.
Supervised fine-tuning: This strategy directly satisfies the requirement to apply advanced fine- tuning techniques only when prompt engineering is insufficient. It allows you to deeply customize the model's behavior and conversational tone to fit your specific analytics interface requirements.
Incorrect:
Guardrails: While valuable for safety and compliance, guardrails focus on enforcing hard operational boundaries (e.g., blocking toxic content or preventing data leaks). They do not optimize RAG output quality or provide advanced behavioral updates when prompt engineering fails.
Synthetic data generation: While helpful for bootstrapping training datasets when real-world data is scarce, it is an data-preparation step rather than a core model refinement strategy designed to iteratively solve prompt engineering limitations or build conversational systems.
Reference:
https://medium.com/@hugoparreao/context-engineering-what-really-improves-the-performance-of-llms-0c0e3ed45c98
NEW QUESTION # 146
You have an Azure Machine Learning workspace that includes an AmICompute cluster and a batch endpoint.
You clone a repository that contains an MLflow model to your local computer. You need to ensure that you can deploy the model to the batch endpoint.
Solution: Add a compute resource to the workspace.
Does the solution meet the goal?
Answer: A
NEW QUESTION # 147
You create an Azure Machine Learning workspace
You are developing a Python SDK v2 notebook to perform custom model training in the workspace. The notebook code imports all required packages.
You need to complete the Python SDK v2 code to include a training script. environment, and compute information.
How should you complete ten code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point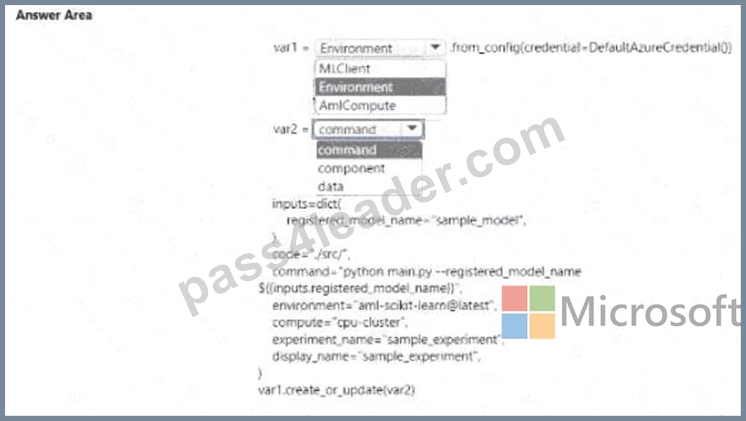
Answer:
Explanation: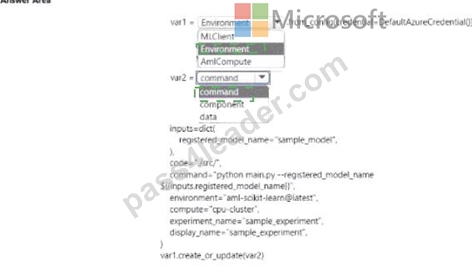
Explanation: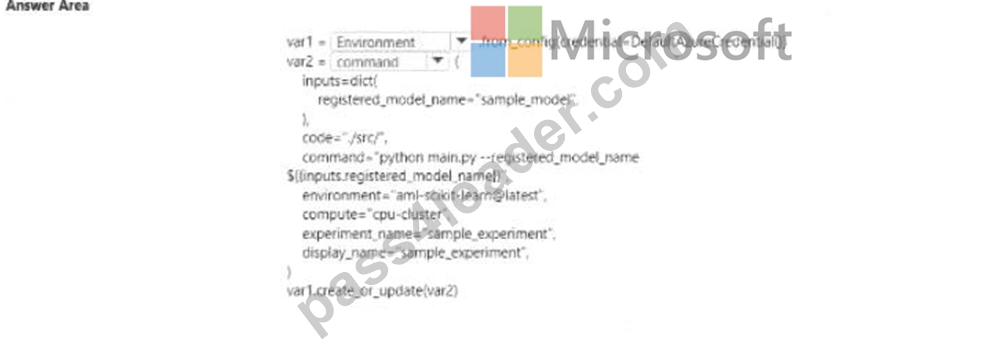
NEW QUESTION # 148
An Azure Machine Learning workspace contains multiple registered versions of a model that is used in production.
An older model version must no longer be deployable, but it must remain available for compliance review and potential rollback.
You need to change the state of the model version to meet the requirements.
What should you do?
Answer: C
Explanation:
To ensure that older Azure Machine Learning model versions are no longer deployable but remain available for reference or historical tracking, you should archive those specific versions.
How to Archive Model Versions
Archiving a model version effectively hides it from standard list queries and management interfaces, preventing accidental deployment while maintaining its metadata and files in the workspace.
Behavior of Archived Models:
Hidden by Default: They will no longer appear in the Azure Machine Learning Studio model list unless you explicitly filter for archived assets.
Referenceable: You can still reference and use an archived model version in existing workflows if you have its specific version number.
Restoreable: If you need to redeploy the model in the future, you can use the restore command to make it active again.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-manage-models
NEW QUESTION # 149
......
For your convenience, Pass4Leader has prepared authentic Microsoft AI-300 Exam study material based on a real exam syllabus to help candidates go through their exams. Candidates who are preparing for the Microsoft exam suffer greatly in their search for preparation material.
Exam AI-300 Bible: https://www.pass4leader.com/Microsoft/AI-300-exam.html
BONUS!!! Download part of Pass4Leader AI-300 dumps for free: https://drive.google.com/open?id=1dZYo3zqmuStGUQSUH1JGTgrMobJaKT8m