2026 Latest Prep4sures DP-100 PDF Dumps and DP-100 Exam Engine Free Share: https://drive.google.com/open?id=1H5O34tWiVSY5h1zdImqhsJ5zEGoeQuve
There are Designing and Implementing a Data Science Solution on Azure (DP-100) exam questions provided in Designing and Implementing a Data Science Solution on Azure (DP-100) PDF questions format which can be viewed on smartphones, laptops, and tablets. So, you can easily study and prepare for your Designing and Implementing a Data Science Solution on Azure (DP-100) exam anywhere and anytime. You can also take a printout of these Microsoft PDF Questions for off-screen study.
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Designing and Implementing a Data Science Solution on Azure |
| Exam Number: | DP-100 |
| Passing Score: | 700/1000 |
| Real Exam Qty: | 40-60 |
| Certificate Validity Period: | 1 year |
| Available Languages: | Portuguese, Spanish, English, French, Japanese, German, Chinese (Simplified), Korean |
| Exam Format: | Interactive Tasks, Drag and Drop, Lab, Multiple Choice, Case Study |
| Exam Price: | $165 USD |
| Related Certifications: | Microsoft Certified: Azure Data Scientist Associate |
| Exam Duration: | 100 minutes |
| Sample Questions: | Microsoft DP-100 Sample Questions |
| Exam Way: | Online proctored exam or test center delivery through Pearson VUE. |
| Pre Condition: | Candidates should have experience with Azure services, Python programming, and machine learning frameworks such as Scikit-Learn, PyTorch, or TensorFlow. |
| Official Syllabus URL: | https://learn.microsoft.com/en-us/credentials/certifications/exams/dp-100/ |
>> Valid Microsoft DP-100 Test Registration <<
It is indeed not easy to make a decision. DP-100 study engine is willing to give you a free trial. If you have some knowledge of our DP-100 training materials, but are not sure whether it is suitable for you, you can email us to apply for a free trial version. You know, we have provided three versions of DP-100 practice quiz: the PDF, Software and APP online. Accordingly, we have three free trial versions as well.
Successful completion of the DP-100 Exam results in the award of the Microsoft Certified: Azure Data Scientist Associate certification, which is recognized by employers globally. Designing and Implementing a Data Science Solution on Azure certification serves as a testament to the candidate's skills and knowledge in the field of data science and can provide a competitive edge in the job market.
NEW QUESTION # 10
space and set up a development environment. You plan to train a deep neural network (DNN) by using the Tensorflow framework and by using estimators to submit training scripts.
You must optimize computation speed for training runs.
You need to choose the appropriate estimator to use as well as the appropriate training compute target configuration.
Which values should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.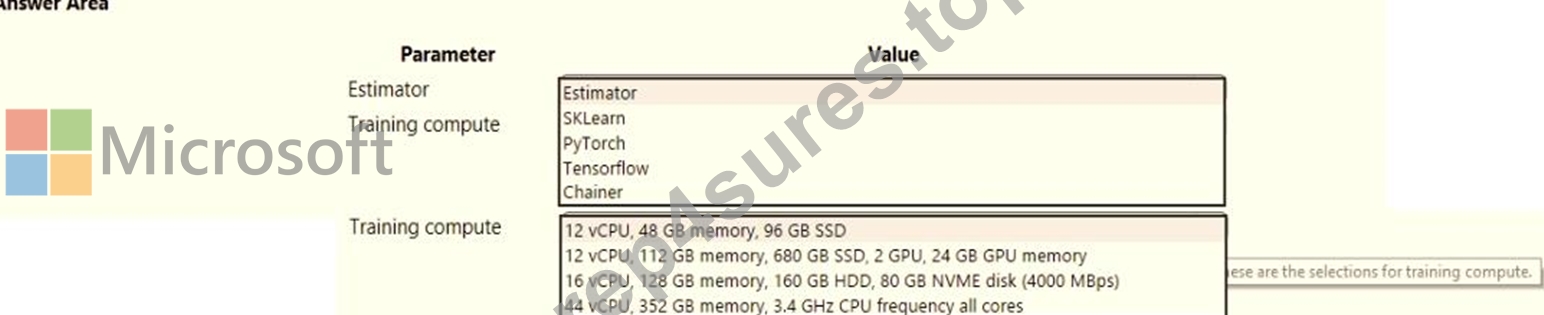
Answer:
Explanation:
Reference:
https://docs.microsoft.com/en-us/python/api/azureml-train-core/azureml.train.dnn
NEW QUESTION # 11
Hotspot Question
You create an Azure Machine Learning workspace and a dataset. The dataset includes age values for a large group of diabetes patients. You use the dp_mean function from the SmartNoise library to calculate the mean of the age value. You store the value in a variable named age_mean.
You must output the value of the interval rage of released mean values that will be returned 95 percent of the time.
You need to complete the code.
Which code values should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.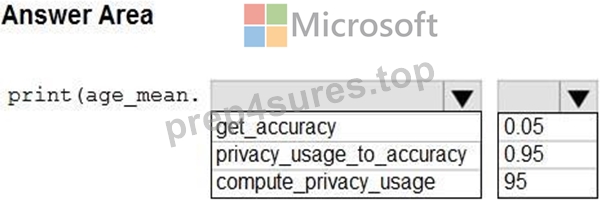
Answer:
Explanation:
NEW QUESTION # 12
Hotspot Question
You have an Azure Machine Learning workspace named workspace1 that is accessible from a public endpoint. The workspace contains an Azure Blob storage datastore named store1 that represents a blob container in an Azure storage account named account1. You configure workspace1 and account1 to be accessible by using private endpoints in the same virtual network.
You must be able to access the contents of store1 by using the Azure Machine Learning SDK for Python. You must be able to preview the contents of store1 by using Azure Machine Learning studio.
You need to configure store1.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Box 1: Regenerate the keys of account1.
Azure Blob Storage support authentication through Account key or SAS token.
To authenticate your access to the underlying storage service, you can provide either your account key, shared access signatures (SAS) tokens, or service principal Box 2: Update the authentication for store1.
For Azure Machine Learning studio users, several features rely on the ability to read data from a dataset; such as dataset previews, profiles and automated machine learning. For these features to work with storage behind virtual networks, use a workspace managed identity in the studio to allow Azure Machine Learning to access the storage account from outside the virtual network.
Note: Some of the studio's features are disabled by default in a virtual network. To re-enable these features, you must enable managed identity for storage accounts you intend to use in the studio.
The following operations are disabled by default in a virtual network:
Preview data in the studio.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-access-data
NEW QUESTION # 13
You need to define a process for penalty event detection.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.
Answer:
Explanation: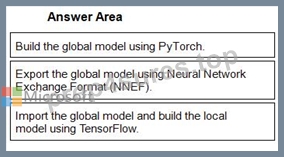
1 - Build the global model using PyTorch.
2 - Export the global model using Neural Network Exchange Format (NNEF).
3 - Import the global model and build the local model using TensorFlow.
Topic 2,
Overview
You are a data scientist for Fabrikam Residences, a company specializing in quality private and commercial property in the United States. Fabrikam Residences is considering expanding into Europe and has asked you to investigate prices for private residences in major European cities. You use Azure Machine Learning Studio to measure the median value of properties. You produce a regression model to predict property prices by using the Linear Regression and Bayesian Linear Regression modules.
Datasets
There are two datasets in CSV format that contain property details for two cities, London and Paris, with the following columns: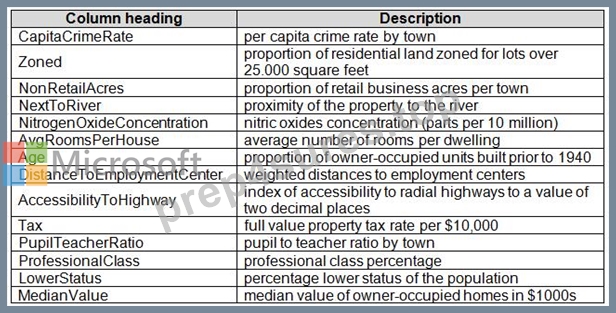
The two datasets have been added to Azure Machine Learning Studio as separate datasets and included as the starting point of the experiment.
Dataset issues
The AccessibilityToHighway column in both datasets contains missing values. The missing data must be replaced with new data so that it is modeled conditionally using the other variables in the data before filling in the missing values.
Columns in each dataset contain missing and null values. The dataset also contains many outliers. The Age column has a high proportion of outliers. You need to remove the rows that have outliers in the Age column. The MedianValue and AvgRoomsinHouse columns both hold data in numeric format. You need to select a feature selection algorithm to analyze the relationship between the two columns in more detail.
Model fit
The model shows signs of overfitting. You need to produce a more refined regression model that reduces the overfitting.
Experiment Requirements
You must set up the experiment to cross-validate the Linear Regression and Bayesian Linear Regression modules to evaluate performance.
In each case, the predictor of the dataset is the column named MedianValue. An initial investigation showed that the datasets are identical in structure apart from the MedianValue column. The smaller Paris dataset contains the MedianValue in text format, whereas the larger London dataset contains the MedianValue in numerical format. You must ensure that the datatype of the MedianValue column of the Paris dataset matches the structure of the London dataset.
You must prioritize the columns of data for predicting the outcome. You must use non-parameters statistics to measure the relationships.
You must use a feature selection algorithm to analyze the relationship between the MedianValue and AvgRoomsinHouse columns.
Model training
Given a trained model and a test dataset, you need to compute the permutation feature importance scores of feature variables. You need to set up the Permutation Feature Importance module to select the correct metric to investigate the model's accuracy and replicate the findings.
You want to configure hyperparameters in the model learning process to speed the learning phase by using hyperparameters. In addition, this configuration should cancel the lowest performing runs at each evaluation interval, thereby directing effort and resources towards models that are more likely to be successful.
You are concerned that the model might not efficiently use compute resources in hyperparameter tuning. You also are concerned that the model might prevent an increase in the overall tuning time. Therefore, you need to implement an early stopping criterion on models that provides savings without terminating promising jobs.
Testing
You must produce multiple partitions of a dataset based on sampling using the Partition and Sample module in Azure Machine Learning Studio. You must create three equal partitions for cross-validation. You must also configure the cross-validation process so that the rows in the test and training datasets are divided evenly by properties that are near each city's main river. The data that identifies that a property is near a river is held in the column named NextToRiver. You want to complete this task before the data goes through the sampling process.
When you train a Linear Regression module using a property dataset that shows data for property prices for a large city, you need to determine the best features to use in a model. You can choose standard metrics provided to measure performance before and after the feature importance process completes. You must ensure that the distribution of the features across multiple training models is consistent.
Data visualization
You need to provide the test results to the Fabrikam Residences team. You create data visualizations to aid in presenting the results.
You must produce a Receiver Operating Characteristic (ROC) curve to conduct a diagnostic test evaluation of the model. You need to select appropriate methods for producing the ROC curve in Azure Machine Learning Studio to compare the Two-Class Decision Forest and the Two-Class Decision Jungle modules with one another.
NEW QUESTION # 14
You need to correct the model fit issue.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.
Answer:
Explanation: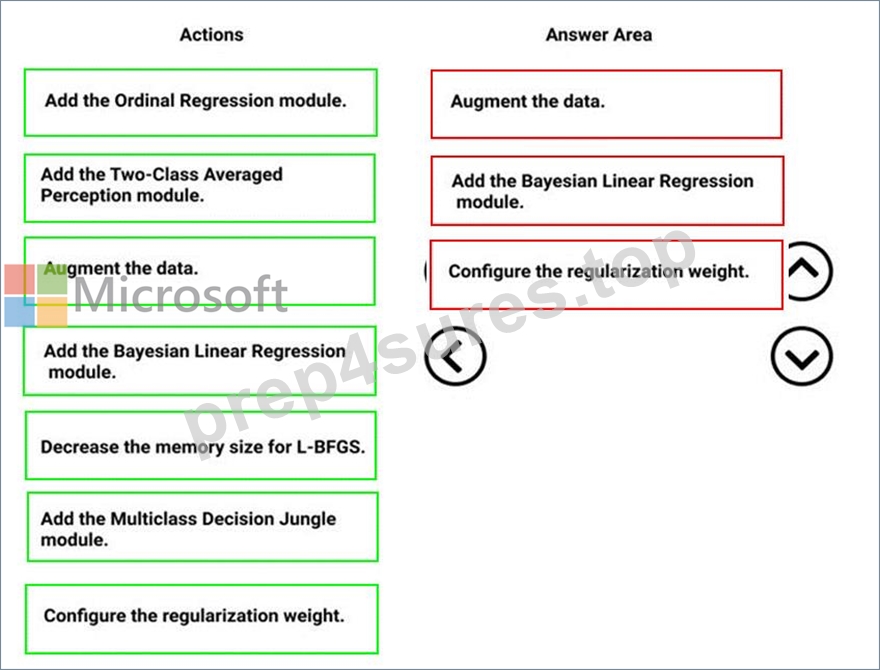
Explanation:
Step 1: Augment the data
Scenario: Columns in each dataset contain missing and null values. The datasets also contain many outliers.
Step 2: Add the Bayesian Linear Regression module.
Scenario: You produce a regression model to predict property prices by using the Linear Regression and Bayesian Linear Regression modules.
Step 3: Configure the regularization weight.
Regularization typically is used to avoid overfitting. For example, in L2 regularization weight, type the value to use as the weight for L2 regularization. We recommend that you use a non-zero value to avoid overfitting.
Scenario:
Model fit: The model shows signs of overfitting. You need to produce a more refined regression model that reduces the overfitting.
Incorrect Answers:
Multiclass Decision Jungle module:
Decision jungles are a recent extension to decision forests. A decision jungle consists of an ensemble of decision directed acyclic graphs (DAGs).
L-BFGS:
L-BFGS stands for "limited memory Broyden-Fletcher-Goldfarb-Shanno". It can be found in the wwo-Class Logistic Regression module, which is used to create a logistic regression model that can be used to predict two (and only two) outcomes.
References:
<https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/linear-regr ession>
NEW QUESTION # 15
......
Test DP-100 Duration: https://www.prep4sures.top/DP-100-exam-dumps-torrent.html
2026 Latest Prep4sures DP-100 PDF Dumps and DP-100 Exam Engine Free Share: https://drive.google.com/open?id=1H5O34tWiVSY5h1zdImqhsJ5zEGoeQuve