MicrosoftのAI-300の認証試験は現在IT業界でもっとも人気があって、その試験に合格すれば君の生活と仕事にいいです。 ShikenPASSはMicrosoftのAI-300「Operationalizing Machine Learning and Generative AI Solutions」の認証試験の合格率を高めるのウエブサイトで、ShikenPASS中のIT業界の専門家が研究を通じてMicrosoftのAI-300の認証試験について問題集を研究し続けています。100%合格率は彼らの研究成果でございます。ShikenPASSを選られば、成功しましょう。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Optimize generative AI systems and model performance | 15–20% | - Improve efficiency and cost-effectiveness
|
| Topic 2: Design and implement a GenAIOps infrastructure | 20–25% | - Set up Microsoft Foundry environment
|
| Topic 3: Design and implement an MLOps infrastructure | 15–20% | - Implement infrastructure as code for Machine Learning
|
| Topic 4: Implement machine learning model lifecycle and operations | 25–30% | - Monitor and maintain models in production
|
| Topic 5: Implement generative AI quality assurance and observability | 10–15% | - Monitor generative AI systems
|
ShikenPASSは実環境であなたの本当のMicrosoft AI-300試験に準備するプロセスを見つけられます。もしあなたが初心者だったら、または自分の知識や専門的なスキルを高めたいのなら、ShikenPASSのMicrosoftのAI-300問題集があなたを助けることができ、一歩一歩でその念願を実現することにヘルプを差し上げます。ShikenPASSのMicrosoftのAI-300は試験に関する全ての質問が解決して差し上げられます。それに一年間の無料更新サービスを提供しますから、ShikenPASSのウェブサイトをご覧ください。
質問 # 44
A team is experimenting with traditional models for a classification workflow in Azure Machine Learning.
The team requires a consistent way to manage assets that are created during experimentation.
You need to ensure that artifacts can be reused and governed across projects.
Which asset should you register?
正解:A
解説:
During experimentation, a data science team produces trained model artifacts they want to share with the MLOps team for deployment, with the governance team for compliance, and with the QA team for testing.
Registering the model in the Azure ML model registry gives each of these teams access to the versioned, immutable artifact through a single reference. Option B (Component) packages a reusable pipeline step, not the model output itself. Option C (Environment) captures the Python runtime, not the trained artifact. Option D (Pipeline) defines the orchestration workflow, not the resulting model. In Azure ML, the model registry is the governance store for trained model artifacts, recording who created it, when, from what data and code, and which metrics it achieved - making it the asset to register for reuse and governance across projects.
Microsoft Learn Reference Topic: Register and manage models in Azure Machine Learning - Model registry
質問 # 45
A team deploys a model to a real-time endpoint in Azure Machine Learning. You deploy some updates to the endpoint.
The endpoint returns errors after the new deployment is released.
You need to restore the service as quickly as possible.
What should you do first?
正解:B
解説:
To restore the service as quickly as possible, you can roll back traffic to the previous deployment by updating the traffic allocation settings of your Azure Machine Learning online endpoint.
Azure Machine Learning managed online endpoints support multiple deployments under a single endpoint, allowing for blue-green deployment strategies where you can shift traffic between versions instantly.
Key Benefits of This Approach
Instant Recovery: Traffic shifting is a routing change and does not require redeploying the previous model's code or environment, making it the fastest recovery method.
No Downtime: Because the previous deployment remains "warm" (active but receiving no traffic), the switch happens without interrupting the service.
Isolation for Debugging: You can keep the failing deployment at 0% traffic to inspect its logs using az ml online-deployment get-logs without affecting end users How to Roll Back Traffic If your new deployment (e.g., "green") is returning errors, you can reallocate 100% of the traffic back to the known stable deployment (e.g., "blue") using the following methods:
* Azure CLI: Use the az ml online-endpoint update command to set the traffic percentage:
az ml online-endpoint update --name <your-endpoint-name> --traffic "blue=100 green=0"
* Azure Machine Learning Studio:
Navigate to Endpoints in the left menu.
Select your specific real-time endpoint.
Go to the Details or Live Traffic tab.
Adjust the traffic percentages so the previous deployment receives 100% and the failing deployment receives 0%.
Select Update or Save to apply the changes immediately
Reference:
https://learn.microsoft.com/en-us/answers/questions/1275110/azure-ml-v2-yaml-code-for-live- traffic-allocation
質問 # 46
You create a binary classification model. You use the Fairlearn package to assess model fairness.
You must eliminate the need to retrain the model.
You need to implement the Fairlearn package.
Which algorithm should you use?
正解:B
質問 # 47
Hotspot Question
You manage a Microsoft Foundry project.
You are evaluating two RAG solutions.
When generating answers, the solutions display the following results:
- The first solution displays low completeness and low utilization.
- The second solution displays low completeness and high utilization.
You need to address the issues found during evaluation.
Which action should you perform first for each issue? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.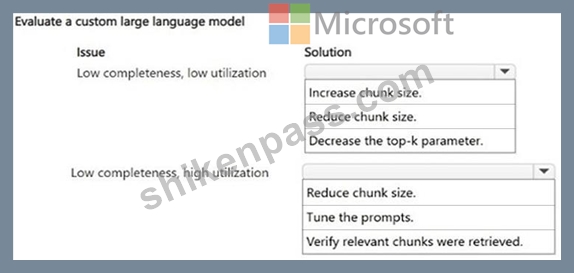
正解:
解説: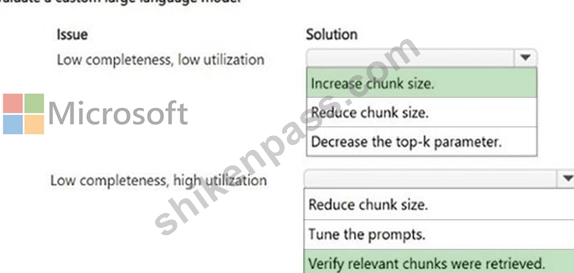
質問 # 48
A team manages an Azure Machine Learning workspace and deploys a model to an endpoint.
A deployed online endpoint shows inconsistent response times during periods of high traffic.
You need to identify potential performance degradation.
Which three metrics should you monitor? Each correct answer presents part of the solution.
Choose three.
NOTE: Each correct selection is worth one point.
正解:A、D、E
解説:
To locate potential performance degradation in an Azure Machine Learning online endpoint during high traffic, you should monitor these three metrics:
Requests per minute: This metric tracks the volume of incoming traffic and helps identify if spikes in load correlate with slower response times.
Connections active: This monitors the total number of concurrent TCP connections from clients, which can indicate if the endpoint is reaching its capacity limits during peak periods.
Request latency: This directly measures the time taken to respond to requests, allowing you to observe exactly when and by how much performance is degrading.
Reference:
https://oneuptime.com/blog/post/2026-02-16-how-to-deploy-a-machine-learning-model-as-a-real- time-endpoint-in-azure-machine-learning/view
質問 # 49
......
ShikenPASSの商品はMicrosoft業界の専門家が自分の豊かな知識と経験を利用して認証試験に対して研究出たので品質がいいのAI-300試験の資料でございます。受験者がShikenPASSを選択したら高度専門のAI-300試験に100%合格することが問題にならないと保証いたします。
AI-300受験練習参考書: https://www.shikenpass.com/AI-300-shiken.html