P.S. Free 2026 NVIDIA NCA-GENM dumps are available on Google Drive shared by Actual4Exams: https://drive.google.com/open?id=11-4QvS-MkdZJM3qeDimwQjSb1VHMO52r
In all respects, you will find our NCA-GENM practice braindumps compatible to your actual preparatory needs. As you can find on our website, we have three different versions of our NCA-GENM exam questions: the PDF, Software and APP online. With all these versins, you can practice the NCA-GENM Learning Materials at any time and condition as you like. The language of our NCA-GENM simulating exam is simple and the content is engaging and easy. What are you waiting for? Just rush to buy it!
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Multimodal Data | 15% | - Applications and use cases - Handling and integrating text, image, and audio data |
| Topic 2: Data Analysis & Visualization | 10% | - Visualization techniques for multimodal data - Data preprocessing and feature engineering |
| Topic 3: Software Development & Engineering | 15% | - Integration and deployment of multimodal AI systems - Python libraries for multimodal AI |
| Topic 4: Core ML & AI Knowledge | 20% | - Basic concepts and terminology - Key algorithms and techniques |
| Topic 5: Experimentation | 25% | - Experimental design - Model evaluation and comparison - Hypothesis testing - A/B testing |
| Topic 6: Performance Optimization | 10% | - Monitoring and improving system efficiency - Techniques for optimizing AI performance |
| Topic 7: Trustworthy AI | 5% | - Ethical considerations in AI development - Ensuring fairness and transparency |
>> NVIDIA NCA-GENM Actual Exam <<
Your selection on the riht tool to help your pass the NCA-GENM exam and get the according certification matters a lot for the right NCA-GENM exam braindumps will spread you a lot of time and efforts. Our NCA-GENM Study Guide is the most reliable and popular exam product in the marcket for we only sell the latest NCA-GENM practice engine to our clients and you can have a free trial before your purchase.
NEW QUESTION # 14
You are tasked with optimizing a multimodal A1 model that processes both images and text. You observe significant latency during the image encoding phase using a pre-trained ResNet50 model. Which of the following techniques would be MOST effective in reducing latency while preserving accuracy, considering energy efficiency?
Answer: D
Explanation:
Knowledge distillation involves training a smaller, more efficient model to approximate the behavior of a larger, more accurate model. This can significantly reduce latency without a major drop in accuracy. Increasing batch size (A) may increase throughput but doesn't necessarily reduce latency per image. Replacing with a larger model (C) will increase latency and power consumption. Using full precision (D) is less energy-efficient than using mixed precision or quantization. Disabling GPU acceleration (E) would drastically increase latency.
NEW QUESTION # 15
A research team is developing a multimodal model to predict stock prices using financial news articles, company filings (text), historical stock prices (time-series), and executive interviews (audio). They are experiencing significant performance issues due to inconsistent data quality across modalities. What specific strategies would you recommend to address these data quality challenges?
Answer: B
Explanation:
All the options are essential. NER standardizes textual data, audio analysis extracts sentiment, and normalization prevents stock price dominance. Addressing data quality holistically across modalities is key.
NEW QUESTION # 16
You're building a generative A1 model that can create realistic 3D models from text descriptions. You have a dataset of text descriptions and corresponding 3D models, but the alignment between the text and the 3D models is weak. The model sometimes generates 3D shapes that don't accurately reflect the text. Which of the following techniques could improve the alignment between the text descriptions and the generated 3D models?
Answer: C,D
Explanation:
A contrastive loss function directly encourages the model to learn a mapping between text and 3D models that preserves semantic similarity. Using a pre-trained text encoder allows the model to leverage existing knowledge about language and extract more meaningful features from the text descriptions, improving alignment. Increasing the number of vertices and faces can improve the resolution of the models but won't directly address alignment. 3D data augmentation can improve robustness, but it's less direct. Batch size has a smaller impact compared to the other options.
NEW QUESTION # 17
You are experimenting with a multimodal model that takes both text and audio as input. During evaluation, you notice that the model is heavily biased towards the text input, largely ignoring the audio. Which of the following techniques could you employ to mitigate this modality imbalance and encourage the model to effectively utilize both inputs? (Select all that apply)
Answer: B,C
Explanation:
Modality imbalance is a common issue in multimodal learning. Applying modality-specific dropout to the dominant modality (text, in this case) forces the model to rely more on the other modality (audio). A contrastive loss directly encourages the model to learn aligned representations between the two modalities. Increasing the audio encoder's learning rate (A) might help, but it is less targeted than dropout or contrastive loss. Reducing the text encoder size (D) is unlikely to be helpful in a controlled way. Replacing Audio features with raw waveform might introduce noise.
NEW QUESTION # 18
Which of the following Python code snippets correctly demonstrates how to load pre-trained word embeddings (e.g., GloVe or Word2Vec) using spaCy and then calculate the cosine similarity between two words?
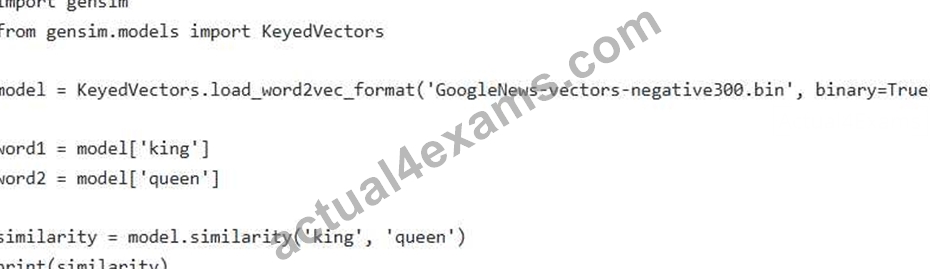
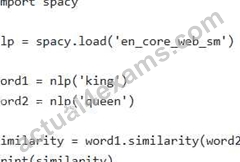
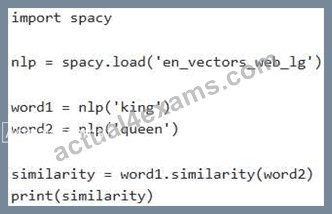
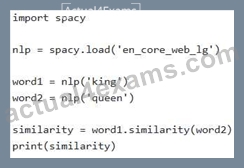
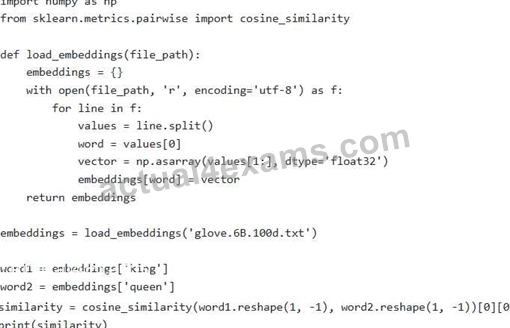
Answer: A,C,D,E
Explanation:
Option A loads a small spacy model without word vectors. Option B loads the large spacy model with word vectors correctly, and calculates the similarity. Option C correctly loads word embeddings from a text file and uses cosine_similarity from sklearn.metrics.pairwise to get similarity Option D shows word similarity and usage of the gensim model.
NEW QUESTION # 19
......
It is very convenient for all people to use the NCA-GENM study materials from our company. Our study materials will help a lot of people to solve many problems if they buy our products. The online version of NCA-GENM study materials from our company is not limited to any equipment, which means you can apply our study materials to all electronic equipment, including the telephone, computer and so on. So the online version of the NCA-GENM Study Materials from our company will be very useful for you to prepare for your exam. We believe that our study materials will be a good choice for you.
Valid Exam NCA-GENM Practice: https://www.actual4exams.com/NCA-GENM-valid-dump.html
BTW, DOWNLOAD part of Actual4Exams NCA-GENM dumps from Cloud Storage: https://drive.google.com/open?id=11-4QvS-MkdZJM3qeDimwQjSb1VHMO52r