2026 Latest Actual4Labs Professional-Machine-Learning-Engineer PDF Dumps and Professional-Machine-Learning-Engineer Exam Engine Free Share: https://drive.google.com/open?id=1YCi2JOTZgjOsr4HX3YbhHzBiTtzzFTR_
The pages of our Professional-Machine-Learning-Engineer guide torrent provide the demo and you can understand part of our titles and the form of our software. On the pages of our Professional-Machine-Learning-Engineer exam torrent you can see the version of the product, the updated time, the quantity of the questions and answers, the characteristics and merits of the product, the price of the product and the discounts. The pages also list the details and the guarantee of our Professional-Machine-Learning-Engineer Exam Torrent, the methods to contact us, the evaluations of the past client on our product, the related exams and other information about our Professional-Machine-Learning-Engineer guide torrent. So before your purchase you can have an understanding of our product and then decide whether to buy our Professional-Machine-Learning-Engineer study questions or not.
| Section | Objectives |
|---|---|
| Architecting low-code ML solutions | - Implementing BigQuery ML for basic models - AutoML capabilities and implementation - Leveraging pre-built ML models as a service (e.g., Vision AI, Speech-to-Text, Recommendations AI) |
| Automating and orchestrating ML pipelines | - Vertex AI Pipelines (Kubeflow Pipelines) - Triggering and scheduling pipelines - CI/CD for ML systems |
| Serving and scaling models | - Hardware accelerators (GPU/TPU) in serving - Model optimization (Quantization, Distillation) - Online prediction (Vertex AI Prediction) - Batch prediction |
| Collaborating within and across teams to manage data and models | - Version control and reproducibility (e.g., DVC, MLOps) - Collaboration between Data Scientists, Data Engineers, and ML Engineers - Data management and governance |
| Scaling prototypes into ML models | - Hyperparameter tuning - Frameworks (TensorFlow, PyTorch, JAX, Scikit-learn) - Training at scale (Distributed training, TPUs) |
| Monitoring ML solutions | - Performance monitoring and drift detection - Logging and alerting (Cloud Monitoring) - Model retraining strategies |
>> Professional-Machine-Learning-Engineer Reliable Test Experience <<
After you use Professional-Machine-Learning-Engineer real exam,you will not encounter any problems with system . If you really have a problem, please contact us in time and our staff will troubleshoot the issue for you. Professional-Machine-Learning-Engineer exam practice’s smooth operating system has improved the reputation of our products. We also received a lot of praise in the international community. I believe this will also be one of the reasons why you choose our Professional-Machine-Learning-Engineer Study Materials.
NEW QUESTION # 116
During batch training of a neural network, you notice that there is an oscillation in the loss. How should you adjust your model to ensure that it converges?
Answer: B
Explanation:
https://developers.google.com/machine-learning/crash-course/introduction-to-neural-networks/playground-exercises
NEW QUESTION # 117
Your team has a model deployed to a Vertex Al endpoint You have created a Vertex Al pipeline that automates the model training process and is triggered by a Cloud Function. You need to prioritize keeping the model up-to-date, but also minimize retraining costs. How should you configure retraining'?
Answer: C
Explanation:
According to the official exam guide1, one of the skills assessed in the exam is to "configure and optimize model monitoring jobs". Vertex AI Model Monitoring documentation states that "model monitoring helps you detect when your model's performance degrades over time due to changes in the data that your model receives or returns" and that "you can configure model monitoring to send notifications to Pub/Sub when it detects anomalies or drift in your model's predictions"2. Therefore, enabling model monitoring on the Vertex AI endpoint and configuring Pub/Sub to call the Cloud Function when feature drift is detected would help you keep the model up-to-date and minimize retraining costs. The other options are not relevant or optimal for this scenario. References:
* Professional ML Engineer Exam Guide
* Vertex AI Model Monitoring
* Google Professional Machine Learning Certification Exam 2023
* Latest Google Professional Machine Learning Engineer Actual Free Exam Questions
NEW QUESTION # 118
Your organization's call center has asked you to develop a model that analyzes customer sentiments in each call. The call center receives over one million calls daily, and data is stored in Cloud Storage. The data collected must not leave the region in which the call originated, and no Personally Identifiable Information (Pll) can be stored or analyzed. The data science team has a third-party tool for visualization and access which requires a SQL ANSI-2011 compliant interface. You need to select components for data processing and for analytics. How should the data pipeline be designed?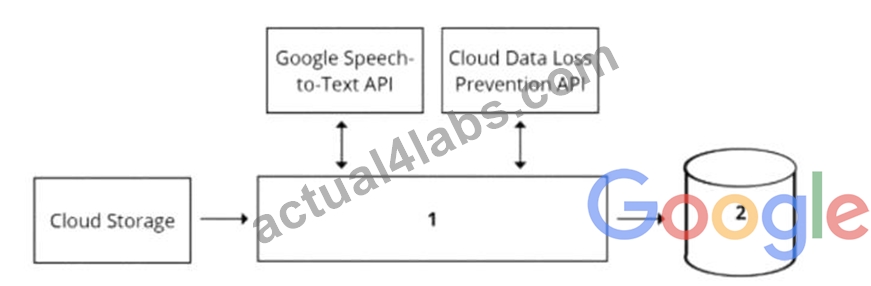
Answer: A
Explanation:
A data pipeline is a set of steps or processes that move data from one or more sources to one or more destinations, usually for the purpose of analysis, transformation, or storage. A data pipeline can be designed using various components, such as data sources, data processing tools, data storage systems, and data analytics tools1 To design a data pipeline for analyzing customer sentiments in each call, one should consider the following requirements and constraints:
* The call center receives over one million calls daily, and data is stored in Cloud Storage. This implies that the data is large, unstructured, and distributed, and requires a scalable and efficient data processing tool that can handle various types of data formats, such as audio, text, or image.
* The data collected must not leave the region in which the call originated, and no Personally Identifiable Information (Pll) can be stored or analyzed. This implies that the data is sensitive and subject to data privacy and compliance regulations, and requires a secure and reliable data storage system that can enforce data encryption, access control, and regional policies.
* The data science team has a third-party tool for visualization and access which requires a SQL ANSI-2011 compliant interface. This implies that the data analytics tool is external and independent of the data pipeline, and requires a standard and compatible data interface that can support SQL queries and operations.
One of the best options for selecting components for data processing and for analytics is to use Dataflow for data processing and BigQuery for analytics. Dataflow is a fully managed service for executing Apache Beam pipelines for data processing, such as batch or stream processing, extract-transform-load (ETL), or data integration. BigQuery is a serverless, scalable, and cost-effective data warehouse that allows you to run fast and complex queries on large-scale data23 Using Dataflow and BigQuery has several advantages for this use case:
* Dataflow can process large and unstructured data from Cloud Storage in a parallel and distributed manner, and apply various transformations, such as converting audio to text, extracting sentiment scores, or anonymizing PII. Dataflow can also handle both batch and stream processing, which can enable real-time or near-real-time analysis of the call data.
* BigQuery can store and analyze the processed data from Dataflow in a secure and reliable way, and enforce data encryption, access control, and regional policies. BigQuery can also support SQL
* ANSI-2011 compliant interface, which can enable the data science team to use their third-party tool for visualization and access. BigQuery can also integrate with various Google Cloud services and tools, such as AI Platform, Data Studio, or Looker.
* Dataflow and BigQuery can work seamlessly together, as they are both part of the Google Cloud ecosystem, and support various data formats, such as CSV, JSON, Avro, or Parquet. Dataflow and BigQuery can also leverage the benefits of Google Cloud infrastructure, such as scalability, performance, and cost-effectiveness.
The other options are not as suitable or feasible. Using Pub/Sub for data processing and Datastore for analytics is not ideal, as Pub/Sub is mainly designed for event-driven and asynchronous messaging, not data processing, and Datastore is mainly designed for low-latency and high-throughput key-value operations, not analytics.
Using Cloud Function for data processing and Cloud SQL for analytics is not optimal, as Cloud Function has limitations on the memory, CPU, and execution time, and does not support complex data processing, and Cloud SQL is a relational database service that may not scale well for large-scale data. Using Cloud Composer for data processing and Cloud SQL for analytics is not relevant, as Cloud Composer is mainly designed for orchestrating complex workflows across multiple systems, not data processing, and Cloud SQL is a relational database service that may not scale well for large-scale data.
References: 1: Data pipeline 2: Dataflow overview 3: BigQuery overview : [Dataflow documentation] :
[BigQuery documentation]
NEW QUESTION # 119
You are implementing a batch inference ML pipeline in Google Cloud. The model was developed using TensorFlow and is stored in SavedModel format in Cloud Storage You need to apply the model to a historical dataset containing 10 TB of data that is stored in a BigQuery table How should you perform the inference?
Answer: A
NEW QUESTION # 120
Your task is classify if a company logo is present on an image. You found out that 96% of a data does not include a logo. You are dealing with data imbalance problem. Which metric do you use to evaluate to model?
Answer: B
Explanation:
The F1 score is a metric that combines both precision and recall, and is suitable for evaluating imbalanced classification problems. Precision measures the fraction of true positives among the predicted positives, and recall measures the fraction of true positives among the actual positives. The F1 score is the harmonic mean of precision and recall, and it ranges from 0 to 1, with higher values indicating better performance. The F1 score is a good metric for imbalanced data because it balances both the false positives and the false negatives, and does not favor the majority class over the minority class.
The other options are not good metrics for imbalanced data. RMSE (root mean squared error) is a metric for regression problems, not classification problems. It measures the average squared difference between the predicted and the actual values, and is not suitable for binary outcomes. F score with higher precision weighting than recall, or F0.5 score, is a metric that gives more importance to precision than recall. This means that it penalizes false positives more than false negatives, which is not desirable for imbalanced data where the minority class is more important. F score with higher recall weighting than precision, or F2 score, is a metric that gives more importance to recall than precision. This means that it penalizes false negatives more than false positives, which might be suitable for some imbalanced data problems, but not for the logo detection problem. In this problem, both false positives and false negatives are equally important, as we want to accurately identify the presence or absence of a logo in an image. Therefore, the F1 score is a better metric than the F2 score. Reference:
Tour of Evaluation Metrics for Imbalanced Classification
Metrics for imbalanced data (simply explained)
NEW QUESTION # 121
......
Our Professional-Machine-Learning-Engineer exam torrent is available in different versions. Whether you like to study on a computer or enjoy reading paper materials, our test prep can meet your needs. Our PDF version of the Professional-Machine-Learning-Engineer quiz guide is available for customers to print. You can print it out, so you can practice it repeatedly conveniently. Our Professional-Machine-Learning-Engineer test prep take full account of your problems and provide you with reliable services and help you learn and improve your ability and solve your problems effectively. Once you choose our Professional-Machine-Learning-Engineer Quiz guide, you have chosen the path to success. We are confident and able to help you realize your dream. A higher social status and higher wages will not be illusory. I will introduce you to the advantages of our Professional-Machine-Learning-Engineer exam torrent.
Download Professional-Machine-Learning-Engineer Free Dumps: https://www.actual4labs.com/Google/Professional-Machine-Learning-Engineer-actual-exam-dumps.html
BONUS!!! Download part of Actual4Labs Professional-Machine-Learning-Engineer dumps for free: https://drive.google.com/open?id=1YCi2JOTZgjOsr4HX3YbhHzBiTtzzFTR_