ハイパスレートのDatabricks-Certified-Professional-Data-Engineer受験料過去問一回合格-100%合格率のDatabricks-Certified-Professional-Data-Engineer資格関連題

無料でクラウドストレージから最新のFast2test Databricks-Certified-Professional-Data-Engineer PDFダンプをダウンロードする:https://drive.google.com/open?id=1K-ir8jIkdO4Q1vswSqr1ju1kDcB6BgvA
我々のソフトを利用してDatabricksのDatabricks-Certified-Professional-Data-Engineer試験失敗したら全額で返金するという承諾は不自信ではなく、我々のお客様への誠な態度を表わしたいです。我々はあなたに試験に安心させます。それだけでなく、あなたに我々のアフターサービスに安心させます。
DataBricks認定プロフェッショナルデータエンジニア認定は、DataBricksプラットフォームの使用に関する専門知識を実証したいデータエンジニアにとって貴重な資格です。雇用主に候補者と従業員のスキルを特定して検証する方法を提供します。また、データエンジンがDataBricksプラットフォームを使用してスケーラブルで信頼できるデータパイプラインを構築および維持する習熟度を実証することにより、キャリアを進めるのに役立ちます。
試験の準備をするために、DataBricksは、オンラインコース、ワークショップ、認定ブートキャンプなど、さまざまなトレーニングリソースを提供しています。これらのリソースは、DataBricksプラットフォーム上のデータエンジニアリング、データサイエンス、機械学習、データ分析などのトピックをカバーしています。さらに、候補者はDataBricks Academyにアクセスすることもできます。これは、自己ペースの学習モジュールと実践試験を提供して、認定試験の準備を支援することもできます。
>> Databricks-Certified-Professional-Data-Engineer受験料過去問 <<
有難い-効率的なDatabricks-Certified-Professional-Data-Engineer受験料過去問試験-試験の準備方法Databricks-Certified-Professional-Data-Engineer資格関連題
Databricks-Certified-Professional-Data-Engineerの最新のダンプ資料を購入することに決めた場合は、支払い用のクレジットカードを準備してください。 ほとんどの国では、クレジットカードをサポートしています。 PDFバージョンまたはソフトバージョン、またはDatabricks Databricks-Certified-Professional-Data-Engineerの最新ダンプのパッケージをクリックしてカートに追加し、電子メールアドレス、割引(ある場合)を入力して、支払いをクリックしてから、クレジットカード支払いへのページ転送を行うことができます。 お支払い後、システムからDatabricks-Certified-Professional-Data-Engineer最新ダンプのダウンロードリンク、アカウント、パスワードを含むメールが送信されます。リンクをクリックしてすぐにダウンロードできます。
Databricks認定プロフェッショナルデータエンジニア試験に合格することは、どのデータエンジニアにとっても大きな成果です。候補者は、Databricksの操作において高いレベルの専門知識を持ち、複雑なデータパイプラインを設計および管理できることを示しています。認定は雇用主によって高く評価されており、新しいキャリアの機会とより高い給与につながる可能性があります。
Databricks Certified Professional Data Engineer Exam 認定 Databricks-Certified-Professional-Data-Engineer 試験問題 (Q98-Q103):
質問 # 98
A data engineer is configuring Delta Sharing for a Databricks-to-Databricks scenario to optimize read performance. The recipient needs to perform time travel queries and streaming reads on shared sales data.
Which configuration will provide the optimal performance while enabling these capabilities?
- A. Share the entire schema WITHOUT HISTORY and rely on recipient-side caching for performance.
- B. Share tables WITH HISTORY, ensure tables don't have partitioning enabled, and enable CDF before sharing.
- C. Use the open sharing protocol instead of Databricks-to-Databricks sharing for better performance.
- D. Share tables WITHOUT HISTORY and enable partitioning for better query performance.
正解:B
解説:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
The official Delta Sharing guidance specifies that in order for recipients to use time travel queries and streaming reads, providers must share Delta tables WITH HISTORY. Sharing history ensures the Delta log is included, which enables efficient access to table snapshots and incremental data streams. Additionally, Change Data Feed (CDF) must be enabled prior to sharing if downstream consumers require streaming CDC queries. Without history, recipients cannot perform time travel or streaming queries. Open sharing supports static Delta tables but lacks streaming support. Therefore, sharing tables WITH HISTORY and enabling CDF is the required configuration for both performance and functionality.
質問 # 99
Which of the following Auto loader structured streaming commands successfully performs a hop from the landing area into Bronze?
- A. 1.spark\
2..readStream\
3..load(rawSalesLocation)\
4..writeStream \
5..option("checkpointLocation", checkpointPath).outputMode("append")\
6..table("uncleanedSales") - B. 1.spark\
2..readStream\
3..format("csv")\
4..option("cloudFiles.schemaLocation", checkpoint_directory)\
5..load("landing")\
6..writeStream.option("checkpointLocation", checkpoint_directory)\
7..table(raw) - C. 1.spark\
2..readStream\
3..format("cloudFiles")\
4..option("cloudFiles.format","csv")\
5..option("cloudFiles.schemaLocation", checkpoint_directory)\
6..load("landing")\
7..writeStream.option("checkpointLocation", checkpoint_directory)\
8..table(raw)
(Correct) - D. 1.spark\
2..read\
3..format("cloudFiles")\
4..option("cloudFiles.format","csv")\
5..option("cloudFiles.schemaLocation", checkpoint_directory)\
6..load("landing")\
7..writeStream.option("checkpointLocation", checkpoint_directory)\
8..table(raw) - E. 1.spark\
2..read\
3..load(rawSalesLocation) \
4..writeStream\
5..option("checkpointLocation", checkpointPath) \
6..outputMode("append")\
7..table("uncleanedSales")
正解:C
解説:
Explanation
The answer is
1.spark\
2..readStream\
3..format("cloudFiles") \# use Auto loader
4..option("cloudFiles.format","csv") \ # csv format files
5..option("cloudFiles.schemaLocation", checkpoint_directory)\
6..load('landing')\
7..writeStream.option("checkpointLocation", checkpoint_directory)\
8..table(raw)
Note: if you chose the below option which is incorrect because it does not have readStream
1.spark.read.format("cloudFiles")
2..option("cloudFiles.format","csv")
3....
4...
5...
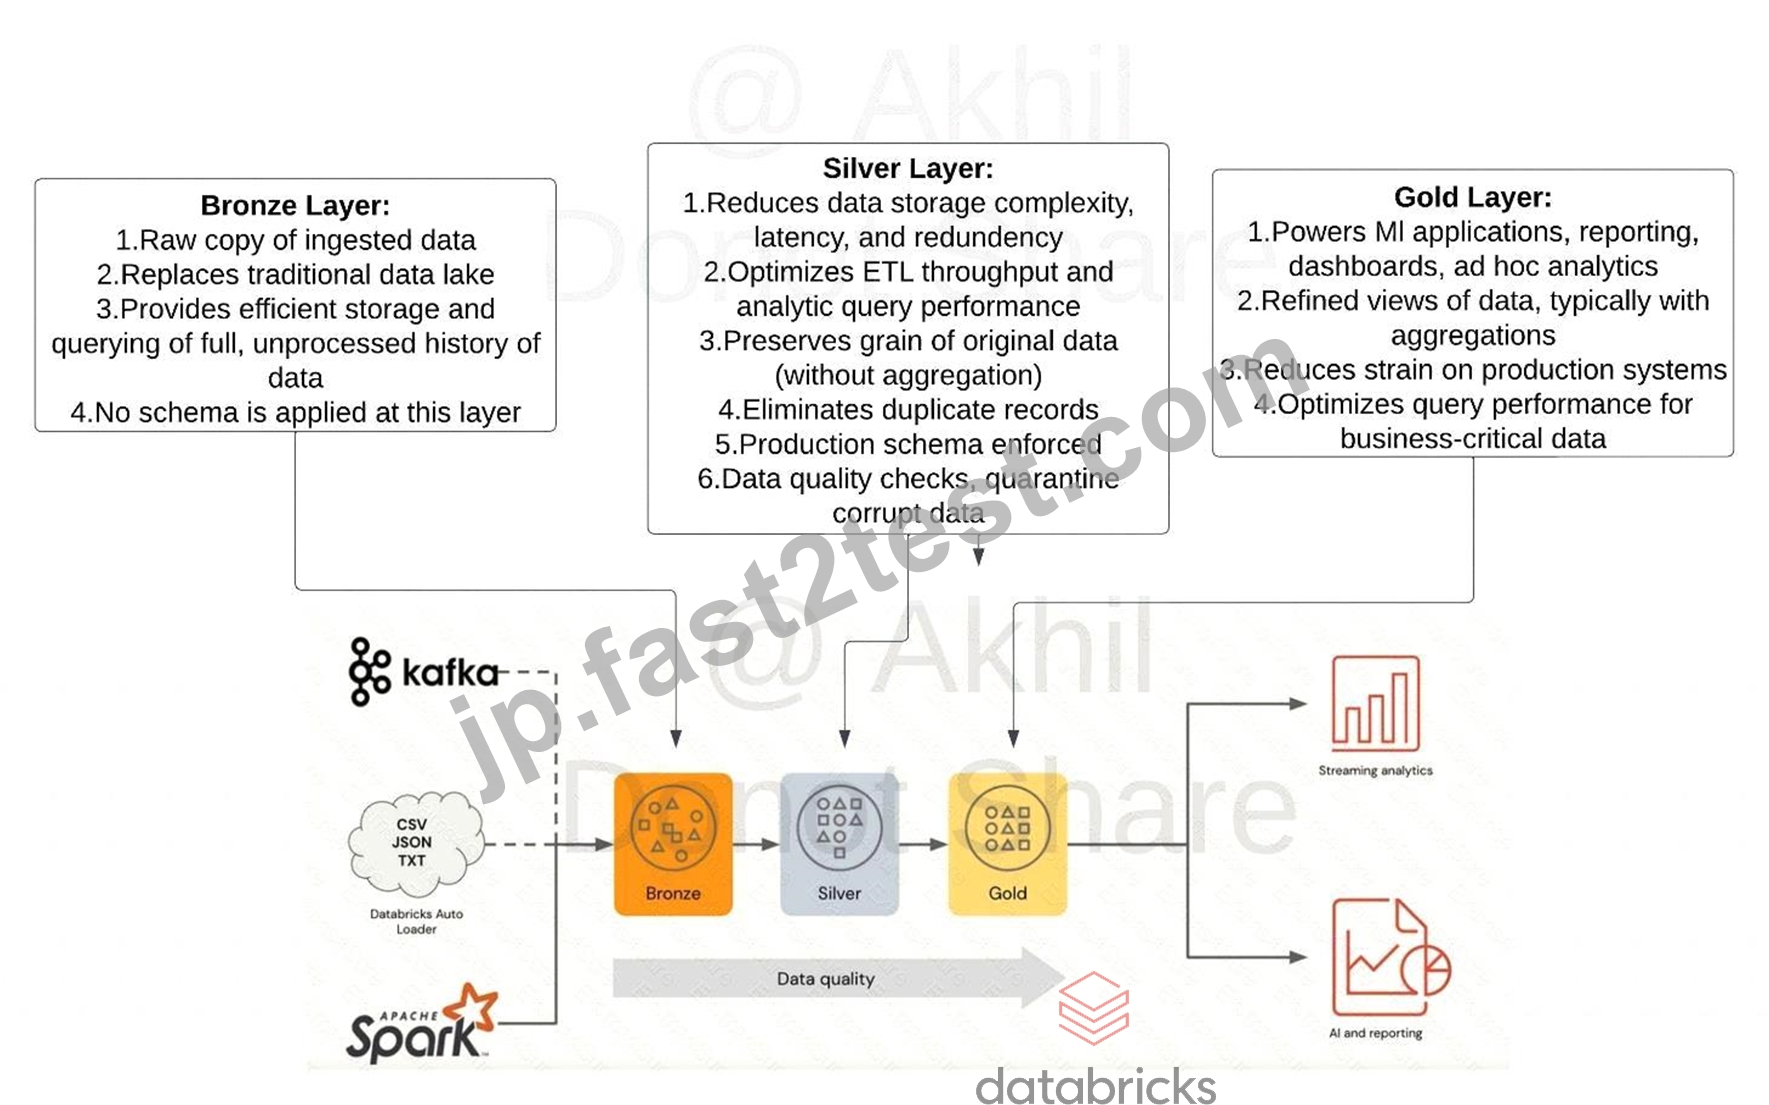
Exam focus: Please review the below image and understand the role of each layer(bronze, silver, gold) in medallion architecture, you will see varying questions targeting each layer and its purpose.
Sorry I had to add the watermark some people in Udemy are copying my content.
A diagram of a house Description automatically generated with low confidence
質問 # 100
A Structured Streaming job deployed to production has been resulting in higher than expected cloud storage costs. At present, during normal execution, each micro-batch of data is processed in less than 3 seconds; at least 12 times per minute, a micro-batch is processed that contains 0 records. The streaming write was configured using the default trigger settings. The production job is currently scheduled alongside many other Databricks jobs in a workspace with instance pools provisioned to reduce start-up time for jobs with batch execution. Holding all other variables constant and assuming records need to be processed in less than 10 minutes, which adjustment will meet the requirement?
- A. Use the trigger once option and configure a Databricks job to execute the query every 10 minutes; this approach minimizes costs for both compute and storage.
- B. Set the trigger interval to 10 minutes; each batch calls APIs in the source storage account, so decreasing trigger frequency to the maximum allowable threshold should minimize this cost.
- C. Set the trigger interval to 3 seconds; the default trigger interval is consuming too many records per batch, resulting in spill to disk that can increase volume costs.
- D. Set the trigger interval to 500 milliseconds; setting a small but non-zero trigger interval ensures that the source is not queried too frequently.
正解:A
解説:
* Exact extract: "If no trigger is specified, the default processing-time trigger runs micro-batches as fast as possible."
* Exact extract: "Trigger once processes all available data once and then stops." References: Structured Streaming triggers; Databricks Jobs and job clusters.
質問 # 101
A Delta Lake table was created with the below query:
Realizing that the original query had a typographical error, the below code was executed:
ALTER TABLE prod.sales_by_stor RENAME TO prod.sales_by_store
Which result will occur after running the second command?
- A. All related files and metadata are dropped and recreated in a single ACID transaction.
- B. The table name change is recorded in the Delta transaction log.
- C. The table reference in the metastore is updated and no data is changed.
- D. A new Delta transaction log Is created for the renamed table.
- E. The table reference in the metastore is updated and all data files are moved.
正解:C
解説:
The query uses the CREATE TABLE USING DELTA syntax to create a Delta Lake table from an existing Parquet file stored in DBFS. The query also uses the LOCATION keyword to specify the path to the Parquet file as /mnt/finance_eda_bucket/tx_sales.parquet. By using the LOCATION keyword, the query creates an external table, which is a table that is stored outside of the default warehouse directory and whose metadata is not managed by Databricks. An external table can be created from an existing directory in a cloud storage system, such as DBFS or S3, that contains data files in a supported format, such as Parquet or CSV.
The result that will occur after running the second command is that the table reference in the metastore is updated and no data is changed. The metastore is a service that stores metadata about tables, such as their schema, location, properties, and partitions. The metastore allows users to access tables using SQL commands or Spark APIs without knowing their physical location or format. When renaming an external table using the ALTER TABLE RENAME TO command, only the table reference in the metastore is updated with the new name; no data files or directories are moved or changed in the storage system. The table will still point to the same location and use the same format as before. However, if renaming a managed table, which is a table whose metadata and data are both managed by Databricks, both the table reference in the metastore and the data files in the default warehouse directory are moved and renamed accordingly. Verified References:
[Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "ALTER TABLE RENAME TO" section; Databricks Documentation, under "Metastore" section; Databricks Documentation, under "Managed and external tables" section.
質問 # 102
A data engineer is using Lakeflow Declarative Pipelines Expectations feature to track the data quality of their incoming sensor data. Periodically, sensors send bad readings that are out of range, and they are currently flagging those rows with a warning and writing them to the silver table along with the good data. They've been given a new requirement - the bad rows need to be quarantined in a separate quarantine table and no longer included in the silver table.
This is the existing code for their silver table:
@dlt.table
@dlt.expect("valid_sensor_reading", "reading < 120")
def silver_sensor_readings():
return spark.readStream.table("bronze_sensor_readings")
What code will satisfy the requirements?
- A. @dlt.table
@dlt.expect("valid_sensor_reading", "reading < 120")
def silver_sensor_readings():
return spark.readStream.table("bronze_sensor_readings")
@dlt.table
@dlt.expect("invalid_sensor_reading", "reading >= 120")
def quarantine_sensor_readings():
return spark.readStream.table("bronze_sensor_readings") - B. @dlt.table
@dlt.expect_or_drop("valid_sensor_reading", "reading < 120")
def silver_sensor_readings():
return spark.readStream.table("bronze_sensor_readings")
@dlt.table
@dlt.expect("invalid_sensor_reading", "reading >= 120")
def quarantine_sensor_readings():
return spark.readStream.table("bronze_sensor_readings") - C. @dlt.table
@dlt.expect_or_drop("valid_sensor_reading", "reading < 120")
def silver_sensor_readings():
return spark.readStream.table("bronze_sensor_readings")
@dlt.table
@dlt.expect("invalid_sensor_reading", "reading < 120")
def quarantine_sensor_readings():
return spark.readStream.table("bronze_sensor_readings") - D. @dlt.table
@dlt.expect_or_drop("valid_sensor_reading", "reading < 120")
def silver_sensor_readings():
return spark.readStream.table("bronze_sensor_readings")
@dlt.table
@dlt.expect_or_drop("invalid_sensor_reading", "reading >= 120")
def quarantine_sensor_readings():
return spark.readStream.table("bronze_sensor_readings")
正解:A
解説:
Comprehensive and Detailed Explanation from Databricks Documentation:
Lakeflow Declarative Pipelines (DLT) supports data quality enforcement using @dlt.expect, @dlt.expect_or_drop, and @dlt.expect_all.
@dlt.expect applies a rule and records whether rows pass or fail the condition but does not drop failing rows. Instead, failing rows can be written to a quarantine table.
@dlt.expect_or_drop enforces that only rows passing the condition flow downstream, dropping bad records automatically.
In this case, the requirement is:
Good rows (reading < 120) go to the silver table.
Bad rows (reading >= 120) go to a quarantine table.
Bad rows should not be included in silver.
The correct implementation is Option A, where:
The silver table uses @dlt.expect to validate reading < 120. These rows flow normally.
The quarantine table applies an expectation for reading >= 120, ensuring bad records are captured separately.
Other options are incorrect:
Option B/D: These either use expect_or_drop incorrectly or apply wrong conditions, leading to dropped rows without quarantining properly.
Option C: Uses expect_or_drop for both tables, which would discard bad rows instead of persisting them into a quarantine table.
Thus, Option A meets the business requirement to split good and bad data streams while ensuring both are captured for auditing and processing.
質問 # 103
......
Databricks-Certified-Professional-Data-Engineer資格関連題: https://jp.fast2test.com/Databricks-Certified-Professional-Data-Engineer-premium-file.html
- Databricks-Certified-Professional-Data-Engineer日本語認定 🍫 Databricks-Certified-Professional-Data-Engineer PDF 🏝 Databricks-Certified-Professional-Data-Engineer無料ダウンロード 🤚 ウェブサイト⇛ www.passtest.jp ⇚から《 Databricks-Certified-Professional-Data-Engineer 》を開いて検索し、無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer日本語的中対策
- Databricks-Certified-Professional-Data-Engineer認定試験、Databricks-Certified-Professional-Data-Engineer練習問題 、Databricks-Certified-Professional-Data-Engineer有効な練習資料 ✏ ⇛ www.goshiken.com ⇚サイトにて➠ Databricks-Certified-Professional-Data-Engineer 🠰問題集を無料で使おうDatabricks-Certified-Professional-Data-Engineer受験対策解説集
- Databricks Databricks-Certified-Professional-Data-Engineer受験料過去問: Databricks Certified Professional Data Engineer Exam - www.it-passports.com 1年間の無料アップデート ⬜ ☀ Databricks-Certified-Professional-Data-Engineer ️☀️を無料でダウンロード⮆ www.it-passports.com ⮄で検索するだけDatabricks-Certified-Professional-Data-Engineer問題と解答
- Databricks-Certified-Professional-Data-Engineer試験の準備方法|効果的なDatabricks-Certified-Professional-Data-Engineer受験料過去問試験|正確的なDatabricks Certified Professional Data Engineer Exam資格関連題 🐁 ☀ www.goshiken.com ️☀️を開き、▶ Databricks-Certified-Professional-Data-Engineer ◀を入力して、無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer日本語練習問題
- Databricks-Certified-Professional-Data-Engineer試験復習赤本 🗨 Databricks-Certified-Professional-Data-Engineer日本語版トレーリング 👵 Databricks-Certified-Professional-Data-Engineer試験復習赤本 🙍 ウェブサイト▷ www.xhs1991.com ◁を開き、✔ Databricks-Certified-Professional-Data-Engineer ️✔️を検索して無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer無料ダウンロード
- Databricks-Certified-Professional-Data-Engineer PDF 🏴 Databricks-Certified-Professional-Data-Engineer問題集 🤔 Databricks-Certified-Professional-Data-Engineer更新版 🤼 ▶ Databricks-Certified-Professional-Data-Engineer ◀を無料でダウンロード➥ www.goshiken.com 🡄ウェブサイトを入力するだけDatabricks-Certified-Professional-Data-Engineer問題と解答
- 信頼的るDatabricks-Certified-Professional-Data-Engineer受験料過去問 - 資格試験のリーダー - 検証するDatabricks Databricks Certified Professional Data Engineer Exam ✍ ▶ jp.fast2test.com ◀で使える無料オンライン版⮆ Databricks-Certified-Professional-Data-Engineer ⮄ の試験問題Databricks-Certified-Professional-Data-Engineer試験準備
- Databricks-Certified-Professional-Data-Engineer資格問題対応 ⚠ Databricks-Certified-Professional-Data-Engineer更新版 ⛲ Databricks-Certified-Professional-Data-Engineer日本語試験情報 🕶 ▛ Databricks-Certified-Professional-Data-Engineer ▟を無料でダウンロード⮆ www.goshiken.com ⮄ウェブサイトを入力するだけDatabricks-Certified-Professional-Data-Engineer問題と解答
- Databricks-Certified-Professional-Data-Engineer試験復習赤本 ↕ Databricks-Certified-Professional-Data-Engineer受験対策解説集 🕝 Databricks-Certified-Professional-Data-Engineer日本語試験情報 🈺 ウェブサイト➠ www.passtest.jp 🠰から{ Databricks-Certified-Professional-Data-Engineer }を開いて検索し、無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer関連資格知識
- 100%合格率のDatabricks-Certified-Professional-Data-Engineer受験料過去問試験-試験の準備方法-信頼的なDatabricks-Certified-Professional-Data-Engineer資格関連題 ☢ サイト( www.goshiken.com )で▷ Databricks-Certified-Professional-Data-Engineer ◁問題集をダウンロードDatabricks-Certified-Professional-Data-Engineer日本語認定
- Databricks-Certified-Professional-Data-Engineer問題集 🥉 Databricks-Certified-Professional-Data-Engineer復習過去問 🆒 Databricks-Certified-Professional-Data-Engineer資格専門知識 💻 今すぐ「 www.mogiexam.com 」を開き、《 Databricks-Certified-Professional-Data-Engineer 》を検索して無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer日本語版トレーリング
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
さらに、Fast2test Databricks-Certified-Professional-Data-Engineerダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1K-ir8jIkdO4Q1vswSqr1ju1kDcB6BgvA