Our supporter of Databricks-Certified-Professional-Data-Engineer study guide has exceeded tens of thousands around the world, which directly reflects the quality of them. Because the exam may put a heavy burden on your shoulder while our Databricks-Certified-Professional-Data-Engineer practice materials can relieve you of those troubles with time passing by. Just spent some time regularly on our Databricks-Certified-Professional-Data-Engineer Exam simulation, your possibility of getting it will be improved greatly. For your information, the passing rate of our Databricks-Certified-Professional-Data-Engineer training engine is over 98% up to now.
| Section | Weight | Objectives |
|---|---|---|
| Data Processing with Spark | 25-30% | - Python and SQL for data engineering
|
| Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
|
| Data Ingestion | 15-20% | - Batch ingestion methods
|
| Pipeline Development and Orchestration | 10-15% | - Databricks workflows
|
| Delta Lake | 20-25% | - Delta Lake operations
|
>> Databricks-Certified-Professional-Data-Engineer Valid Exam Registration <<
Cease to struggle and you cease to live. Only by continuous learning can we not be surpassed by others. Many people do not like to study and think that learning is a very vexing thing. This kind of cognition makes their careers stagnate. Databricks-Certified-Professional-Data-Engineer test question will change your perception. Databricks-Certified-Professional-Data-Engineer learning dumps aim to help students learn easily and effectively that has been developed over many years by many industry experts. With Databricks-Certified-Professional-Data-Engineer study tool, you no longer need to look at a drowsy textbook. You do not need to study day and night. With Databricks-Certified-Professional-Data-Engineer learning dumps, you only need to spend 20-30 hours on studying, and then you can easily pass the exam. At the same time, the language in Databricks-Certified-Professional-Data-Engineer test question is very simple and easy to understand. Even if you are a newcomer who has just entered the industry, you can learn all the knowledge points without any obstacles. We believe that Databricks-Certified-Professional-Data-Engineer study tool will make you fall in love with learning. Come and buy it now.
NEW QUESTION # 107
A Delta Lake table was created with the below query: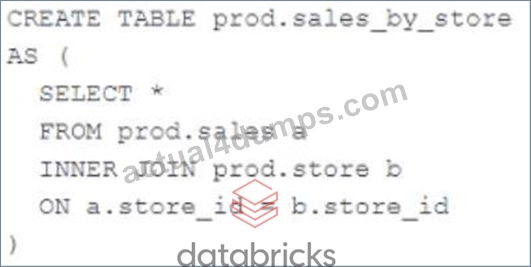
Consider the following query:
DROP TABLE prod.sales_by_store -
If this statement is executed by a workspace admin, which result will occur?
Answer: C
Explanation:
When a table is dropped in Delta Lake, the table is removed from the catalog and the data is deleted. This is because Delta Lake is a transactional storage layer that provides ACID guarantees. When a table is dropped, the transaction log is updated to reflect the deletion of the table and the data is deleted from the underlying storage. References :
* https://docs.databricks.com/delta/quick-start.html#drop-a-table
* https://docs.databricks.com/delta/delta-batch.html#drop-table
NEW QUESTION # 108
A platform engineer is creating catalogs and schemas for the development team to use.
The engineer has created an initial catalog, catalog_A, and initial schema, schema_A. The engineer has also granted USE CATALOG, USE SCHEMA, and CREATE TABLE to the development team so that the engineer can begin populating the schema with new tables.
Despite being owner of the catalog and schema, the engineer noticed that they do not have access to the underlying tables in Schema_A.
What explains the engineer's lack of access to the underlying tables?
Answer: D
Explanation:
In Databricks, catalogs, schemas (or databases), and tables are managed through the Unity Catalog or Hive Metastore, depending on the environment. Permissions and ownership within these structures are governed by access control lists (ACLs).
* Catalog and Schema Ownership: When a platform engineer creates a catalog (such as catalog_A) and schema (such as schema_A), they automatically become the owner of those entities. This ownership gives them control over granting permissions for those entities (i.e., granting the USE CATALOG and USE SCHEMA privileges to others). However, ownership of the catalog or schema does not automatically extend to ownership or permission of individual tables within that schema.
* Table Permissions: For tables within a schema, the permission model is more granular. The table creator (i.e., whoever creates the table) is automatically assigned as the owner of that table. In this case, the platform engineer owns the schema but does not automatically inherit permissions to any table created within the schema unless explicitly granted by the table's owner or unless they grant permissions to themselves.
* Why the Engineer Lacks Access: The platform engineer notices that they do not have access to the underlying tables in schema_A despite being the owner of the schema. This occurs because the schema's ownership does not cascade to the tables. The engineer must either:
* Grant permissions to themselves for the tables in schema_A, or
* Be granted permissions by whoever created the tables within the schema.
* Resolution: As the owner of the schema, the platform engineer can easily grant themselves the required permissions (such as SELECT, INSERT, etc.) for the tables in the schema. This explains why the owner of a schema may not automatically have access to the tables and must take explicit steps to acquire those permissions.
References
* Databricks Unity Catalog Documentation: Manage Permissions
* [Databricks Permissions and Ownership (https://docs.databricks.com/security/access-control/workspace-acl.html#permissions
NEW QUESTION # 109
The data governance team is reviewing user for deleting records for compliance with GDPR. The following logic has been implemented to propagate deleted requests from the user_lookup table to the user aggregate table.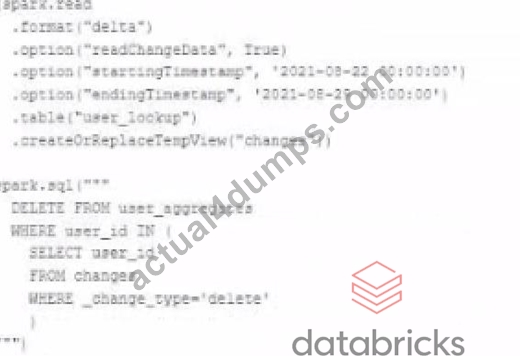
Assuming that user_id is a unique identifying key and that all users have requested deletion have been removed from the user_lookup table, which statement describes whether successfully executing the above logic guarantees that the records to be deleted from the user_aggregates table are no longer accessible and why?
Answer: C
Explanation:
The DELETE operation in Delta Lake is ACID compliant, which means that once the operation is successful, the records are logically removed from the table. However, the underlying files that contained these records may still exist and be accessible via time travel to older versions of the table. To ensure that these records are physically removed and compliance with GDPR is maintained, a VACUUM command should be used to clean up these data files after a certain retention period. The VACUUM command will remove the files from the storage layer, and after this, the records will no longer be accessible.
NEW QUESTION # 110
A data engineer is running a groupBy aggregation on a massive user activity log grouped by user_id. A few users have millions of records, causing task skew and long runtimes.
Which technique will fix the skew in this aggregation?
Answer: B
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
Task skew occurs when a small subset of keys holds a disproportionate amount of data, causing certain tasks to process significantly more records than others. Databricks documentation recommends salting as an effective mitigation technique.
Salting introduces a random or calculated prefix to skewed keys, distributing records across multiple partitions and balancing the workload during the shuffle stage. After aggregation, a second pass re-aggregates results by removing the prefix to restore key integrity.
Increasing memory (B) does not resolve distribution imbalance; reduceByKey (C) still triggers shuffles; and filtering (D) would remove valid business data. Hence, salting is the correct and officially recommended approach to address skew in Spark aggregations.
NEW QUESTION # 111
A data engineer, User A, has promoted a new pipeline to production by using the REST API to programmatically create several jobs. A DevOps engineer, User B, has configured an external orchestration tool to trigger job runs through the REST API. Both users authorized the REST API calls using their personal access tokens.
Which statement describes the contents of the workspace audit logs concerning these events?
Answer: A
Explanation:
The events are that a data engineer, User A, has promoted a new pipeline to production by using the REST API to programmatically create several jobs, and a DevOps engineer, User B, has configured an external orchestration tool to trigger job runs through the REST API. Both users authorized the REST API calls using their personal access tokens. The workspace audit logs are logs that record user activities in a Databricks workspace, such as creating, updating, or deleting objects like clusters, jobs, notebooks, or tables. The workspace audit logs also capture the identity of the user who performed each activity, as well as the time and details of the activity. Because these events are managed separately, User A will have their identity associated with the job creation events and User B will have their identity associated with the job run events in the workspace audit logs. Verified Reference: [Databricks Certified Data Engineer Professional], under "Databricks Workspace" section; Databricks Documentation, under "Workspace audit logs" section.
NEW QUESTION # 112
......
The emerging field of information technology has created a vast space for Databricks Databricks-Certified-Professional-Data-Engineer certification exam holders to get promotions and high-paying jobs. Thousands of candidates don't clear the Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) exam because they have short time and they don't prepare for the Databricks-Certified-Professional-Data-Engineer exam questions. It results in a loss of time, money, and confidence. Actual4Dumps is here to save you from this unfortunate situation with its Real Databricks-Certified-Professional-Data-Engineer Exam Questions. These Databricks Databricks-Certified-Professional-Data-Engineer Exam Questions are enough to ace the Databricks-Certified-Professional-Data-Engineer exam and move forward into Databricks sector with full ease and confidence.
Valid Study Databricks-Certified-Professional-Data-Engineer Questions: https://www.actual4dumps.com/Databricks-Certified-Professional-Data-Engineer-study-material.html