New Certification Databricks-Certified-Professional-Data-Engineer Exam Cost | High-quality Databricks-Certified-Professional-Data-Engineer: Databricks Certified Professional Data Engineer Exam 100% Pass

Whether for a student or an office worker, obtaining Databricks-Certified-Professional-Data-Engineer certificate can greatly enhance the individual's competitiveness in the future career. Try our Databricks-Certified-Professional-Data-Engineer study materials, which are revised by hundreds of experts according to the changes in the syllabus and the latest developments in theory and practice. Once you choose Databricks-Certified-Professional-Data-Engineer training dumps, passing the exam one time is no longer a dream.
| Section | Weight | Objectives |
|---|
| Data Governance | 7% | - Data lineage and metadata tracking
- Policy enforcement
- Unity Catalog management
|
| Data Transformation, Cleansing, and Quality | 10% | - Standardization and normalization
- Data validation and quality checks
- Handling missing or inconsistent data
|
| Debugging and Deploying | 10% | - Troubleshooting pipelines and errors
- Deployment using bundles, CLI, and APIs
- CI/CD and DevOps practices
|
| Data Sharing and Federation | 5% | - Cross-workspace and cross-cloud access
- Unity Catalog data sharing
|
| Ensuring Data Security and Compliance | 10% | - Access control and permissions
- Data encryption and masking
- Compliance standards implementation
|
| Developing Code for Data Processing using Python and SQL | 22% | - Batch and incremental processing logic
- Data transformation and aggregation
- Integration with Databricks APIs and tools
|
| Monitoring and Alerting | 10% | - Pipeline observability and logging
- Performance and health monitoring
- Setting up alerts and notifications
|
| Cost & Performance Optimisation | 13% | - Storage optimization (partitioning, Z-order, indexing)
- Query optimization and caching
- Cluster configuration and scaling
|
| Data Modelling | 6% | - Schema design and management
- Delta Lake table design
- Medallion Architecture implementation
|
| Data Ingestion & Acquisition | 7% | - Schema inference and evolution
- Connecting to diverse data sources
- Auto Loader and streaming ingestion
|
>> Certification Databricks-Certified-Professional-Data-Engineer Exam Cost <<
Reliable Certification Databricks-Certified-Professional-Data-Engineer Exam Cost - Practical & First-Grade Databricks-Certified-Professional-Data-Engineer Materials Free Download for Databricks Databricks-Certified-Professional-Data-Engineer Exam
Our Databricks-Certified-Professional-Data-Engineer exam dumps strive for providing you a comfortable study platform and continuously explore more functions to meet every customer’s requirements. We may foresee the prosperous talent market with more and more workers attempting to reach a high level through the Databricks certification. To deliver on the commitments of our Databricks-Certified-Professional-Data-Engineer Test Prep that we have made for the majority of candidates, we prioritize the research and development of our Databricks-Certified-Professional-Data-Engineer test braindumps, establishing action plans with clear goals of helping them get the Databricks certification.
Databricks Certified Professional Data Engineer Exam Sample Questions (Q88-Q93):
NEW QUESTION # 88
A table named user_ltv is being used to create a view that will be used by data analysts on various teams. Users in the workspace are configured into groups, which are used for setting up data access using ACLs.
The user_ltv table has the following schema:
email STRING, age INT, ltv INT
The following view definition is executed:
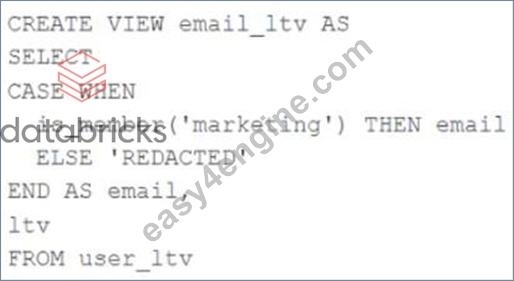
An analyst who is not a member of the marketing group executes the following query:
SELECT * FROM email_ltv
Which statement describes the results returned by this query?
- A. Only the email and itv columns will be returned; the email column will contain all null values.
- B. The email, age. and ltv columns will be returned with the values in user ltv.
- C. Only the email and ltv columns will be returned; the email column will contain the string "REDACTED" in each row.
- D. The email and ltv columns will be returned with the values in user itv.
- E. Three columns will be returned, but one column will be named "redacted" and contain only null values.
Answer: C
Explanation:
The code creates a view called email_ltv that selects the email and ltv columns from a table called user_ltv, which has the following schema: email STRING, age INT, ltv INT. The code also uses the CASE WHEN expression to replace the email values with the string "REDACTED" if the user is not a member of the marketing group. The user who executes the query is not a member of the marketing group, so they will only see the email and ltv columns, and the email column will contain the string "REDACTED" in each row. Verified Reference: [Databricks Certified Data Engineer Professional], under "Lakehouse" section; Databricks Documentation, under "CASE expression" section.
NEW QUESTION # 89
A data engineering team is in the process of converting their existing data pipeline to utilize Auto Loader for
incremental processing in the ingestion of JSON files. One data engineer comes across the following code
block in the Auto Loader documentation:
1. (streaming_df = spark.readStream.format("cloudFiles")
2. .option("cloudFiles.format", "json")
3. .option("cloudFiles.schemaLocation", schemaLocation)
4. .load(sourcePath))
Assuming that schemaLocation and sourcePath have been set correctly, which of the following changes does
the data engineer need to make to convert this code block to use Auto Loader to ingest the data?
- A. The data engineer needs to add the .autoLoader line before the .load(sourcePath) line
- B. The data engineer needs to change the format("cloudFiles") line to format("autoLoader")
- C. There is no change required. The data engineer needs to ask their administrator to turn on Auto Loader
- D. There is no change required. The inclusion of format("cloudFiles") enables the use of Auto Loader
- E. There is no change required. Databricks automatically uses Auto Loader for streaming reads
Answer: D
NEW QUESTION # 90
A task orchestrator has been configured to run two hourly tasks. First, an outside system writes Parquet data to a directory mounted at /mnt/raw_orders/. After this data is written, a Databricks job containing the following code is executed:
(spark.readStream
.format("parquet")
.load("/mnt/raw_orders/")
.withWatermark("time", "2 hours")
.dropDuplicates(["customer_id", "order_id"])
.writeStream
.trigger(once=True)
.table("orders")
)
Assume that the fields customer_id and order_id serve as a composite key to uniquely identify each order, and that the time field indicates when the record was queued in the source system. If the upstream system is known to occasionally enqueue duplicate entries for a single order hours apart, which statement is correct?
- A. The orders table will not contain duplicates, but records arriving more than 2 hours late will be ignored and missing from the table.
- B. The orders table will contain only the most recent 2 hours of records and no duplicates will be present.
- C. All records will be held in the state store for 2 hours before being deduplicated and committed to the orders table.
- D. Duplicate records enqueued more than 2 hours apart may be retained and the orders table may contain duplicate records with the same customer_id and order_id.
Answer: A
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
* Exact extract: "dropDuplicates with watermark performs stateful deduplication on the keys within the watermark delay."
* Exact extract: "Records older than the event-time watermark are considered late and may be dropped." References: Structured Streaming watermarking and deduplication; One-time trigger.
NEW QUESTION # 91
A Structured Streaming job deployed to production has been resulting in higher than expected cloud storage costs. At present, during normal execution, each micro-batch of data is processed in less than 3 seconds; at least 12 times per minute, a micro-batch is processed that contains 0 records. The streaming write was configured using the default trigger settings. The production job is currently scheduled alongside many other Databricks jobs in a workspace with instance pools provisioned to reduce start-up time for jobs with batch execution. Holding all other variables constant and assuming records need to be processed in less than 10 minutes, which adjustment will meet the requirement?
- A. Set the trigger interval to 500 milliseconds; setting a small but non-zero trigger interval ensures that the source is not queried too frequently.
- B. Set the trigger interval to 3 seconds; the default trigger interval is consuming too many records per batch, resulting in spill to disk that can increase volume costs.
- C. Use the trigger once option and configure a Databricks job to execute the query every 10 minutes; this approach minimizes costs for both compute and storage.
- D. Set the trigger interval to 10 minutes; each batch calls APIs in the source storage account, so decreasing trigger frequency to the maximum allowable threshold should minimize this cost.
Answer: C
Explanation:
* Exact extract: "If no trigger is specified, the default processing-time trigger runs micro-batches as fast as possible."
* Exact extract: "Trigger once processes all available data once and then stops." References: Structured Streaming triggers; Databricks Jobs and job clusters.
NEW QUESTION # 92
The following code has been migrated to a Databricks notebook from a legacy workload:
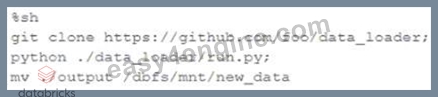
The code executes successfully and provides the logically correct results, however, it takes over 20 minutes to extract and load around 1 GB of data.
Which statement is a possible explanation for this behavior?
- A. Instead of cloning, the code should use %sh pip install so that the Python code can get executed in parallel across all nodes in a cluster.
- B. %sh executes shell code on the driver node. The code does not take advantage of the worker nodes or Databricks optimized Spark.
- C. Python will always execute slower than Scala on Databricks. The run.py script should be refactored to Scala.
- D. %sh triggers a cluster restart to collect and install Git. Most of the latency is related to cluster startup time.
- E. %sh does not distribute file moving operations; the final line of code should be updated to use %fs instead.
Answer: B
Explanation:
https://www.databricks.com/blog/2020/08/31/introducing-the-databricks-web-terminal.html The code is using %sh to execute shell code on the driver node. This means that the code is not taking advantage of the worker nodes or Databricks optimized Spark. This is why the code is taking longer to execute. A better approach would be to use Databricks libraries and APIs to read and write data from Git and DBFS, and to leverage the parallelism and performance of Spark. For example, you can use the Databricks Connect feature to run your Python code on a remote Databricks cluster, or you can use the Spark Git Connector to read data from Git repositories as Spark DataFrames.
NEW QUESTION # 93
......
Life is full of ups and downs. We cannot predicate what will happen in the future. To avoid being washed out by the artificial intelligence, we must keep absorbing various new knowledge. Our Databricks-Certified-Professional-Data-Engineer learning questions will inspire your motivation to improve yourself. Tens of thousands of our loyal customers are benefited from our Databricks-Certified-Professional-Data-Engineer Study Materials and lead a better life now after they achieve their Databricks-Certified-Professional-Data-Engineer certification.
Databricks-Certified-Professional-Data-Engineer Valid Exam Materials: https://www.easy4engine.com/Databricks-Certified-Professional-Data-Engineer-test-engine.html
- Pass Guaranteed Databricks Databricks-Certified-Professional-Data-Engineer Fantastic Certification Exam Cost 🔎 Simply search for ( Databricks-Certified-Professional-Data-Engineer ) for free download on ➽ www.easy4engine.com 🢪 🚚Databricks-Certified-Professional-Data-Engineer Reliable Test Objectives
- Databricks-Certified-Professional-Data-Engineer Dump with the Help of Pdfvce Exam Questions 🧚 Easily obtain ➤ Databricks-Certified-Professional-Data-Engineer ⮘ for free download through ⏩ www.pdfvce.com ⏪ 🤪New Databricks-Certified-Professional-Data-Engineer Exam Book
- 100% Pass Quiz 2026 Databricks Databricks-Certified-Professional-Data-Engineer Useful Certification Exam Cost 🟦 Search for ⇛ Databricks-Certified-Professional-Data-Engineer ⇚ and obtain a free download on ☀ www.exam4labs.com ️☀️ 🥣Databricks-Certified-Professional-Data-Engineer Reliable Mock Test
- Get the Real Databricks Databricks-Certified-Professional-Data-Engineer Exam Dumps In Different Formats 🐅 Search for ➠ Databricks-Certified-Professional-Data-Engineer 🠰 on { www.pdfvce.com } immediately to obtain a free download 🪂Free Databricks-Certified-Professional-Data-Engineer Braindumps
- Databricks-Certified-Professional-Data-Engineer Reliable Exam Price 🚟 New Databricks-Certified-Professional-Data-Engineer Exam Question 📴 New Databricks-Certified-Professional-Data-Engineer Exam Bootcamp 🚲 The page for free download of “ Databricks-Certified-Professional-Data-Engineer ” on ➤ www.validtorrent.com ⮘ will open immediately 🦪Databricks-Certified-Professional-Data-Engineer Reliable Exam Price
- 100% Pass Quiz 2026 Databricks Databricks-Certified-Professional-Data-Engineer Useful Certification Exam Cost 🥱 Search for ➡ Databricks-Certified-Professional-Data-Engineer ️⬅️ and download it for free on ( www.pdfvce.com ) website 🕦Databricks-Certified-Professional-Data-Engineer New Real Exam
- Databricks-Certified-Professional-Data-Engineer Reliable Test Objectives 🛒 Valid Databricks-Certified-Professional-Data-Engineer Exam Camp Pdf 📓 Free Databricks-Certified-Professional-Data-Engineer Braindumps ❎ Easily obtain free download of ➤ Databricks-Certified-Professional-Data-Engineer ⮘ by searching on ➡ www.troytecdumps.com ️⬅️ 📂Databricks-Certified-Professional-Data-Engineer Reliable Test Objectives
- Seeing The Certification Databricks-Certified-Professional-Data-Engineer Exam Cost Means that You Have Passed Half of Databricks Certified Professional Data Engineer Exam 🆗 Search for 【 Databricks-Certified-Professional-Data-Engineer 】 and easily obtain a free download on ⮆ www.pdfvce.com ⮄ 🦋Databricks-Certified-Professional-Data-Engineer Reliable Test Objectives
- Pass Guaranteed Quiz 2026 Unparalleled Databricks Databricks-Certified-Professional-Data-Engineer: Certification Databricks Certified Professional Data Engineer Exam Exam Cost 📓 Open website ⇛ www.prepawaypdf.com ⇚ and search for 《 Databricks-Certified-Professional-Data-Engineer 》 for free download 🔕Databricks-Certified-Professional-Data-Engineer New Real Exam
- Real Databricks-Certified-Professional-Data-Engineer Testing Environment 🔜 Free Databricks-Certified-Professional-Data-Engineer Braindumps 🛑 Databricks-Certified-Professional-Data-Engineer Reliable Exam Price 🙎 Download ( Databricks-Certified-Professional-Data-Engineer ) for free by simply searching on ✔ www.pdfvce.com ️✔️ 🏓Databricks-Certified-Professional-Data-Engineer Valid Study Guide
- 100% Pass Quiz 2026 Databricks Databricks-Certified-Professional-Data-Engineer Useful Certification Exam Cost 🧒 Search for “ Databricks-Certified-Professional-Data-Engineer ” and easily obtain a free download on 「 www.examdiscuss.com 」 🔹Databricks-Certified-Professional-Data-Engineer Reliable Exam Price
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, mahsaamini5421.blogspot.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, aprenderfotografia.online, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes