To gain a full understanding of our product please firstly look at the introduction of the features and the functions of our DP-750 exam torrent. The page of our product provide the demo and the aim to provide the demo is to let the you understand part of our titles before their purchase and see what form the software is after the you open it. The client can visit the page of our product on the website. So the client can understand our DP-750 Quiz torrent well and decide whether to buy our product or not at their wishes. The client can see the forms of the answers and the titles.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Prepare and process data | 30-35% | - Ingest and transform data
|
| Topic 2: Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
| Topic 3: Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
| Topic 4: Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
>> DP-750 Complete Exam Dumps <<
In the modern world, obtaining DP-750 certification is essential. With the growing popularity of Microsoft, the demand for professionals holding this Implementing Data Engineering Solutions Using Azure Databricks (DP-750) certification holders has increased significantly. Unfortunately, many candidates fail to pass the DP-750 Exam due to outdated Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam study material. Such failure can lead to the loss of time, money, and confidence.
NEW QUESTION # 41
You have an Azure Databricks workspace that uses serverless compute.
You need to ingest data by using Lakeflow Jobs. New records must be processed as soon as they become available.
Which type of job trigger should you use for the ingestion?
Answer: C
Explanation:
The best trigger type for this scenario is the Continuous trigger.
Immediate Processing: The Continuous trigger mode processes new records as soon as they arrive at the configured data sources. This matches your requirement to ingest and process records without waiting for an artificial time interval.
Native Serverless Support: When paired with serverless compute, Lakeflow Jobs efficiently manage resources by automatically scaling up or down according to the real-time stream volume.
Built-in Fault Tolerance: Continuous pipelines on Databricks automatically handle failures by retrying with an exponential backoff policy, keeping your automated ingestion operational 24/7 without manual intervention.
Reference:
https://docs.databricks.com/aws/en/jobs/continuous
NEW QUESTION # 42
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains two catalogs named Catalog1 and Catalog2.
An external application uses a service principal named SP1 to connect to a SQL warehouse.
You need to ensure that SP1 can query the data in Catalog1 and Catalog2. The solution must follow the principle of least privilege.
Which permissions should you grant to SP1 for the catalogs?
Answer: D
Explanation:
To ensure a service principal can query data in two specific catalogs while maintaining the principle of least privilege, you must assign the following permissions for each catalog:
Unified Catalog Permissions
USE CATALOG on the specific catalog: This is a prerequisite that allows the principal to see the catalog and its child objects.
USE SCHEMA on the schemas containing the data: This allows the principal to interact with the schemas within that catalog.
SELECT on the specific tables or views: This provides the actual read access required to query the data.
Reference:
https://learn.microsoft.com/en-us/purview/data-governance-roles-permissions
NEW QUESTION # 43
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Sales. Sales stores transaction data and contains the following columns:
* transactionjd (string)
* transaction date (date)
* amount (decimal)
You need to implement the following data quality requirements by using table-level data quality enforcement:
* amount must be greater than 0.
* transaction id must never be null.
* Invalid records must be rejected when data is written to the Sales table.
What should you do?
Answer: B
Explanation:
The correct answer is D - a NOT NULL constraint on transaction_id and a CHECK constraint on amount.
Delta Lake table constraints are enforced at write time by the Delta engine itself. A NOT NULL constraint rejects any INSERT or UPDATE that would place a null in transaction_id. A CHECK constraint with amount
> 0 rejects any row where amount is zero or negative. Combined, they implement exactly the stated quality rules: bad rows are rejected when data is written, not filtered away at read time.
Options A and C (SELECT with WHERE / views) are read-time constructs - they don't prevent invalid data from entering the table. A clever pipeline bypass could write directly to the table and skip the view entirely.
Option B (row-level security with WHERE conditions) is an access-control feature for restricting which rows users see, not for enforcing data quality on writes. Table constraints are the only mechanism that genuinely blocks bad data at the storage layer.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/delta-constraints
NEW QUESTION # 44
You have an Azure Databticks workspace that contains an all-purpose compute cluster named Cluster1.
Cluser1 is used for
interactive development.
You need to configure Cluster1 to meet the following requirements:
* Automatically add and remove worker nodes based on workload demand
* Automatically shut down when the cluster has been idle for a specific period.
What should you configure for each requirement? To answer, drag the appropriate options to the correct requirements. Each option may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content NOTE: Each correct selection is worth one point.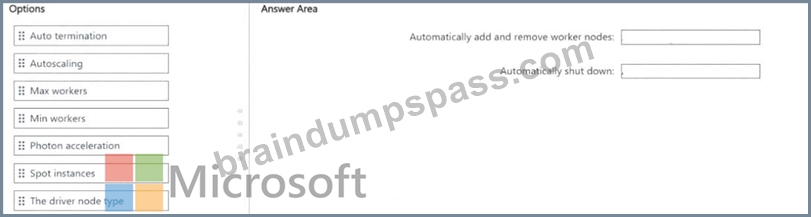
Answer:
Explanation: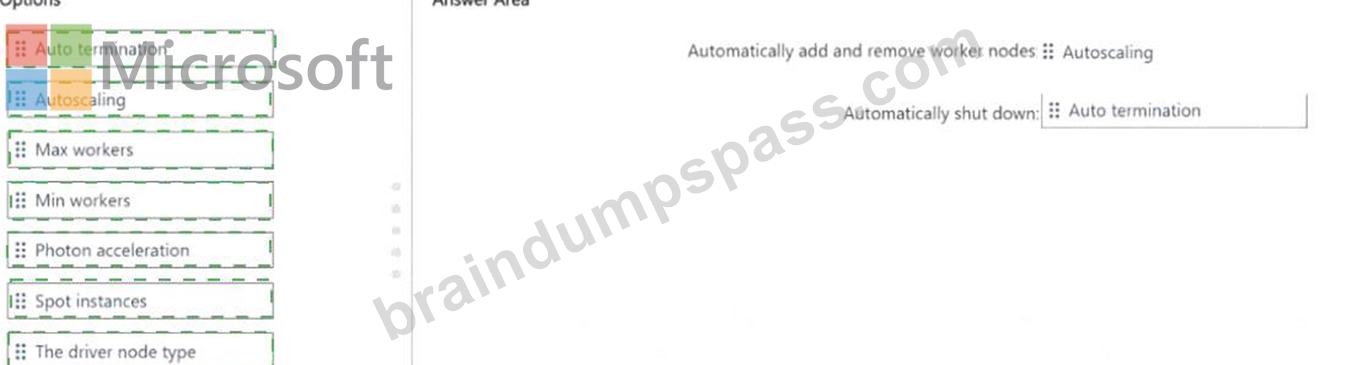
Explanation:
Two separate cluster settings address the two requirements:
Autoscaling handles the first requirement - dynamically adding workers when the workload is heavy and removing them when it lightens. You set a minimum and maximum node count, and Databricks adjusts the cluster size between those bounds based on task queue depth.
Auto-termination handles the second - the cluster shuts itself down after a configurable idle period (e.g., 30 minutes with no active queries), preventing wasted spend on a development cluster left running overnight.
These two settings are independent and complementary: autoscaling manages horizontal elasticity during active use, while auto-termination manages complete shutdown during inactivity. Both are configured in the cluster creation UI under the Compute section.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/configure#autoscaling
NEW QUESTION # 45
You have an Azure Databricks workspace.
You need to ingest streaming data from Azure Event Hubs by using Apache Spark Structured Streaming The solution must authenticate to Event Hubs and read the event payload.
How should you complete the PySpark code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.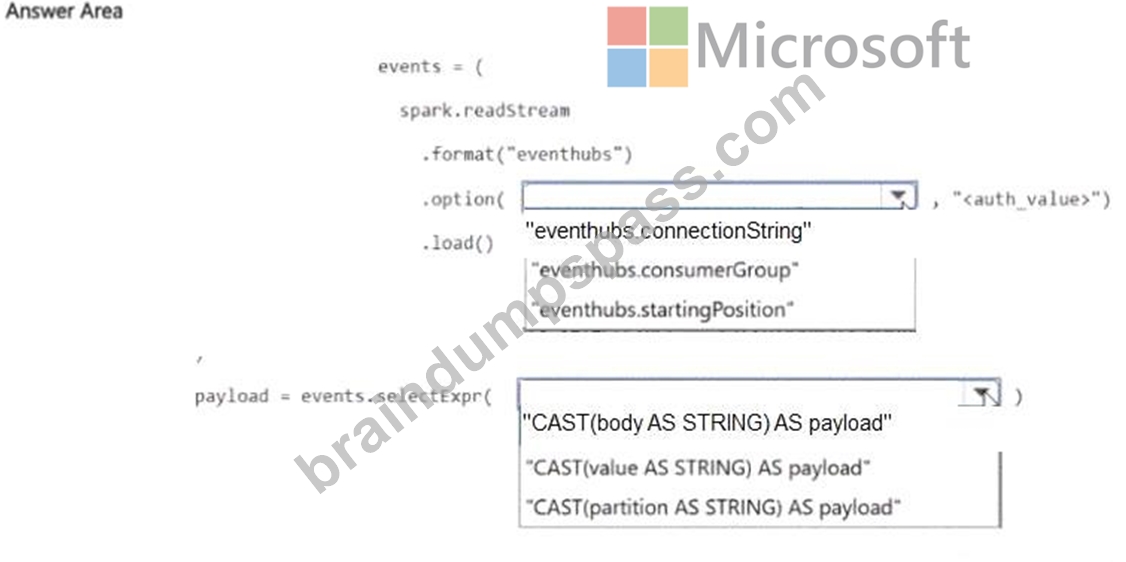
Answer:
Explanation: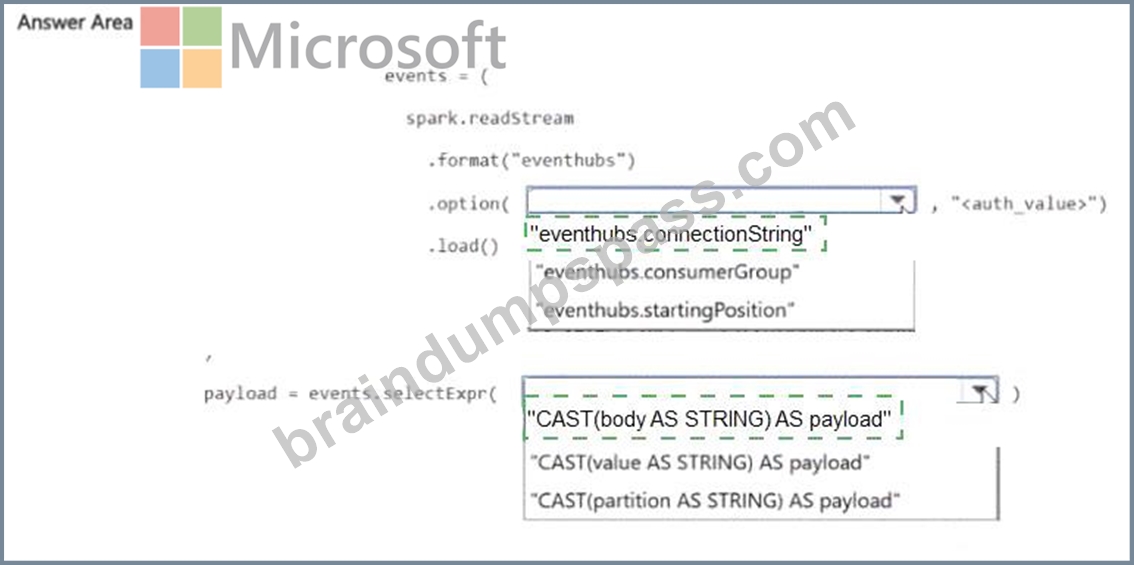
Explanation:
Reading from Azure Event Hubs in Spark Structured Streaming requires three things:
An EventHubsConf object built with the Event Hubs connection string (eventhubs.connectionString). This object is then converted to a map with .toMap before being passed to Spark.
spark.readStream.format( ' eventhubs ' ).options(**ehConf).load() to create the streaming DataFrame. The ' eventhubs ' format is provided by the azure-eventhubs-spark connector library.
A cast( ' string ' ) on the body column to decode the binary payload. Event Hubs delivers messages with the raw event bytes in a column called body - without the cast, you get binary data rather than the readable JSON or text payload.
This is the standard, documented integration pattern for connecting Azure Databricks to Event Hubs with Structured Streaming, providing the checkpoint-based exactly-once semantics required by the Contoso telemetry pipeline.
Reference: https://learn.microsoft.com/en-us/azure/databricks/connect/storage/events/eventhubs
NEW QUESTION # 46
......
Passing an Implementing Data Engineering Solutions Using Azure Databricks exam on the first attempt can be stressful, but Microsoft DP-750 exam questions can help manage stress and allow you to perform at your best. We at BraindumpsPass give you the techniques and resources to make sure you get the most out of your exam study. We provide preparation material for the Implementing Data Engineering Solutions Using Azure Databricks exam that will guide you when you sit to study for it. DP-750 updated questions give you enough confidence to sit for the Microsoft exam.
Free DP-750 Practice Exams: https://www.braindumpspass.com/Microsoft/DP-750-practice-exam-dumps.html