2026 Die neuesten ZertPruefung SPS-C01 PDF-Versionen Prüfungsfragen und SPS-C01 Fragen und Antworten sind kostenlos verfügbar: https://drive.google.com/open?id=1_lW-00oE1Y_0L_UIKpOjL8zmXKPsbaOz
Nur kontinuierlich zu verbessern kann man immer an der führenden Stelle stehen. Und es ist auch unsere Firmenphilosophie. Deshalb prüfen wir regelmäßig nach, ob die Snowflake SPS-C01 Prüfung aktualisiert hat. Wenn sie aktualisiert hat, informieren wir unsere Kunden sofort darüber. Dadurch lassen Sie die neueste Informationen über Snowflake SPS-C01 Prüfung erfahren. Aller Kundendienst der Aktualisierung nach der Kauf der Snowflake SPS-C01 Software ist kostenlos innerhalb einem Jahr.
| Section | Objectives |
|---|---|
| Topic 1: Performance Optimization and Best Practices | - Efficient Snowpark execution
|
| Topic 2: Data Engineering with Snowpark | - Pipeline development
|
| Topic 3: Testing, Debugging, and Deployment | - Production readiness
|
| Topic 4: Snowpark Fundamentals | - Snowpark architecture and concepts
|
| Topic 5: User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
| Topic 6: DataFrame Operations and Data Processing | - Data transformation workflows
|
>> SPS-C01 Fragen Und Antworten <<
Unser ZertPruefung hat langjährige Schulungserfahrungen über IT-Zertifizierungsprüfungen. Die Schulungsunterlagen zur Snowflake SPS-C01 Prüfung von ZertPruefung sind zuverlässig. Unser Eliteteam aktualisiert ständig die neuesten Schulungsunterlagen zur Snowflake SPS-C01 Prüfung. Unsere Angestelleten haben sich sehr viel Mühe dafür geben, um Ihnen zu helfen, eine gute Note in der Prüfung zu bekommen. Es ist sicher, dass ZertPruefung Ihnen die realen und besten Schulungsunterlagen zur Snowflake SPS-C01 Prüfung bietet.
372. Frage
You are developing a Snowpark Python stored procedure for processing financial data'. The procedure uses the 'pandas' library for data manipulation and the 'scipy' library for statistical calculations. You want to optimize the execution of the stored procedure to leverage the available resources in your Snowflake environment. Which of the following strategies would be MOST effective in improving the performance of your stored procedure, considering the need to handle large datasets?
Antwort: E
Begründung:
Option C is the most effective strategy for improving performance with large datasets. Snowpark's vectorized UDFs allow you to leverage Snowflake's distributed processing capabilities to perform calculations in parallel, avoiding the overhead of transferring data to Pandas. Option B would bring the entire dataset into memory on a single node which defeats the purpose of Snowflakes distributed computing. Option A might help but wouldn't fundamentally address the distribution issue. Option D is a brute-force approach and might help, but vectorized UDFs are more efficient. Option E could work but it requires complicated coding of partitioning logic.
373. Frage
You're using Snowpark in Python and need to execute a complex SQL query. The query involves several joins and aggregations, and you want to optimize its performance. You are using "session.sql(query)' to execute the query. Which of the following strategies, applied before executing 'session.sql(query)' , would likely lead to the most significant performance improvement for a very large dataset?
Antwort: E
Begründung:
Option A provides the most significant improvement because Snowpark DataFrame operations allow Snowflake's query optimizer to leverage pushdown optimizations. When you express your logic as DataFrame operations, Snowpark translates these into SQL that is specifically tailored for Snowflake's engine. This gives Snowflake more control over the execution plan compared to simply passing in a pre-written SQL query via 'session.sql(queryy. DataFrame operations allow the query optimizer to push down operations such as filters and aggregations to the data source, significantly reducing the amount of data transferred and processed. Option B is incorrect because comments only improve readability, not performance. Option C, , can help if the DataFrame is used multiple times, but it doesn't address the initial optimization of the query itself. Option D could help, but converting to DataFrame operations provides more comprehensive optimization. Option E can assist, but often DataFrame creation and optimal query plan generation can be better using Option A.
374. Frage
You have a Snowflake table named 'raw events' with a VARIANT column named 'event data'. The 'event data' column contains JSON objects with a field 'timestamp' that is sometimes represented as a string and sometimes as a number (Unix epoch). You need to create a Snowpark DataFrame that extracts the 'timestamp' as a timestamp object, handling both string and numeric representations. Which of the following code snippets correctly accomplishes this, avoiding errors when encountering incompatible types?





Antwort: E
Begründung:
Option D correctly uses the 'is_number' function to check if the timestamp is numeric. If it is, it divides by 1000 (assuming milliseconds) and converts to a timestamp. If it's not numeric, it converts directly to a timestamp (assuming it is a string representation). Options A, B, C, and E will fail when encountering mixed data types because 'to_timestamp' expects either a number or a string, not both interchangeably. Casting numeric value as String then passing to 'to_timestamp' would raise issues, it needs to be divided.
375. Frage
You have a Snowpark DataFrame named and want to create a stored procedure that calculates the average purchase amount for each customer. The stored procedure should accept the DataFrame as input, perform the aggregation, and return a new DataFrame with the results. Which of the following code snippets BEST demonstrates how to correctly define and deploy this stored procedure?

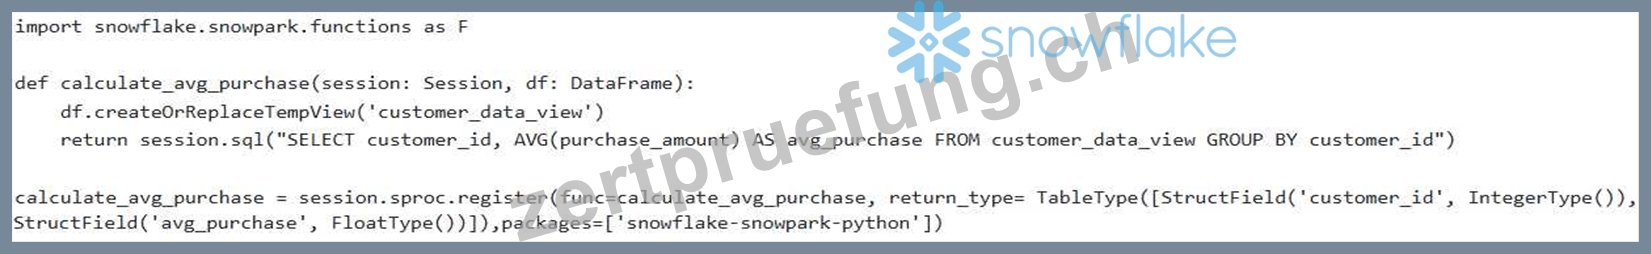


Antwort: E
Begründung:
Option E is the most correct. It correctly registers the stored procedure using 'session.sproc.register' with the correct return type annotation for a DataFrame (using TableType and StructFields) and explicitly declares the input type to be DataFrame using 'input_types' parameter in registration. Option A uses the '@sproc' decorator which is the older API (still valid, but less explicit). Option B uses session.sql which is not appropriate for creating DataFrame based stored procedures. Option C is not correct because the return type SeqType(FloatType()) expects a sequence of float types instead of a DataFrame structure. Option D writes the result to a table, which is not the defined requirement to return a DataFrame.
376. Frage
You are working with Snowpark and a DataFrame named 'orders df that contains order data, including a column named 'items' which is a VARIANT type and holds an array of JSON objects, where each object represents an item in the order. You need to explode this array into separate rows, extracting the 'item_id' and 'quantity' for each item. Which of the following Snowpark snippets correctly performs this transformation AND handles potential NULL or empty arrays in the 'items' column?





Antwort: B
Begründung:
Option E is the most robust. It explicitly handles NULL or empty arrays in the 'items' column by replacing them with an empty array before exploding. This prevents errors during the explode operation. The other options will fail if the array is NULL because you cannot explode a NULL array. Additionally the items column need to be dropped after explode, so it won't be there in the last query. Column 'col' created by expload function must be used to extract the 'item_id' and 'quantity' values.
377. Frage
......
Wenn Sie die Fragen und Antworten zur Snowflake SPS-C01 Prüfung von ZertPruefung kaufen, können Sie ihre wichtige Vorbereitung im leben treffen und die Fragenkataloge von guter Qualität bekommen. Kaufen Sie unsere Produkte heute, dann öffnen Sie sich eine Tür, um eine bessere Zukunft zu haben. Sie können auch mit weniger Mühe den großen Erfolg erzielen.
SPS-C01 Tests: https://www.zertpruefung.ch/SPS-C01_exam.html
Laden Sie die neuesten ZertPruefung SPS-C01 PDF-Versionen von Prüfungsfragen kostenlos von Google Drive herunter: https://drive.google.com/open?id=1_lW-00oE1Y_0L_UIKpOjL8zmXKPsbaOz