Microsoft AI-500 덤프의 PDF 버전과 Software 버전의 내용은 동일합니다. PDF버전은 프린트 가능한 버전으로서 단독구매하셔도 됩니다. Software 버전은 테스트용으로 PDF 버전 공부를 마친후 시험전에 실력테스트 가능합니다. Software 버전은 PDF버전의 보조용이기에 단독 판매하지 않습니다. 소프트웨어버전까지 필요하신 분은 PDF버전을 구입하실때 공동구매하셔야 합니다.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Architect multi-agent solutions | 15-20% | - Specify technology components for multi-agent solutions
|
| Topic 2: Develop multi-agent solutions in Azure | 30-35% | - Design and implement advanced prompt engineering strategies
|
| Topic 3: Secure, govern, and deploy multi-agent solutions | 20-25% | - Design and implement guardrails
|
| Topic 4: Evaluate, optimize, and monitor multi-agent solutions | 20-25% | - Implement observability and monitoring
|
Itcertkr의 Microsoft인증 AI-500덤프를 구매하시고 공부하시면 밝은 미래를 예약한것과 같습니다. Itcertkr의 Microsoft인증 AI-500덤프는 고객님이 시험에서 통과하여 중요한 IT인증자격증을 취득하게끔 도와드립니다. IT인증자격증은 국제적으로 인정받기에 취직이나 승진 혹은 이직에 힘을 가해드립니다. 학원공부나 다른 시험자료가 필요없이Itcertkr의 Microsoft인증 AI-500덤프만 공부하시면Microsoft인증 AI-500시험을 패스하여 자격증을 취득할수 있습니다.
질문 # 12
You have a Microsoft Foundry multi-agent solution that includes a orchestrator and agents named Agent1 and Agent2. The solution has the following characteristics:
* The orchestrator routes tasks to both agents.
* The agents invoice Model Context Protocol (MCP)-hosted tools.
* Agent? sends model-generated JSON parameters directly to tool endpoints.
* The agents use a shared managed identity that has contributor access to the resource group that contains the tool-backed Azure resources.
You need to implement a guardrail strategy for tool calls. The solution must meet the following requirements:
* Prevent invalid or out-of-range tool parameters from reaching the tool endpoints.
* Scope each agent ' s permissions to its assigned tools
* Limit Agent? to refund-processing tools only.
* Log tool invocations for audit purposes.
What should you do?
정답:C
설명:
The solution needs deterministic validation before model-generated tool arguments reach MCP endpoints, per- agent authorization boundaries, tool scoping, and audit logging. Validating typed payload schemas at the tool boundary prevents malformed or out-of-range arguments before execution, which is stronger than validating outputs after a tool has already run. Per-agent managed identities and scoped RBAC roles reduce lateral movement and contain the impact of a compromised agent. A per-agent tool-access policy also ensures the refund-focused agent cannot invoke unrelated tools. Finally, Azure Monitor/trace logging provides an auditable record of tool invocations. A2A capability cards describe remote-agent capabilities rather than validate tool arguments. System instructions are not an authorization boundary, and shared Contributor access leaves an excessive blast radius. Option D is therefore the only answer that satisfies all four requirements at enforceable platform boundaries. From a security and governance perspective, the control should be enforced at the narrowest platform boundary that can deterministically block or constrain the action. Relying only on prompt text is weaker because the model can still be induced to behave unexpectedly.
Official Microsoft reference: AI-500 Study Guide - tool scopes, permission boundaries, and auditing
질문 # 13
You have a Microsoft Foundry agent that completes benefits enrollment during a single user conversation The agent collects the required enrollment fields during 15 turns. Users can correct earlier values before final submission. The current implementation sends the complete transcript with every model request.
You need to change the context accumulation strategy for the active enrollment. The solution must meet the following requirements:
* Preserve the latest value for each required enrollment field until submission.
* Bound the maximum number of tokens sent with each model request
* Preserve user corrections until submission.
* Prevent durable cross-session memory.
What should you do?
정답:A
설명:
The application must preserve the latest authoritative value of each enrollment field even when the user corrects an earlier value, while also placing a firm bound on prompt size. A session-scoped enrollment-state snapshot provides deterministic structured state: each correction overwrites the previous field value. A recent- turn sliding window then preserves enough conversational context for natural interaction without resending the full 15-turn transcript. Response chaining with a fixed number of prior turns can lose an important field once it falls outside the retained history. Summarization can omit or distort corrected values, and automatic truncation likewise offers no guarantee that the latest value of every required field survives. Because the state is scoped only to the active enrollment and is not written to long-term memory, the design also avoids durable cross-session memory. Therefore A is correct. At implementation time, the same rule should be expressed through the framework or service configuration rather than left only as a natural-language convention. That makes the behavior repeatable across runs, easier to test, and less sensitive to model variability.
Official Microsoft reference: Microsoft Agent Framework - workflow state and context management
질문 # 14
You need to define a strategy to meet the business requirements for emergency room visits.
Which workflow node should you add to the Lead Orchestrator workflow?
정답:A
설명:
The business requirement says that a physician must approve any triage assessment that recommends an emergency room visit. The workflow must therefore pause and collect a human response before continuing.
Ask a question is the option that introduces that interactive human-in-the-loop step. Deliver a message only informs someone; it does not capture a decision. Agent invokes another AI component, which would not satisfy the explicit requirement for a physician ' s approval. Go to changes the workflow path but likewise does not obtain human authorization. Microsoft Agent Framework documents human-in-the-loop request
/response patterns for cases where execution must wait for approval or additional human input. For a medical escalation decision, the control must be deterministic and auditable rather than encoded as a prompt suggestion. Consequently, Ask a question is the workflow node that best enforces the business requirement.
At implementation time, the same rule should be expressed through the framework or service configuration rather than left only as a natural-language convention. That makes the behavior repeatable across runs, easier to test, and less sensitive to model variability.
Official Microsoft reference: Microsoft Agent Framework - Human-in-the-loop workflows
질문 # 15
You have a LangGraph workflow in Microsoft Foundry that is compiled as app by using a checkpointer. Each request includes a value named ticket_id.
You need to instrument the workflow so that each streamed run sends OpenTelemetry traces to Observability in Foundry. The solution must meet the following requirements:
* Correlate graph steps and tool calls for each request by the supplied ticket__id.
* Use the Azure Al OpenTelemetry tracer with the LangGraph invocation.
How should you complete the code? To answer, select the appropriate options in the answer area NOTE: Each correct selection is worth one point.
정답:
설명: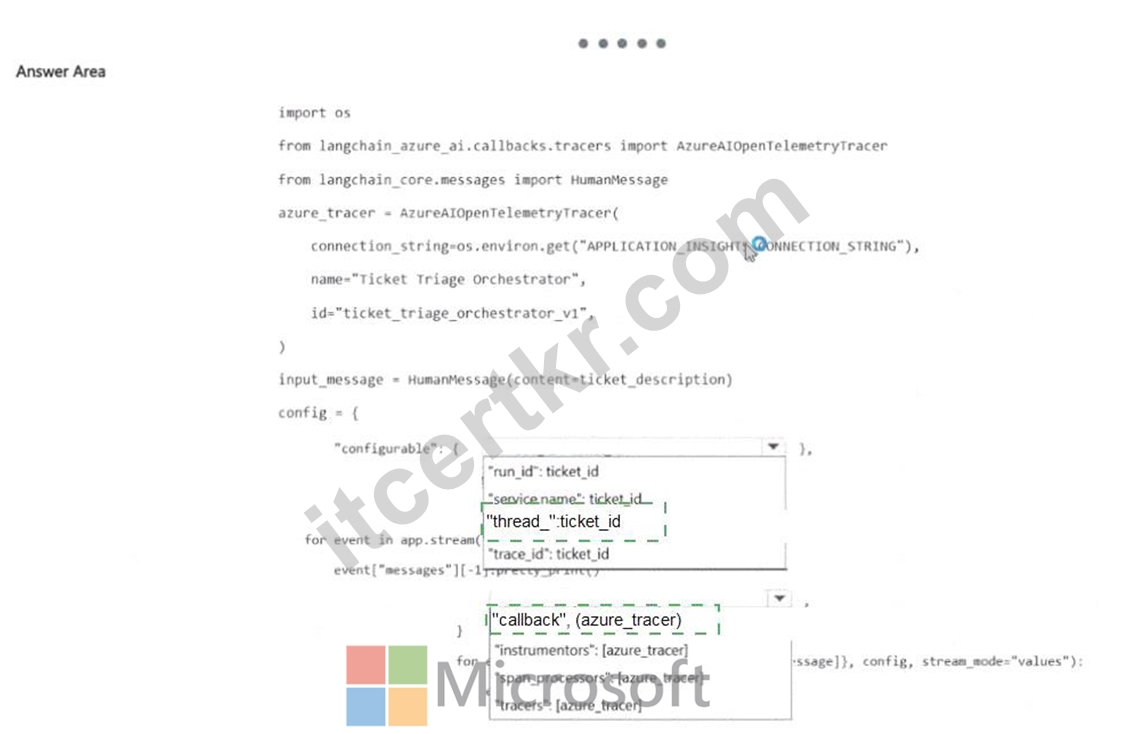
Explanation:
` " thread_id " : ticket_id` and ` " callbacks " : [azure_tracer]`.
LangGraph checkpointers use a stable `thread_id` under the configurable invocation context to associate execution and persisted state with the same logical request or conversation. Setting that value to the supplied
`ticket_id` allows graph steps and tool calls to be correlated to the ticket across a streamed run. Microsoft Foundry ' s LangGraph integration also uses `AzureAIOpenTelemetryTracer` through LangChain/LangGraph callbacks. Adding the tracer in the `callbacks` list causes agent, model, and tool spans to be emitted through OpenTelemetry and become visible in Foundry/Application Insights. A random run ID would not provide the stable checkpointer identity needed for state continuity, and fields such as `span_processors` are configured at a different instrumentation layer. Therefore the two code completions shown in the answer are correct. A robust evaluation program separates process metrics from final-response metrics. The selected answer measures the layer where the stated failure actually occurs, which is essential for deciding whether to change retrieval, orchestration, prompt behavior, or the final generator.
Official Microsoft reference: Microsoft Foundry - develop LangChain/LangGraph agents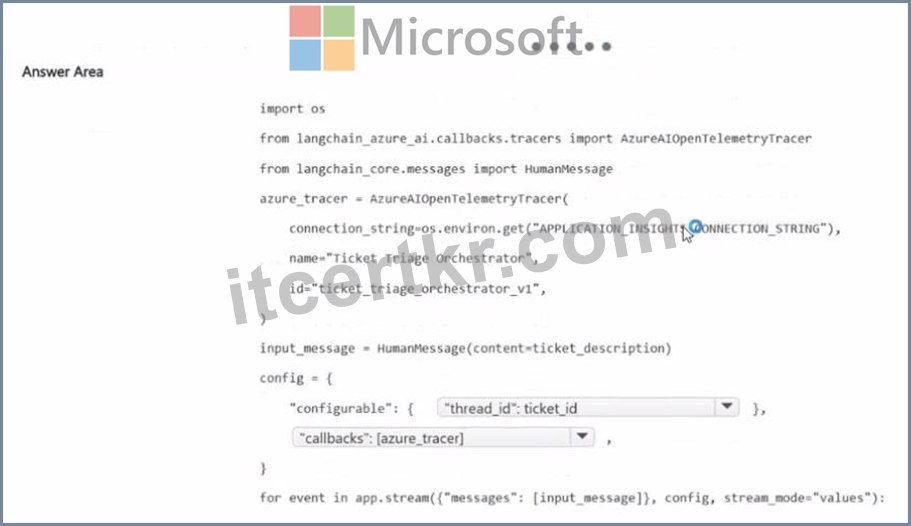
질문 # 16
You have a Microsoft Foundry project that contains a multi-agent customer support solution. The solution includes a final response agent.
You need to provide reviewers with the ability to assess agent responses in the preview web app and record a completion score for each agent response. The solution must follow the principle of least privilege.
Which roles should you assign to the reviewers?
정답:A
설명:
Microsoft ' s human-evaluation guidance for the Foundry preview web app requires reviewers to have Foundry User permissions on the project plus Reader access on the Foundry account/resource. That combination gives the reviewer enough project-level access to open the agent experience and record evaluation feedback while avoiding project-management or account-management privileges. Application Insights Reader alone only grants telemetry visibility and does not provide the Foundry interaction permissions needed to score responses. Foundry User alone does not satisfy the documented account-level visibility requirement for this preview experience. Foundry Project Manager would be broader than necessary and violate the least-privilege objective. Therefore C is the documented reviewer role combination. The same configuration should be paired with auditable identity, trace, and evaluation data so reviewers can prove which principal acted, which policy was applied, and why a request was allowed or blocked. That is particularly important for production multi-agent systems with external tools. Least privilege remains the governing principle: grant only the identity, data, tool, or deployment access required for the specific operation. The selected answer preserves that boundary while still allowing the workflow to satisfy its functional requirement.
Official Microsoft reference: Microsoft Foundry - Human evaluation
질문 # 17
......
Itcertkr에서 판매하고 있는 Microsoft AI-500인증시험자료는 시중에서 가장 최신버전으로서 시험적중율이 100%에 가깝습니다. Microsoft AI-500덤프자료를 항상 최신버전으로 보장해드리기 위해Microsoft AI-500시험문제가 변경되면 덤프자료를 업데이트하도록 최선을 다하고 있습니다. Itcertkr는 여러분이 자격증을 취득하는 길에서 없어서는 안되는 동반자로 되어드릴것을 약속해드립니다.
AI-500인증덤프문제: https://www.itcertkr.com/AI-500_exam.html