2026年It-Passportsの最新DP-600 PDFダンプおよびDP-600試験エンジンの無料共有:https://drive.google.com/open?id=1r3z650ja8I0ALkIm3KeXRUXnFFyDlHeg
多くの候補者は実際の戦闘経験がないため、資格試験は初めて参加するため、テストMicrosoft認定を取得する方法については、一連の方法を所有していませんでした。値がありません。 DP-600試験の練習では、受験者の興味や趣味に応じて、コンテンツと形式を高効率かつ正確に配置できるというメリットを享受することができます。忠実な顧客からの多くの感謝のフィードバックは、DP-600準備の質問を提供するこの分野で最も人気のあるベンダーであることを証明しました。
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Implementing Analytics Solutions Using Microsoft Fabric |
| Exam Number: | DP-600 |
| Exam Format: | Case studies, Drag-and-drop, Multiple-choice |
| Passing Score: | 700/1000 |
| Certificate Validity Period: | 1 year |
| Real Exam Qty: | 40-60 |
| Exam Duration: | 120 minutes |
| Related Certifications: | Microsoft Certified: Fabric Analytics Engineer Associate |
| Exam Price: | $165 USD |
| Available Languages: | Korean, English, Chinese (Simplified), Japanese |
| Sample Questions: | Microsoft DP-600 Sample Questions |
| Exam Way: | Online proctored or in-person testing center |
| Pre Condition: | Candidates should have foundational knowledge of data concepts, experience with Microsoft Fabric, and proficiency in data transformation and modeling. Familiarity with Power BI is recommended but not required. |
| Official Syllabus URL: | https://learn.microsoft.com/en-us/certifications/exams/dp-600 |
時間が経つとともに、我々はインタネット時代に生活します。この時代にはIT資格認証を取得するは重要になります。それでは、DP-600試験に参加しよう人々は弊社It-PassportsのDP-600問題集を選らんで勉強して、一発合格して、MicrosoftIT資格証明書を受け取れます。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
質問 # 21
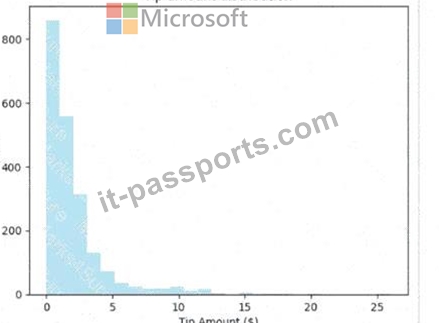
You have a Fabric notebook that has the Python code and output shown in the following exhibit.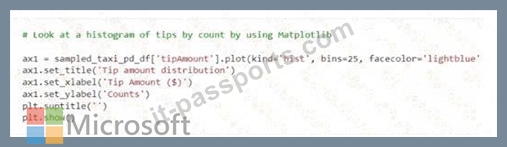
Which type of analytics are you performing?
正解:B
解説:
The Python code and output shown in the exhibit display a histogram, which is a representation of the distribution of data. This kind of analysis is descriptive analytics, which is used to describe or summarize the features of a dataset. Descriptive analytics answers the question of "what has happened" by providing insight into past data through tools such as mean, median, mode, standard deviation, and graphical representations like histograms.
References: Descriptive analytics and the use of histograms as a way to visualize data distribution are basic concepts in data analysis, often covered in introductory analytics and Python programming resources.
質問 # 22
You have a Microsoft Power Bl report named Report1 that uses a Fabric semantic model.
Users discover that Report1 renders slowly.
You open Performance analyzer and identify that a visual named Orders By Date is the slowest to render. The duration breakdown for Orders By Date is shown in the following table.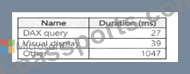
What will provide the greatest reduction in the rendering duration of Report1?
正解:D
解説:
Based on the duration breakdown provided, the major contributor to the rendering duration is categorized as
"Other," which is significantly higher than DAX Query and Visual display times. This suggests that the issue is less likely with the DAX calculation or visual rendering times and more likely related to model performance or the complexity of the visual. However, of the options provided, optimizing the DAX query can be a crucial step, even if "Other" factors are dominant. Using DAX Studio, you can analyze and optimize the DAX queries that power your visuals for performance improvements. Here's how you might proceed:
* Open DAX Studio and connect it to your Power BI report.
* Capture the DAX query generated by the Orders By Date visual.
* Use the Performance Analyzer feature within DAX Studio to analyze the query.
* Look for inefficiencies or long-running operations.
* Optimize the DAX query by simplifying measures, removing unnecessary calculations, or improving iterator functions.
* Test the optimized query to ensure it reduces the overall duration.
References: The use of DAX Studio for query optimization is a common best practice for improving Power BI report performance as outlined in the Power BI documentation.
質問 # 23
You need to implement the date dimension in the data store. The solution must meet the technical requirements.
What are two ways to achieve the goal? Each correct answer presents a complete solution.
NOTE: Each correct selection is worth one point.
正解:B、C
解説:
Both a dataflow (A) and a Stored procedure activity in a pipeline (B) are capable of creating and populating a date dimension table. A dataflow can perform the transformation needed to create the date dimension, and it aligns with the preference for using low-code tools for data ingestion when possible. A Stored procedure could be written to generate the necessary date dimension data and executed within a pipeline, which also adheres to the technical requirements for the PoC.
Topic 1, Litware. Inc. Case Study
Overview
Litware. Inc. is a manufacturing company that has offices throughout North America. The analytics team at Litware contains data engineers, analytics engineers, data analysts, and data scientists.
Existing Environment
litware has been using a Microsoft Power Bl tenant for three years. Litware has NOT enabled any Fabric capacities and features.
Fabric Environment
Litware has data that must be analyzed as shown in the following table.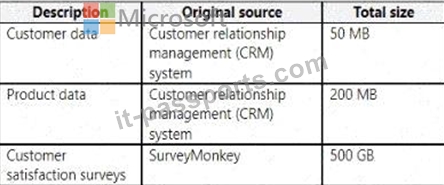
The Product data contains a single table and the following columns.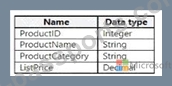
The customer satisfaction data contains the following tables:
* Survey
* Question
* Response
For each survey submitted, the following occurs:
* One row is added to the Survey table.
* One row is added to the Response table for each question in the survey.
The Question table contains the text of each survey question. The third question in each survey response is an overall satisfaction score. Customers can submit a survey after each purchase.
User Problems
The analytics team has large volumes of data, some of which is semi-structured. The team wants to use Fabric to create a new data store.
Product data is often classified into three pricing groups: high, medium, and low. This logic is implemented in several databases and semantic models, but the logic does NOT always match across implementations.
Planned Changes
Litware plans to enable Fabric features in the existing tenant. The analytics team will create a new data store as a proof of concept (PoC). The remaining Litware users will only get access to the Fabric features once the PoC is complete. The PoC will be completed by using a Fabric trial capacity.
The following three workspaces will be created:
* AnalyticsPOC: Will contain the data store, semantic models, reports, pipelines, dataflows, and notebooks used to populate the data store
* DataEngPOC: Will contain all the pipelines, dataflows, and notebooks used to populate Onelake
* DataSciPOC: Will contain all the notebooks and reports created by the data scientists The following will be created in the AnalyticsPOC workspace:
* A data store (type to be decided)
* A custom semantic model
* A default semantic model
* Interactive reports
The data engineers will create data pipelines to load data to OneLake either hourly or daily depending on the data source. The analytics engineers will create processes to ingest transform, and load the data to the data store in the AnalyticsPOC workspace daily. Whenever possible, the data engineers will use low-code tools for data ingestion. The choice of which data cleansing and transformation tools to use will be at the data engineers ' discretion.
All the semantic models and reports in the Analytics POC workspace will use the data store as the sole data source.
Technical Requirements
The data store must support the following:
* Read access by using T-SQL or Python
* Semi-structured and unstructured data
* Row-level security (RLS) for users executing T-SQL queries
Files loaded by the data engineers to OneLake will be stored in the Parquet format and will meet Delta Lake specifications.
Data will be loaded without transformation in one area of the AnalyticsPOC data store. The data will then be cleansed, merged, and transformed into a dimensional model.
The data load process must ensure that the raw and cleansed data is updated completely before populating the dimensional model.
The dimensional model must contain a date dimension. There is no existing data source for the date dimension. The Litware fiscal year matches the calendar year. The date dimension must always contain dates from 2010 through the end of the current year.
The product pricing group logic must be maintained by the analytics engineers in a single location. The pricing group data must be made available in the data store for T-SQL queries and in the default semantic model. The following logic must be used:
* List prices that are less than or equal to 50 are in the low pricing group.
* List prices that are greater than 50 and less than or equal to 1,000 are in the medium pricing group.
* List pnces that are greater than 1,000 are in the high pricing group.
Security Requirements
Only Fabric administrators and the analytics team must be able to see the Fabric items created as part of the PoC. Litware identifies the following security requirements for the Fabric items in the AnalyticsPOC workspace:
* Fabric administrators will be the workspace administrators.
* The data engineers must be able to read from and write to the data store. No access must be granted to datasets or reports.
* The analytics engineers must be able to read from, write to, and create schemas in the data store. They also must be able to create and share semantic models with the data analysts and view and modify all reports in the workspace.
* The data scientists must be able to read from the data store, but not write to it. They will access the data by using a Spark notebook.
* The data analysts must have read access to only the dimensional model objects in the data store. They also must have access to create Power Bl reports by using the semantic models created by the analytics engineers.
* The date dimension must be available to all users of the data store.
* The principle of least privilege must be followed.
Both the default and custom semantic models must include only tables or views from the dimensional model in the data store. Litware already has the following Microsoft Entra security groups:
* FabricAdmins: Fabric administrators
* AnalyticsTeam: All the members of the analytics team
* DataAnalysts: The data analysts on the analytics team
* DataScientists: The data scientists on the analytics team
* Data Engineers: The data engineers on the analytics team
* Analytics Engineers: The analytics engineers on the analytics team
Report Requirements
The data analysis must create a customer satisfaction report that meets the following requirements:
* Enables a user to select a product to filter customer survey responses to only those who have purchased that product
* Displays the average overall satisfaction score of all the surveys submitted during the last 12 months up to a selected date
* Shows data as soon as the data is updated in the data store
* Ensures that the report and the semantic model only contain data from the current and previous year
* Ensures that the report respects any table-level security specified in the source data store
* Minimizes the execution time of report queries
質問 # 24
You have a Fabric workspace named Workspace1 that contains a lakehouse named Lakehouse1 and a user named User1. You need to ensure that User1 can read all the data in Lakehouse1. The solution must follow the principle of least privilege. Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
正解:C、D
質問 # 25
You need to design a semantic model for the customer satisfaction report.
Which data source authentication method and mode should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.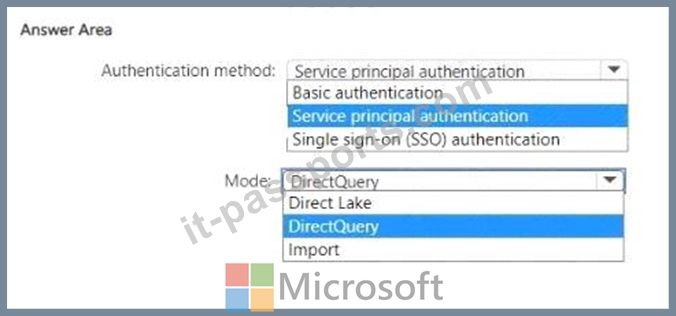
正解:
解説: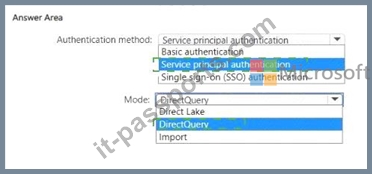
Explanation:
For the semantic model design required for the customer satisfaction report, the choices for data source authentication method and mode should be made based on security and performance considerations as per the case study provided.
Authentication method: The data should be accessed securely, and given that row-level security (RLS) is required for users executing T-SQL queries, you should use an authentication method that supports RLS.
Service principal authentication is suitable for automated and secure access to the data, especially when the access needs to be controlled programmatically and is not tied to a specific user's credentials.
Mode: The report needs to show data as soon as it is updated in the data store, and it should only contain data from the current and previous year. DirectQuery mode allows for real-time reporting without importing data into the model, thus meeting the need for up-to-date data. It also allows for RLS to be implemented and enforced at the data source level, providing the necessary security measures.
Based on these considerations, the selections should be:
* Authentication method: Service principal authentication
* Mode: DirectQuery
質問 # 26
......
DP-600模擬モード: https://www.it-passports.com/DP-600.html
P.S. It-PassportsがGoogle Driveで共有している無料かつ新しいDP-600ダンプ:https://drive.google.com/open?id=1r3z650ja8I0ALkIm3KeXRUXnFFyDlHeg