Newest Certified-Data-Engineer-Professional Pdf Torrent, Ensure to pass the Certified-Data-Engineer-Professional Exam

As you see, all of the three versions are helpful for you to get the Certified-Data-Engineer-Professional certification: the PDF, Software and APP online. So there is another choice for you to purchase the comprehensive version which contains all the three formats, it is the Value Pack. Besides, the price for the Value Pack is quite favorable. And no matter which format of Certified-Data-Engineer-Professional study engine you choose, we will give you 24/7 online service and one year's free updates on the Certified-Data-Engineer-Professional practice questions.
| Section | Objectives |
|---|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
- 2. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
|
| Data Governance | - Govern enterprise data
- 1. Create and add descriptions and metadata to enterprise data to improve discoverability
- 2. Demonstrate understanding of the Unity Catalog permission inheritance model
|
| Data Sharing and Federation | - Share and federate data
- 1. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 2. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 3. Configure Lakehouse Federation with appropriate governance across supported source systems
|
| Ensuring Data Security and Compliance | - Ensuring Compliance
- 1. Implement compliant batch and streaming pipelines that detect and mask PII
- 2. Develop data purging solutions that comply with data retention policies
- Applying Data Security Mechanisms
- 1. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 2. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 3. Use row filters and column masks to protect sensitive table data
|
| Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
- 2. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
|
| Monitoring and Alerting | - Monitoring
- 1. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 2. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 3. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 4. Use Query Profile and Spark UI to monitor workloads
- Alerting
- 1. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- 2. Use SQL Alerts to monitor data quality
|
| Data Modeling | - Design and optimize data models
- 1. Design and implement scalable data models using Delta Lake to manage large datasets
- 2. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 3. Simplify data layout decisions and optimize query performance using liquid clustering
- 4. Design dimensional models for analytical workloads with efficient querying and aggregation
|
| Debugging and Deploying | - Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- Debugging and Troubleshooting
- 1. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 2. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 3. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
|
| Cost & Performance Optimization | - Optimize cost and performance
- 1. Apply Change Data Feed to address streaming table limitations and improve latency
- 2. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 3. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 4. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 5. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
|
| Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 2. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 3. Develop User-Defined Functions using Pandas/Python UDF
- Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 2. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 3. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 4. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 5. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 6. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 7. Create pipeline components using control flow operators such as if/else and foreach
- 8. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
|
>> Certified-Data-Engineer-Professional Pdf Torrent <<
Certified-Data-Engineer-Professional Training Kit | Certified-Data-Engineer-Professional Exam Flashcards
First and foremost, in order to cater to the different needs of people from different countries in the international market, we have prepared three kinds of versions of our Certified-Data-Engineer-Professional learning questions in this website. Second, we can assure you that you will get the latest version of our Certified-Data-Engineer-Professional Training Materials for free from our company in the whole year after payment on Certified-Data-Engineer-Professional practice materials. Last but not least, we will provide the most considerate after sale service on our Certified-Data-Engineer-Professional study guide for our customers in twenty four hours a day seven days a week.
Databricks Certified Data Engineer Professional Sample Questions (Q189-Q194):
NEW QUESTION # 189
A data engineer is analyzing a large, partitioned retail dataset in Databricks, where each row represents a sale made by a salesperson. The dataset contains millions of records with the following schema:
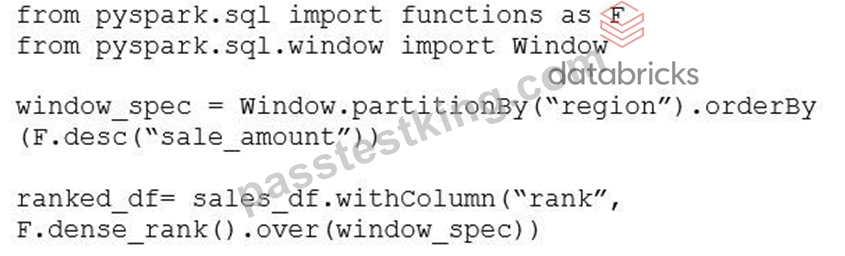
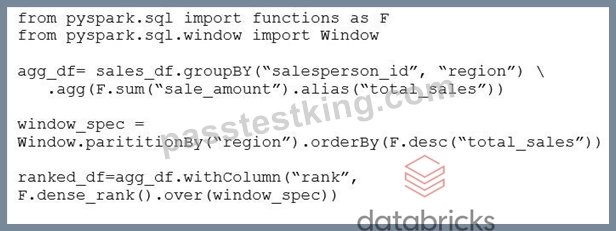
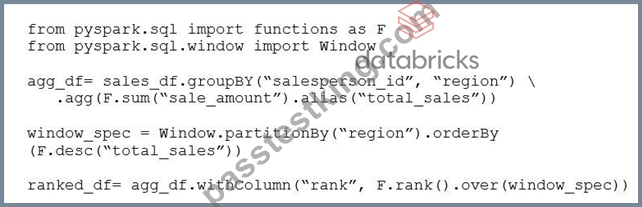
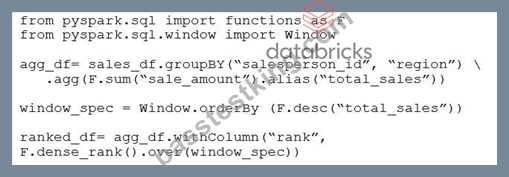
sales_df: [salesperson_id: string, region: string, sale_amount: double, sale_date: date] The data engineer needs to generate a DataFrame that ranks salespeople within each region based on their total cumulative sales, with the highest seller ranked as 1. If multiple salespeople have the same total sales, they should share the same rank.
The data engineer wants to implement this logic using a PySpark window function and the dense_rank () function.
Which code snippet will perform this ranking?
Answer: B
Explanation:
This approach first aggregates sales by salesperson and region to compute total cumulative sales. It then applies a window function partitioned by region and ordered by total sales in descending order, using dense_rank to assign ranks so that salespeople with equal totals share the same rank and the highest total receives rank 1.
NEW QUESTION # 190
A data engineer is building a customer data pipeline in Lakeflow Spark Declarative Pipelines. The source is a cloud-based event stream with limited retention containing inserts, updates, and deletes for customer records. These changes are being applied using the AUTO CDC INTO syntax to maintain an SCD Type 1 table as the target table, customer_dim. How should the data engineer build a downstream job that streams from the customer_dim table to only act on updates and delete events, processing data incrementally?
- A. Streaming from customer_dim table would only be possible in the case of SCD 2 retention.
- B. Read change data feed from customer_dim table and apply filters to incrementally act on the change events.
- C. When stored as SCD 1, the target of AUTO CDC INTO includes updates and deletes. Streaming from customer_dim can fail due to these operations. Instead, build another stream from the original source.
- D. Use ignoreChanges flag while streaming from customer_dim to avoid breaking the pipeline during updates and deletes.
Answer: B
Explanation:
Reading the change data feed from the customer_dim table enables downstream processing to react specifically to update and delete events while operating incrementally. Change data feed exposes row-level change types and versions, making it the correct mechanism for streaming only the relevant changes from an SCD Type 1 table maintained with AUTO CDC INTO.
NEW QUESTION # 191
Two data engineers are working on the same Databricks notebook in separate branches. Both have edited the same section of code. When one tries to merge the other's branch into their own using the Databricks Git folders UI, a merge conflict occurs on that notebook file. The UI highlights the conflict and presents options for resolution. How should the data engineers resolve this merge conflict using Databricks Git folders?
- A. Use the Git folders UI to manually edit the notebook file, selecting the desired lines from both versions and removing the conflict markers, then mark the conflict as resolved.
- B. Delete the conflicted notebook file via the Databricks workspace UI, commit the deletion, and recreate the notebook from scratch in a new commit to bypass the conflict entirely.
- C. Use the Git CLI in the cluster's web terminal to force-push the conflicted merge (git push -force), overriding the remote branch with the local version and discarding changes.
- D. Abort the merge, discard all local changes, and try the merge operation again without reviewing the conflicting code.
Answer: A
Explanation:
In the Databricks Git folders integration, when merge conflicts arise in notebooks, the UI provides a visual diff editor that highlights conflicting code segments. Users can manually choose which changes to keep from each branch, edit directly in the notebook UI, and remove conflict markers.
After resolving, the engineer must mark the conflict as resolved, save, and commit the final version.
This process ensures that both contributors' valid code segments are merged correctly and version history is maintained.
Forcing a push (C) or deleting notebooks (B) introduces data loss or versioning issues. Aborting without review (A) violates collaborative best practices. Therefore, D is the only correct and Databricks-approved way to resolve notebook merge conflicts.
NEW QUESTION # 192
A junior data engineer is working to implement logic for a Lakehouse table named silver_device_recordings. The source data contains 100 unique fields in a highly nested JSON structure.
The silver_device_recordings table will be used downstream to power several production monitoring dashboards and a production model. At present, 45 of the 100 fields are being used in at least one of these applications.
The data engineer is trying to determine the best approach for dealing with schema declaration given the highly-nested structure of the data and the numerous fields.
Which of the following accurately presents information about Delta Lake and Databricks that may impact their decision-making process?
- A. Because Databricks will infer schema using types that allow all observed data to be processed, setting types manually provides greater assurance of data quality enforcement.
- B. Because Delta Lake uses Parquet for data storage, data types can be easily evolved by just modifying file footer information in place.
- C. Human labor in writing code is the largest cost associated with data engineering workloads; as such, automating table declaration logic should be a priority in all migration workloads.
- D. Schema inference and evolution on .Databricks ensure that inferred types will always accurately match the data types used by downstream systems.
- E. The Tungsten encoding used by Databricks is optimized for storing string data; newly-added native support for querying JSON strings means that string types are always most efficient.
Answer: A
Explanation:
This is the correct answer because it accurately presents information about Delta Lake and Databricks that may impact the decision-making process of a junior data engineer who is trying to determine the best approach for dealing with schema declaration given the highly-nested structure of the data and the numerous fields. Delta Lake and Databricks support schema inference and evolution, which means that they can automatically infer the schema of a table from the source data and allow adding new columns or changing column types without affecting existing queries or pipelines. However, schema inference and evolution may not always be desirable or reliable, especially when dealing with complex or nested data structures or when enforcing data quality and consistency across different systems. Therefore, setting types manually can provide greater assurance of data quality enforcement and avoid potential errors or conflicts due to incompatible or unexpected data types.
NEW QUESTION # 193
A member of the data engineering team has submitted a short notebook that they wish to schedule as part of a larger data pipeline. Assume that the commands provided below produce the logically correct results when run as presented.
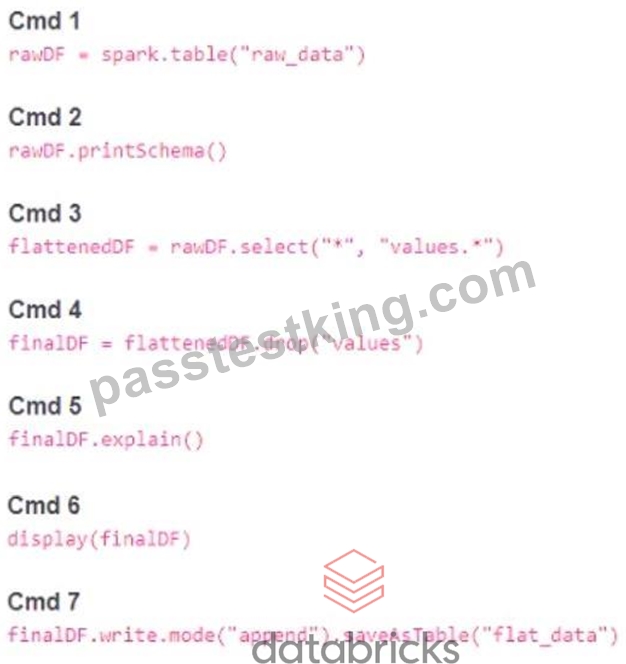
Which command should be removed from the notebook before scheduling it as a job?
- A. Cmd 6
- B. Cmd 4
- C. Cmd 3
- D. Cmd 5
- E. Cmd 2
Answer: A
Explanation:
When scheduling a Databricks notebook as a job, it's generally recommended to remove or modify commands that involve displaying output, such as using the display() function. Displaying data using display() is an interactive feature designed for exploration and visualization within the notebook interface and may not work well in a production job context.
The finalDF.explain() command, which provides the execution plan of the DataFrame transformations and actions, is often useful for debugging and optimizing queries. While it doesn't display interactive visualizations like display(), it can still be informative for understanding how Spark is executing the operations on your DataFrame.
NEW QUESTION # 194
......
With the furious competition of the society, our PassTestking still have a good reputation from candidates in IT exam certification, because we always develop our exam software in the examinees' stand. For instance, Certified-Data-Engineer-Professional exam software with good sales is developed by our professional technical team with deep analysis of a lot of Certified-Data-Engineer-Professional Exam Questions. Although we guarantee "No help, full refund", those who have purchased our products have pass the exam successfully, which shows the effectiveness and reliability of our Certified-Data-Engineer-Professional exam software.
Certified-Data-Engineer-Professional Training Kit: https://www.passtestking.com/Databricks/Certified-Data-Engineer-Professional-practice-exam-dumps.html
- Certified-Data-Engineer-Professional Downloadable PDF 🌈 Certified-Data-Engineer-Professional Excellect Pass Rate 🈺 Certified-Data-Engineer-Professional Excellect Pass Rate 🩲 Immediately open ➡ www.troytecdumps.com ️⬅️ and search for ⇛ Certified-Data-Engineer-Professional ⇚ to obtain a free download 📚Braindumps Certified-Data-Engineer-Professional Downloads
- Certified-Data-Engineer-Professional Downloadable PDF 🈺 Certified-Data-Engineer-Professional Latest Test Simulations 🟪 Exam Certified-Data-Engineer-Professional Prep 🧀 The page for free download of ➥ Certified-Data-Engineer-Professional 🡄 on [ www.pdfvce.com ] will open immediately 🗼Certified-Data-Engineer-Professional New Dumps Free
- Topping Certified-Data-Engineer-Professional Practice Quiz: Databricks Certified Data Engineer Professional Supply You the Most Veracious Exam Brain Dumps - www.prep4away.com 🔩 Search for “ Certified-Data-Engineer-Professional ” and obtain a free download on ☀ www.prep4away.com ️☀️ ☢Certified-Data-Engineer-Professional PDF Questions
- New Certified-Data-Engineer-Professional Exam Camp 🐠 Certified-Data-Engineer-Professional PDF Questions 🙄 Certified-Data-Engineer-Professional New Dumps Free 🟠 Open 《 www.pdfvce.com 》 and search for ➠ Certified-Data-Engineer-Professional 🠰 to download exam materials for free 💈Certified-Data-Engineer-Professional Dumps Download
- Pass Guaranteed 2026 Databricks Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Marvelous Pdf Torrent 👨 Immediately open ➡ www.exam4labs.com ️⬅️ and search for ⇛ Certified-Data-Engineer-Professional ⇚ to obtain a free download 🍎Certified-Data-Engineer-Professional PDF Questions
- Latest Upload Certified-Data-Engineer-Professional Pdf Torrent - Databricks Certified-Data-Engineer-Professional Training Kit: Databricks Certified Data Engineer Professional 🔯 Copy URL 「 www.pdfvce.com 」 open and search for ☀ Certified-Data-Engineer-Professional ️☀️ to download for free 🛵Certified-Data-Engineer-Professional Reliable Exam Tutorial
- Certified-Data-Engineer-Professional Excellect Pass Rate 👴 Exam Certified-Data-Engineer-Professional Prep 🦕 Certified-Data-Engineer-Professional New Dumps Free 😽 Search for 「 Certified-Data-Engineer-Professional 」 on ⇛ www.troytecdumps.com ⇚ immediately to obtain a free download 🏛Reliable Certified-Data-Engineer-Professional Test Blueprint
- Certified-Data-Engineer-Professional Reliable Exam Pattern 🏜 Certified-Data-Engineer-Professional New Dumps Free 🧩 Certified-Data-Engineer-Professional Downloadable PDF 😮 Easily obtain { Certified-Data-Engineer-Professional } for free download through ⏩ www.pdfvce.com ⏪ 🏜Certified-Data-Engineer-Professional Dumps Download
- Topping Certified-Data-Engineer-Professional Practice Quiz: Databricks Certified Data Engineer Professional Supply You the Most Veracious Exam Brain Dumps - www.examcollectionpass.com 🩺 Search for 《 Certified-Data-Engineer-Professional 》 and download it for free on 《 www.examcollectionpass.com 》 website 💢Braindumps Certified-Data-Engineer-Professional Downloads
- Certified-Data-Engineer-Professional Authorized Test Dumps 🔉 Certified-Data-Engineer-Professional Test King 💮 New Certified-Data-Engineer-Professional Exam Camp 🧏 Simply search for ⮆ Certified-Data-Engineer-Professional ⮄ for free download on ▷ www.pdfvce.com ◁ 🏁Certified-Data-Engineer-Professional New Dumps Free
- First-grade Certified-Data-Engineer-Professional Pdf Torrent - Passing Certified-Data-Engineer-Professional Exam is No More a Challenging Task 😉 Search for 《 Certified-Data-Engineer-Professional 》 and download it for free immediately on 《 www.practicevce.com 》 🎅Latest Certified-Data-Engineer-Professional Examprep
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, faithlife.com, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes