ちなみに、Xhs1991 AIF-C01の一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=19TBLBIYxNFl0twoYn14pRqXICHLTMBy-
現在、試験がシミュレーションテストを提供するような統合システムを持っていることはほとんどありません。 AIF-C01学習ツールについて学習した後、実際の試験を刺激することの重要性が徐々に認識されます。この機能により、AIF-C01練習システムがどのように動作するかを簡単に把握でき、AIF-C01試験に関する中核的な知識を得ることができます。さらに、実際の試験環境にいるときは、質問への回答の速度と品質を制御し、エクササイズの良い習慣を身に付けることができるため、AIF-C01試験に合格することができます。
| Section | Objectives |
|---|---|
| Fundamentals of Generative AI | - Foundation models and prompt engineering basics - Large language models (LLMs) concepts - AWS generative AI services overview (e.g., Amazon Bedrock) |
| Applications of Foundation Models | - AI-powered assistants and automation - Content generation and summarization - Use cases for generative AI in business |
| Fundamentals of Artificial Intelligence and Machine Learning | - Common ML workflows and lifecycle - Data fundamentals for AI/ML - Core AI and ML concepts |
| Responsible AI and Security | - Security, privacy, and governance in AI systems - AI ethics and responsible use - Bias, fairness, and explainability |
AmazonのAIF-C01の試験の資料やほかのトレーニング資料を提供しているサイトがたくさんありますが、AmazonのAIF-C01の認証試験の高品質の資料を提供しているユニークなサイトはXhs1991です。Xhs1991のガイダンスとヘルプを通して、初めにAmazonのAIF-C01「AWS Certified AI Practitioner」の認証を受けるあなたは、気楽に試験に合格すことができます。Xhs1991が提供した問題と解答は現代の活力がみなぎる情報技術専門家が豊富な知識と実践経験を活かして研究した成果で、あなたが将来IT分野でより高いレベルに達することに助けを差し上げます。
質問 # 151
A company wants to use a large language model (LLM) on Amazon Bedrock for sentiment analysis. The company wants to classify the sentiment of text passages as positive or negative.
Which prompt engineering strategy meets these requirements?
正解:A
質問 # 152
A publishing company built a Retrieval Augmented Generation (RAG) based solution to give its users the ability to interact with published content. New content is published daily. The company wants to provide a near real-time experience to users.
Which steps in the RAG pipeline should the company implement by using offline batch processing to meet these requirements? (Select TWO.)
正解:A、B
解説:
Comprehensive and Detailed Explanation From Exact Extract:
In a RAG (Retrieval Augmented Generation) architecture, there are steps that can be optimized using offline batch processing, particularly for operations that do not require real-time updates:
* A. Generation of content embeddings:When new content is published, it can be processed in batches to generate embeddings (vector representations) offline. These embeddings are then used at query time for similarity search. As new documents come in daily, batch processing is ideal for generating embeddings for all new content together.
"Content/document embeddings are typically generated offline, as this operation can be computationally expensive and does not need to happen in real-time." (Reference: AWS GenAI RAG Blog, Amazon Bedrock RAG Pattern)
* C. Creation of the search index:After generating the content embeddings, these are indexed in a vector database or search service. This indexing is also typically performed in batch as part of the offline pipeline.
"Building or updating the vector index is often performed as a batch operation, reflecting the latest state of the content repository." (Reference: AWS RAG Pattern Whitepaper) B, D, and E are real-time steps. Embeddings for user queries (B), retrieval of relevant content (D), and response generation (E) must be processed in real-time to provide an interactive experience.
References:
Retrieval Augmented Generation (RAG) on AWS
Amazon Bedrock RAG Documentation
質問 # 153
A company is using Amazon SageMaker to develop AI models.
Select the correct SageMaker feature or resource from the following list for each step in the AI model lifecycle workflow. Each SageMaker feature or resource should be selected one time or not at all. (Select TWO.) SageMaker Clarify SageMaker Model Registry SageMaker Serverless Inference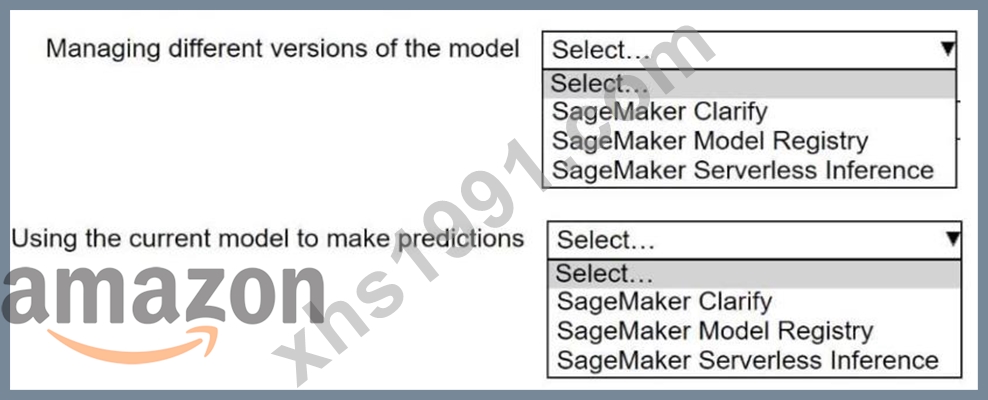
正解:
解説: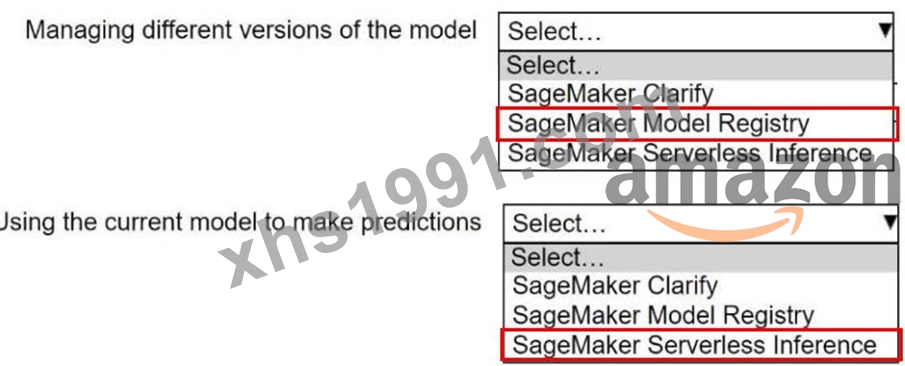
Reference:
AWS SageMaker Documentation: Model Registry (https://docs.aws.amazon.com/sagemaker/latest/dg/model-registry.html) AWS SageMaker Documentation: Serverless Inference (https://docs.aws.amazon.com/sagemaker/latest/dg/serverless-inference.html) AWS AI Practitioner Study Guide (conceptual alignment with SageMaker features for model lifecycle management and inference) Let's format this question according to the specified structure and provide a detailed, verified answer based on AWS AI Practitioner knowledge and official AWS documentation. The question focuses on selecting an AWS database service that supports storage and queries of embeddings as vectors, which is relevant to generative AI applications.
質問 # 154
A large retail bank wants to develop an ML system to help the risk management team decide on loan allocations for different demographics.
What must the bank do to develop an unbiased ML model?
正解:C
解説:
Class imbalance in a training dataset can cause ML models to favor overrepresented groups, leading to biased predictions. The AWS AI Practitioner guide and SageMaker Clarify documentation emphasize the need to identify and mitigate class imbalance to ensure fairness and unbiased model outcomes.
* D is correct: By measuring class imbalance and adapting the training process (e.g., through oversampling, undersampling, or using class weights), organizations can improve fairness and reduce bias across demographic groups.
* A (reducing data size) could worsen bias by removing potentially useful diverse data.
* B (consistency with historical results) might reinforce existing biases.
* C (separate models) is not scalable and can introduce other fairness issues.
"To reduce bias, examine class imbalance in your training data and use techniques to ensure all groups are fairly represented." (Reference: AWS SageMaker Clarify: Mitigating Bias, AWS Responsible AI)
質問 # 155
A company needs to build its own large language model (LLM) based on only the company's private dat a. The company is concerned about the environmental effect of the training process.
Which Amazon EC2 instance type has the LEAST environmental effect when training LLMs?
正解:A
解説:
The Amazon EC2 Trn series (Trainium) instances are designed for high-performance, cost-effective machine learning training while being energy-efficient. AWS Trainium-powered instances are optimized for deep learning models and have been developed to minimize environmental impact by maximizing energy efficiency.
Option D (Correct): "Amazon EC2 Trn series": This is the correct answer because the Trn series is purpose-built for training deep learning models with lower energy consumption, which aligns with the company's concern about environmental effects.
Option A: "Amazon EC2 C series" is incorrect because it is intended for compute-intensive tasks but not specifically optimized for ML training with environmental considerations.
Option B: "Amazon EC2 G series" (Graphics Processing Unit instances) is optimized for graphics-intensive applications but does not focus on minimizing environmental impact for training.
Option C: "Amazon EC2 P series" is designed for ML training but does not offer the same level of energy efficiency as the Trn series.
AWS AI Practitioner Reference:
AWS Trainium Overview: AWS promotes Trainium instances as their most energy-efficient and cost-effective solution for ML model training.
質問 # 156
......
Xhs1991を手に入れるのは、AmazonのAIF-C01認定試験に合格する鍵を手に入れるのに等しいです。Xhs1991の AmazonのAIF-C01試験トレーニング資料は高度に認証されたIT領域の専門家の経験と創造を含めているものです。その権威性は言うまでもありません。あなたはうちのAmazonのAIF-C01問題集を購入する前に、Xhs1991は無料でサンプルを提供することができます。
AIF-C01資格専門知識: https://www.xhs1991.com/AIF-C01.html
ちなみに、Xhs1991 AIF-C01の一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=19TBLBIYxNFl0twoYn14pRqXICHLTMBy-