Trotzdem sagen viele Menschen, dass das Ergebniss nicht wichtig und der Prozess am allerwichtigsten ist. Aber diese Darstellung passt nicht in der Microsoft DP-800 Prüfung, denn die Zertifizierung der Microsoft DP-800 können Ihnen im Arbeitsleben in der IT-Branche echte Vorteile mitbringen. Wenn Sie Entschluss haben, die Prüfung zu bestehen, dann sollten Sie unsere Microsoft DP-800 Prüfungssoftware benutzen wegen ihrer anspruchsvollen Garantie. Wenn Sie noch zögern, können Sie zuerst unsere kostenlose Demo der Microsoft DP-800 probieren. Dadurch werden Sie empfinden die Konfidenz fürs Bestehen, die wir Fast2test Ihnen mitbringen!
| Thema | Einzelheiten |
|---|---|
| Thema 1 |
|
| Thema 2 |
|
| Thema 3 |
|
Fast2test bietet Ihnen eine reale Umgebung, in der Sie sich auf die Microsoft DP-800 Prüfung vorbereiten. Wenn Sie Anfänger sind oder Ihre beruflichen Fertigkeiten verbessern wollen, wird Fast2test Ihnen helfen, IhremTraum Schritt für Schritt zu ernähern. Wenn Sie Fragen haben, werden wir Ihnen sofort helfen. Innerhalb einesJahres bieten wir kostenlosen Update-Service.
75. Frage
You have an Azure SQL database that supports the OLTP workload of an order-processing application.
During a 10-minute incident window, you run a dynamic management view query and discover the following:
Session 72 is sleeping with open_transaction_count = 1.
Multiple other sessions show blocking_session_id = 72 in sys.dm_exec_requests.
sys.dm_exec_input_buffer(72, NULL) returns only BEGIN TRANSACTION UPDATE Sales.Orders.
Users report that updates to Sales.Orders intermittently time out during the incident window. The timeouts stop only after you manually terminate session 72.
What is a possible cause of the blocking?
Antwort: C
76. Frage
Case Study 2 - Fabrikam
Existing Environment
Azure Environment
Fabrikam has a single Azure subscription in the East US 2 Azure region. The subscription contains an Azure SQL database named DB1. DB1 contains the following tables:
* Patients
* Employees
* Procedures
* Transactions
* UsefulPrompts
* ProcedureDocuments
You store a column master key as a secret in Azure Key Vault.
You have an on-premises application named TransactionProcessing that uses a hard-coded username and password in a connection string to access DB1.
Problem Statements
Users report that after executing a long-running stored procedure named sp_UpdateProcedureForPatient, updates to the underlying data are sometimes inconsistent.
Requirements
Planned Changes
Fabrikam plans to manage all changes to Azure SQL Database objects by using source control in GitHub. Every pull request submitted to production will be validated before it can be merged.
Deployments must use the Release configuration.
Security Requirements
Fabrikam identifies the following security requirements:
* The TransactionProcessing application must use a passwordless connection to DB1.
* The Employees table contains two columns named TaxID and Salary that must be encrypted at rest.
* Auditors must have a tamper-evident history of transactions with cryptographic proof of changes to the employee data.
Database Performance Requirements
Records accessed by using sp_UpdateProcedureForPatient must NOT be changed by other transactions while the stored procedure runs.
AI Search, Embeddings, and Vector Indexing
Fabrikam identifies the following AI-related requirements:
* Queries to the ProcedureDocuments table must use Reciprocal Rank Fusion (RRF).
* Users must be able to query the data in DB1 by using prompts in Copilot in Microsoft Fabric.
* The UsefulPrompts table will store prompts that doctors can use to help diagnose patient illness by connecting to an Azure OpenAI endpoint.
Development Requirements
Fabrikam identifies the following development requirements:
* Provide the functionality to retrieve all the transactions of a given patient between two dates, showing a running total.
* Expose a Data API builder (DAB) configuration file to enable Azure services to perform the following operations over a REST API:
- Read data from the procedures table without authentication.
- Read and insert data into the Transactions table once authenticated.
- Execute the sp_UpdateProcedurePatient stored procedure.
* Provide the functionality to retrieve a list of the names of patients who underwent medical procedures during the last 30 days.
* Information for each medical procedure will be stored in a table. The table will be used with a large language model (LLM) for user querying and will have the following structure.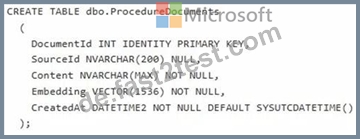
DAB
You create a DAB configuration file that meets the development requirements for DB1 and includes the following entities.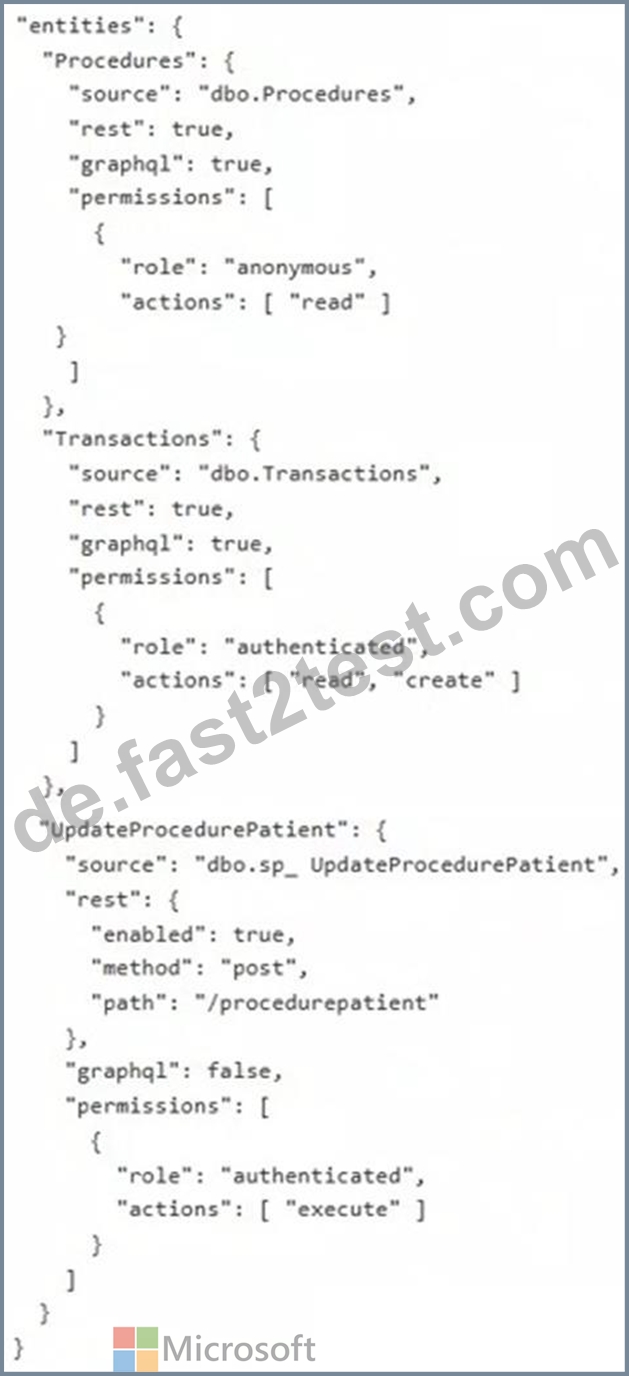
You plan to implement changes to sp_UpdateProcedureForPatient to meet the performance requirements.
You change the stored procedure to run all its code within a transaction.
Which transaction level should you use?
Antwort: B
Begründung:
Scenario: Database Performance Requirements
Records accessed by using sp_UpdateProcedureForPatient must NOT be changed by other transactions while the stored procedure runs.
To prevent other transactions from changing records while your stored procedure runs, you should use the Repeatable Read isolation level.
Repeatable ReadMechanism: Places shared locks on all data read by the query.
Prevention: Prevents other transactions from modifying or deleting the rows you have accessed.
Consistency: Ensures that if you read the same data twice within the procedure, the values remain identical.
Incorrect:
[Not C]
Serializable
Strictness: This is the highest level of isolation.
Phantom Protection: In addition to preventing changes to existing records, it prevents other transactions from inserting new records that would fall into the range of your query (phantom reads).
Usage: Use this if your procedure relies on aggregate counts or specific ranges that must remain absolutely static.
Key Considerations
Concurrency: Both levels reduce system performance because they hold locks longer, potentially causing other users to wait.
Deadlocks: Higher isolation levels increase the risk of deadlocks in busy databases.
Reference:
https://learn.microsoft.com/en-us/sql/connect/jdbc/understanding-isolation-levels
77. Frage
You have a database named DB1. The schema is stored in a GitHub repository as an SDK style SQL database project.
You use a feature branch workflow to deploy changes to DB1
You need to update the local feature branch with the latest changes to main, and then create a pull request to merge the feature branch into main for review.
How should you complete the GitHub CLI script? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.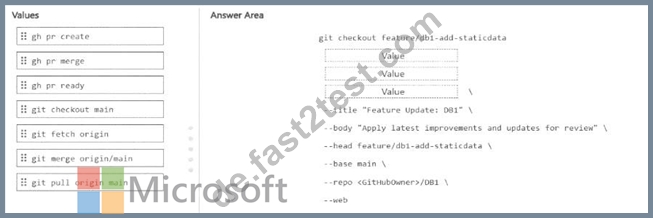
Antwort:
Begründung: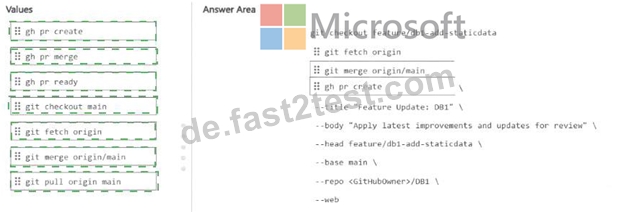
Explanation: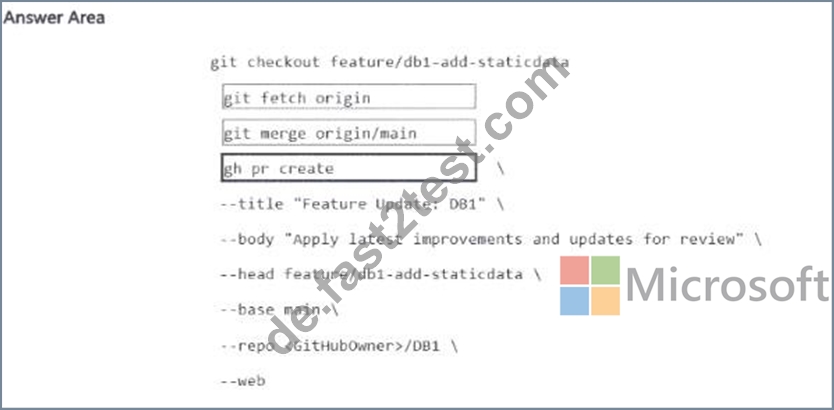
The correct sequence is:
* git fetch origin
* git merge origin/main
* gh pr create
This is the right workflow because the script starts on the local feature branch:
git checkout feature/db1-add-staticdata
To update that local feature branch with the latest changes from main, you first fetch the latest remote refs with git fetch origin , then merge the updated remote main branch into the current feature branch with git merge origin/main . After the feature branch is up to date, the correct GitHub CLI command to open the pull request is gh pr create . GitHub's CLI documentation shows that gh pr create is the command used to create a pull request, and supports flags such as --title, --body, --head, --base, --repo, and --web, which match the script shown in the question.
The other commands are not the best fit here:
* git checkout main would move you off the feature branch, which is not what you want before merging main into the feature branch.
* git pull origin main could update from remote main, but the script pattern here clearly separates fetching and then merging.
* gh pr merge merges an existing pull request, not create one.
* gh pr ready marks a draft PR as ready for review, but does not create the PR.
78. Frage
You have a Microsoft SQL Server 2025 database that contains a table named products. products contains two columns named description and embedding. embedding is generated from description.
You have an application named App1. App1 has a feature that uses the following query.
VECTOR_DISTANCE('cosine', @query_vector, embedding)
Users report that the feature is slow during peak usage times.
You discover that during peak usage times, the semantic search latency increases and CPU utilization spikes.
You need to reduce latency and CPU utilization related to the App1 feature.
What should you do?
Antwort: D
Begründung:
The correct answer is C because the current query uses VECTOR_DISTANCE( ' cosine ' , @query_vector, embedding) , which performs an exact vector distance calculation . Microsoft explicitly documents that VECTOR_DISTANCE does not use a vector index , even when one exists. Exact k-nearest-neighbor searches can require scanning large numbers of vectors and calculating distances row by row, which explains the observed CPU spikes and increased semantic-search latency during peak load.
A vector index on products.embedding is specifically designed to accelerate nearest-neighbor search, and VECTOR_SEARCH is the Transact-SQL function that can use that approximate nearest-neighbor index when the index metric matches the query metric. Using METRIC = ' cosine ' preserves the same similarity metric currently used by App1 while reducing the amount of computation required.
The other choices are incorrect:
* A normalizes vectors but does not replace the expensive exact search with indexed ANN retrieval.
* B replaces semantic vector search with lexical full-text search and changes the feature's behavior.
* D a standard nonclustered B-tree index cannot accelerate vector-distance operations.
* E converting embeddings to VARBINARY(8000) removes native vector semantics and does not solve the performance problem.
Therefore, the exam-aligned solution is create a vector index and use VECTOR_SEARCH with cosine distance .
79. Frage
You have a database named DB1. The schema is stored in a Git repository as an SDK-style SQL database project.
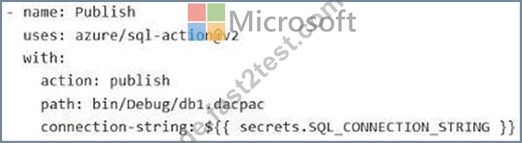
You have a GitHub Actions workflow that already runs dotnet build and produces a database artifact.
You need to add a deployment step that publishes the .dacpac file to an Azure SQL database by using the secrets stored in GitHub repository secrets.
What should you include in the workflow?
Antwort: D
Begründung:
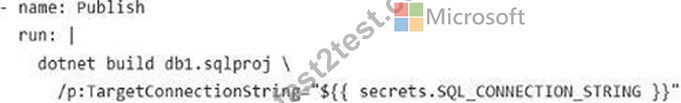
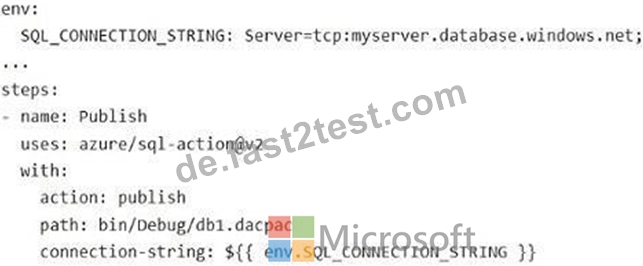
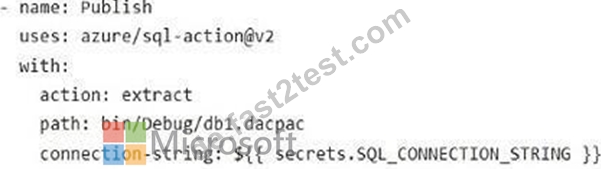
To deploy your .dacpac to Azure SQL using GitHub Actions, you should use the official azure/sql- action@v2. This action is designed specifically to take the output of your dotnet build and publish it.
Assuming your build step is already working, here is how you structure the deployment job.
GitHub Actions Workflow Snippet
Add this job to your .yml file. It depends on your build job (usually named build) and runs on a runner with the Azure CLI installed (like ubuntu-latest).
- name: Deploy SQL Schema
uses: azure/sql-action@v2
with:
connection-string: ${{ secrets.AZURE_SQL_CONNECTION_STRING }}
path: './bin/Release/netstandard2.1/YourDatabase.dacpac' # Path to your .dacpac action: 'publish' Incorrect:
[Not A]
Use connection-string: ${{ secrets.AZURE_SQL_CONNECTION_STRING }}
[Not B]
Action set to publish, not to extract.
[Not D]
Use azure/sql-action@v2.
Reference:
https://stackoverflow.com/questions/75490960/github-actions-dotnet-publish-specify-a-project- with-a-dot-in-the-name
80. Frage
......
Wollen Sie die Microsoft DP-800 Zertifizierungsprüfung schnell bestehen? Dann wählen Sie doch unseren Fast2test, der Ihren Traum schnell verwirklichen kann. Unser Fast2test bietet die genauen Prüfungsmaterialien zu den IT-Zertifizierungsprüfungen. Unser Fast2test kann den IT-Fachleuten helfen, im Beruf befördert zu werden. Unsere Kräfte sind unglaublich stark. Sie können im Internet die Demo zur Microsoft DP-800 Prüfung kostenlos herunterladen, so dass Sie die Glaubwürdigkeit von Fast2test testen können.
DP-800 Deutsche: https://de.fast2test.com/DP-800-premium-file.html