Real Databricks Databricks-Machine-Learning-Professional Exam Questions: Ensure Your Success
What's more, part of that TorrentValid Databricks-Machine-Learning-Professional dumps now are free: https://drive.google.com/open?id=1mZ6WGQv8DoVOQA0LYOeCnCcDDWB8p4aG
Our Databricks-Machine-Learning-Professional learning guide materials have won the favor of many customers by virtue of their high quality. Started when the user needs to pass the qualification test, choose the Databricks-Machine-Learning-Professional real questions, they will not have any second or even third backup options, because they will be the first choice of our practice exam materials. Our Databricks-Machine-Learning-Professional Practice Guide is devoted to research on which methods are used to enable users to pass the test faster. Therefore, through our unremitting efforts, our Databricks-Machine-Learning-Professional real questions have a pass rate of 98% to 100%.
Databricks Databricks-Machine-Learning-Professional Exam Overview:
>> Formal Databricks-Machine-Learning-Professional Test <<
Databricks-Machine-Learning-Professional Exam Course | Instant Databricks-Machine-Learning-Professional Download
TorrentValid is a website for Databricks Certification Databricks-Machine-Learning-Professional Exam to provide a short-term effective training. Databricks Databricks-Machine-Learning-Professional is a certification exam which is able to change your life. IT professionals who gain Databricks Databricks-Machine-Learning-Professional authentication certificate must have a higher salary than the ones who do not have the certificate and their position rising space is also very big, who will have a widely career development prospects in the IT industry in.
| Topic | Details |
|---|
| Topic 1 | - Identify less performant data storage as a solution for other use cases
- Describe why complex business logic must be handled in streaming deployments
|
| Topic 2 | - Identify live serving benefits of querying precomputed batch predictions
- Describe Structured Streaming as a common processing tool for ETL pipelines
|
| Topic 3 | - Identify JIT feature values as a need for real-time deployment
- Describe how to list all webhooks and how to delete a webhook
|
| Topic 4 | - Test whether the updated model performs better on the more recent data
- Identify when retraining and deploying an updated model is a probable solution to drift
|
| Topic 5 | - Describe model serving deploys and endpoint for every stage
- Identify scenarios in which feature drift and
- or label drift are likely to occur
|
| Topic 6 | - Identify a use case for HTTP webhooks and where the Webhook URL needs to come
- Identify advantages of using Job clusters over all-purpose clusters
|
| Topic 7 | - Identify which code block will trigger a shown webhook
- Describe the basic purpose and user interactions with Model Registry
|
| Topic 8 | - Describe the advantages of using the pyfunc MLflow flavor
- Manually log parameters, models, and evaluation metrics using MLflow
|
| Topic 9 | - Describe concept drift and its impact on model efficacy
- Describe summary statistic monitoring as a simple solution for numeric feature drift
|
| Topic 10 | - Identify that data can arrive out-of-order with structured streaming
- Identify how model serving uses one all-purpose cluster for a model deployment
|
Databricks Certified Machine Learning Professional Sample Questions (Q33-Q38):
NEW QUESTION # 33
A data scientist would like to switch from manually using MLflow logging to MLflow Autologging for all machine learning libraries used in a notebook.
They begin by adding mlflow.autolog()to the top of the below code block:
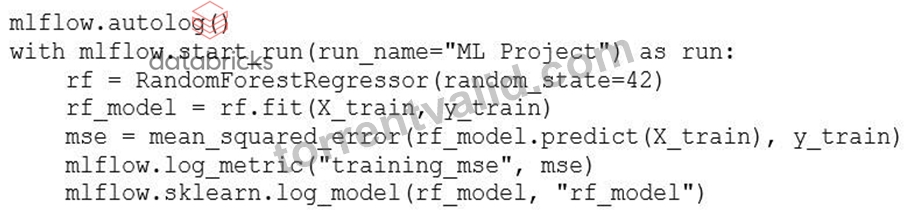
The data scientist is now trying to determine which line of code will kick off the MLflow Autologging process.
Which line of code within the above code block will start the MLflow Autologging process?
- A. mlflow.log_metric("training_mse", mse)
- B. mlflow.sklearn.log_model(rf_model, "rf_model")
- C. rf_model = rf.fit(X_train, y_train)
- D. with mlflow.start_run(run_name="ML Project") as run:
Answer: C
Explanation:
The MLflow Autologging process is triggered when a model's training function is called. In this case, rf.fit(X_train, y_train) starts the autologging process because mlflow.autolog() automatically tracks parameters, metrics, and the model when a supported estimator (like RandomForestRegressor) is fitted. The context manager mlflow.start_run() only initiates an MLflow run, but the actual autologging begins during the .fit() execution.
NEW QUESTION # 34
A Machine Learning Engineer needs to build a time series model. In Databricks, they have created isolated environments in different workspaces for development, staging, and production.
To manage this model, they are planning on using a "deploy code" strategy. They are concerned that the model trained in development will not remain consistent across environments, due to differences in the dependencies installed. What can they do to ensure that the model is trained with the same packages?
- A. Use MLflow to track the model parameters and metrics in development, then export the same training conditions in staging and production.
- B. Use the same Databricks Runtime (DBR) version across environments and define dependencies in a lock file that is installed as part of the job.
- C. Use Databricks Repos to store the model code and install the required libraries in the notebook.
- D. Use custom init scripts that install the necessary packages as part of the job.
Answer: B
Explanation:
Using the same Databricks Runtime across environments ensures a consistent base environment, and installing dependencies from a lock file guarantees identical package versions during training. This combination follows best practices for deploy-code workflows by making the training environment reproducible and preventing dependency drift between development, staging, and production.
NEW QUESTION # 35
Which of the following lists all of the model stages are available in the MLflow Model Registry?
- A. Staging. Production. Archived
- B. None. Staging. Production. Archived
- C. Development. Staging. Production
- D. Development. Staging. Production. Archived
- E. None. Staging. Production
Answer: B
NEW QUESTION # 36
A Machine Learning Engineer has deployed a fraud detection model that processes 10,000 transactions per hour. The model was trained on data from Q1 2024, but it's now Q4 2024. The ML team notices three concerning trends: (1) the model's precision has dropped from 92% to
78% over the past month, (2) the average transaction amount in recent data has increased from
$150 to $220 and (3) the relationship between transaction frequency and fraud likelihood has weakened significantly due to new payment methods being introduced. The engineer needs to implement a monitoring solution that can detect the root cause of the performance degradation, identify why the precision dropped, and be able to do this at the scale needed. Which monitoring pipeline component will do this?
- A. Drift Detection Pipeline because it can identify both the data drift (transaction amount changes) and concept drift (weakened relationship between features and target).
- B. Model Performance Monitoring Pipeline because it directly tracks precision metrics and can alert when thresholds are breached.
- C. Logging and Monitoring Pipeline because it captures all prediction requests and can identify patterns in the fraud predictions.
- D. Model Health Monitoring Pipeline because it ensures the infrastructure can handle the 10,000 transactions per hour load.
Answer: A
Explanation:
A drift detection pipeline is designed to diagnose the root causes of model performance degradation at scale. It can detect data drift, such as changes in the distribution of transaction amounts, and concept drift, where the relationship between input features and the fraud label changes due to new payment methods. This directly explains why precision dropped and provides actionable insight beyond simply observing metric degradation.
NEW QUESTION # 37
A Machine Learning Engineer has trained a credit scoring model and needs to evaluate fairness metrics across different customer segments while maintaining different levels of granularity for business reporting. They need to compute metrics like precision, recall, and demographic parity at the individual feature level (credit_score_range, income_bracket) as well as intersectional slices (combinations of features). The model outputs are stored in a Delta table with prediction probabilities and actual default labels. The engineer wants to systematically evaluate model performance across these various feature slices and granularities. Which approach will do this?
- A. Create Lakehouse Monitoring with slicing expressions for individual features and intersection conditions.
- B. Use Unity Catalog metric views with dimensions defined for each feature and measures for the fairness metrics.
- C. Implement custom MLflow evaluation functions that iterate through all possible feature combinations.
- D. Build separate Spark DataFrames for each slice and compute metrics using standard DataFrame operations.
Answer: A
Explanation:
Lakehouse Monitoring supports defining slicing expressions on one or more columns, allowing metrics such as precision, recall, and fairness indicators to be computed at both individual feature levels and intersectional combinations. This provides a systematic, scalable, and governed way to evaluate model performance and fairness across multiple granularities directly from Delta tables without custom metric pipelines.
NEW QUESTION # 38
......
Databricks-Machine-Learning-Professional Exam Course: https://www.torrentvalid.com/Databricks-Machine-Learning-Professional-valid-braindumps-torrent.html
- Free PDF Quiz Useful Databricks-Machine-Learning-Professional - Formal Databricks Certified Machine Learning Professional Test ✒ Search for ⇛ Databricks-Machine-Learning-Professional ⇚ and download it for free on ➠ www.exam4labs.com 🠰 website 🌵Exam Databricks-Machine-Learning-Professional Experience
- Professional Databricks-Machine-Learning-Professional - Formal Databricks Certified Machine Learning Professional Test 🍉 Easily obtain ⇛ Databricks-Machine-Learning-Professional ⇚ for free download through ✔ www.pdfvce.com ️✔️ 🍡Passing Databricks-Machine-Learning-Professional Score Feedback
- Professional Databricks-Machine-Learning-Professional - Formal Databricks Certified Machine Learning Professional Test 🧄 Search for 「 Databricks-Machine-Learning-Professional 」 and obtain a free download on ➥ www.pass4test.com 🡄 🍾Reliable Databricks-Machine-Learning-Professional Exam Book
- Professional Databricks-Machine-Learning-Professional - Formal Databricks Certified Machine Learning Professional Test 🍯 Copy URL ✔ www.pdfvce.com ️✔️ open and search for ☀ Databricks-Machine-Learning-Professional ️☀️ to download for free 🌶Reliable Databricks-Machine-Learning-Professional Exam Book
- 2026 RealisticDatabricks-Machine-Learning-Professional Exam Course - Databricks Formal Databricks Certified Machine Learning Professional Test 100% Pass 🔢 Open website ➥ www.troytecdumps.com 🡄 and search for { Databricks-Machine-Learning-Professional } for free download 🪑Databricks-Machine-Learning-Professional Real Testing Environment
- Exam Databricks-Machine-Learning-Professional Objectives Pdf 🏞 Databricks-Machine-Learning-Professional Exam Introduction 🧦 Training Databricks-Machine-Learning-Professional Kit 🚛 Easily obtain [ Databricks-Machine-Learning-Professional ] for free download through ➽ www.pdfvce.com 🢪 🍡Latest Databricks-Machine-Learning-Professional Test Questions
- Free PDF Quiz Useful Databricks-Machine-Learning-Professional - Formal Databricks Certified Machine Learning Professional Test 🚏 Simply search for ▷ Databricks-Machine-Learning-Professional ◁ for free download on ☀ www.exam4labs.com ️☀️ 🔒Valid Exam Databricks-Machine-Learning-Professional Vce Free
- 100% Pass 2026 High Pass-Rate Databricks Databricks-Machine-Learning-Professional: Formal Databricks Certified Machine Learning Professional Test 🥣 Search for ➥ Databricks-Machine-Learning-Professional 🡄 and download it for free immediately on ( www.pdfvce.com ) 🤎Latest Databricks-Machine-Learning-Professional Test Questions
- Fast Download Formal Databricks-Machine-Learning-Professional Test - Pass Databricks-Machine-Learning-Professional in One Time - Useful Databricks-Machine-Learning-Professional Exam Course 🪁 Download ➥ Databricks-Machine-Learning-Professional 🡄 for free by simply searching on ➡ www.prepawayete.com ️⬅️ 🐶Exam Databricks-Machine-Learning-Professional Quick Prep
- Efficient Formal Databricks-Machine-Learning-Professional Test Offers Candidates High-quality Actual Databricks Databricks Certified Machine Learning Professional Exam Products ⛽ The page for free download of ⏩ Databricks-Machine-Learning-Professional ⏪ on ⇛ www.pdfvce.com ⇚ will open immediately 🏙Reliable Databricks-Machine-Learning-Professional Exam Book
- Databricks-Machine-Learning-Professional Technical Training 🥼 Databricks-Machine-Learning-Professional Reliable Test Online 🤩 Exam Databricks-Machine-Learning-Professional Discount 🍄 Download ( Databricks-Machine-Learning-Professional ) for free by simply searching on ➡ www.practicevce.com ️⬅️ 👵Databricks-Machine-Learning-Professional Reliable Test Online
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.toprecepty.cz, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
P.S. Free 2026 Databricks Databricks-Machine-Learning-Professional dumps are available on Google Drive shared by TorrentValid: https://drive.google.com/open?id=1mZ6WGQv8DoVOQA0LYOeCnCcDDWB8p4aG