Certified-Data-Engineer-Professional Exam Test, Valid Braindumps Certified-Data-Engineer-Professional Files

Actual4dump is the website that has been known to learn IT technology. Actual4dump gets high praise from our customers in real test questions and answers. It is the real website that can help you to pass Databricks Certified-Data-Engineer-Professional certificate. Why is Actual4dump very popular? Because Actual4dump has a group of IT elite which is committed to provide you with the best test questions and test answers. Therefore, Actual4dump will provide you with more and better certification training materials to satisfy your need.
| Section | Objectives |
|---|
| Topic 1: Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Manage and troubleshoot third-party library installations and dependencies
- 2. Develop User-Defined Functions using Pandas/Python UDFs
- 3. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- Building and Testing ETL Pipelines
- 1. Compare streaming tables and materialized views
- 2. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 3. Configure environments, dependencies, memory, and retry behavior
- 4. Develop unit and integration tests for data processing code
- 5. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 6. Use APPLY CHANGES APIs for change data capture
- 7. Use control flow operators in pipeline components
- 8. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
|
| Topic 2: Data Governance | - Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
- Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
|
| Topic 3: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest data from message buses and cloud storage
- 2. Build append-only pipelines for batch and streaming data using Delta
- 3. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
|
| Topic 4: Cost & Performance Optimisation | - Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
- Delta Optimization
- 1. Apply data skipping and file pruning techniques
- 2. Understand deletion vectors and liquid clustering
- 3. Use Change Data Feed to address streaming table limitations and improve latency
- Query Performance
- 1. Identify inefficient joins and excessive data shuffling
- 2. Use Query Profile to identify performance bottlenecks
|
| Topic 5: Data Modelling | - Scalable Data Models
- 1. Design and implement scalable data models using Delta Lake
- 2. Optimize data layout using Liquid Clustering
- 3. Understand Liquid Clustering versus partitioning and Z-Ordering
- Dimensional Modelling
- 1. Design dimensional models for analytical workloads
|
| Topic 6: Data Transformation, Cleansing, and Quality | - Data Quality
- 1. Develop data quarantining processes for invalid data
- 2. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- Advanced Data Transformation
- 1. Apply window functions, joins, and aggregations to large datasets
- 2. Write efficient Spark SQL and PySpark transformations
|
| Topic 7: Data Sharing and Federation | - Delta Sharing
- 1. Configure Databricks-to-Databricks Sharing
- 2. Configure sharing with external platforms using the open sharing protocol
- 3. Share live Lakehouse data with external computing platforms
- Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
|
| Topic 8: Debugging and Deploying | - Debugging and Troubleshooting
- 1. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- 2. Analyze errors and remediate failed job runs
- 3. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- Deploying CI/CD
- 1. Integrate Git-based CI/CD workflows using Databricks Git Folders
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
|
| Topic 9: Ensuring Data Security and Compliance | - Compliance
- 1. Implement pipelines that detect and mask personally identifiable information
- 2. Develop data purging solutions according to data retention policies
- Data Security
- 1. Use row filters and column masks for sensitive data
- 2. Use ACLs to secure workspace objects and enforce least privilege
- 3. Apply anonymization and pseudonymization techniques
|
| Topic 10: Monitoring and Alerting | - Monitoring
- 1. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 2. Use Query Profiler and Spark UI to monitor workloads
- 3. Use system tables for resource, cost, audit, and workload monitoring
- 4. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- Alerting
- 1. Configure Lakeflow Jobs notifications for job status and performance issues
- 2. Use SQL Alerts for data quality monitoring
|
>> Certified-Data-Engineer-Professional Exam Test <<
New Certified-Data-Engineer-Professional Exam Test | High-quality Databricks Valid Braindumps Certified-Data-Engineer-Professional Files: Databricks Certified Data Engineer Professional
Using Certified-Data-Engineer-Professional exam prep is an important step for you to improve your soft power. I hope that you can spend a little time understanding what our study materials have to attract customers compared to other products in the industry. Certified-Data-Engineer-Professional exam dumps have a higher pass rate than products in the same industry. If you want to pass Certified-Data-Engineer-Professional Certification, then it is necessary to choose a product with a high pass rate. Our study materials guarantee the pass rate from professional knowledge, services, and flexible plan settings. According to user needs, Certified-Data-Engineer-Professional exam prep provides everything possible to ensure their success.
Databricks Certified Data Engineer Professional Sample Questions (Q243-Q248):
NEW QUESTION # 243
The data engineering team has configured a job to process customer requests to be forgotten (have their data deleted). All user data that needs to be deleted is stored in Delta Lake tables using default table settings.
The team has decided to process all deletions from the previous week as a batch job at 1am each Sunday. The total duration of this job is less than one hour. Every Monday at 3am, a batch job executes a series of VACUUM commands on all Delta Lake tables throughout the organization.
The compliance officer has recently learned about Delta Lake's time travel functionality. They are concerned that this might allow continued access to deleted data.
Assuming all delete logic is correctly implemented, which statement correctly addresses this concern?
- A. Because Delta Lake time travel provides full access to the entire history of a table, deleted records can always be recreated by users with full admin privileges.
- B. Because the default data retention threshold is 24 hours, data files containing deleted records will be retained until the vacuum job is run the following day.
- C. Because the vacuum command permanently deletes all files containing deleted records, deleted records may be accessible with time travel for around 24 hours.
- D. Because the default data retention threshold is 7 days, data files containing deleted records will be retained until the vacuum job is run 8 days later.
- E. Because Delta Lake's delete statements have ACID guarantees, deleted records will be permanently purged from all storage systems as soon as a delete job completes.
Answer: D
Explanation:
https://learn.microsoft.com/en-us/azure/databricks/delta/vacuum
NEW QUESTION # 244
A data architect has designed a system in which two Structured Streaming jobs will concurrently write to a single bronze Delta table. Each job is subscribing to a different topic from an Apache Kafka source, but they will write data with the same schema. To keep the directory structure simple, a data engineer has decided to nest a checkpoint directory to be shared by both streams.
The proposed directory structure is displayed below:
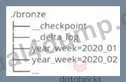
Which statement describes whether this checkpoint directory structure is valid for the given scenario and why?
- A. No; only one stream can write to a Delta Lake table.
- B. Yes; both of the streams can share a single checkpoint directory.
- C. Yes; Delta Lake supports infinite concurrent writers.
- D. No; Delta Lake manages streaming checkpoints in the transaction log.
- E. No; each of the streams needs to have its own checkpoint directory.
Answer: E
Explanation:
This is the correct answer because checkpointing is a critical feature of Structured Streaming that provides fault tolerance and recovery in case of failures. Checkpointing stores the current state and progress of a streaming query in a reliable storage system, such as DBFS or S3. Each streaming query must have its own checkpoint directory that is unique and exclusive to that query. If two streaming queries share the same checkpoint directory, they will interfere with each other and cause unexpected errors or data loss.
NEW QUESTION # 245
A workspace admin has created a new catalog called finance_data and wants to delegate permission management to a finance team lead without giving them full admin rights. Which privilege should be granted to the finance team lead?
- A. GRANT OPTION privilege on the finance_data catalog.
- B. MANAGE privilege on the finance_data catalog.
- C. Make the finance team lead a metastore admin.
- D. ALL PRIVILEGES on the finance_data catalog.
Answer: B
Explanation:
The MANAGE privilege in Unity Catalog provides the ability to grant and revoke privileges on the specified object (in this case, a catalog) without giving full administrative access or ownership.
This is the Databricks-recommended approach for delegating governance responsibilities while preserving the principle of least privilege.
By contrast, the ALL PRIVILEGES option grants excessive access (including read and write permissions), and metastore admin status provides global control over all catalogs--far exceeding the requirement. The MANAGE privilege enables the finance team lead to control access to objects within finance_data responsibly while limiting overall administrative exposure.
NEW QUESTION # 246
A security team wants to enforce data protection for a customer table containing customer PII data. To comply with local policies, sales team members should only see customers from their region, while non-admin users should have email addresses masked. Which implementation approach should be used when using Unity Catalog row filters and column masks?
- A. Implement row filters with SQL UDFs based on user region only since column masks cannot be combined with row filters on the same table, then apply them be recreating the table with DROP TABLE and CREATE TABLE SET ROW FILTER commands.
- B. Use table ACLs to restrict access using tags with GRANT SELECT ON table_name WITH TAG command, and rely on application-level filtering for sensitive data based on user region.
- C. Create a view with dynamic WHERE clauses for region filtering and use string replacement functions for email masking using ALTER COLUMN SET MASK command.
- D. Create SQL UDFs for row filtering based on user region and column masking based on group membership, then apply them using ALTER TABLE SET ROW FILTER and ALTER COLUMN SET MASK commands.
Answer: D
Explanation:
Unity Catalog enforces fine-grained access control by applying SQL UDF-based row filters and column masks directly at the table level. Row filter UDFs can restrict visible rows based on the user's region, while column mask UDFs can dynamically mask sensitive fields like email addresses for non-admin users. Applying them with ALTER TABLE SET ROW FILTER and ALTER COLUMN SET MASK ensures centralized, consistent enforcement of data protection policies across all access paths.
NEW QUESTION # 247
A data engineer needs to install the PyYAML Python package within an air-gapped Databricks environment. The workspace has no direct internet access to PyPI. The engineer has downloaded the .whl file locally and wants it available automatically on all new clusters. Which approach should the data engineer use?
- A. Upload the PyYAML .whl file to a Unity Catalog Volume, ensure it's allow-listed, and create a cluster-scoped init script that installs it from that path.
- B. Upload the PyYAML .whl file to the user home directory and create a cluster-scoped init script to install it.
- C. Add the .whl file to Databricks Git Repos and assume automatic installation.
- D. Set up a private PyPI repository and install via pip index URL.
Answer: A
Explanation:
For secure, air-gapped Databricks deployments, the recommended practice is to host dependency files such as .whl packages in Unity Catalog Volumes -- a managed storage layer governed by Unity Catalog.
Once stored in a volume, these files can be safely referenced from cluster-scoped init scripts, which automatically execute installation commands (e.g., pip install
/Volumes/catalog/schema/path/PyYAML.whl) during cluster startup.
This ensures consistent environment setup across clusters and compliance with data governance rules.
User directories (A) lack enterprise security controls; private repositories (C) are not viable in air- gapped setups; and Git repos (D) do not trigger package installation. Therefore, B is the correct and officially approved method.
NEW QUESTION # 248
......
All our regular candidates have impulse to choose again when they have the similar Certified-Data-Engineer-Professional exam. So they totally trust us. All exams are not insuperable obstacle anymore with our Certified-Data-Engineer-Professional training materials. Our credibility is unquestionable. In the course of obtaining success, we need a number of helps, either external or internal, but to the exam, the quality of Certified-Data-Engineer-Professional practice materials are of great importance. So our Certified-Data-Engineer-Professional learning dumps are acclaimed as masterpieces.
Valid Braindumps Certified-Data-Engineer-Professional Files: https://www.actual4dump.com/Databricks/Certified-Data-Engineer-Professional-actualtests-dumps.html
- Certified-Data-Engineer-Professional Valid Study Materials 🚔 Certified-Data-Engineer-Professional Latest Test Practice 🍇 New Certified-Data-Engineer-Professional Test Review 🚞 Copy URL ➥ www.prepawaypdf.com 🡄 open and search for ➤ Certified-Data-Engineer-Professional ⮘ to download for free 📃Certified-Data-Engineer-Professional Practice Exam
- 2026 Certified-Data-Engineer-Professional: Perfect Databricks Certified Data Engineer Professional Exam Test 🖋 Search for ➤ Certified-Data-Engineer-Professional ⮘ and obtain a free download on ▷ www.pdfvce.com ◁ 🛃Latest Certified-Data-Engineer-Professional Exam Format
- 2026 Certified-Data-Engineer-Professional Exam Test | Newest Databricks Certified Data Engineer Professional 100% Free Valid Braindumps Files 🔓 Simply search for 【 Certified-Data-Engineer-Professional 】 for free download on ☀ www.easy4engine.com ️☀️ 🧟Certified-Data-Engineer-Professional Valid Braindumps Questions
- Certified-Data-Engineer-Professional Test Voucher 🦐 Certified-Data-Engineer-Professional Complete Exam Dumps 🕛 Certified-Data-Engineer-Professional Valid Braindumps Questions 💂 Simply search for ⮆ Certified-Data-Engineer-Professional ⮄ for free download on 「 www.pdfvce.com 」 🥭Certified-Data-Engineer-Professional Test Voucher
- Newest Databricks Certified-Data-Engineer-Professional Exam Test Offer You The Best Valid Braindumps Files | Databricks Certified Data Engineer Professional ⛑ Search for “ Certified-Data-Engineer-Professional ” and download it for free on 「 www.prepawayete.com 」 website 📷Certified-Data-Engineer-Professional Valid Braindumps Questions
- Certified-Data-Engineer-Professional Practice Exam 🤾 Certified-Data-Engineer-Professional Reliable Exam Tips 🍫 Certified-Data-Engineer-Professional Reliable Exam Practice 📸 Open website ✔ www.pdfvce.com ️✔️ and search for ⏩ Certified-Data-Engineer-Professional ⏪ for free download 🦟Certified-Data-Engineer-Professional PDF
- Realistic Certified-Data-Engineer-Professional Exam Test - Find Shortcut to Pass Certified-Data-Engineer-Professional Exam 🎠 Search on ➥ www.prepawayexam.com 🡄 for ☀ Certified-Data-Engineer-Professional ️☀️ to obtain exam materials for free download 🕵Latest Certified-Data-Engineer-Professional Exam Format
- Certified-Data-Engineer-Professional Test Torrent 🌈 Search for ☀ Certified-Data-Engineer-Professional ️☀️ and download it for free on 【 www.pdfvce.com 】 website 🆘New Certified-Data-Engineer-Professional Test Review
- 100% Pass Quiz 2026 Databricks Authoritative Certified-Data-Engineer-Professional Exam Test 🍑 Download ✔ Certified-Data-Engineer-Professional ️✔️ for free by simply searching on 「 www.prep4sures.top 」 😣New Certified-Data-Engineer-Professional Test Review
- Realistic Certified-Data-Engineer-Professional Exam Test - Find Shortcut to Pass Certified-Data-Engineer-Professional Exam 🎽 Open 《 www.pdfvce.com 》 enter ⏩ Certified-Data-Engineer-Professional ⏪ and obtain a free download 🔷Latest Certified-Data-Engineer-Professional Exam Format
- Actual Certified-Data-Engineer-Professional Test 🍃 Certified-Data-Engineer-Professional PDF 🎩 Certified-Data-Engineer-Professional Reliable Guide Files 🐶 Open ▷ www.pdfdumps.com ◁ enter ▶ Certified-Data-Engineer-Professional ◀ and obtain a free download ✌Certified-Data-Engineer-Professional Valid Braindumps Questions
- www.toprecepty.cz, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, elearn.ellak.gr, www.stes.tyc.edu.tw, freestyler.ws, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes