2026 Latest RealValidExam DEA-C02 PDF Dumps and DEA-C02 Exam Engine Free Share: https://drive.google.com/open?id=1oDV9hNyzMOBcO-oebTDPzaHvaZTG6-va
As long as you can form a positive outlook, which can aid you to realize your dreams through your constant efforts. Then our DEA-C02 learning questions will aid you to regain confidence and courage. So you will never regret to choose our DEA-C02 Study Materials. And we have help numerous of our customers achieved their dreams and live a better life. Just browser our websites and choose a suitable DEA-C02 practice guide for you.
| Section | Weight | Objectives |
|---|---|---|
| Data Sharing and Collaboration | 5-10% | - Design multi-tenant and cross-account data architectures - Implement secure data sharing and data exchanges - Work with Snowflake Data Marketplace and external data providers |
| Performance Optimization and Compute Management | 15-20% | - Monitor and tune workloads and resource utilization - Use search optimization and query acceleration services - Optimize query performance: clustering, partitioning, materialized views - Manage virtual warehouses: sizing, scaling, multi-cluster, cost control |
| Data Governance, Security, and Compliance | 10-15% | - Implement access control: RBAC, authentication, authorization - Manage data lineage, cataloging, and compliance policies - Enforce data quality and governance standards - Apply data protection: encryption, masking, row-level security |
| Data Ingestion and Sourcing | 20-25% | - Ingest data from various sources: data lakes, APIs, on-premises systems, cloud storage - Use Snowflake ingestion methods: Snowpipe, COPY INTO, External Functions - Design and implement continuous and batch ingestion pipelines - Handle different data formats: structured, semi-structured, unstructured |
| Data Transformation and Processing | 20-25% | - Process semi-structured data: JSON, Avro, Parquet, ORC - Implement ELT/ETL workflows using Streams, Tasks, and Dynamic Tables - Transform and enrich data using SQL, JavaScript, Python, and Snowpark - Manage data quality, validation, and deduplication |
| Data Pipeline Architecture and Design | 15-20% | - Design scalable, reliable, and maintainable data pipelines - Integrate with external tools and platforms: orchestration, BI, ML - Apply design patterns for data engineering workloads - Build end-to-end near real-time streaming solutions |
>> DEA-C02 Reliable Braindumps Pdf <<
We always strictly claim for our DEA-C02 study materials must be the latest version, to keep our study materials up to date, we constantly review and revise them to be at par with the latest Snowflake syllabus for DEA-C02 exam. This feature has been enjoyed by over 80,000 takes whose choose our study materials. The one who choose our study materials that consider our website as the top preparation material seller for DEA-C02 Study Materials, and inevitable to carry all candidates the finest knowledge on exam syllabus contents. Not only that, we will provide you a free update service within one year from the date of purchase, in order to keep up the changes in the exam so that every candidates who purchase our DEA-C02 study materials can pass the exam one time.
NEW QUESTION # 241
You're managing a Snowflake data warehouse and need to create a development environment for testing a complex stored procedure that updates a critical table, 'SALES DATA'. The procedure is located in the 'PRODUCTION' database and you want to ensure minimal impact to the production environment during development. You decide to use cloning and time travel. Which of the following strategies is the MOST efficient and safest approach to achieve this, minimizing downtime and resource consumption in production?
Answer: B
Explanation:
Option E offers the best balance of minimal impact and realistic testing. Cloning the entire database (A) is resource-intensive. Cloning only the table (B) requires significant manual setup to address dependencies. Option C might result in unpredictable behavior if any data dependencies exist that rely on related tables. Option D is almost correct, but the risk is that other objects in the 'PRODUCTION' database schema might change resulting in incomplete testing. Cloning the schema and using Time Travel on the schema level before updating the procedure gives the most consistent and efficient development setup and the best balance.
NEW QUESTION # 242
You have a Snowflake table named 'ORDERS clustered on 'ORDER DATE. After a significant data load, you want to evaluate the effectiveness of the clustering. Which of the following SQL queries, using Snowflake system functions, will provide insights into the clustering depth and overlap of micro-partitions in the 'ORDERS' table, specifically helping you identify whether re-clustering is necessary? Assume that the table





Answer: C
Explanation:
The query SELECT avg_depth, avg_overlap FROM is the correct approach. The function, when given the table name and the clustering key column(s), returns information about the clustering state. Using 'TABLE()' allows you to extract 'avg_deptm and 'avg_overlap', which are key metrics for assessing clustering effectiveness. 'avg_depth' indicates how well the data is clustered (lower is better), and 'avg_overlap' indicates the degree of overlap between micro-partitions (lower is better). A high 'avg_depth' or 'avg_overlap' suggests the need for re-clustering. Option A returns a JSON which is difficult to process to get the required metrics. Option B is missing the clustering key. Option C returns JSON and not the desired output. Option E is not valid SQL syntax in Snowflake.
NEW QUESTION # 243
You are developing a data pipeline that uses Snowpipe Streaming to ingest JSON data into a Snowflake table. Some JSON documents contain nested arrays and complex structures. You need to flatten the JSON structure during ingestion to simplify querying. Consider the following JSON document: { "order id": 123, "customer": { "id": "cust123", "name": "John Doe", "address": { "street": "123 Main St", "city": "Anytown" } }, "items": [ {"product_id": "prodl", "quantity": 2}, {"product_id": "prod2", "quantity": 1} ] } Which approach would you use within the 'COPY INTO' statement of your Snowpipe to flatten this JSON structure during ingestion?
Answer: A
Explanation:
Snowflake's 'FLATTEN()' function, combined with dot notation for nested objects, provides the most efficient way to flatten JSON data during ingestion within the 'COPY INTO' statement. Options B, C, and D introduce unnecessary complexity and latency. Snowpipe does NOT automatically flatten JSON (E).
NEW QUESTION # 244
You are tasked with building a User-Defined Aggregate Function (UDAF) in Snowflake to calculate the weighted average of product prices. The weight is determined by the quantity sold for each product. You have the following table: 'SALES (product_id INTEGER, price quantity INTEGER)'. Which of the following UDAF definitions would correctly calculate the weighted average?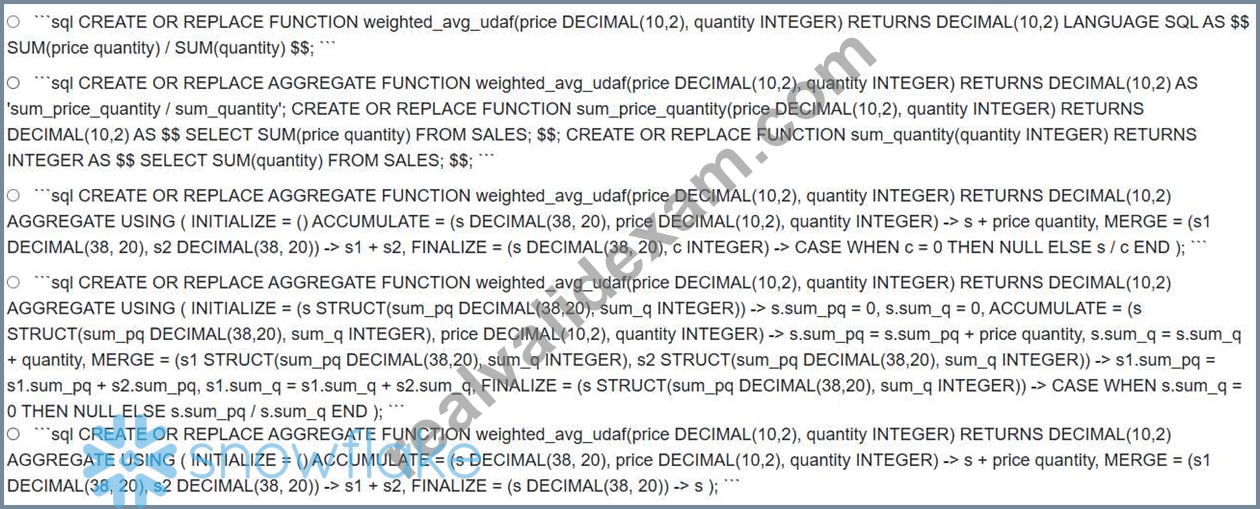
Answer: E
Explanation:
Option D is the correct implementation of a UDAF for calculating the weighted average. It uses a struct to store the sum of (price quantity) and the sum of quantities. It correctly initializes, accumulates, merges, and finalizes the aggregate result. Other options have logical and syntactic errors making it fail. Option A is wrong as it does not provide aggregate function. Option B defines SQL UDF as aggregate functions are called when there are multiple rows, and a single result is desired from those rows, making this definition also wrong. Option C does not account for sum of quanities and uses an unprovided count. Option E also does not account for quanities.
NEW QUESTION # 245
You are designing a data pipeline in Snowflake to process IoT sensor data'. The data arrives in JSON format, and you need to extract specific nested fields using a Snowpark UDF for performance reasons. Which of the following statements are true regarding best practices and limitations when working with complex JSON data and Snowpark UDFs (Python or Scala)? (Select all that apply)
Answer: A,B,D
Explanation:
Options B, C, and D are correct. B: Scala UDFs often offer better performance for complex operations like JSON parsing due to the JVM's efficiency and the availability of robust libraries like Jackson. Snowflake support different approaches for handling JSON parsing such as Jackson. C: UDF idempotency is crucial for reliable results, as Snowflake might rerun them for optimizatiom D: Pre-processing JSON data using Snowflake's built-in functions ('PARSE_JSON', 'GET _ PATH') reduces the UDF's workload and can improve performance. Option A is incorrect because Snowflake has its own internal JSON representation; using standard Python 'json' module is not optimized for it. Option E is incorrect because the UDF input data size is limited by the maximum input size of the UDF and available memory not the size of the UDF code.
NEW QUESTION # 246
......
Our website gives detailed guidance to our customers for preparation of DEA-C02 actual test and take them towards the direction of achievement. Each of our Snowflake exam preparation materials is designed by IT professionals in order to improve your particular skills. Our DEA-C02 Practice Questions will boost the confidence of candidates for appearing in the real exam.
Exam Topics DEA-C02 Pdf: https://www.realvalidexam.com/DEA-C02-real-exam-dumps.html
DOWNLOAD the newest RealValidExam DEA-C02 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1oDV9hNyzMOBcO-oebTDPzaHvaZTG6-va