BONUS!!! Jpexam AP-215ダンプの一部を無料でダウンロード:https://drive.google.com/open?id=1rgeBLkaywpG5A6kCpVSMCRrzqb08rklS
IT職員の一員として、目前のSalesforceのAP-215試験情報を明らかに了解できますか?もし了解しなかったら、心配する必要がありません。我々社Jpexamは試験政策の変化に応じて、SalesforceのAP-215問題集をタイムリーに更新しています。こうした、お客様に完備かつ高品質のAP-215試験資料を提供できます。
| Section | Weight | Objectives |
|---|---|---|
| Data Permissions and Governance | 5% | - User access and roles - Data update controls - Parent-child data setups |
| Data Harmonization | 3% | - Standardization methods - Cross-source alignment - Pros and cons of harmonization approaches |
| Dashboards and Visualization | 15% | - KPI and metric display - Dashboard design and layout - Chart types and usage |
| Data Quality and Cleansing | 7% | - Validation rules - Error handling and correction - Duplicate management |
| Performance and Troubleshooting | 5% | - Common issues and fixes - Monitoring and optimization |
| Overarching Entities | 3% | - Use cases and application scenarios - Structure and configuration |
| Calculated Fields and Functions | 5% | - Extract and transformation formulas - Custom calculations - VLOOKUP and FUZZYVLOOKUP |
| Automation and Workflow | 5% | - Automated distribution - Workflow setup |
| Datasets and Data Views | 10% | - Dataset creation and management - Filtering and segmentation - View configuration and sharing |
| Reporting and Analytics | 12% | - Report creation and scheduling - Insight generation and interpretation - Attribution models |
| General Functionalities | 13% | - Core platform capabilities - Basic concepts and terminology - Navigation and interface |
| Data Mapping and Modeling | 5% | - Source of truth configuration - Data structure and relationships - Dimensions and measures |
| Data Integration and Ingestion | 12% | - Data streams and connectors - Refresh schedules and data flow - API and file-based import |
もし君がサラリーマンで、もし君が早い時間でSalesforceのAP-215認定試験に合格したいなら、Jpexamは君のベストな選択になります。うちのSalesforceのAP-215学習教材はJpexamのIT専門家たちが研究して、実践して開発されたものです。それは十年過ぎのIT認証経験を持っています。うちの商品を使ったら、君は最も早い時間で、簡単に認定試験に合格することができます。
質問 # 58
An implementation engineer has been provided with 4 different source files: 03m 16s
1. Twitter Ads
2. Creative Classification
3. Placement Classification
4, Campaign Category Classification
The main source is Twitter Ads (which includes various fields and KPIs), and the rest are classification files that connect to Twitter Ads and enrich different fields within it.
The connections between the files are described as follows:
1st Party Creative Classification
File structure/headers:
Creative ID - links back to Creative Key (Twitter Ads)
1st Party Placement Classification &
File structure/headers:
Category - links back to Campaign Category (Twitter Ads)
Which proposed solution meets the client's requirements for the above use case?
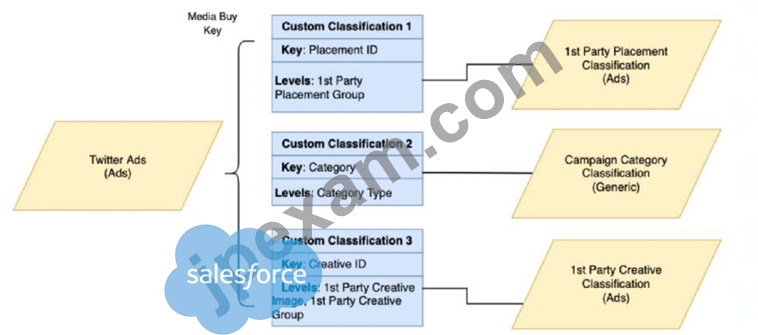
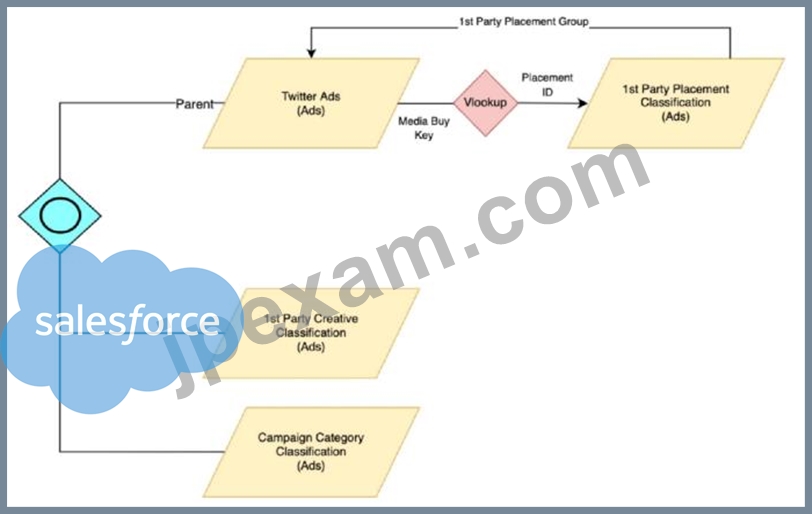
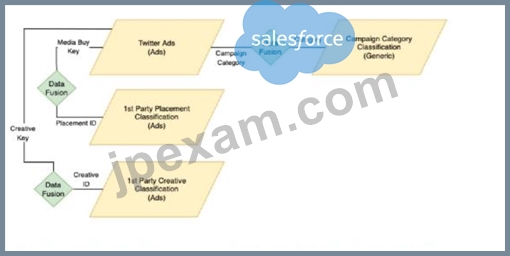
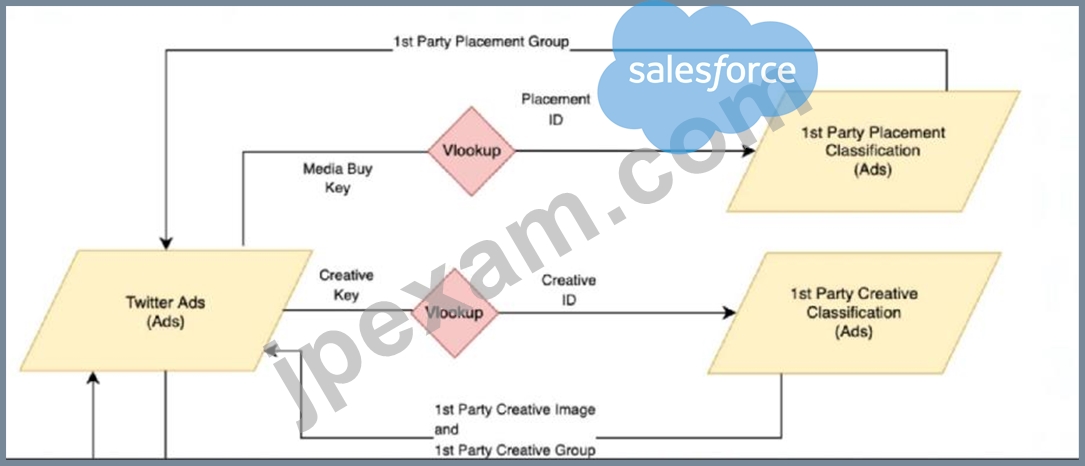
正解:D
解説:
For the given use case, where the Twitter Ads data stream needs to be enriched with classifications from three other sources, the correct implementation would involve creating links between the various fields across these files.
Option A is correct because it shows the correct usage of the fields from the classification files:
"Creative ID" in the Creative Classification file is linked to the "Creative Key" in the Twitter Ads data, allowing for enrichment with creative details.
"Placement ID" in the Placement Classification file is linked to a corresponding field in the Twitter Ads data, allowing for placement details to be added.
"Category" in the Campaign Category Classification file is linked back to "Campaign Category" in the Twitter Ads data, thus enriching the campaign data with the correct categories.
This configuration correctly uses VLOOKUP to enrich the Twitter Ads data stream with additional details from the classification files, aligning with best practices for data integration and enrichment in Marketing Cloud Intelligence.
質問 # 59
A client wants to integrate their data within Marketing Cloud Intelligence to optimize their marketing insights and cross-channel marketing activity analysis. Below are details regarding the different data sources and the number of data streams required for each source.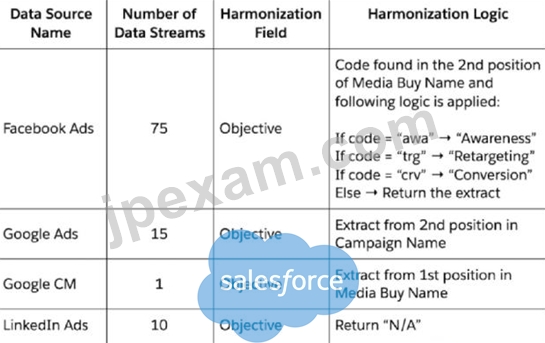
When harmonizing the Objective field from within the data stream mapping, which advantage is gained?
正解:C
解説:
By harmonizing the Objective field within data stream mapping, an organization can benefit from:
Ease of Maintenance: Harmonization allows for consistent naming conventions across different data sources and streams. This means when business logic or naming conventions change, updates can be made in one place and consistently applied across all data streams. It also reduces the complexity of managing multiple streams and ensures data consistency, which is vital for accurate reporting and analysis.
質問 # 60
A client has integrated data from Facebook Ads, Twitter Ads, and Google Ads in Marketing Cloud Intelligence. For each data source, the data follows a naming convention as shown below:
Facebook Ads Naming Convention - Campaign Name:
Camp|D_CampName#Market_Objective#TargetAge_TargetGender
Twitter Ads Naming Convention - Media Buy Name:
Market|TargetAge|Objective|OrderID
' Google Ads Naming Convention - Media Buy Name:
Buying Type_Market_Objective
The client wants to harmonize their data on the common fields between these two platforms (i.e. Market and Objective) using the Harmonization 'Center.
In addition to the previous details, the client provides the following data sample: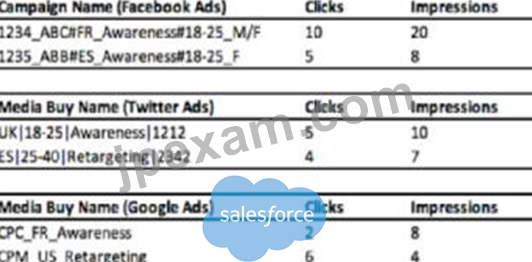
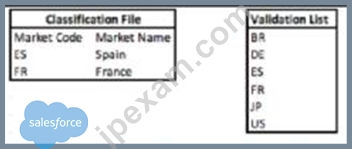
Logic specification:
If a value is not present in the Validation List, return "Not Valid"
If a value is not present in the Classification File, return "Unclassified".
If the Harmonization center is used to harmonize the above data and files, what table will show the final output?
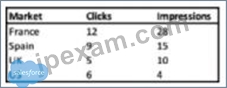
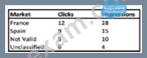
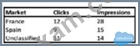
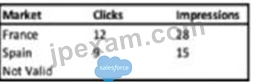
正解:B
解説:
The correct table would be Option B.
The harmonization process would identify the 'Market' from the campaign or media buy name based on the delimiter and position rules specified in the naming conventions. The harmonized 'Market' would then be matched against the classification file and validation list. If a value does not match the validation list, it would return 'Not Valid', and if it's not present in the classification file, it would return 'Unclassified'. Option B is the only table showing the 'Not Valid' category which aligns with the logic specification provided.
質問 # 61
Which Marketing Cloud Intelligence field is considered an attribute and not a "variable"?
正解:A
解説:
In Marketing Cloud Intelligence, attributes refer to characteristics of the data that describe the environment or context but do not change within the scope of the data being analyzed. 'Device Category' is typically an attribute as it describes a characteristic of the device used and doesn't vary within a given session or user interaction. In contrast, variables are typically metrics or dimensions that can change value or be measured.
質問 # 62
Which two statements are correct regarding variable Dimensions in marketing Cloud intelligence's data model?
正解:B、D
解説:
Variable dimensions in Marketing Cloud Intelligence's data model are flexible and can be associated with multiple entities, forming a many-to-many relationship. These dimensions are configured and stored at the workspace level, allowing for customization and alignment with specific reporting needs and analytics practices.
質問 # 63
......
Jpexamは多種なSalesforce認証試験を受ける方を正確な資料を提供者でございます。弊社の無料なAP-215サンプルを遠慮なくダウンロードしてください。
AP-215出題範囲: https://www.jpexam.com/AP-215_exam.html
無料でクラウドストレージから最新のJpexam AP-215 PDFダンプをダウンロードする:https://drive.google.com/open?id=1rgeBLkaywpG5A6kCpVSMCRrzqb08rklS