Jeder in der IT-Branche hat seinen eigenen Traum: das Zertifikat von Microsoft DP-750 zu erhalten, berufliche Beförderung oder Gehaltserhöhung zu bekommen. Traum unseres Fast2test ist es, Ihnen dabei zu helfen, die Microsoft DP-750 Zertifizierungsprüfung zu bestehen. Nachdem Sie unsere Schulungsunterlagen gekauft haben, können Sie einjährige Aktualisierung kostenlos genießen. Falls Sie die DP-750 Prüfung leider nicht bestehen, versprechen wir Ihnen eine volle Rückerstattung.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Prepare and process data | 30–35% | - Optimize and manage data storage
|
| Topic 2: Deploy and maintain data pipelines and workloads | 30–35% | - Build and orchestrate pipelines
|
| Topic 3: Secure and govern Unity Catalog objects | 15–20% | - Manage data sharing and permissions
|
| Topic 4: Set up and configure an Azure Databricks environment | 15–20% | - Select and configure compute resources
|
>> DP-750 Prüfungsvorbereitung <<
Unser Fast2test stellt Ihnen die besten Fragen und Antworten zur Microsoft DP-750 Zertifizierungsprüfung zur Verfügung und führt Ihnen schrittweise zum Erfolg. Die Schulungsunterlagen zur Microsoft DP-750 Zertifizierungsprüfung von Fast2test werden Ihnen eine reale Prüfungsvorbereitung bieten. Sie sind ganz zielgerichtet. Sie werden sicher ein IT-Expert werden. Unsere Microsoft DP-750 Schulungsunterlagen sind Ihnen am geeignetesten.Tragen Sie doch in unserer Website ein. Sie werden sicher etwas Unerwartetes bekommen.
89. Frage
You have an Azure Databricks workspace that is enabled for Unity Catalog. You plan to run the following PySpark code.
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.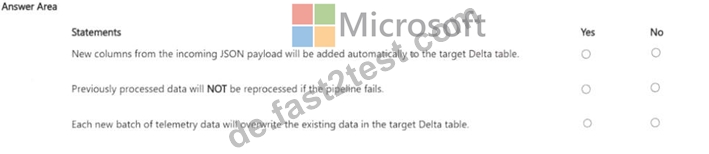
Antwort:
Begründung: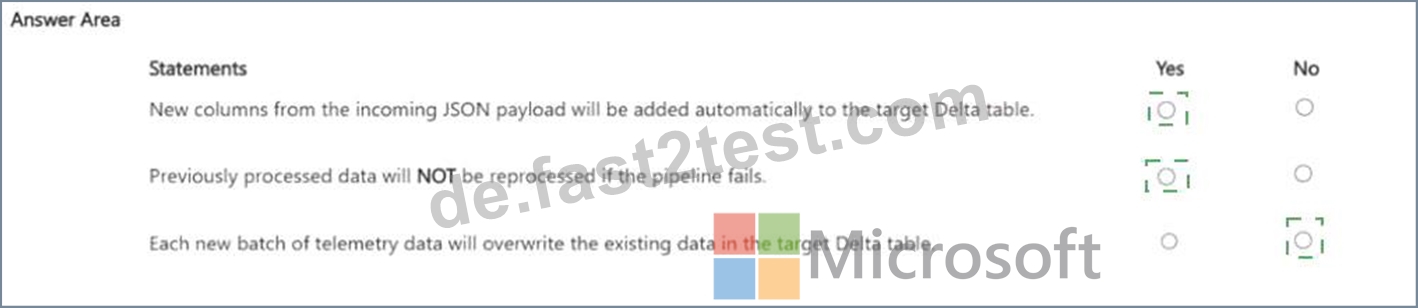
Explanation:
For HOTSPOT questions, each statement must be evaluated against the actual PySpark code shown in the answer area. Key evaluation principles:
DataFrames are immutable - every transformation returns a new DataFrame; the original is unchanged.
Transformations (filter, select, groupBy, join) are lazy and only execute when an action (show, count, write) is called.
Null handling: df.filter(col != None) is incorrect in PySpark due to SQL null semantics; use col.isNotNull() or dropna() instead. Schema changes: using mergeSchema=true or schema evolution handles new columns.
Write modes: 'overwrite' replaces existing data; 'append' adds to it.
Always check whether the code uses the correct Delta format (.format('delta')), Unity Catalog three-part naming, and whether write operations include a checkpointLocation for streaming queries. Evaluate each statement strictly on what the code does, not on what it might intend to do.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
90. Frage
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You have an Azure Databricks workspace named Workspace1 that contains a lakehouse and is enabled for Unity Catalog.
You have a connection to a Microsoft SQL Server database named DB1.
You need to expose the schemas and tables of DB1 to meet the following requirements:
- The schemas and tables can be queried in Databricks.
- The schemas and tables appear alongside other Unity Catalog objects.
- The data is NOT copied into Databricks-managed storage.
Solution: You create a new native catalog in Unity Catalog.
Does this meet the goal?
Antwort: A
Begründung:
Correct:
* You create a foreign catalog in Catalog Explorer.
You should create a Foreign Catalog using Lakehouse Federation.
Data Copying: Lakehouse Federation queries data directly in the source SQL Server without moving or copying it.
Seamless Integration: The database schemas and tables appear right inside Unity Catalog alongside your other data objects.Real-time Access: It provides immediate access to live SQL Server data.
Incorrect:
* You create a Databricks access connector.
* You create a Lakeflow Connect pipeline and connect it to DB1.
Data Copying: Lakeflow Connect is an ingestion tool that physically replicates and copies data into Databricks-managed storage (Delta tables).
Storage Costs: It violates your requirement to keep data out of Databricks storage.
* You create a new native catalog in Unity Catalog.
Note:
To expose the external SQL Server database in Unity Catalog without copying the data, you must use Lakehouse Federation.
Here are the step-by-step actions you need to take:
1. Create a Connection
Create a securable object in Unity Catalog that specifies the path and credentials to access the SQL Server database.
Go to Catalog Explorer or use SQL.
Select External Data > Connections.
Create a connection using the SQL Server connection details (URL, host, port, and database credentials).
*-> 2. Create a Foreign Catalog
Create a specific type of catalog in Unity Catalog that mirrors the external database.
Use the CREATE FOREIGN CATALOG SQL command or the Catalog Explorer UI.
Link this foreign catalog directly to the connection you created in step 1.
3. Query the DataOnce the foreign catalog is created, Unity Catalog automatically syncs the schemas and tables from SQL Server.
Reference:
https://docs.databricks.com/gcp/en/database-objects/
91. Frage
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to profile a table to meet the following requirements:
* The count of null values per column must be evaluated repeatedly as new records are added to the table.
* Changes in the count of null values must be observable over the progression of the dataset.
Which type of profile should you create?
Antwort: A
Begründung:
A time series profile repeatedly calculates data-quality metrics as a table changes and preserves those measurements over time. This makes it possible to observe whether the number of null values in each column is increasing, decreasing, or remaining stable as new records are added. A snapshot profile evaluates the table at a particular point in time and is therefore insufficient when the requirement is to analyze metric progression across multiple updates. Inference is associated with deriving information such as a schema or statistical characteristics; it is not the profile type used to maintain a historical sequence of monitoring measurements.
Because the question requires repeated evaluation and the ability to observe changes throughout the dataset's progression, the time series profile satisfies both requirements.
92. Frage
A Delta table receives new fields in incoming JSON data. You want to automatically adapt without breaking pipelines. What should you enable?
Antwort: A
Begründung:
Auto Loader supports schema inference and schema evolution, allowing new columns to be added automatically during ingestion. This reduces pipeline maintenance and avoids failures due to schema drift. Disabling enforcement is unsafe and risks data corruption. Overwrite mode deletes existing data. Manual updates are not scalable.
93. Frage
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that writes numerical data to a table named Table1 by using a data quality validation rule named rule1.
You need to modify rule1 to meet the following requirements:
- Ensure that amount is always greater than 0.
- Prevent an update to Table1 from being committed when data that
violates rule1 is detected.
Which statement should you execute?
Antwort: C
Begründung:
To ensure the data validation rule forces the pipeline update to abort and roll back transactions when data violates the condition, you must use a "fail" expectation operator. In Databricks Lakeflow Spark Declarative Pipelines (SDP), the command/syntax depends on whether your pipeline is written in Python or SQL.
Python Implementation
If your pipeline uses Python, apply the @dp.expect_or_fail decorator above your table definition (note: dp is the standard alias for the databricks.pipelines module in Lakeflow SDP):
dp.expect_or_fail("amount_greater_than_zero", "amount > 0")
Reference:
https://docs.databricks.com/aws/en/ldp/expectations
94. Frage
......
Wenn Sie unsere Softwaren benutzen, können Sie wissen, dass die Microsoft DP-750 zu bestehen nicht so schwer ist. Sie können in die Unterlagen, die unsere Fast2test bietet, die Geschicklichkeit des Bestehens der Microsoft DP-750 Prüfung finden. Um Sie beruhigt kaufen zu lassen, bieten wir Ihnen kostenlose demo der Microsoft DP-750 für dich. Sie können nach des Downloads mal probieren.
DP-750 Zertifizierungsfragen: https://de.fast2test.com/DP-750-premium-file.html