2026 Latest Prep4sures DP-750 PDF Dumps and DP-750 Exam Engine Free Share: https://drive.google.com/open?id=1AeM0ISdW-aaR_S1TZec5QoF3AFll-DwE
After choose Prep4sures's DP-750 exam training materials, you can get the latest edition of DP-750 exam dumps and answers. The accuracy rate of Prep4sures DP-750 exam training materials can ensure you to Pass DP-750 Test. After you purchase our DP-750 test training materials, if you fail DP-750 exam certification or there are any quality problems of DP-750 exam dumps, we guarantee a full refund.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Set up and configure an Azure Databricks environment | 15–20% | - Select and configure compute resources
|
| Topic 2: Secure and govern Unity Catalog objects | 15–20% | - Manage data sharing and permissions
|
| Topic 3: Deploy and maintain data pipelines and workloads | 30–35% | - Monitor, troubleshoot, and maintain workloads
|
| Topic 4: Prepare and process data | 30–35% | - Optimize and manage data storage
|
>> Intereactive DP-750 Testing Engine <<
Our DP-750 quiz torrent boost 3 versions and they include PDF version, PC version, App online version. Different version boosts different functions and using method. For example, the PDF version is convenient for the download and printing our DP-750 exam torrent and is easy and suitable for browsing learning. It can be printed on the papers which are convenient for you to take notes and learn at any time and place. You can practice DP-750 Quiz prep repeatedly and there are no limits for the amount of the persons and times. And the PC version of DP-750 quiz torrent can stimulate the real exam’s scenarios, is stalled on the Windows operating system and runs on the Java environment. You can use it any time to test your own Exam stimulation tests scores and whether you have mastered our DP-750 exam torrent.
NEW QUESTION # 43
You need to deploy Databricks Asset Bundles to a development environment. The solution must support automated and repeatable deployments across environments. What should you use?
Answer: C
Explanation:
The best option to use is the Databricks CLI.
The Databricks CLI is the core orchestration tool natively designed to validate, deploy, and manage Declarative Automation Bundles (formerly known as Databricks Asset Bundles) across multiple target environments using simple terminal commands like databricks bundle deploy.
Incorrect:
[Not A]
Git folders: Git folders are strictly a mechanism for version control, code syncing, and repository collaboration inside the workspace. While they are highly integrated with bundle development, they cannot directly deploy or provision bundle targets to isolated environments on their own without the CLI.
[Not C]
Databricks SDK for Python: While the Python SDK provides general programmatic access to Databricks APIs, it is not the primary or optimized tool for executing bundle operations. The bundle framework natively relies on the Databricks CLI executable to compile and translate your configurations.
[Not D]
Jobs UI: The Jobs user interface is built for manual interactions. It does not support native bundle multi-environment targeting or automated, repeatable CI/CD pipelines.
Reference:
https://docs.databricks.com/aws/en/dev-tools/bundles/
NEW QUESTION # 44
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to recommend a pipeline that ingests files from cloud storage, performs cleansing and enrichment transformations, and writes curated Delta tables for analytics. The solution must minimize development effort and provide built-in monitoring and automatic retries.
What should you include in the recommendation?
Answer: C
Explanation:
The best choice is a Lakeflow Spark Declarative Pipelines (SDP) pipeline.
Low Development Effort: Lakeflow SDP (formerly known as Delta Live Tables or DLT) is a completely declarative ETL framework. You simply define the target schemas and data transformations using standard SQL or Python. Databricks automatically manages the underlying operational complexities, state maintenance, task orchestration, and DAG dependencies for you.
Built-in Quality & Monitoring: It offers out-of-the-box data monitoring capabilities via Expectations, which allow you to specify data cleansing policies (like drop, retain, or fail on bad rows) with zero custom validation code. It also captures complete, automatic end-to-end data lineage and operational stats straight into Unity Catalog.
Built-in Resilience: Infrastructure failure handling and automatic retries are natively managed by the Lakeflow runtime.
Native Storage Ingestion: Using read_files() (Auto Loader) within SDP allows effortless, incremental ingestion of files from cloud object storage directly into curated Delta tables.
Reference:
https://docs.databricks.com/aws/en/ldp/
NEW QUESTION # 45
Drag and Drop Question
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a catalog named finance, finance contains two schemas named default and procurement.
You need to create a table named assets in the procurement schema, assets must contain the following columns:
- asset_id
- asset_type
- asset_name
How should you complete the SQL statement? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.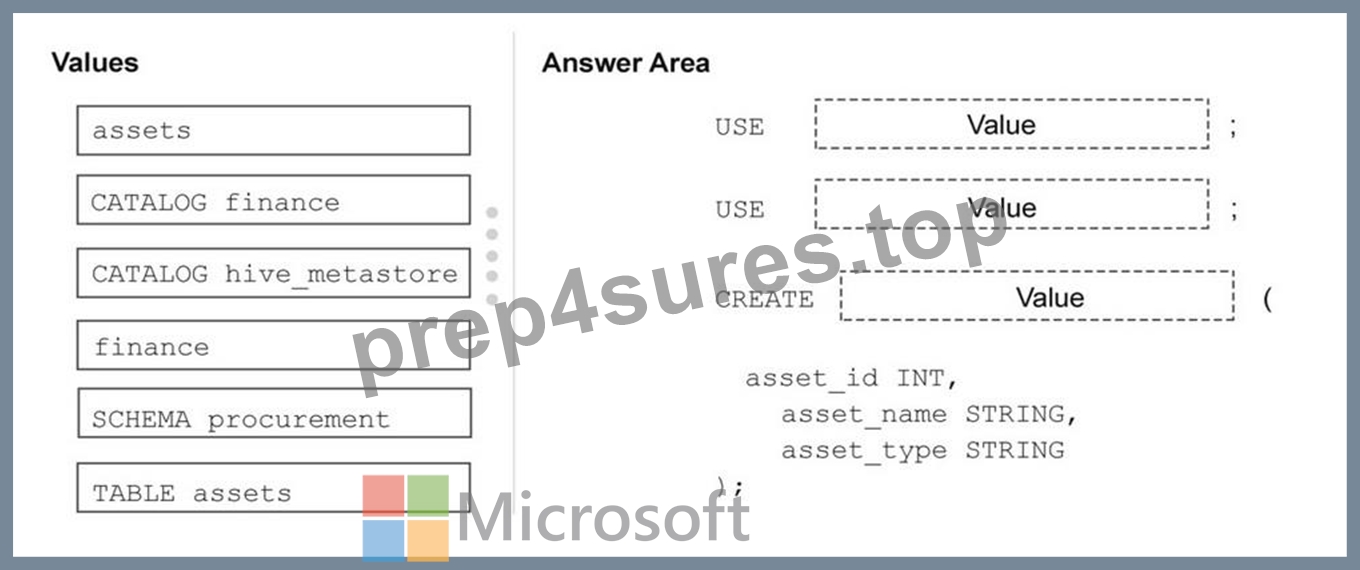
Answer:
Explanation: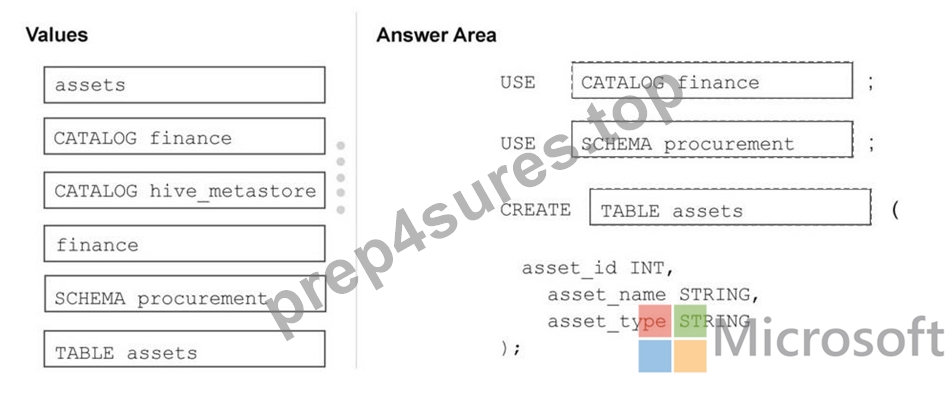
NEW QUESTION # 46
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Sales_orders.
Sales_orders stores historical sales data.
You receive a daily CSV file daily that contains new sales records only. The file does NOT contain updates to existing rows.
You need to load the daily data into Sales_orders. The solution must meet the following requirements:
- Preserve the existing data.
- Add only the new records.
- Minimize processing effort.
Which command should include in the loading strategy?
Answer: A
Explanation:
The best command for this scenario is INSERT INTO.
The INSERT INTO command appends new rows directly to the end of an existing Delta table.
Because your daily CSV file contains only new records and zero updates to existing rows, simply appending the data completely satisfies your requirements. It leaves all historical data untouched and requires the absolute lowest processing power because Databricks does not need to scan, modify, or rewrite any existing files.
Incorrect:
The UPDATE command is used to modify values in rows that already exist in the table based on a matching condition. It cannot be used to add entirely new rows to a table, and it requires a heavy scan of the data to find matches, which violates the requirement to keep processing low.
The INSERT OVERWRITE command deletes all the existing historical data in the table (or a specific partition) and replaces it with the data from the new CSV file. Using this would erase your historical sales data.
Reference:
https://medium.com/@jithujosekokken/understanding-data-patterns-in-medallion-architecture-full- incremental-and-change-only-loads-e33db28e51f4
NEW QUESTION # 47
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a catalog named CatalogV Catalog1 contains a schema named Schema! and a table named Table1.
You need to ensure that access to the data in Table1 is controlled by using attribute based access control (ABAC).
What should you apply to Table1, and how should you control access for users? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.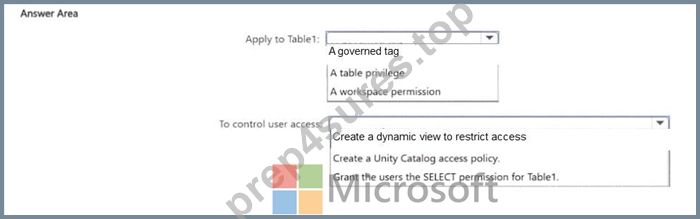
Answer:
Explanation: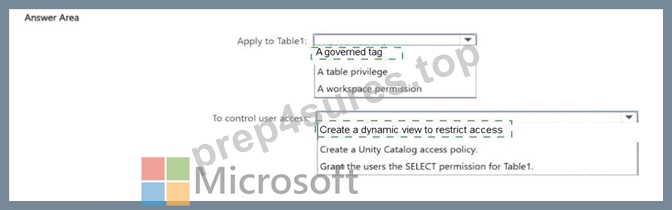
Explanation:
Attribute-based access control (ABAC) in Unity Catalog is implemented through row filters. A row filter is a SQL function registered on a table that evaluates the identity or group membership of the querying user and returns only the rows they're entitled to see.
The key functions are CURRENT_USER() (returns the logged-in user's email) and IS_ACCOUNT_GROUP_MEMBER() (returns true if the user belongs to a specified group). By building filter logic around these, you create access rules that are data-driven - a user in the 'EMEA' group sees EMEA rows, a user in 'APAC' sees APAC rows - without maintaining separate table-level grants per data segment.
This is what distinguishes ABAC from role-based access control: decisions are based on the user's attributes evaluated at query time, not on static grant lists. The filter is transparent to end users - they query the table normally and only receive rows the policy allows.
Reference: https://learn.microsoft.com/en-us/azure/databricks/data-governance/unity-catalog/row-and-column- filters
NEW QUESTION # 48
......
The study material to get Microsoft Implementing Data Engineering Solutions Using Azure Databricks certified should be according to individual's learning style and experience. Real Microsoft DP-750 Exam Questions certification makes you more dedicated and professional as it will provide you complete information required to work within a professional working environment.
Study DP-750 Material: https://www.prep4sures.top/DP-750-exam-dumps-torrent.html
P.S. Free 2026 Microsoft DP-750 dumps are available on Google Drive shared by Prep4sures: https://drive.google.com/open?id=1AeM0ISdW-aaR_S1TZec5QoF3AFll-DwE