Übrigens, Sie können die vollständige Version der It-Pruefung DP-600 Prüfungsfragen aus dem Cloud-Speicher herunterladen: https://drive.google.com/open?id=1kuu2xxwH1qvOnw_y1d9nqcHTCpc05aUB
Die Microsoft DP-600 (Implementing Analytics Solutions Using Microsoft Fabric)Schulungsunterlagen von It-Pruefung sind den echten Prüfungen ähnlich. Durch die kurze Sonderausbildung können Sie schnell die Fachkenntnisse beherrschen und sich gut auf die Microsoft DP-600 (Implementing Analytics Solutions Using Microsoft Fabric)Prüfung vorbereiten. Wir versprechen, dass wir alles tun würden, um Ihnen beim Bestehen der Microsoft DP-600 Zertifizierungsprüfung helfen.
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Implementing Analytics Solutions Using Microsoft Fabric |
| Exam Number: | DP-600 |
| Certificate Validity Period: | 1 year |
| Real Exam Qty: | 40-60 |
| Exam Duration: | 120 minutes |
| Passing Score: | 700/1000 |
| Related Certifications: | Microsoft Certified: Fabric Analytics Engineer Associate |
| Exam Format: | Case studies, Multiple-choice, Drag-and-drop |
| Available Languages: | Korean, English, Japanese, Chinese (Simplified) |
| Exam Price: | $165 USD |
| Sample Questions: | Microsoft DP-600 Sample Questions |
| Exam Way: | Online proctored or in-person testing center |
| Pre Condition: | Candidates should have foundational knowledge of data concepts, experience with Microsoft Fabric, and proficiency in data transformation and modeling. Familiarity with Power BI is recommended but not required. |
| Official Syllabus URL: | https://learn.microsoft.com/en-us/certifications/exams/dp-600 |
Wir It-Pruefung sind der beste Lieferant von Microsoft DP-600 Zertifizierungsprüfungen und bieten Ihnen auch echte Prüfungsfragen und Antworten. Die IT-Eliten von It-Pruefung bieten Ihnen Hilfen, damit Sie DP-600 Zertifizierungsprüfung bestehen. Und wir It-Pruefung beinhalten echte Fragen und Antworten in PDF-Versionen. Nach dem Kauf unserer DP-600 Schulungsunterlagen können Sie eine kostlose Aktualisierung bekommen.
| Thema | Einzelheiten |
|---|---|
| Thema 1 |
|
| Thema 2 |
|
| Thema 3 |
|
12. Frage
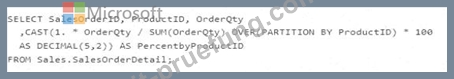
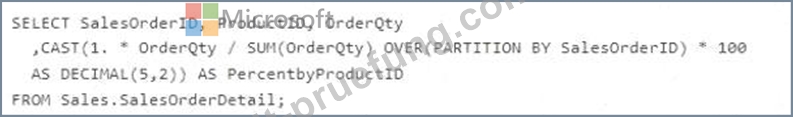
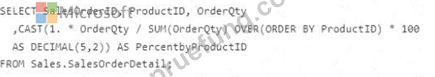
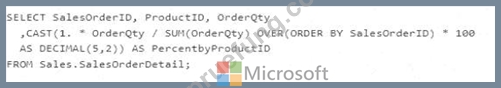
You have a Fabric warehouse that contains a table named SalesOrderDetail. SalesOrderDetail contains three columns named OrderQty, ProductID and SalesOrderlD. SalesOrderDetail contains one row per combination of SalesOrderlD and ProductID.
You need to calculate the proportion of the total quantity of each sales order represented by each product within the sales order.
Which T-SQL statement should you run?
Antwort: B
Begründung:
Comprehensive Detailed Explanation
We need to calculate the proportion of the total quantity of each sales order represented by each product within the sales order.
Step 1: Analyze the requirement
Table: SalesOrderDetail
Columns: OrderQty, ProductID, SalesOrderID
Each row = one product in a sales order.
Requirement: For each SalesOrderID, calculate what percentage each product contributes to the total order quantity.
This means we must:
Calculate the total order quantity per SalesOrderID.
Divide each product's OrderQty by that total.
Express it as a percentage.
Step 2: Evaluate the options
A). Uses OVER(ORDER BY ProductID)
Wrong: ORDER BY does not segment data, it only defines sequence. We need grouping by sales order.
B). Uses OVER(PARTITION BY ProductID)
Wrong: This would calculate percentages per product across all sales orders, not per sales order.
C). Uses OVER(PARTITION BY SalesOrderID)
Correct: This computes the total OrderQty per SalesOrderID and divides each product's quantity by that total.
Exactly what the requirement asks.
D). Uses OVER(ORDER BY SalesOrderID)
Wrong: Again, ORDER BY just sequences rows, does not group them.
Step 3: Correct Query
SELECT
SalesOrderID,
ProductID,
OrderQty,
CAST(1. * OrderQty / SUM(OrderQty)
OVER(PARTITION BY SalesOrderID) * 100 AS DECIMAL(5,2))
AS PercentByProductID
FROM Sales.SalesOrderDetail;
Why Option C is Correct
PARTITION BY SalesOrderID ensures the denominator is the total quantity for the current order.
This produces the correct percentage breakdown of each product inside its sales order.
References
T-SQL Window Functions
Aggregate Functions with PARTITION BY
Microsoft Fabric Warehouse T-SQL Support
13. Frage
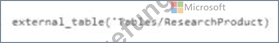
Which syntax should you use in a notebook to access the Research division data for Productlinel?



Antwort: B
Begründung:
Comprehensive Detailed Explanation
The question asks: Which syntax should you use in a Fabric notebook to access the Research division data for Productline1?
Key Background from the Case
In Productline1ws, a lakehouse named Lakehouse1 is created.
In Lakehouse1, a shortcut is created to storage1, named ResearchProduct.
Storage1 contains the Research division data for Productline1 in Delta format.
Requirement: All data in lakehouses must be presented as managed tables in Lakehouse explorer.
Analyzing the Syntax Options
Option A:
spark.sql( " SELECT * FROM Lakehouse1.ResearchProduct " )
This syntax directly queries the ResearchProduct shortcut within Lakehouse1 using Spark SQL.
Since the shortcut points to Delta data, Spark can directly query it.
This is the correct way to retrieve Productline1 data from Lakehouse1.
Option B:
spark.sql( " SELECT * FROM Lakehouse1.productline1.ResearchProduct " )
This introduces an extra schema-like path (productline1) that is not part of the shortcut name.
Incorrect, because the shortcut was created as ResearchProduct inside Lakehouse1, not under another schema.
Option C:
external_table( ' Tables/ResearchProduct ' )
external_table is not the correct way to access a Lakehouse shortcut.
Shortcuts in Lakehouses appear as tables and can be queried using Spark SQL directly.
Option D:
spark.sql( " SELECT * FROM Lakehouse1.productline1.ResearchProduct " )
Same issue as Option B, includes a schema path that does not exist.
Correct Choice
Since the shortcut to ResearchProduct was created inside Lakehouse1, and Spark SQL can query it directly, the correct syntax is:
spark.sql( " SELECT * FROM Lakehouse1.ResearchProduct " )
That matches Option A.
References
Microsoft Fabric Lakehouse - Shortcuts
Query data in a lakehouse using Spark SQL
Delta format support in Microsoft Fabric
14. Frage
You have a Fabric tenant.
You plan to create a Fabric notebook that will use Spark DataFrames to generate Microsoft Power Bl visuals.
You run the following code.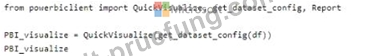
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.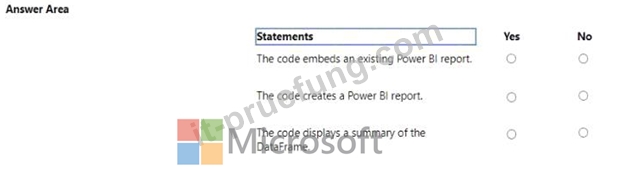
Antwort:
Begründung: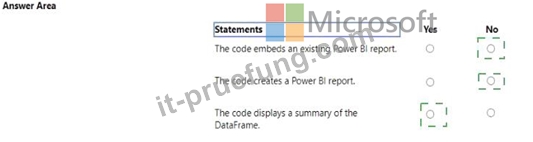
Explanation:
* The code embeds an existing Power BI report. - No
* The code creates a Power BI report. - No
* The code displays a summary of the DataFrame. - Yes
The code provided seems to be a snippet from a SQL query or script which is neither creating nor embedding a Power BI report directly. It appears to be setting up a DataFrame for use within a larger context, potentially for visualization in Power BI, but the code itself does not perform the creation or embedding of a report. Instead, it's likely part of a data processing step that summarizes data.
References =
* Introduction to DataFrames - Spark SQL
* Power BI and Azure Databricks
15. Frage
You have the following T-SQI statement.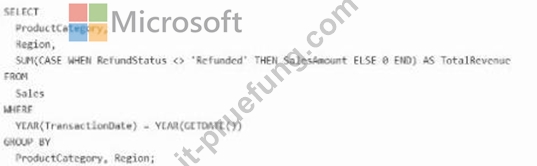
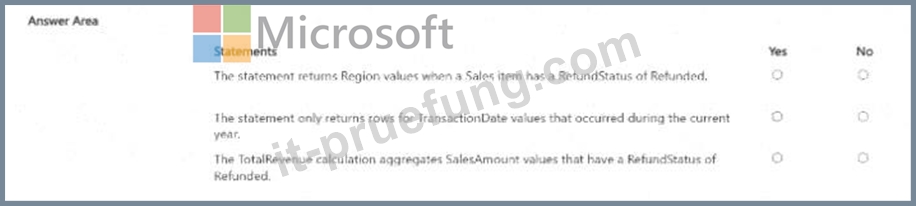
Antwort:
Begründung: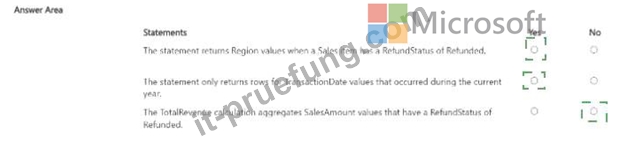
Explanation: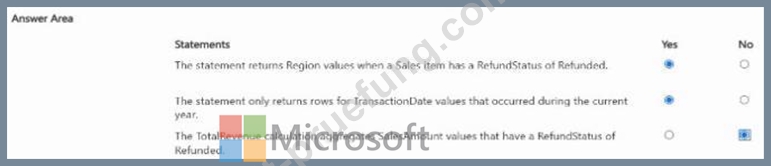
The statement uses SUM(CASE WHEN RefundStatus = 'Refunded' THEN SalesAmount ELSE 0 END) AS TotalRevenue, which calculates TotalRevenue by summing SalesAmount only when RefundStatus is
'Refunded', and 0 otherwise. This means Region values are returned regardless of RefundStatus, but the TotalRevenue reflects refunded items.
The WHERE (TransactionDate) - YEAR(GETDATE()) condition is incomplete and lacks proper comparison (e.g., no equality or range check), so it does not filter for the current year.
The TotalRevenue calculation does not aggregate all SalesAmount values with RefundStatus of 'Refunded'; it sums SalesAmount only for refunded items within the grouped data, with 0 for non-refunded items.
16. Frage
You have a Fabric workspace named Workspace1 and an Azure Data Lake Storage Gen2 account named storage"!. Workspace1 contains a lakehouse named Lakehouse1.
You need to create a shortcut to storage! in Lakehouse1.
Which connection and endpoint should you specify? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.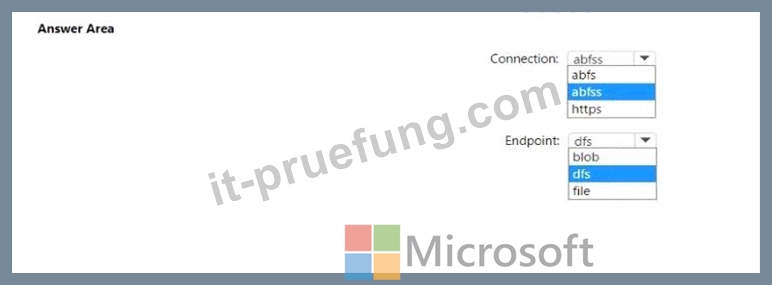
Antwort:
Begründung: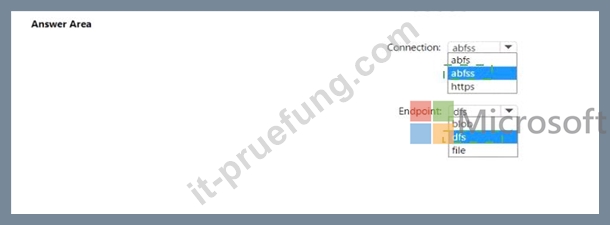
Explanation: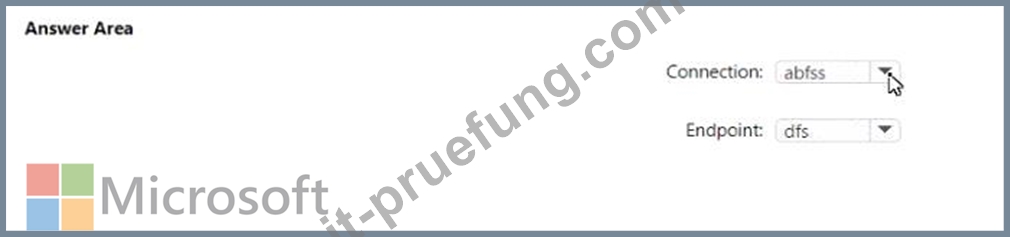
When creating a shortcut to an Azure Data Lake Storage Gen2 account in a lakehouse, you should use the abfss (Azure Blob File System Secure) connection string and the dfs (Data Lake File System) endpoint. The abfss is used for secure access to Azure Data Lake Storage, and the dfs endpoint indicates that the Data Lake Storage Gen2 capabilities are to be used.
17. Frage
......
DP-600 Buch: https://www.it-pruefung.com/DP-600.html
P.S. Kostenlose und neue DP-600 Prüfungsfragen sind auf Google Drive freigegeben von It-Pruefung verfügbar: https://drive.google.com/open?id=1kuu2xxwH1qvOnw_y1d9nqcHTCpc05aUB