TOP Certified-Data-Engineer-Professional Actual Exam - Latest Databricks Pdf Certified-Data-Engineer-Professional Exam Dump: Databricks Certified Data Engineer Professional

As long as you study with our Certified-Data-Engineer-Professional exam braindump, you can find that it is easy to study with the Certified-Data-Engineer-Professional exam questions. Therefore, even ordinary examiners can master all the learning problems without difficulty. In addition, Certified-Data-Engineer-Professional candidates can benefit themselves by using our test engine and get a lot of test questions like exercises and answers. They will help them modify the entire syllabus in a short time. The most important thing is that our Certified-Data-Engineer-Professional Practice Guide can help you obtain the certification without difficulty.
| Section | Objectives |
|---|
| Topic 1: Data Sharing and Federation | - Share and federate data
- 1. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 2. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 3. Configure Lakehouse Federation with appropriate governance across supported source systems
|
| Topic 2: Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
- 2. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
|
| Topic 3: Data Modeling | - Design and optimize data models
- 1. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 2. Simplify data layout decisions and optimize query performance using liquid clustering
- 3. Design dimensional models for analytical workloads with efficient querying and aggregation
- 4. Design and implement scalable data models using Delta Lake to manage large datasets
|
| Topic 4: Monitoring and Alerting | - Monitoring
- 1. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 2. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 3. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 4. Use Query Profile and Spark UI to monitor workloads
- Alerting
- 1. Use SQL Alerts to monitor data quality
- 2. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
|
| Topic 5: Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 2. Apply Change Data Feed to address streaming table limitations and improve latency
- 3. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 4. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 5. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
|
| Topic 6: Data Governance | - Govern enterprise data
- 1. Demonstrate understanding of the Unity Catalog permission inheritance model
- 2. Create and add descriptions and metadata to enterprise data to improve discoverability
|
| Topic 7: Developing Code for Data Processing using Python and SQL | - Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 2. Create pipeline components using control flow operators such as if/else and foreach
- 3. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 4. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 5. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 6. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 7. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 8. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- Using Python and Tools for Development
- 1. Develop User-Defined Functions using Pandas/Python UDF
- 2. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 3. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
|
| Topic 8: Debugging and Deploying | - Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 2. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 3. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
|
| Topic 9: Ensuring Data Security and Compliance | - Applying Data Security Mechanisms
- 1. Use row filters and column masks to protect sensitive table data
- 2. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 3. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- Ensuring Compliance
- 1. Implement compliant batch and streaming pipelines that detect and mask PII
- 2. Develop data purging solutions that comply with data retention policies
|
| Topic 10: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
- 2. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
|
>> Certified-Data-Engineer-Professional Actual Exam <<
Newest Certified-Data-Engineer-Professional Actual Exam, Pdf Certified-Data-Engineer-Professional Exam Dump
The pas rate is 98.95% for the Certified-Data-Engineer-Professional exam torrent, and you can pass the exam if you choose us. The Certified-Data-Engineer-Professional exam dumps we recommend to you are the latest information we have, with that you can know the information of the exam center timely. Furthermore, with skilled professionals to revise the Certified-Data-Engineer-Professional Questions and answers, the quality is high. And we offer you free update for 365 days, therefore you can get update version timely, and the update version will be sent to your email address automatically.
Databricks Certified Data Engineer Professional Sample Questions (Q184-Q189):
NEW QUESTION # 184
A data engineer created a daily batch ingestion pipeline using a cluster with the latest DBR version to store banking transaction data, and persisted it in a MANAGED DELTA table called prod.gold.all_banking_transactions_daily. The data engineer is constantly receiving complaints from business users who query this table ad hoc through a SQL Serverless Warehouse about poor query performance. Upon analysis, the data engineer identified that these users frequently use high- cardinality columns as filters. The engineer now seeks to implement a data layout optimization technique that is incremental, easy to maintain, and can evolve over time. Which command should the data engineer implement?
- A. Alter the table to use Hive-Style Partitions + Z-ORDER and implement a periodic OPTIMIZE command.
- B. Alter the table to use Liquid Clustering and implement a periodic OPTIMIZE command.
- C. Alter the table to use Hive-Style Partitions and implement a periodic OPTIMIZE command.
- D. Alter the table to use Z-ORDER and implement a periodic OPTIMIZE command.
Answer: B
Explanation:
Databricks recommends Liquid Clustering for optimizing data layout in large Delta tables where query filters involve high-cardinality columns. Liquid Clustering automatically manages file organization and supports incremental maintenance without the need to rewrite data when clustering keys evolve. This is a key advantage over static partitioning or Z-ordering, which require costly file rewrites whenever optimization keys change. By combining Liquid Clustering with a periodic OPTIMIZE command, Databricks automatically compacts small files and maintains efficient data skipping performance. As stated in the Delta Lake optimization guide, Liquid Clustering is designed for scalability, minimal maintenance, and adaptability for analytical workloads with evolving query patterns--making B the correct answer.
NEW QUESTION # 185
A data engineer is performing a join operation to combine values from a static userlookup table with a streaming DataFrame streamingDF.
Which code block attempts to perform an invalid stream-static join?
- A. userLookup.join(streamingDF, ["user_id"], how="right")
- B. streamingDF.join(userLookup, ["user_id"], how="left")
- C. streamingDF.join(userLookup, ["userid"], how="inner")
- D. streamingDF.join(userLookup, ["user_id"], how="outer")
- E. userLookup.join(streamingDF, ["userid"], how="inner")
Answer: D
Explanation:
https://spark.apache.org/docs/latest/structured-streaming-programming-guide.html#support-matrix-for-joins-in-streaming-queries
NEW QUESTION # 186
The data governance team is reviewing user for deleting records for compliance with GDPR. The following logic has been implemented to propagate deleted requests from the user_lookup table to the user aggregate table.
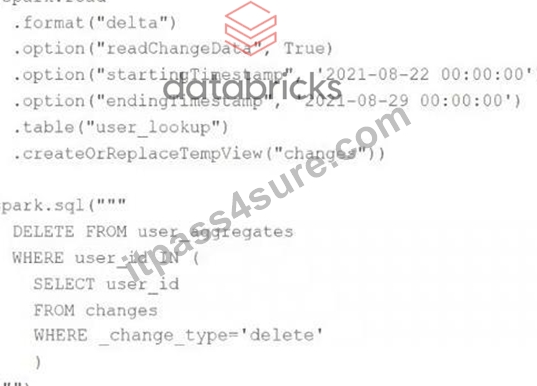
Assuming that user_id is a unique identifying key and that all users have requested deletion have been removed from the user_lookup table, which statement describes whether successfully executing the above logic guarantees that the records to be deleted from the user_aggregates table are no longer accessible and why?
- A. No; the Delta Lake DELETE command only provides ACID guarantees when combined with the MERGE INTO command
- B. Yes; the change data feed uses foreign keys to ensure delete consistency throughout the Lakehouse.
- C. No; the change data feed only tracks inserts and updates not deleted records.
- D. No; files containing deleted records may still be accessible with time travel until a BACUM command is used to remove invalidated data files.
- E. Yes; Delta Lake ACID guarantees provide assurance that the DELETE command successed fully and permanently purged these records.
Answer: D
Explanation:
The DELETE operation in Delta Lake is ACID compliant, which means that once the operation is successful, the records are logically removed from the table. However, the underlying files that contained these records may still exist and be accessible via time travel to older versions of the table. To ensure that these records are physically removed and compliance with GDPR is maintained, a VACUUM command should be used to clean up these data files after a certain retention period. The VACUUM command will remove the files from the storage layer, and after this, the records will no longer be accessible.
NEW QUESTION # 187
The data engineer team is configuring environment for development testing, and production before beginning migration on a new data pipeline. The team requires extensive testing on both the code and data resulting from code execution, and the team want to develop and test against similar production data as possible.
A junior data engineer suggests that production data can be mounted to the development testing environments, allowing pre production code to execute against production data. Because all users have Admin privileges in the development environment, the junior data engineer has offered to configure permissions and mount this data for the team.
Which statement captures best practices for this situation?
- A. All developer, testing and production code and data should exist in a single unified workspace; creating separate environments for testing and development further reduces risks.
- B. Because delta Lake versions all data and supports time travel, it is not possible for user error or malicious actors to permanently delete production data, as such it is generally safe to mount production data anywhere.
- C. Because access to production data will always be verified using passthrough credentials it is safe to mount data to any Databricks development environment.
- D. In environments where interactive code will be executed, production data should only be accessible with read permissions; creating isolated databases for each environment further reduces risks.
Answer: D
Explanation:
The best practice in such scenarios is to ensure that production data is handled securely and with proper access controls. By granting only read access to production data in development and testing environments, it mitigates the risk of unintended data modification. Additionally, maintaining isolated databases for different environments helps to avoid accidental impacts on production data and systems.
NEW QUESTION # 188
A data engineer has created a new cluster using shared access mode with default configurations.
The data engineer needs to allow the development team access to view the driver logs if needed.
What are the minimal cluster permissions that allow the development team to accomplish this?
- A. CAN MANAGE
- B. CAN RESTART
- C. CAN ATTACH TO
- D. CAN VIEW
Answer: D
Explanation:
The CAN VIEW permission on a cluster allows users to see cluster details, including driver and executor logs. This is the minimal permission required for the development team to access logs without granting them the ability to modify, restart, or attach notebooks to the cluster.
NEW QUESTION # 189
......
With the rapid market development, there are more and more companies and websites to sell Certified-Data-Engineer-Professional guide torrent for learners to help them prepare for exam. If you have known before, it is not hard to find that the study materials of our company are very popular with candidates, no matter students or businessman. Welcome your purchase for our Certified-Data-Engineer-Professional Exam Torrent. As is an old saying goes: Client is god! Service is first! Certified-Data-Engineer-Professional Guide Braindumps can simulate limited-timed examination and online error correcting, and have 24/7 Service Online, Certified-Data-Engineer-Professional Exam Torrent is the best and wisest choice for you to prepare your test.
Pdf Certified-Data-Engineer-Professional Exam Dump: https://www.itpass4sure.com/Certified-Data-Engineer-Professional-practice-exam.html
- www.vceengine.com Certified-Data-Engineer-Professional Web-Based Practice Tests 📕 Simply search for ▶ Certified-Data-Engineer-Professional ◀ for free download on ✔ www.vceengine.com ️✔️ 😧New Certified-Data-Engineer-Professional Test Book
- Exam Certified-Data-Engineer-Professional Simulations 🐤 Exam Certified-Data-Engineer-Professional Simulations 🥳 Certified-Data-Engineer-Professional Reliable Real Exam 🥼 Search on [ www.pdfvce.com ] for ⇛ Certified-Data-Engineer-Professional ⇚ to obtain exam materials for free download 🕎Related Certified-Data-Engineer-Professional Certifications
- Certification Certified-Data-Engineer-Professional Sample Questions 🌭 New Certified-Data-Engineer-Professional Exam Practice 👤 Certification Certified-Data-Engineer-Professional Sample Questions 🐠 Easily obtain free download of “ Certified-Data-Engineer-Professional ” by searching on ➤ www.examdiscuss.com ⮘ ⏮Certification Certified-Data-Engineer-Professional Test Answers
- Certified-Data-Engineer-Professional Certification Exam Infor 🕺 Certification Certified-Data-Engineer-Professional Test Answers 😳 Certified-Data-Engineer-Professional Valid Braindumps Pdf 📳 Search for ▶ Certified-Data-Engineer-Professional ◀ and download it for free immediately on 《 www.pdfvce.com 》 📰Certified-Data-Engineer-Professional Latest Dumps
- Certified-Data-Engineer-Professional Certification Exam Infor 🦥 Exam Certified-Data-Engineer-Professional Simulations 🟢 New Certified-Data-Engineer-Professional Test Book 🤭 Search for “ Certified-Data-Engineer-Professional ” on ☀ www.prep4away.com ️☀️ immediately to obtain a free download 😂Certified-Data-Engineer-Professional Study Material
- New Certified-Data-Engineer-Professional Actual Exam | High-quality Databricks Pdf Certified-Data-Engineer-Professional Exam Dump: Databricks Certified Data Engineer Professional 💡 Simply search for ➡ Certified-Data-Engineer-Professional ️⬅️ for free download on ✔ www.pdfvce.com ️✔️ ⏲Related Certified-Data-Engineer-Professional Certifications
- Related Certified-Data-Engineer-Professional Certifications 🦒 Latest Certified-Data-Engineer-Professional Test Voucher 🦍 Certified-Data-Engineer-Professional Instant Download 💠 Search for ▷ Certified-Data-Engineer-Professional ◁ and download it for free on ⮆ www.practicevce.com ⮄ website 🙊Certified-Data-Engineer-Professional Instant Download
- Certification Certified-Data-Engineer-Professional Test Answers 🍽 Practice Certified-Data-Engineer-Professional Test 🌗 Certified-Data-Engineer-Professional Latest Dumps 🏏 Easily obtain { Certified-Data-Engineer-Professional } for free download through ▛ www.pdfvce.com ▟ 🌀Exam Certified-Data-Engineer-Professional Simulations
- 2026 Professional Certified-Data-Engineer-Professional – 100% Free Actual Exam | Pdf Certified-Data-Engineer-Professional Exam Dump 😈 Open website “ www.dumpsquestion.com ” and search for ☀ Certified-Data-Engineer-Professional ️☀️ for free download 🆒Certified-Data-Engineer-Professional Certification Exam Infor
- 2026 Professional Certified-Data-Engineer-Professional – 100% Free Actual Exam | Pdf Certified-Data-Engineer-Professional Exam Dump 🚊 Copy URL ✔ www.pdfvce.com ️✔️ open and search for 「 Certified-Data-Engineer-Professional 」 to download for free 🚙Latest Certified-Data-Engineer-Professional Test Voucher
- Certified-Data-Engineer-Professional Certification Exam Infor 🧔 Related Certified-Data-Engineer-Professional Certifications 🔶 New Certified-Data-Engineer-Professional Exam Practice 💽 Download ➤ Certified-Data-Engineer-Professional ⮘ for free by simply searching on ➡ www.dumpsmaterials.com ️⬅️ 🧖Latest Braindumps Certified-Data-Engineer-Professional Ebook
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes