Databricks-Certified-Data-Analyst-Associate Guide Torrent - Databricks-Certified-Data-Analyst-Associate Real Test - Databricks-Certified-Data-Analyst-Associate Test Prep
BONUS!!! Download part of ITExamDownload Databricks-Certified-Data-Analyst-Associate dumps for free: https://drive.google.com/open?id=1bxHKb0M44KjjXMQ8Gz49pBfRzwk_uGr-
Differ as a result the Databricks-Certified-Data-Analyst-Associate questions torrent geared to the needs of the user level, cultural level is uneven, have a plenty of college students in school, have a plenty of work for workers, and even some low education level of people laid off, so in order to adapt to different level differences in users, the Databricks-Certified-Data-Analyst-Associate Exam Questions at the time of writing teaching materials with a special focus on the text information expression, so you can understand the content of the Databricks-Certified-Data-Analyst-Associate learning guide and pass the Databricks-Certified-Data-Analyst-Associate exam easily.
| Topic | Details |
|---|
| Topic 1 | - Analytics applications: It describes key moments of statistical distributions, data enhancement, and the blending of data between two source applications. Moroever, the topic also explains last-mile ETL, a scenario in which data blending would be beneficial, key statistical measures, descriptive statistics, and discrete and continuous statistics.
|
| Topic 2 | - SQL in the Lakehouse: It identifies a query that retrieves data from the database, the output of a SELECT query, a benefit of having ANSI SQL, access, and clean silver-level data. It also compares and contrasts MERGE INTO, INSERT TABLE, and COPY INTO. Lastly, this topic focuses on creating and applying UDFs in common scaling scenarios.
|
| Topic 3 | - Databricks SQL: This topic discusses key and side audiences, users, Databricks SQL benefits, complementing a basic Databricks SQL query, schema browser, Databricks SQL dashboards, and the purpose of Databricks SQL endpoints
- warehouses. Furthermore, the delves into Serverless Databricks SQL endpoint
- warehouses, trade-off between cluster size and cost for Databricks SQL endpoints
- warehouses, and Partner Connect. Lastly it discusses small-file upload, connecting Databricks SQL to visualization tools, the medallion architecture, the gold layer, and the benefits of working with streaming data.
|
| Topic 4 | - Data Visualization and Dashboarding: Sub-topics of this topic are about of describing how notifications are sent, how to configure and troubleshoot a basic alert, how to configure a refresh schedule, the pros and cons of sharing dashboards, how query parameters change the output, and how to change the colors of all of the visualizations. It also discusses customized data visualizations, visualization formatting, Query Based Dropdown List, and the method for sharing a dashboard.
|
| Topic 5 | - Data Management: The topic describes Delta Lake as a tool for managing data files, Delta Lake manages table metadata, benefits of Delta Lake within the Lakehouse, tables on Databricks, a table owner’s responsibilities, and the persistence of data. It also identifies management of a table, usage of Data Explorer by a table owner, and organization-specific considerations of PII data. Lastly, the topic it explains how the LOCATION keyword changes, usage of Data Explorer to secure data.
|
>> Databricks-Certified-Data-Analyst-Associate Reliable Exam Dumps <<
Unparalleled Databricks-Certified-Data-Analyst-Associate Reliable Exam Dumps - 100% Pass Databricks-Certified-Data-Analyst-Associate Exam
ITExamDownload is not only a website but as a professional Databricks-Certified-Data-Analyst-Associate Study Tool for candidates. Last but not least, we have advanced operation system of Databricks-Certified-Data-Analyst-Associate training materials which not only can ensure our customers the fastest delivery speed but also can protect the personal information of our customers automatically. In addition, our professional after sale stuffs will provide considerate online after sale service twenty four hours a day, seven days a week for all of our customers.
Databricks Certified Data Analyst Associate Exam Sample Questions (Q114-Q119):
NEW QUESTION # 114
Which of the following statements describes descriptive statistics?
- A. A branch of statistics that uses a variety of data analysis techniques to infer properties of an underlying distribution of probability.
- B. A branch of statistics that uses summary statistics to quantitatively describe and summarize data.
- C. A branch of statistics that uses quantitative variables that must take on an uncountable set of values.
- D. A branch of statistics that uses summary statistics to categorically describe and summarize data.
- E. A branch of statistics that uses quantitative variables that must take on a finite or countably infinite set of values.
Answer: B
Explanation:
Descriptive statistics is a branch of statistics that uses summary statistics, such as mean, median, mode, standard deviation, range, frequency, or correlation, to quantitatively describe and summarize data.
Descriptive statistics can help data analysts understand the main features of a data set, such as its central tendency, variability, or distribution. Descriptive statistics can also help data analysts visualize data using charts, graphs, or tables. Descriptive statistics do not make any inferences or predictions about the data, unlike inferential statistics, which use data analysis techniques to infer properties of an underlying population or probability distribution from a sample of data. References: Databricks - Descriptive Statistics, Databricks - Data Analysis with Databricks SQL
NEW QUESTION # 115
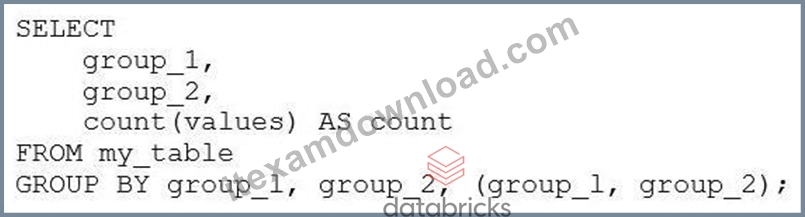
A data analyst is processing a complex aggregation on a table with zero null values and their query returns the following result:
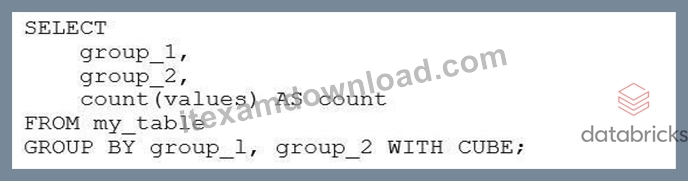
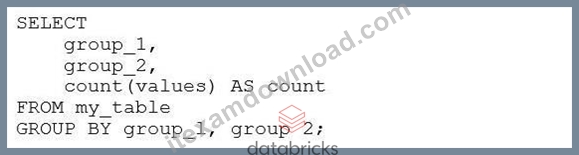
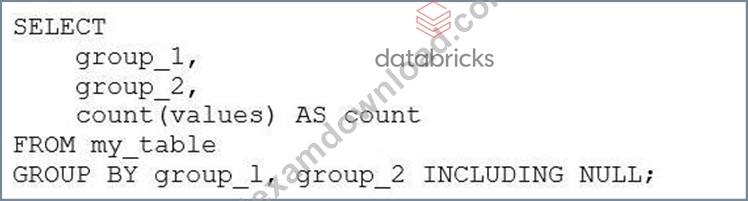
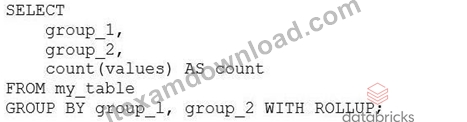
Which of the following queries did the analyst run to obtain the above result?
Answer: D
Explanation:
The result set provided shows a combination of grouping by two columns (group_1 and group_2) with subtotals for each level of grouping and a grand total. This pattern is typical of a GROUP BY ... WITH ROLLUP operation in SQL, which provides subtotal rows and a grand total row in the result set.
Considering the query options:
A) Option A: GROUP BY group_1, group_2 INCLUDING NULL - This is not a standard SQL clause and would not result in subtotals and a grand total.
B) Option B: GROUP BY group_1, group_2 WITH ROLLUP - This would create subtotals for each unique group_1, each combination of group_1 and group_2, and a grand total, which matches the result set provided.
C) Option C: GROUP BY group_1, group 2 - This is a simple GROUP BY and would not include subtotals or a grand total.
D) Option D: GROUP BY group_1, group_2, (group_1, group_2) - This syntax is not standard and would likely result in an error or be interpreted as a simple GROUP BY, not providing the subtotals and grand total.
E) Option E: GROUP BY group_1, group_2 WITH CUBE - The WITH CUBE operation produces subtotals for all combinations of the selected columns and a grand total, which is more than what is shown in the result set.
The correct answer is Option B, which uses WITH ROLLUP to generate the subtotals for each level of grouping as well as a grand total. This matches the result set where we have subtotals for each group_1, each combination of group_1 and group_2, and the grand total where both group_1 and group_2 are NULL.
NEW QUESTION # 116
Which of the following is a benefit of the Databricks Lakehouse Platform embracing open source technologies?
- A. Avoiding vendor lock-in
- B. Cloud-specific integrations
- C. Ability to scale storage
- D. Simplified governance
- E. Ability to scale workloads
Answer: A
Explanation:
Option E is correct. A major benefit of open source technologies and open data formats is avoiding vendor lock-in. Databricks supports open formats and interfaces so data can be used across tools and systems rather than being locked into a proprietary platform. Cloud integrations, governance, and workload scalability are Databricks benefits, but the specific benefit of embracing open source is avoiding vendor lock-in. Official Databricks extract: "Using open data formats and interfaces helps to avoid" vendor lock-in, and Databricks states that no proprietary data formats are used because Delta Lake and Iceberg are open source.
NEW QUESTION # 117
A data scientist wants to tune a set of hyperparameters for a machine learning model. They have wrapped a Spark ML model in the objective function objective_function, and they have defined the search space search_space.
As a result, they have the following code block:
num_evals = 100
trials = SparkTrials()
best_hyperparam = fmin(
fn=objective_function,
space=search_space,
algo=tpe.suggest,
max_evals=num_evals,
trials=trials
)
Which of the following changes do they need to make to the above code block in order to accomplish the task?
- A. Change SparkTrials() to Trials()
- B. Change fmin() to fmax()
- C. Reduce num_evals to be less than 10
- D. Remove the trials=trials argument
- E. Remove the algo=tpe.suggest argument
Answer: A
Explanation:
Option A is correct. The model being tuned is a Spark ML model, which is already distributed. SparkTrials is intended to distribute independent single-machine trials across Spark workers. For distributed ML algorithms such as Spark MLlib/Spark ML, Hyperopt should run trials from the driver so each trial can access the full cluster resources. Therefore, SparkTrials() should be changed to Trials(). Official Databricks documentation explains that this setup works for distributed machine learning algorithms including Apache Spark MLlib, and the Databricks notebook guidance states that SparkTrials is incompatible for that distributed-training pattern because each trial must be evaluated on the driver node.
NEW QUESTION # 118
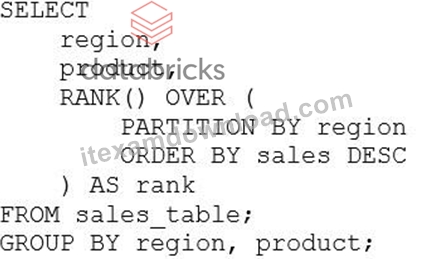
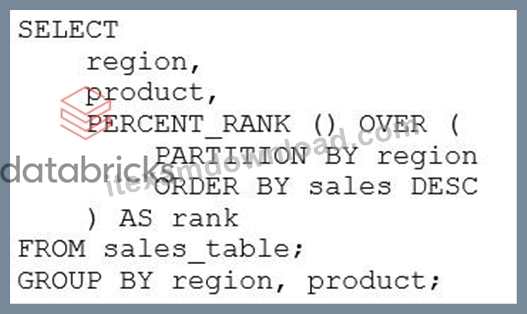
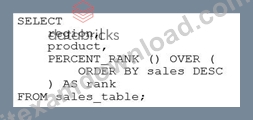
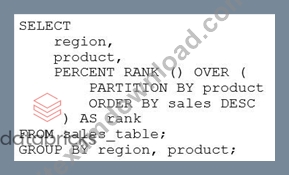
A data analyst has been asked to use the below table sales_table to get the percentage rank of products within region by the sales:
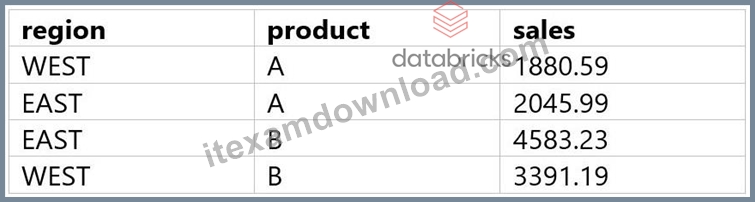
The result of the query should look like this:
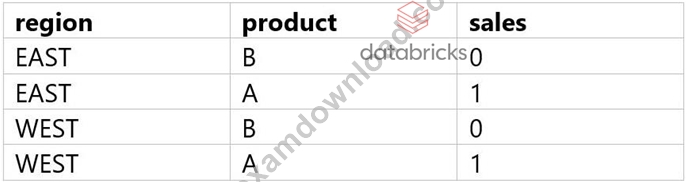
Which of the following queries will accomplish this task?
A)
B)
C)
- A. Option B
- B. Option D
- C. Option C
- D. Option A
Answer: A
Explanation:
The correct query to get the percentage rank of products within region by the sales is option B. This query uses the PERCENT_RANK() window function to calculate the relative rank of each product within each region based on the sales amount. The window function is partitioned by region and ordered by sales in descending order. The result is aliased as rank and displayed along with the region and product columns. The other options are incorrect because:
A) Option A uses the RANK() window function instead of the PERCENT_RANK() function. The RANK() function returns the rank of each row within the partition, but not the percentage rank. Also, the query does not have a GROUP BY clause, which is required for aggregate functions like SUM().
C) Option C uses the DENSE_RANK() window function instead of the PERCENT_RANK() function. The DENSE_RANK() function returns the rank of each row within the partition, but not the percentage rank. Also, the query does not have a GROUP BY clause, which is required for aggregate functions like SUM().
D) Option D uses the ROW_NUMBER() window function instead of the PERCENT_RANK() function. The ROW_NUMBER() function returns the sequential number of each row within the partition, but not the percentage rank. Also, the query does not have a GROUP BY clause, which is required for aggregate functions like SUM(). Reference:
1: PERCENT_RANK (Transact-SQL)
2: Window functions in Databricks SQL
3: Databricks Certified Data Analyst Associate Exam Guide
NEW QUESTION # 119
......
This Databricks Databricks-Certified-Data-Analyst-Associate exam preparation material is important because it will help you cover each topic and understand it well. You cannot pass the Databricks-Certified-Data-Analyst-Associate exam if you do not have real Databricks-Certified-Data-Analyst-Associate exam questions. It is the foremost thing that everyone should have to nail the Databricks-Certified-Data-Analyst-Associate Exam. The Databricks-Certified-Data-Analyst-Associate practice test material of ITExamDownload is available in web-based practice tests, desktop practice exam software, and PDF.
Reliable Databricks-Certified-Data-Analyst-Associate Test Objectives: https://www.itexamdownload.com/Databricks-Certified-Data-Analyst-Associate-valid-questions.html
- Databricks-Certified-Data-Analyst-Associate Test Lab Questions - Databricks-Certified-Data-Analyst-Associate Latest Exam Topics - Databricks-Certified-Data-Analyst-Associate Study Questions Files 🖍 Search for [ Databricks-Certified-Data-Analyst-Associate ] and obtain a free download on ⏩ www.practicevce.com ⏪ 🥔Databricks-Certified-Data-Analyst-Associate Exam Tips
- Databricks-Certified-Data-Analyst-Associate Online Bootcamps 🟨 Databricks-Certified-Data-Analyst-Associate Exam Tips 🥗 Databricks-Certified-Data-Analyst-Associate Exam Tips ⏳ Open website ⇛ www.pdfvce.com ⇚ and search for [ Databricks-Certified-Data-Analyst-Associate ] for free download 🔬Vce Databricks-Certified-Data-Analyst-Associate Format
- Databricks-Certified-Data-Analyst-Associate Test Lab Questions - Databricks-Certified-Data-Analyst-Associate Latest Exam Topics - Databricks-Certified-Data-Analyst-Associate Study Questions Files 🔂 Search for ☀ Databricks-Certified-Data-Analyst-Associate ️☀️ and download it for free on ( www.practicevce.com ) website 💘Databricks-Certified-Data-Analyst-Associate Training Pdf
- Pdf Databricks-Certified-Data-Analyst-Associate Pass Leader 🥪 Databricks-Certified-Data-Analyst-Associate Reliable Cram Materials 🏙 Reliable Databricks-Certified-Data-Analyst-Associate Dumps Book 🤛 Go to website ( www.pdfvce.com ) open and search for ➠ Databricks-Certified-Data-Analyst-Associate 🠰 to download for free 🌂Databricks-Certified-Data-Analyst-Associate Lab Questions
- Databricks-Certified-Data-Analyst-Associate Torrent PDF - Databricks-Certified-Data-Analyst-Associate Exam Torrent - Databricks-Certified-Data-Analyst-Associate Test Dumps 🎣 Search for ▷ Databricks-Certified-Data-Analyst-Associate ◁ on [ www.examcollectionpass.com ] immediately to obtain a free download ⬇Databricks-Certified-Data-Analyst-Associate Exam Tests
- Databricks-Certified-Data-Analyst-Associate Test Lab Questions - Databricks-Certified-Data-Analyst-Associate Latest Exam Topics - Databricks-Certified-Data-Analyst-Associate Study Questions Files 🔇 Search for ⇛ Databricks-Certified-Data-Analyst-Associate ⇚ and easily obtain a free download on ✔ www.pdfvce.com ️✔️ 🌹Databricks-Certified-Data-Analyst-Associate Lab Questions
- Databricks - Databricks-Certified-Data-Analyst-Associate - Reliable Databricks Certified Data Analyst Associate Exam Reliable Exam Dumps 🤏 Download ➤ Databricks-Certified-Data-Analyst-Associate ⮘ for free by simply searching on ☀ www.verifieddumps.com ️☀️ 🎈Databricks-Certified-Data-Analyst-Associate Exam Tips
- New Databricks-Certified-Data-Analyst-Associate Test Price 🧐 Vce Databricks-Certified-Data-Analyst-Associate Format 💅 Vce Databricks-Certified-Data-Analyst-Associate Format ⌛ Search for ✔ Databricks-Certified-Data-Analyst-Associate ️✔️ and obtain a free download on “ www.pdfvce.com ” 📹Databricks-Certified-Data-Analyst-Associate Online Bootcamps
- Databricks-Certified-Data-Analyst-Associate Torrent Pdf - Databricks-Certified-Data-Analyst-Associate Latest Vce - Databricks-Certified-Data-Analyst-Associate Valid Study Material 🌞 Download ☀ Databricks-Certified-Data-Analyst-Associate ️☀️ for free by simply searching on 《 www.verifieddumps.com 》 ↖Databricks-Certified-Data-Analyst-Associate Lab Questions
- 100% Pass Quiz 2026 Databricks The Best Databricks-Certified-Data-Analyst-Associate Reliable Exam Dumps ➰ Open ➽ www.pdfvce.com 🢪 and search for ( Databricks-Certified-Data-Analyst-Associate ) to download exam materials for free 🐒Databricks-Certified-Data-Analyst-Associate Complete Exam Dumps
- Databricks - Databricks-Certified-Data-Analyst-Associate - Reliable Databricks Certified Data Analyst Associate Exam Reliable Exam Dumps ⛲ Search for ▷ Databricks-Certified-Data-Analyst-Associate ◁ and obtain a free download on “ www.pdfdumps.com ” 👶Databricks-Certified-Data-Analyst-Associate Lab Questions
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.zazzle.com, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
BTW, DOWNLOAD part of ITExamDownload Databricks-Certified-Data-Analyst-Associate dumps from Cloud Storage: https://drive.google.com/open?id=1bxHKb0M44KjjXMQ8Gz49pBfRzwk_uGr-