First-hand Databricks Databricks-Certified-Professional-Data-Engineer Test Discount: Databricks Certified Professional Data Engineer Exam
Our Databricks-Certified-Professional-Data-Engineer preparationdumps are considered the best friend to help the candidates on their way to success for the exactness and efficiency based on our experts’ unremitting endeavor. This can be testified by our claim that after studying with our Databricks-Certified-Professional-Data-Engineer Actual Exam for 20 to 30 hours, you will be confident to take your Databricks-Certified-Professional-Data-Engineer exam and successfully pass it. Tens of thousands of our loyal customers relayed on our Databricks-Certified-Professional-Data-Engineer preparation materials and achieved their dreams.
| Section | Objectives |
|---|
| Topic 1: Data Modeling and Storage | - Schema evolution and data partitioning strategies
- Design scalable data lakehouse architectures
- Delta Lake table design and optimization
|
| Topic 2: Data Ingestion and Transformation | - Transform and clean datasets using Spark SQL and DataFrame APIs
- Handle batch and streaming data pipelines
- Ingest data using Apache Spark and Databricks
|
| Topic 3: Production Pipelines and Orchestration | - Pipeline reliability and fault tolerance
- Build and manage workflows using Databricks Jobs
- Automate ETL pipelines and scheduling
|
| Topic 4: Security, Governance, Monitoring, and Optimization | - Implement Unity Catalog governance and access control
- Cost optimization and performance tuning
- Monitor and optimize Spark workloads
|
>> Databricks-Certified-Professional-Data-Engineer Test Discount <<
Databricks-Certified-Professional-Data-Engineer Download Pdf, Databricks-Certified-Professional-Data-Engineer Latest Exam Review
According to personal propensity and various understanding level of exam candidates, we have three versions of Databricks-Certified-Professional-Data-Engineer practice materials for your reference. Here are the respective features and detailed disparities of our Databricks-Certified-Professional-Data-Engineer practice materials. Pdf version- it is legible to read and remember, and support customers’ printing request, so you can have a print and practice in papers. Software version-It support simulation test system, and times of setup has no restriction. Remember this version support Windows system users only. App online version-Be suitable to all kinds of equipment or digital devices. Be supportive to offline exercise on the condition that you practice it without mobile data.
Databricks Certified Professional Data Engineer Exam Sample Questions (Q215-Q220):
NEW QUESTION # 215
A security analytics pipeline must enrich billions of raw connection logs with geolocation data. The join hinges on finding which IPv4 range each event's address falls into.
Table 1: network_events (≈ 5 billion rows)
event_id ip_int
42 3232235777
Table 2: ip_ranges (≈ 2 million rows)
start_ip_int end_ip_int country
3232235520 3232236031 US
The query is currently very slow:
SELECT n.event_id, n.ip_int, r.country
FROM network_events n
JOIN ip_ranges r
ON n.ip_int BETWEEN r.start_ip_int AND r.end_ip_int;
Which change will most dramatically accelerate the query while preserving its logic?
- A. Force a sort-merge join with /*+ MERGE(r) */.
- B. Add a range-join hint /*+ RANGE_JOIN(r, 65536) */.
- C. Add a broadcast hint: /*+ BROADCAST(r) */ for ip_ranges.
- D. Increase spark.sql.shuffle.partitions from 200 to 10000.
Answer: B
Explanation:
Comprehensive and Detailed Explanation from Databricks Documentation:
The query joins billions of rows (network_events) with millions of rows (ip_ranges) using a range predicate (BETWEEN). Unlike equality joins (=), range joins are not efficiently handled by broadcast or sort-merge joins because:
* Broadcast Join (D): Effective for small tables but only for equality joins. Since this query uses a range condition, broadcast will not reduce the complexity of scanning billions of records across non-equality conditions.
* Sort-Merge Join (C): Works for ordered joins but is inefficient on range conditions. Sorting billions of records adds excessive overhead and will not resolve the bottleneck.
* Increasing Shuffle Partitions (A): Only spreads out shuffle work but does not address the fundamental inefficiency of range-based lookups at scale.
Range Joins in Spark (RANGE_JOIN hint):
Databricks provides range join optimizations specifically for conditions such as BETWEEN. By applying a RANGE_JOIN hint, Spark can build optimized data structures (such as interval indexes or partition pruning strategies) that map billions of input rows to ranges much faster. This avoids brute-force scans and unnecessary shuffle costs.
Thus, Option B is the correct solution because:
* It leverages range-join optimization, which is purpose-built for queries joining massive event logs to smaller lookup tables with IP ranges.
* This ensures Spark can evaluate billions of rows against millions of ranges with optimized matching logic, drastically improving query performance while preserving correctness.
NEW QUESTION # 216
Which of the following SQL statement can be used to query a table by eliminating duplicate rows from the query results?
- A. SELECT * FROM table_name GROUP BY * HAVING COUNT(*) < 1
- B. SELECT DISTINCT * FROM table_name
- C. SELECT DISTINCT_ROWS (*) FROM table_name
- D. SELECT DISTINCT * FROM table_name HAVING COUNT(*) > 1
- E. SELECT * FROM table_name GROUP BY * HAVING COUNT(*) > 1
Answer: B
Explanation:
Explanation
The answer is SELECT DISTINCT * FROM table_name
NEW QUESTION # 217
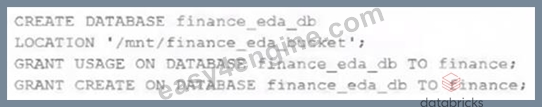
An external object storage container has been mounted to the location /mnt/finance_eda_bucket.
The following logic was executed to create a database for the finance team:
After the database was successfully created and permissions configured, a member of the finance team runs the following code:
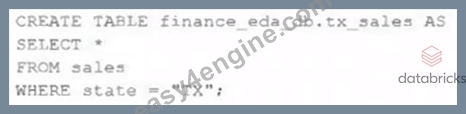
If all users on the finance team are members of the finance group, which statement describes how the tx_sales table will be created?
- A. An external table will be created in the storage container mounted to /mnt/finance eda bucket.
- B. An managed table will be created in the storage container mounted to /mnt/finance eda bucket.
- C. A managed table will be created in the DBFS root storage container.
- D. A logical table will persist the physical plan to the Hive Metastore in the Databricks control plane.
- E. A logical table will persist the query plan to the Hive Metastore in the Databricks control plane.
Answer: B
Explanation:
https://docs.databricks.com/en/lakehouse/data-objects.html
NEW QUESTION # 218
A Databricks SQL dashboard has been configured to monitor the total number of records present in a collection of Delta Lake tables using the following query pattern:
SELECT COUNT (*) FROM table -
Which of the following describes how results are generated each time the dashboard is updated?
- A. The total count of rows is calculated by scanning all data files
- B. The total count of records is calculated from the Hive metastore
- C. The total count of rows will be returned from cached results unless REFRESH is run
- D. The total count of records is calculated from the Delta transaction logs
- E. The total count of records is calculated from the parquet file metadata
Answer: D
Explanation:
https://delta.io/blog/2023-04-19-faster-aggregations-metadata/#:~:text=You%20can%20get%20the%
20number,a%20given%20Delta%20table%20version.
NEW QUESTION # 219
A platform team is creating a standardized template for Databricks Asset Bundles to support CI/CD. The template must specify defaults for artifacts, workspace root paths, and a run identity, while allowing a "dev" target to be the default and override specific paths.
How should the team use databricks.yml to satisfy these requirements?
- A. Use roots, modules, profiles, actor, and targets; where profiles contain workspace and artifacts defaults and actor sets run identity.
- B. Use project, packages, environment, identity, and stages; set dev as default stage and override workspace under environment.
- C. Use deployment, builds, context, identity, and environments; set dev as default environment and override paths under builds.
- D. Use bundle, artifacts, workspace, run_as, and targets at the top level; set one target with default: true and override workspace paths or artifacts under that target.
Answer: D
Explanation:
In Databricks Asset Bundles, the databricks.yml file defines all top-level configuration keys, including bundle, artifacts, workspace, run_as, and targets. The targets section defines specific deployment contexts (for example, dev, test, prod). Setting default: true for a target marks it as the default environment. Overrides for workspace paths and artifact configurations can be defined inside each target while keeping defaults at the top level.
Reference Source: Databricks Asset Bundle Configuration Guide - "Structure of databricks.yml and target overrides."
=========
NEW QUESTION # 220
......
There are a lot of experts and professors in our company. All Databricks-Certified-Professional-Data-Engineer study torrent of our company are designed by these excellent experts and professors in different area. We can make sure that our Databricks-Certified-Professional-Data-Engineer test torrent has a higher quality than other study materials. The aim of our design is to improving your learning and helping you gains your Databricks-Certified-Professional-Data-Engineer Certification in the shortest time. If you long to gain the certification, our Databricks Certified Professional Data Engineer Exam guide torrent will be your best choice.
Databricks-Certified-Professional-Data-Engineer Download Pdf: https://www.easy4engine.com/Databricks-Certified-Professional-Data-Engineer-test-engine.html
- Databricks-Certified-Professional-Data-Engineer certification dumps - Databricks-Certified-Professional-Data-Engineer Databricks guides - 100% valid 💕 The page for free download of ➡ Databricks-Certified-Professional-Data-Engineer ️⬅️ on 《 www.dumpsmaterials.com 》 will open immediately 😚Relevant Databricks-Certified-Professional-Data-Engineer Answers
- Relevant Databricks-Certified-Professional-Data-Engineer Answers 📲 Test Databricks-Certified-Professional-Data-Engineer Simulator 🤳 Databricks-Certified-Professional-Data-Engineer Certification Questions 🦘 Search for ▶ Databricks-Certified-Professional-Data-Engineer ◀ and easily obtain a free download on [ www.pdfvce.com ] 📷Databricks-Certified-Professional-Data-Engineer Latest Real Exam
- Quiz 2026 Databricks Databricks-Certified-Professional-Data-Engineer: Databricks Certified Professional Data Engineer Exam – Professional Test Discount 🩸 Download 【 Databricks-Certified-Professional-Data-Engineer 】 for free by simply entering ( www.exam4labs.com ) website 😓Databricks-Certified-Professional-Data-Engineer Reliable Exam Pass4sure
- Verified Databricks-Certified-Professional-Data-Engineer Test Discount Spend Your Little Time and Energy to Pass Databricks Databricks-Certified-Professional-Data-Engineer exam 🕎 Open “ www.pdfvce.com ” enter ▶ Databricks-Certified-Professional-Data-Engineer ◀ and obtain a free download 🕌Databricks-Certified-Professional-Data-Engineer Interactive Course
- 100% Pass Quiz 2026 Fantastic Databricks-Certified-Professional-Data-Engineer: Databricks Certified Professional Data Engineer Exam Test Discount 📣 Go to website ▷ www.dumpsmaterials.com ◁ open and search for ⏩ Databricks-Certified-Professional-Data-Engineer ⏪ to download for free 💕Databricks-Certified-Professional-Data-Engineer Valid Braindumps Pdf
- 100% Pass Quiz 2026 Fantastic Databricks-Certified-Professional-Data-Engineer: Databricks Certified Professional Data Engineer Exam Test Discount 🦹 Simply search for 「 Databricks-Certified-Professional-Data-Engineer 」 for free download on ☀ www.pdfvce.com ️☀️ 🕊Databricks-Certified-Professional-Data-Engineer Certification Questions
- Quiz 2026 Databricks Databricks-Certified-Professional-Data-Engineer: Databricks Certified Professional Data Engineer Exam – Professional Test Discount 🎺 Download ➠ Databricks-Certified-Professional-Data-Engineer 🠰 for free by simply searching on ▷ www.troytecdumps.com ◁ 🎦Valid Databricks-Certified-Professional-Data-Engineer Real Test
- 100% Pass Quiz 2026 Fantastic Databricks-Certified-Professional-Data-Engineer: Databricks Certified Professional Data Engineer Exam Test Discount 🛄 Easily obtain free download of ▶ Databricks-Certified-Professional-Data-Engineer ◀ by searching on ✔ www.pdfvce.com ️✔️ 😎Databricks-Certified-Professional-Data-Engineer Exam Topics Pdf
- Databricks-Certified-Professional-Data-Engineer - Latest Databricks Certified Professional Data Engineer Exam Test Discount 🍵 Open website ➡ www.vce4dumps.com ️⬅️ and search for ⇛ Databricks-Certified-Professional-Data-Engineer ⇚ for free download 🤭Valid Databricks-Certified-Professional-Data-Engineer Test Materials
- Databricks-Certified-Professional-Data-Engineer Practice Mock 🏘 Databricks-Certified-Professional-Data-Engineer Practice Mock 🐯 Databricks-Certified-Professional-Data-Engineer Valid Braindumps Pdf 💝 Search for “ Databricks-Certified-Professional-Data-Engineer ” and easily obtain a free download on [ www.pdfvce.com ] 🍲100% Databricks-Certified-Professional-Data-Engineer Accuracy
- Valid Databricks-Certified-Professional-Data-Engineer Real Test 🔆 Databricks-Certified-Professional-Data-Engineer PDF VCE 🐶 Certification Databricks-Certified-Professional-Data-Engineer Torrent 🩳 Search for ➥ Databricks-Certified-Professional-Data-Engineer 🡄 on ➠ www.vce4dumps.com 🠰 immediately to obtain a free download 🚰Valid Databricks-Certified-Professional-Data-Engineer Exam Camp Pdf
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes