NCA-GENM시험패스가능한공부 & NCA-GENM시험정보

참고: Itexamdump에서 Google Drive로 공유하는 무료 2026 NVIDIA NCA-GENM 시험 문제집이 있습니다: https://drive.google.com/open?id=1D080BLQLlwSmmkr2vy3olgW7e_17Wt1W
여러분은 우선 우리 Itexamdump사이트에서 제공하는NVIDIA인증NCA-GENM시험덤프의 일부 문제와 답을 체험해보세요. 우리 Itexamdump를 선택해주신다면 우리는 최선을 다하여 여러분이 꼭 한번에 시험을 패스할 수 있도록 도와드리겠습니다.만약 여러분이 우리의 인증시험덤프를 보시고 시험이랑 틀려서 패스를 하지 못하였다면 우리는 무조건 덤프비용전부를 환불해드립니다.
NVIDIA NCA-GENM Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Topic 1: Multimodal Data | 15% | - Handling and integrating text, image, and audio data
- Applications and use cases
|
| Topic 2: Performance Optimization | 10% | - Techniques for optimizing AI performance
- Monitoring and improving system efficiency
|
| Topic 3: Software Development & Engineering | 15% | - Integration and deployment of multimodal AI systems
- Python libraries for multimodal AI
|
| Topic 4: Data Analysis & Visualization | 10% | - Data preprocessing and feature engineering
- Visualization techniques for multimodal data
|
| Topic 5: Experimentation | 25% | - Model evaluation and comparison
- Hypothesis testing
- Experimental design
- A/B testing
|
| Topic 6: Trustworthy AI | 5% | - Ethical considerations in AI development
- Ensuring fairness and transparency
|
| Topic 7: Core ML & AI Knowledge | 20% | - Key algorithms and techniques
- Basic concepts and terminology
|
>> NCA-GENM시험패스 가능한 공부 <<
NCA-GENM시험정보, NCA-GENM시험패스자료
NVIDIA NCA-GENM덤프구매에 관심이 있는데 선뜻 구매결정을 하지 못하는 분이라면 사이트에 있는 demo를 다운받아 보시면NVIDIA NCA-GENM시험패스에 믿음이 생길것입니다. NVIDIA NCA-GENM덤프는 시험문제변경에 따라 업데이트하여 항상 가장 최선버전이도록 유지하기 위해 최선을 다하고 있습니다.
최신 NVIDIA-Certified Associate NCA-GENM 무료샘플문제 (Q12-Q17):
질문 # 12
You're working with a multimodal model that fuses text and image features. You've noticed that the model performs poorly when the text and image are semantically misaligned (e.g., an image of a dog and the caption 'a cat on a mat'). Which of the following techniques can help improve the model's robustness to such misalignment?
- A. Using only positive text-image pairs for training.
- B. Decreasing the batch size.
- C. Increasing the learning rate during training.
- D. Removing dropout layers from the model architecture.
- E. Adding a contrastive loss that penalizes embeddings of misaligned text-image pairs.
정답:E
설명:
A contrastive loss function directly addresses the issue of semantic misalignment by penalizing the model when it produces similar embeddings for text and images that don't correspond semantically. This encourages the model to learn more robust and meaningful feature representations.
질문 # 13
Consider the following PyTorch code snippet intended for training a variational autoencoder (VAE):
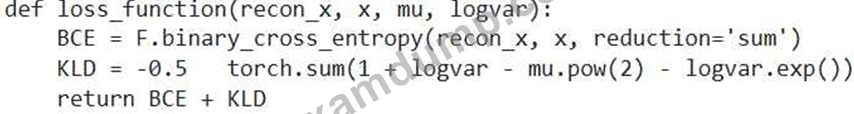
What potential issue(s) exist(s) in this code, and how would you address them?
- A. The Kullback-Leibler divergence (KLD) term isn't scaled appropriately for the batch size; divide it by the batch size to get a mean KLD loss.
- B. All of the above.
- C. The binary cross-entropy (BCE) loss doesn't account for pixel values outside the range [0, 1]; normalize the input images to this range.
- D. The BCE loss is summed across all pixels; average it by dividing by the total number of pixels in the input.
- E. The KLD calculation is incorrect; it should be 0.5 torch.sum(mu.pow(2) + logvar - 1 - logvar.exp()).
정답:B
설명:
All the mentioned issues exist. Firstly, BCE requires inputs between 0 and 1 . Secondly, KLD loss needs to be scaled according to batch size for proper gradients during training. Thirdly, simply summing the BCE isn't ideal, average is better. Finally, the KLD calculation is indeed reverse of what it should be.
질문 # 14
You are tasked with creating a multimodal A1 assistant that can understand and respond to user queries based on images and text. The assistant should be able to identify objects in images, understand the relationships between them, and answer questions about the image content using natural language. Given a scenario where a user uploads an image of a living room and asks, 'What is the color of the sofa next to the window?', what are the essential steps and techniques needed to implement this functionality?
- A. Visual question answering (VQA): Use a VQA model that takes the image and the user's question as input and generates a natural language answer (e.g., 'The sofa is blue').
- B. All of the above.
- C. Relationship extraction: Use a relationship extraction model to determine the spatial relationships between the detected objects (e.g., 'sofa is next to window').
- D. Object detection: Use an object detection model (e.g., YOLO, Faster R-CNN) to identify objects in the image (sofa, window, etc.).
- E. Sentiment Analysis.
정답:B
설명:
All steps are required. Object detection identifies the objects, relationship extraction understands their spatial relationships, and VQA generates the natural language answer based on the image and question. Sentiment analysis is not relevant in this scenario.
질문 # 15
You are working with a dataset containing text descriptions of products and corresponding product images. You want to train a model that can retrieve the most relevant image for a given text description. Which of the following loss functions is MOST appropriate for this task?
- A. Triplet loss
- B. Cross-entropy loss
- C. Binary Cross-entropy loss
- D. Mean Squared Error (MSE) loss
- E. Huber Loss
정답:A
설명:
Triplet loss is specifically designed for learning embeddings where similar examples are close together in the embedding space and dissimilar examples are far apart. In this case, the triplets would consist of (text description, correct image, incorrect image). The goal is to learn embeddings that bring the text description and its corresponding image closer while pushing the text description and the incorrect image further apart. Cross-entropy and binary cross-entropy are typically used for classification tasks. MSE loss is used for regression tasks. Huber loss is for regression that's less sensitive to outliers. None of these are as well-suited as triplet loss for this retrieval task.
질문 # 16
Which of the following NVIDIA SDKs is most suitable for deploying a real-time, low-latency speech-to-text service as part of a multimodal AI application?
- A. NVIDIA NeMo.
- B. NVIDIA Tritone Inference Server
- C. NVIDIAAvatar Cloud Engine (ACE)
- D. CUDA Toolkit
- E. NVIDIA Riva
정답:E
설명:
NVIDIA Riva is specifically designed for building and deploying real-time conversational A1 services, including speech-to-text, text-to- speech, and natural language understanding. Its focus is on low latency and high accuracy for conversational applications.
질문 # 17
......
IT자격증을 많이 취득하여 IT업계에서 자신만의 단단한 자리를 보장하는것이 여러분들의 로망이 아닐가 싶습니다. Itexamdump의 완벽한 NVIDIA인증 NCA-GENM덤프는 IT전문가들이 자신만의 노하우와 경험으로 실제NVIDIA인증 NCA-GENM시험문제에 대비하여 연구제작한 완벽한 작품으로서 100%시험통과율을 보장합니다.
NCA-GENM시험정보: https://www.itexamdump.com/NCA-GENM.html
- 최신버전 NCA-GENM시험패스 가능한 공부 퍼펙트한 덤프로 시험패스하여 자격증을 취득하기 🏺 시험 자료를 무료로 다운로드하려면▶ www.passtip.net ◀을 통해➽ NCA-GENM 🢪를 검색하십시오NCA-GENM완벽한 시험기출자료
- NCA-GENM최신 업데이트버전 덤프 🆕 NCA-GENM최신 덤프문제모음집 🍞 NCA-GENM합격보장 가능 덤프문제 🌖 ✔ www.itdumpskr.com ️✔️을(를) 열고《 NCA-GENM 》를 입력하고 무료 다운로드를 받으십시오NCA-GENM퍼펙트 덤프 최신 데모
- 시험준비에 가장 좋은 NCA-GENM시험패스 가능한 공부 인증덤프 🏏 【 www.koreadumps.com 】웹사이트를 열고➤ NCA-GENM ⮘를 검색하여 무료 다운로드NCA-GENM시험대비 공부
- NCA-GENM합격보장 가능 덤프문제 🏢 NCA-GENM시험합격 🔫 NCA-GENM시험패스 가능한 인증공부자료 😥 ➽ www.itdumpskr.com 🢪웹사이트에서⇛ NCA-GENM ⇚를 열고 검색하여 무료 다운로드NCA-GENM최신덤프자료
- NCA-GENM시험대비 공부 🕌 NCA-GENM최신덤프자료 🧭 NCA-GENM시험패스 가능한 인증공부자료 🥰 ▶ www.passtip.net ◀에서➡ NCA-GENM ️⬅️를 검색하고 무료로 다운로드하세요NCA-GENM시험패스 가능한 인증덤프
- NCA-GENM퍼펙트 덤프 최신 데모 🐕 NCA-GENM합격보장 가능 덤프문제 🏄 NCA-GENM시험패스 가능한 인증공부자료 😵 ⮆ www.itdumpskr.com ⮄웹사이트를 열고✔ NCA-GENM ️✔️를 검색하여 무료 다운로드NCA-GENM합격보장 가능 덤프문제
- 최신버전 NCA-GENM시험패스 가능한 공부 퍼펙트한 덤프로 시험패스하여 자격증을 취득하기 👤 검색만 하면✔ www.pass4test.net ️✔️에서➤ NCA-GENM ⮘무료 다운로드NCA-GENM최신버전 시험공부자료
- NCA-GENM시험패스 가능한 인증덤프 🐖 NCA-GENM최신 업데이트버전 덤프 🤧 NCA-GENM시험대비 공부 🧛 ✔ www.itdumpskr.com ️✔️에서▛ NCA-GENM ▟를 검색하고 무료 다운로드 받기NCA-GENM시험패스 가능한 인증공부자료
- NCA-GENM시험합격 🧤 NCA-GENM최신 덤프문제 👶 NCA-GENM최신 덤프문제 🚥 ➤ kr.fast2test.com ⮘을(를) 열고☀ NCA-GENM ️☀️를 검색하여 시험 자료를 무료로 다운로드하십시오NCA-GENM시험대비 공부
- NCA-GENM시험패스 가능한 공부자료 ▶ NCA-GENM덤프문제은행 ⭐ NCA-GENM최신 업데이트버전 덤프 📺 ⮆ www.itdumpskr.com ⮄을(를) 열고⇛ NCA-GENM ⇚를 입력하고 무료 다운로드를 받으십시오NCA-GENM최신 덤프문제
- 시험준비에 가장 좋은 NCA-GENM시험패스 가능한 공부 인증덤프 🦲 《 www.dumptop.com 》웹사이트를 열고( NCA-GENM )를 검색하여 무료 다운로드NCA-GENM시험패스 가능한 공부자료
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
참고: Itexamdump에서 Google Drive로 공유하는 무료, 최신 NCA-GENM 시험 문제집이 있습니다: https://drive.google.com/open?id=1D080BLQLlwSmmkr2vy3olgW7e_17Wt1W